# Ecotone Blog — PHP Messaging, DDD & Event Sourcing
> Ecotone gives you a set of composable building blocks on a single messaging foundation. You write the business logic, Ecotone glues the rest - by providing composable building blocks working on top of your current infrastructure.
Public Ghost content for AI and LLM tooling. This file includes a bounded export of public pages first, then recent public posts.
Append `.md` to any post or page URL to get the content in Markdown (for example, `/example-post.md`).
## Pages
_No public content available._
## Posts
### How Ecotone Inspired Seven Symfony Messenger Proposals
URL: https://blog.ecotone.tech/how-ecotone-inspired-seven-symfony-messenger-proposals/
Last updated: 2026-09-10T18:53:59.000Z
*Updated on 2026-09-09*
Seven Symfony Messenger feature proposals were drafted in a single morning, covering capabilities that had been requested in Symfony issues since 2019\. The morning they appeared was the morning I've published Ecotone vs Symfony Messenger comparison article.
## Table of contents
- [Seven proposals in one batch](#seven-proposals-in-one-batch)
- [Same narration, same examples, same design goals](#same-narration-same-examples-same-design-goals)
- [Driven from Ecotone's features](#driven-from-ecotones-features)
- [Agentic followers](#agentic-followers)
- [Differences in underlying model stay](#differences-in-underlying-model-stay)
- [Closing](#closing)
📌
Every screenshot below shows both pages as they render live, matching passages highlighted; timestamps visible in them are CEST (UTC+2). The Symfony PRs are proposals under review — Nicolas Grekas calls them "open for discussion".
## Seven proposals in one batch
On Tuesday morning, September 8, I published [Symfony Messenger vs Ecotone: The Real Difference](https://blog.ecotone.tech/ecotone-vs-symfony-messenger-the-real-difference/), my long answer to a question I kept getting as a one-liner: "So it's like Symfony Messenger?"
Three hours later, Nicolas Grekas opened six Symfony Messenger feature PRs in a single batch, all within thirty seconds of each other. A seventh followed few hours later:
- [#65898](https://github.com/symfony/symfony/pull/65898?ref=blog.ecotone.tech) — a `transport:` option on `#[AsMessageHandler]`, so each handler declares its own execution
- [#65899](https://github.com/symfony/symfony/pull/65899?ref=blog.ecotone.tech) — stamp propagation across dispatches, stamps as handler arguments, message identity
- [#65900](https://github.com/symfony/symfony/pull/65900?ref=blog.ecotone.tech) — `MessengerAssertionsTrait`, testing async flows without hand-building a Worker
- [#65901](https://github.com/symfony/symfony/pull/65901?ref=blog.ecotone.tech) — an `outbox:` option on transports: store in the database, relay to the broker
- [#65902](https://github.com/symfony/symfony/pull/65902?ref=blog.ecotone.tech) — retries and a failure transport for the `sync://` transport
- [#65903](https://github.com/symfony/symfony/pull/65903?ref=blog.ecotone.tech) — `ChainStamp`, dispatching messages one after another
- [#65917](https://github.com/symfony/symfony/pull/65917?ref=blog.ecotone.tech) — `DispatchOnFailureStamp`, a failure hook that is itself a message (opened the same afternoon)
Looking at those pull requests, I found them describing what I had written in my article, three hours before the features were raised.
## Same narration, same examples, same design goals
So I checked each description against the article. They were driving the same narration, using the same examples, and setting the same design goals I had set three hours earlier.
The testing PR opens with the article's test code. Same dispatch, character for character, asserting on `ScoreLoanApplication`, the second step of the article's loan flow:
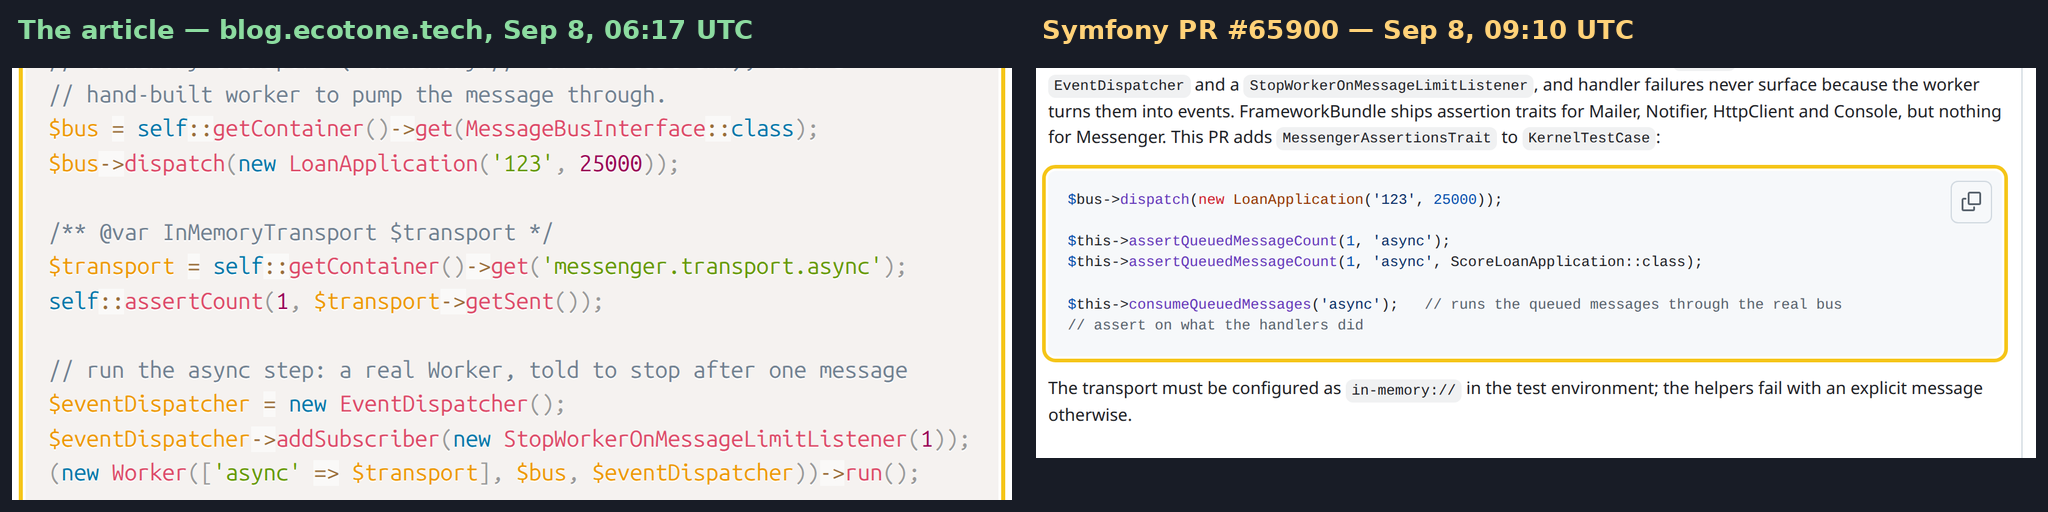
The routing PR demonstrates on the article's pub-sub example: `NotifyCustomer` and `UpdateOrdersList`, both handling `OrderWasPlaced`, changed the way the article argues for:
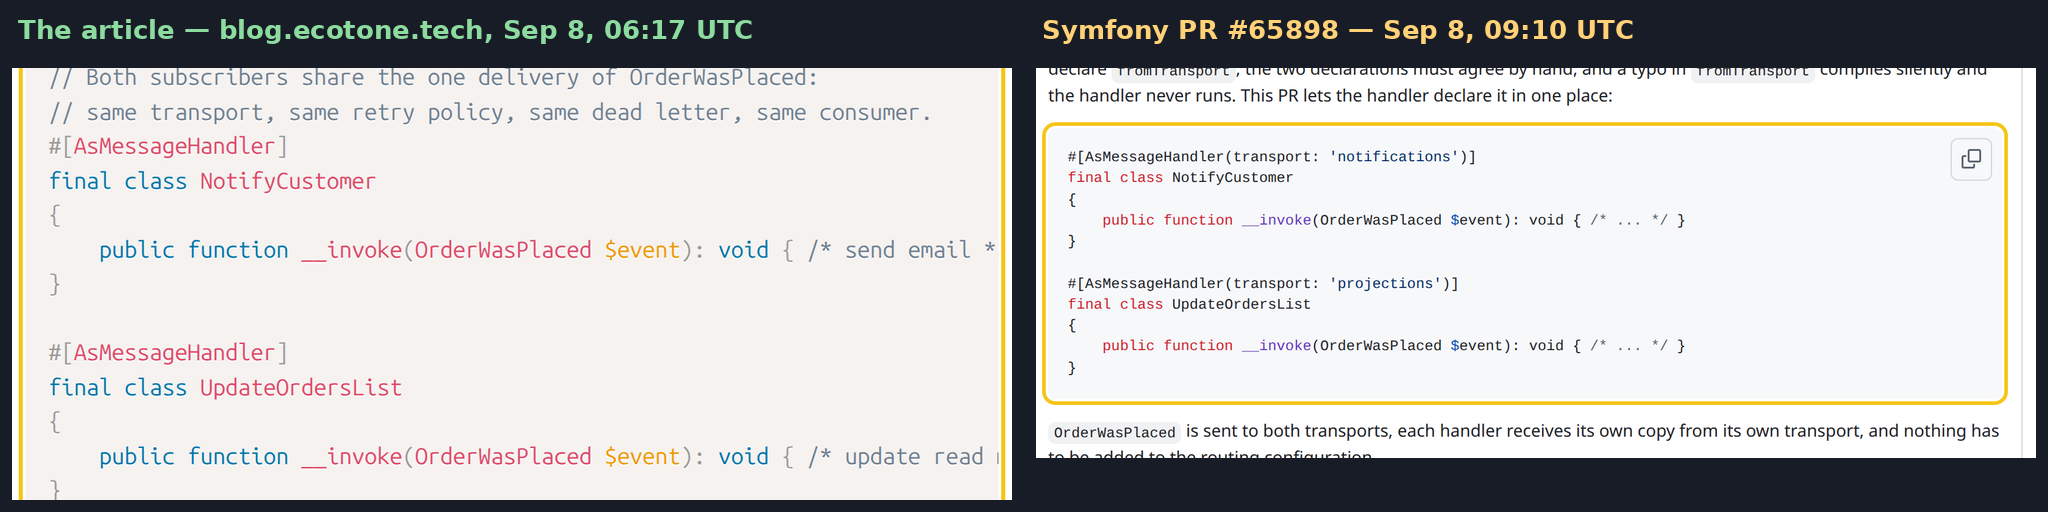
The chaining PR restates the article's critique nearly word for word. The article ends its flow section on "The flow itself is not declarative; it is implied by dispatch calls scattered across handlers" — the PR opens with "The sequence is then implied by dispatch calls scattered across handlers":
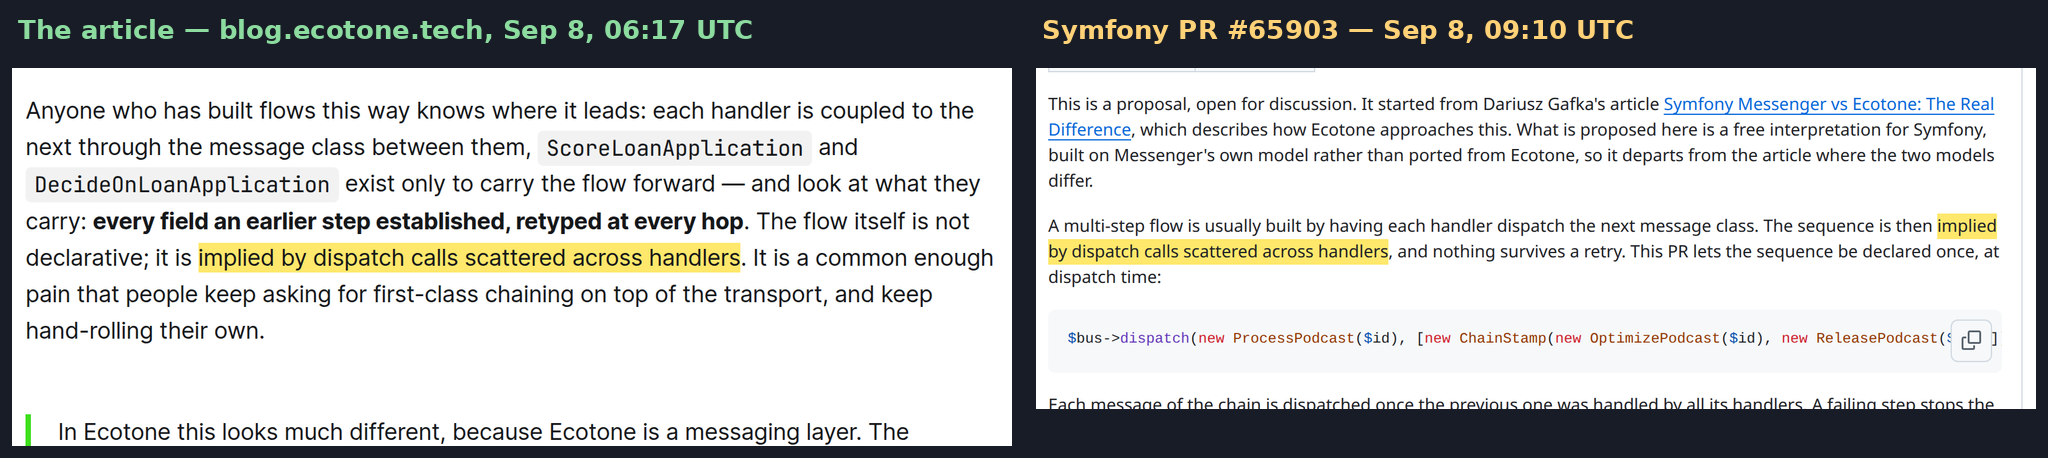
And the stamps PR echoes the article's warning down to the phrasing: "forget once, and the context is silently gone" became "forgetting once loses it silently":
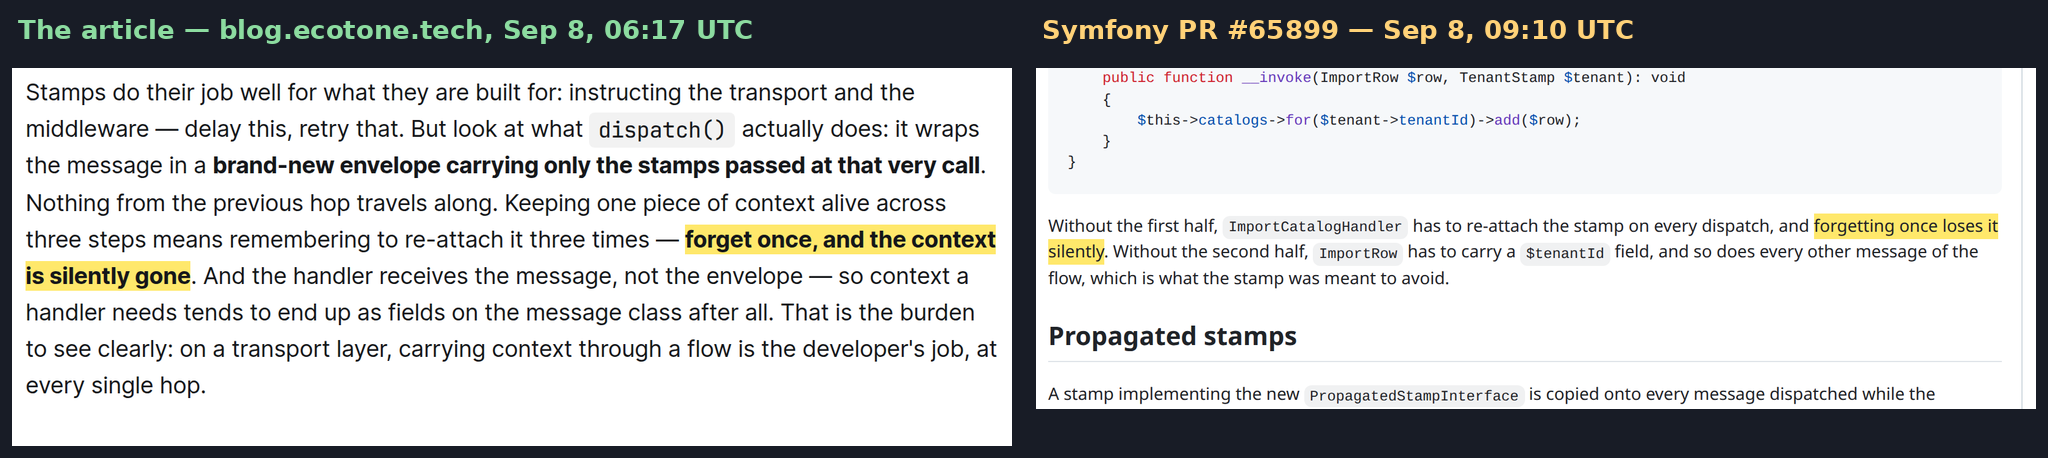
## Driven from Ecotone's features
At that point it was obvious: these proposals were driven from the Ecotone capabilities I had described in the article. Each proposal that Nicolas Grekas opened was related to a section from the article:
| Symfony PR | The article section it mirrors | What it proposes |
| -------------------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------ |
| [#65903](https://github.com/symfony/symfony/pull/65903?ref=blog.ecotone.tech) — ChainStamp | [The messaging layer focuses on flows](https://blog.ecotone.tech/ecotone-vs-symfony-messenger-the-real-difference/#the-messaging-layer-focuses-on-flows) | Declare a multi-step flow once at dispatch |
| [#65899](https://github.com/symfony/symfony/pull/65899?ref=blog.ecotone.tech) — Stamp propagation + handler arguments + identity | The stamps passage of [the flows section](https://blog.ecotone.tech/ecotone-vs-symfony-messenger-the-real-difference/#the-messaging-layer-focuses-on-flows) | Context travels the flow in stamps instead of message-class fields |
| [#65898](https://github.com/symfony/symfony/pull/65898?ref=blog.ecotone.tech) — transport: on #\[AsMessageHandler\] | [Async is about execution, not the message](https://blog.ecotone.tech/ecotone-vs-symfony-messenger-the-real-difference/#async-is-about-execution-not-the-message) | Each handler declares its own execution |
| [#65900](https://github.com/symfony/symfony/pull/65900?ref=blog.ecotone.tech) — MessengerAssertionsTrait | [Testing the flow, piece by piece](https://blog.ecotone.tech/ecotone-vs-symfony-messenger-the-real-difference/#testing-the-flow-piece-by-piece) | Test an async flow without hand-building a Worker |
| [#65901](https://github.com/symfony/symfony/pull/65901?ref=blog.ecotone.tech) — outbox: transport option | [The outbox is channel composition](https://blog.ecotone.tech/ecotone-vs-symfony-messenger-the-real-difference/#the-outbox-is-channel-composition) | Store in the database inside the transaction, relay to the broker |
| [#65902](https://github.com/symfony/symfony/pull/65902?ref=blog.ecotone.tech) — retries + failure transport for sync:// | [Messaging is not only about async](https://blog.ecotone.tech/ecotone-vs-symfony-messenger-the-real-difference/#messaging-is-not-only-about-async) | Queue-grade resilience for synchronous handling |
| [#65917](https://github.com/symfony/symfony/pull/65917?ref=blog.ecotone.tech) — DispatchOnFailureStamp | A failure hook that is itself a message (maps thematically, stacked on #65903) | The failure-flow thread running through the article |
So it became clear to me that Ecotone has been the source of the new functionality now proposed for Symfony Messenger.
## Agentic followers
By then it became clear to me that, that this knowledge have been scrapped from the Ecotone's capabilities from the article using AI, and build against Symfony Messenger model.
The work that I did to write the article, name the problems, describe the context on how those can be solved, provide exact use-case and code examples - was the great source of context for AI agents to actually remap those capabilities to Symfony Messenger's model.
And these are core features. Some of them, as Grekas himself later pointed out, had been waiting in Symfony issues since 2019.
As I felt that I've done all the hard work, for those capabilities to be implemented, I've started to look over those pull requests description, whatever I could find mentioning Ecotone, myself or at least article - but I've found none.
I wrote to Nicolas the very same day, on [the chaining PR](https://github.com/symfony/symfony/pull/65903?ref=blog.ecotone.tech):
> "Some things are literally taken 1:1 from the article, meaning test example, pull request description, and of course most importantly the reason for given PR to exists - the feature itself. So all the hard work was already done, running agents against my article and Ecotone feature was all needed for creating those features into Symfony Messenger."
Nicolas was really fair about it. He [answered the same evening](https://github.com/symfony/symfony/pull/65903?ref=blog.ecotone.tech#issuecomment-5590574302), stated plainly that the work was LLM-driven over the article, and agreed to return the credit to the related pull requests:
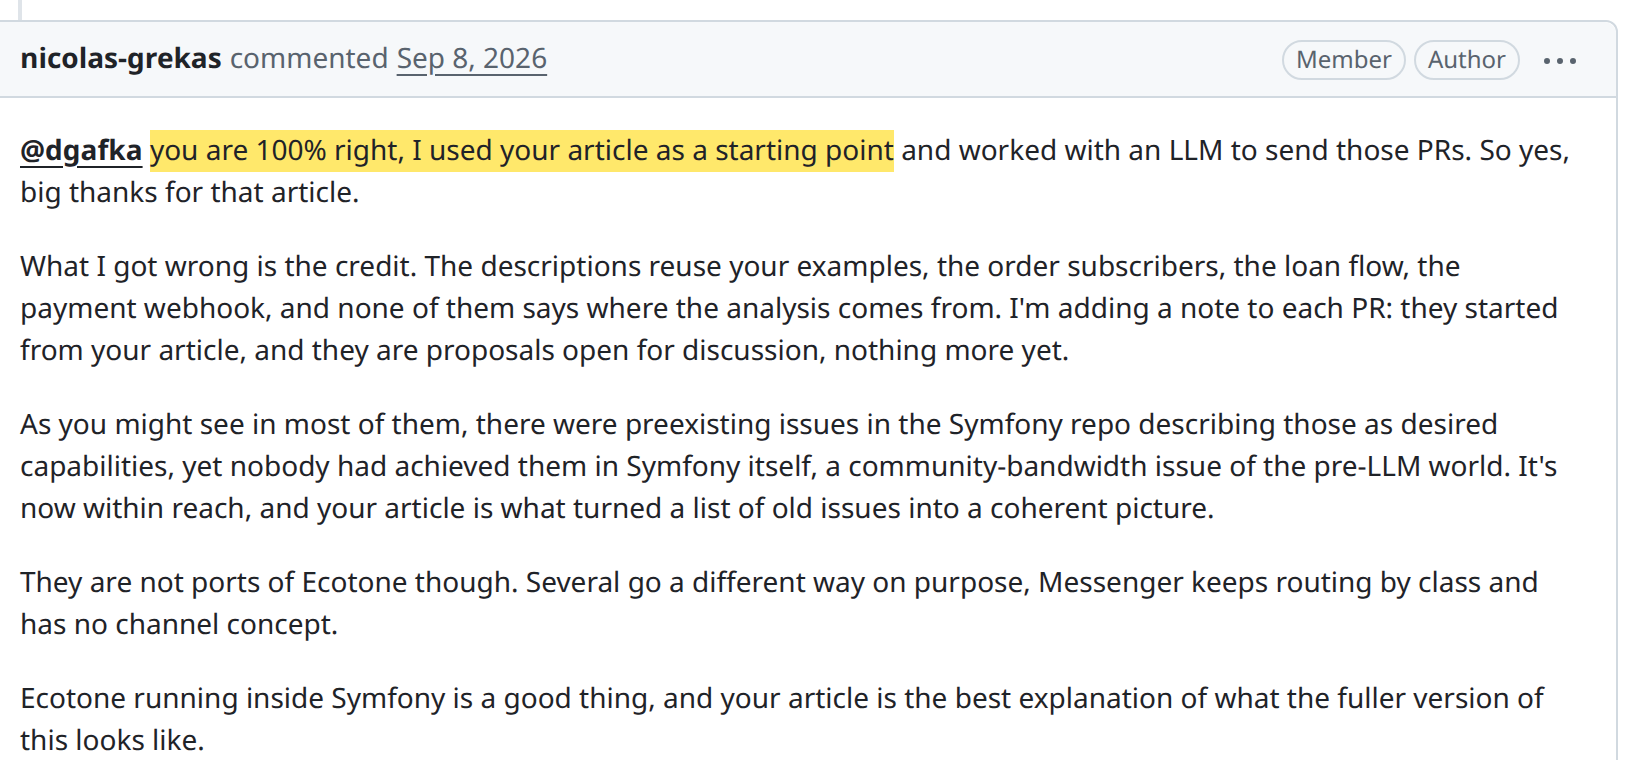
> "you are 100% right, I used your article as a starting point and worked with an LLM to send those PRs. So yes, big thanks for that article. What I got wrong is the credit."
His full reply, as it stands on the PR:
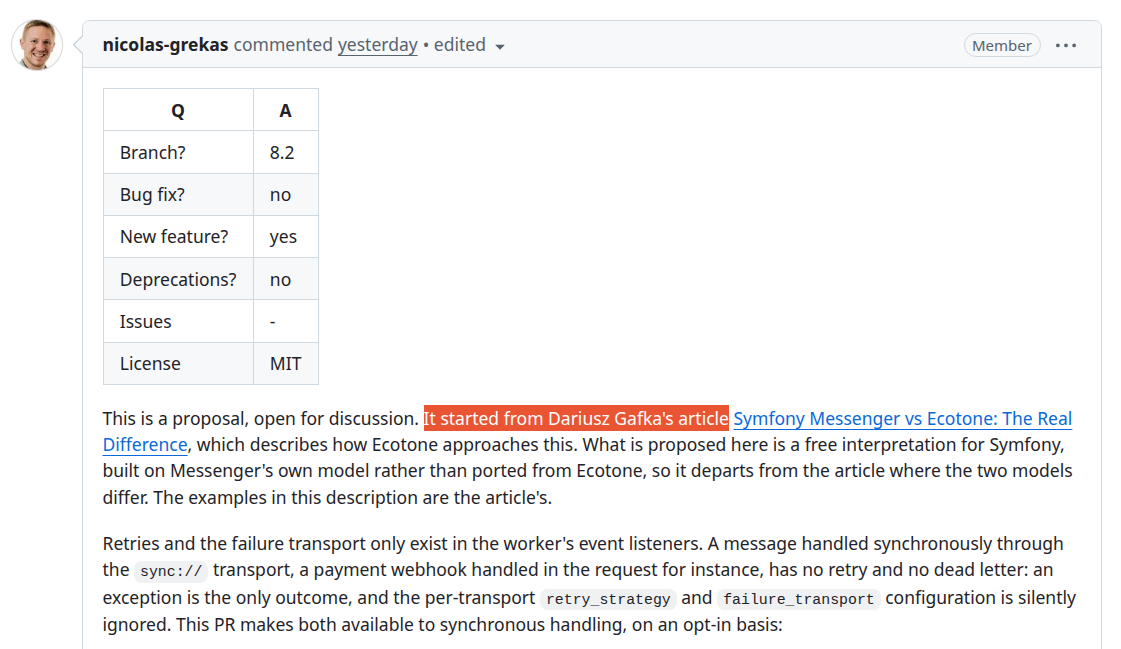
The same evening, Nicolas updated PRs to open with the credit — and I am thankful for this:
## Differences in underlying model stay
If the credit and reference does one thing, I hope it's this: it gives developers a trail to a framework many of them never knew existed.
Plenty assume Symfony Messenger is all they will ever need — and now, from inside Messenger's own proposals, they can discover where these ideas came from: a framework where they are part of the DNA and have carried production workloads for years.
Following that trail is how an informed decision gets made.
> What the trail also shows is what the proposals can and cannot change. Messenger remains a transport layer, so every one of these capabilities has to arrive as a new, separately configured feature — and some won't reach the shape the article describes on that model, which is where end users will feel the limits. Ecotone never had to treat them as separate features, because its messaging model is built on channels. Another handler in the flow is another channel. Failure isolation travels with the channel itself, not with per-feature setup. The outbox relay is a channel too. When the model carries the feature, there is nothing left to wire.
What does it mean in practice? That creating different combination of flow becomes available out of the box, thanks that everything rides on the same messaging model under the hood. Take the Place Order as example: once an order is placed, wait 24 hours, and expire it if it was not paid. The Order here is a plain Doctrine ORM entity — the same one you already have in your Symfony application. Adding `#[Aggregate]` makes it an Ecotone Aggregate: commands land on it directly, and Ecotone stores and fetches it through Doctrine's EntityManager.
```php
#[ORM\Entity]
#[ORM\Table(name: 'orders')]
#[Aggregate]
class Order
{
use WithEvents;
#[ORM\Id]
#[ORM\Column(type: 'string')]
#[Identifier]
private string $orderId;
#[ORM\Column(type: 'boolean')]
private bool $isPaid = false;
#[ORM\Column(type: 'boolean')]
private bool $isExpired = false;
#[CommandHandler]
public static function place(PlaceOrder $command): self
{
$order = new self();
$order->orderId = $command->orderId;
$order->recordThat(new OrderWasPlaced($order->orderId));
return $order;
}
}
```
The 24-hour wait is where the model shows itself. There is no scheduler to configure, no state table to poll, and no extra class to write — the Aggregate itself subscribes to the event it recorded, and the subscription is a delayed message. This method sits inside the same `Order` entity:
```php
#[ORM\Entity]
#[ORM\Table(name: 'orders')]
#[Aggregate]
class Order
{
...
#[Delayed(TimeSpan::withMinutes(24 * 60))] // 24 hours after placing
#[Asynchronous('orders')]
#[EventHandler(endpointId: 'order.expire.when.unpaid')]
public function expire(OrderWasPlaced $event): void
{
if (!$this->isPaid) {
$this->isExpired = true;
}
}
```
*`OrderWasPlaced` waits 24 hours on the channel, then lands back on the very Order that recorded it — Ecotone loads the entity by the `orderId` the event carries, and the method does nothing if the order was paid in the meantime.*
And this is just one combination. When messaging sits at the core of the architecture, every building block can join every other — delays, aggregates, channels, retries — so whatever flow your business comes up with, there is usually a way to assemble it with messaging as a unifying layer.
## Closing
This story could have ended in a flame war, and it ended in credit lines instead. Nicolas took inspiration, I asked for the source to be named, he named it the same evening and thanked me for the article — and Symfony came out of this with feature proposals, and Ecotone came out of this with more visibility than it had before.
My part of the invitation stands: the article that inspired the proposals is the deepest comparison of the two models I know how to write, and Ecotone itself is one `composer require ecotone/symfony-bundle` away, inside the Symfony application you already run.
Once you try it, you will feel it.
[Read the full comparison](https://blog.ecotone.tech/ecotone-vs-symfony-messenger-the-real-difference/)
---
*About the author: Dariusz Gafka is a Software Architect and author of the* [*Ecotone Framework*](https://github.com/ecotoneframework/ecotone?ref=blog.ecotone.tech)*. He writes about event sourcing, CQRS, and PHP architecture patterns.*
### Symfony Messenger vs Ecotone: The Real Difference
URL: https://blog.ecotone.tech/ecotone-vs-symfony-messenger-the-real-difference/
Last updated: 2026-09-08T06:17:24.000Z
*Updated on 2026-09-03*
I am often asked what the difference is between Ecotone and Symfony Messenger, and the honest answer needs more room than a Reddit or Twitter comment. Messenger is a transport layer, and it does that job well: it gets a message from a publisher to a handler and hides the broker underneath. Ecotone's difference sits one level up, in what the abstraction is built around, and it only becomes visible once a flow has more than one step.
> **TL;DR:** Symfony Messenger is a transport layer — it delivers a message to its handler and hides the broker underneath. Ecotone is a messaging layer — handlers bind to channels, so multi-step flows are wired once instead of redispatched at every step, and its architecture layer provides building blocks on top of that (Aggregates, Sagas, Projections, Orchestrators) which inherits retries, dead-lettering and asynchronicity.
## Table of contents
- [The question behind the comparison](#the-question-behind-the-comparison)
- [Symfony Messenger is a transport layer](#symfony-messenger-is-a-transport-layer)
- [The messaging layer focuses on flows](#the-messaging-layer-focuses-on-flows)
- [Dictate routing in business logic](#dictate-routing-in-business-logic)
- [Async is about execution, not the message](#async-is-about-execution-not-the-message)
- [Testing the flow, piece by piece](#testing-the-flow-piece-by-piece)
- [The outbox is channel composition](#the-outbox-is-channel-composition)
- [Messaging is not only about async](#messaging-is-not-only-about-async)
- [Adopt it one flow at a time](#adopt-it-one-flow-at-a-time)
- [Ecotone is an architecture layer](#ecotone-is-an-architecture-layer)
- [Wrapping up](#wrapping-up)
ℹ️
Prerequisites — PHP 8.2+, hands-on experience with any message bus helps. Everything shown is core open-source Ecotone except where marked as Ecotone Enterprise.
## The question behind the comparison
Ecotone vs Symfony Messenger is a question I keep answering in places built for one-liners. Under one of my recent Reddit posts about Ecotone, one of the comments boiled down to: "So it's like Symfony Messenger?" - The implication was clear: if two looks the same way, why bother to change? Another comment put the same sentiment directly: "Why not just use Symfony Messenger. Does everything well."
Messenger is the tool most PHP developers already know and have hands-on experience with, which is exactly why Ecotone gets compared to it most. The honest answer needs more room than a comment thread gives, so this is my longer answer. And the first thing to state plainly about Symfony Messenger is what kind of abstraction it is.
---
## Symfony Messenger is a transport layer
A transport layer does one job, and does it well: it gets a message from one place to another.
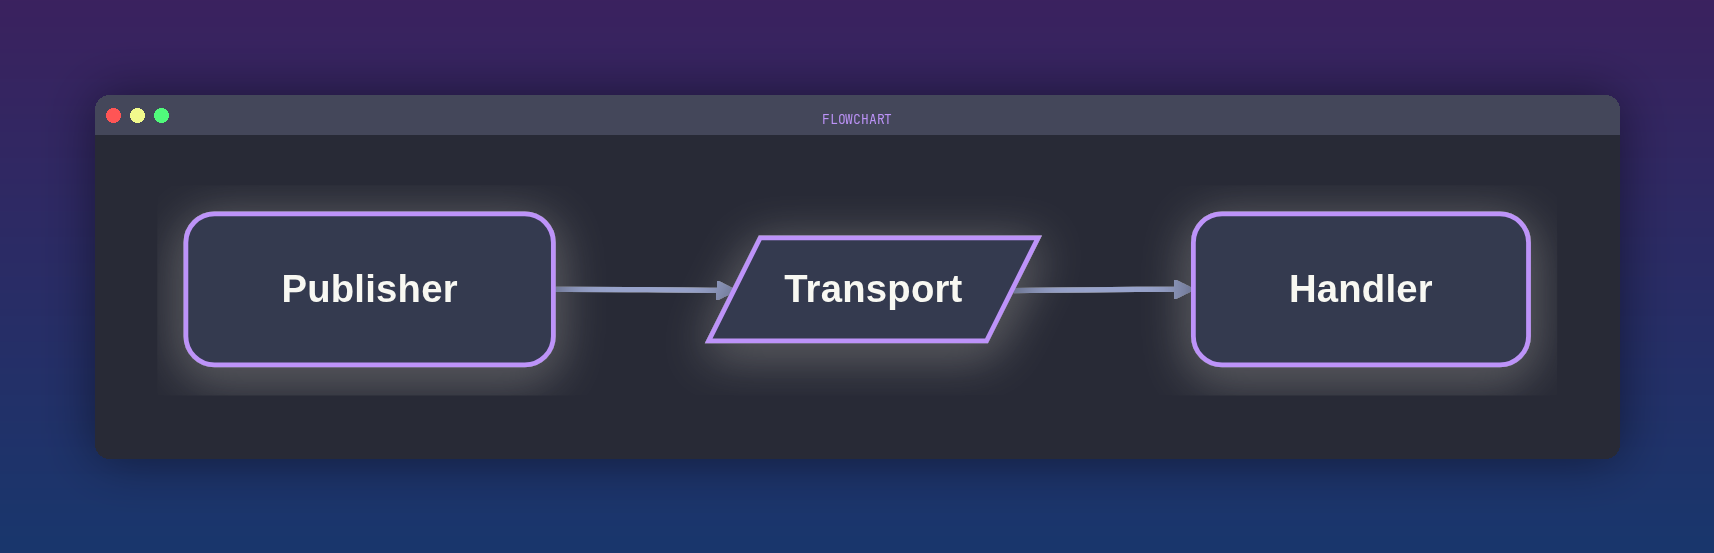
On one side there is a publisher, on the other side the handler we want the message delivered to. Everything in between — connecting to the broker, converting the message, consuming it — is complexity Messenger absorbs. Absorbing it is its main goal.
In practice that means we get to work with the message as a plain class. Messenger serializes it into whatever the underlying message broker understands, moves it across, and deserializes it back into the class we sent.
```php
// Symfony Messenger: dispatch a message class,
// the handler registered for that class receives it.
use Symfony\Component\Messenger\Attribute\AsMessageHandler;
final readonly class OrderPlaced
{
public function __construct(public string $orderId) {}
}
// Sending side ($bus is Messenger's MessageBusInterface)
$bus->dispatch(new OrderPlaced('123'));
// Receiving side: the handler registered for the OrderPlaced class
#[AsMessageHandler]
final class SendOrderConfirmation
{
public function __invoke(OrderPlaced $message): void
{
// react to the placed order
}
}
```
*Dispatch a class, the handler registered for that class receives it.*
**Sending messages this way is much easier than integrating with a broker directly, where connecting, converting and consuming are all yours to handle.** That ease is the transport layer's value, and it is real. Messenger goes further than bare delivery, too: a message travels wrapped in an envelope, stamps let metadata travel with the payload, and middleware lets you hook into the dispatch process itself.
Those are extras on top of the model. The core stays the same: deliver a message from sender to handler. **Where things start to diverge is what happens when one delivery is not the whole story.**
---
## The messaging layer focuses on flows
**The messaging layer focuses on message flows rather than message transport.** At a high level the two can look similar — there is a bus, there are messages, there are handlers — but the abstraction driving them is different.
> The messaging layer is built to help with message flows: take a message and pass it through steps. A single message can travel through different handlers, because the message itself is not coupled to a destination.
To see what that means in practice, take a flow every bank and lending platform runs: loan application approval. An application comes in, and before anyone can say yes it moves through steps — the applicant is verified (does the declared identity and income hold up?), the application is scored (how risky is this loan?), and only then a decision falls. The order is not an implementation detail, it is business policy: nobody scores an unverified applicant, and nobody decides without a score. And each step adds knowledge the next one needs.
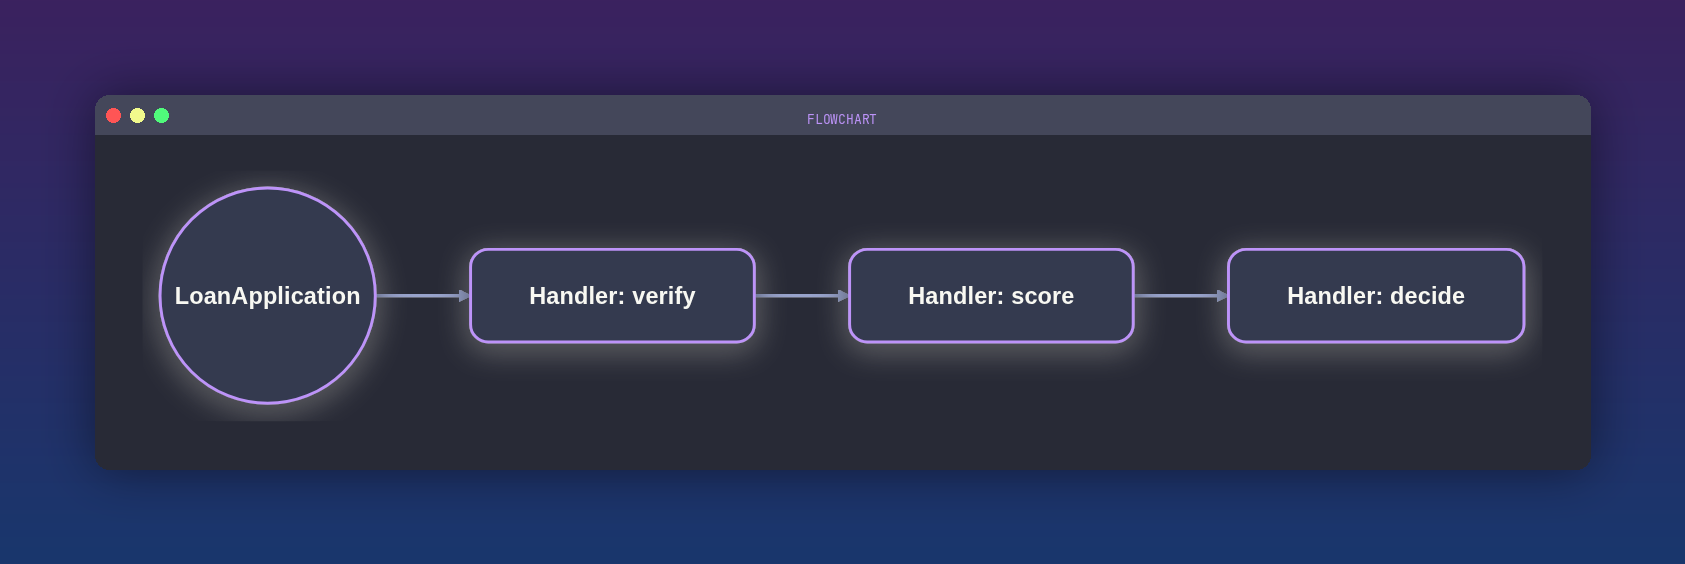
To be fair before any code: when all three steps run in one process and are allowed to fail together, a single handler calling three services could be right call. The steps become messages the moment one of them must survive a crash, call an external system, or run in the background — and a loan flow, with a credit bureau in the middle of it, is exactly that case. That is the flow we are building.
> When building a flow like this on Symfony Messenger, we will often need to retrigger the publisher: the handler that finished its step creates the next message class and dispatches it, so the next handler can be reached. And because a redispatch is a new message, everything the earlier steps established has to be carried in that class — the fields accumulate at every hop.
```php
// Symfony Messenger: the loan flow — each step is its own handler, and
// moving forward means creating the next message and dispatching again.
use Symfony\Component\Messenger\Attribute\AsMessageHandler;
use Symfony\Component\Messenger\MessageBusInterface;
#[AsMessageHandler]
final class VerifyApplicantHandler
{
public function __construct(
private ApplicantVerifier $verifier,
private MessageBusInterface $bus,
) {}
public function __invoke(LoanApplication $application): void
{
$verification = $this->verifier->verify($application);
// the same data, repackaged into a new class plus what this step
// added — reusing LoanApplication is not an option here: the class
// is the routing, dispatching it again would land right back here
$this->bus->dispatch(new ScoreLoanApplication(
$application->applicationId,
$application->amount,
$verification,
));
}
}
#[AsMessageHandler]
final class ScoreLoanApplicationHandler
{
public function __construct(
private RiskScoring $scoring,
private MessageBusInterface $bus,
) {}
public function __invoke(ScoreLoanApplication $message): void
{
$score = $this->scoring->score($message);
$this->bus->dispatch(new DecideOnLoanApplication(
$message->applicationId,
$message->amount,
$message->verification, // retyped from the previous class
$score,
));
}
}
#[AsMessageHandler]
final class DecideOnLoanApplicationHandler
{
public function __invoke(DecideOnLoanApplication $message): void
{
// approve or reject, based on everything carried along
}
}
```
*Each step finishes by dispatching the next message class to reach the next handler.*
Anyone who has built flows this way knows where it leads: each handler is coupled to the next through the message class between them, `ScoreLoanApplication` and `DecideOnLoanApplication` exist only to carry the flow forward — and look at what they carry: **every field an earlier step established, retyped at every hop**. The flow itself is not declarative; it is implied by dispatch calls scattered across handlers. It is a common enough pain that people keep asking for first-class chaining on top of the transport, and keep hand-rolling their own.
> In Ecotone this looks much different, because Ecotone is a messaging layer. The message is not bound to a destination, so pushing a message from one place to another is a matter of simple binding. Between the sending bus and the receiving handler there is a message channel.
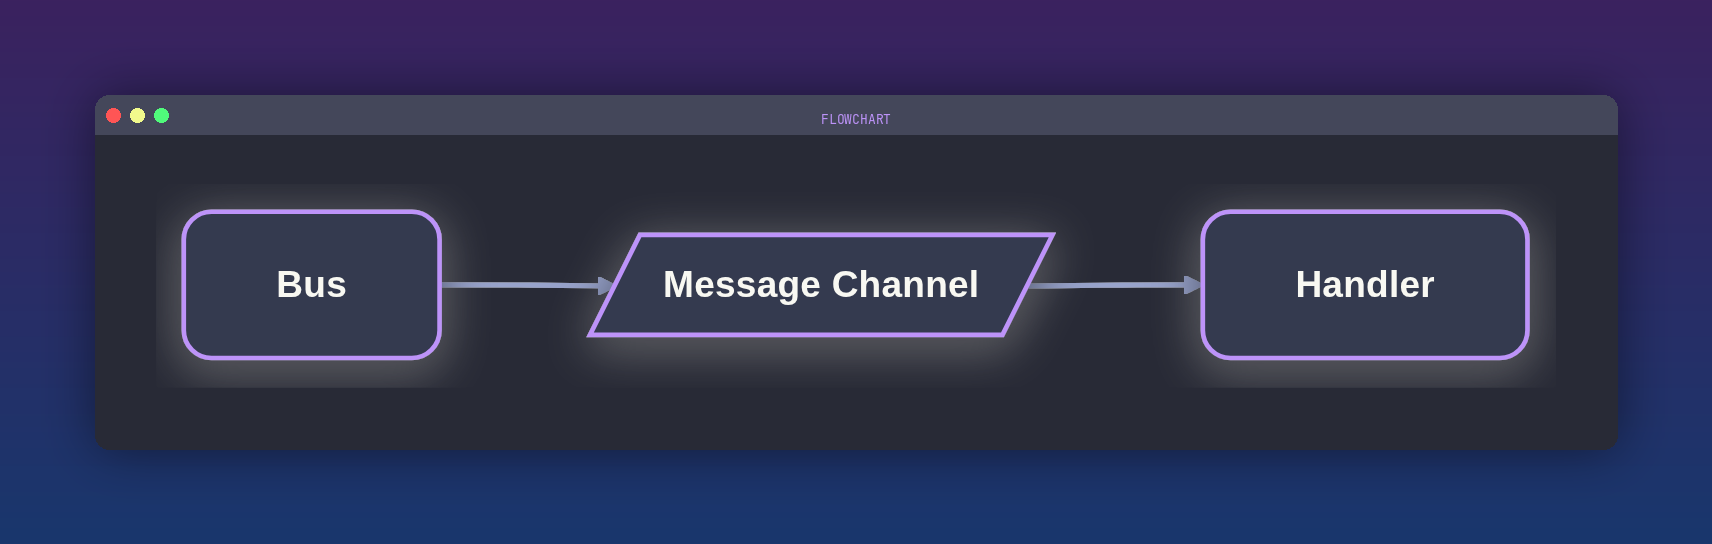
The message is just a data record flying over the channel. **The handler is bound to the channel, not to the message, so you can take any message and pass it through.** This model also allows handlers to be connected into flows, because the wiring abstraction is the channel: one handler's output channel is simply the next handler's input channel. Here is the exact same loan flow — verify, score, decide — built the messaging way:
```php
// Ecotone: the same loan flow, three handlers connected through channels.
// Each handler's output channel is the next handler's input channel,
// and a handler's return value travels onward as the next message payload.
final class LoanApplicationProcess
{
#[CommandHandler(routingKey: 'loan.apply', outputChannelName: 'loan.score')]
public function verify(LoanApplication $application): LoanApplication
{
$verification = $this->verifier->verify($application);
return $application->addVerification($verification);
}
#[InternalHandler(inputChannelName: 'loan.score', outputChannelName: 'loan.decide')]
public function score(LoanApplication $application): LoanApplication
{
return $application->withRiskScore($this->scoring->score($application));
}
#[InternalHandler(inputChannelName: 'loan.decide')]
public function decide(LoanApplication $application): void
{
// approve or reject
}
}
```
*The same loan flow wired through channel names, readable in one place.*
Look closely at `verify` and `score`: each takes the `LoanApplication`, adds what it just established — `addVerification`, `withRiskScore` — and returns it. **The same message simply continues over the channel in its new state**; a handler is free to modify the payload and pass it through, because the message is just data flying between channels. On Symfony Messenger each of those steps had to build a brand-new message class and dispatch it, only to carry the changed state forward — and reusing the class was never an option there, because **the class is the routing**.
> No intermediate message classes, no redispatching — the flow reads top to bottom in one place, and the business policy (verify, then score, then decide) is visible as wiring.
Those channel names are not grep-and-pray strings, either. The binding is a compiled process: Ecotone builds and verifies the wiring when the application is compiled, so the feedback comes without executing any code — a misspelled channel fails the build with the exact name in hand, not in production at 3 a.m. And nothing stops the names from living as constants.
And here is where the channel abstraction actually pays off. Scoring calls the credit bureau, so we want it queued and retried — the step must survive a crash. In Ecotone that is one attribute on that one step, and the flow does not change:
```php
// Going asynchronous is one attribute on one step — the wiring stays.
#[Asynchronous('scoring')]
#[InternalHandler(inputChannelName: 'loan.score', outputChannelName: 'loan.decide', endpointId: 'loan.scoring')]
public function score(LoanApplication $application): LoanApplication
{
return $application->withRiskScore($this->scoring->score($application));
}
```
*One attribute makes the step asynchronous; the flow's wiring stays untouched.*
On the transport layer this exact change is where the redispatch pattern becomes mandatory: a new message class, a transport routed in configuration, a handler dispatching it — the flow restructured just to change how one step executes - which Ecotone's messaging layer comes down to `#[Asynchronous]`.
There is one more thing the messaging layer gives this flow. Not everything a step establishes belongs in the domain object — who verified, when, with which provider, what the raw score was. That is context about the message, not the message itself.
Symfony Messenger has a concept for exactly this: stamps — metadata attached to the envelope a message travels in. Attaching one means writing a stamp class and adding it at dispatch:
```php
// Symfony Messenger: metadata travels as a stamp on the envelope.
use Symfony\Component\Messenger\Stamp\StampInterface;
final readonly class VerificationStamp implements StampInterface
{
public function __construct(
public string $provider,
public DateTimeImmutable $verifiedAt,
) {}
}
$this->bus->dispatch(
new ScoreLoanApplication(/* ...all the fields again... */),
[new VerificationStamp('kyc-x', $this->clock->now())],
);
```
*A stamp class, attached at dispatch, riding the envelope.*
Stamps do their job well for what they are built for: instructing the transport and the middleware — delay this, retry that. But look at what `dispatch()` actually does: it wraps the message in a **brand-new envelope carrying only the stamps passed at that very call**. Nothing from the previous hop travels along. Keeping one piece of context alive across three steps means remembering to re-attach it three times — **forget once, and the context is silently gone**. And the handler receives the message, not the envelope — so context a handler needs tends to end up as fields on the message class after all. That is the burden to see clearly: on a transport layer, carrying context through a flow is the developer's job, at every single hop.
In a messaging layer this context has a natural home, because a real Message flies over the channel — payload plus headers. A handler can enrich the flow's metadata and let the payload continue untouched. In fact, the verification from our flow does not even need to modify the domain object at all: the verify step can attach it as a header instead, and the `LoanApplication` continues onward exactly as it arrived:
```php
// Ecotone: enrich the flow's metadata instead of the payload.
// The returned array is merged into the message headers; the
// LoanApplication continues onward unchanged.
#[ChangingHeaders]
#[CommandHandler(routingKey: 'loan.apply', outputChannelName: 'loan.score')]
public function verify(LoanApplication $application): array
{
return ['verification' => $this->verifier->verify($application)];
}
#[InternalHandler(inputChannelName: 'loan.decide')]
public function decide(
LoanApplication $application,
#[Header('verification')] Verification $verification,
): void
{
// decide with the verification at hand
}
```
*The enrichment travels with the message, every downstream handler can read it — and neither a message class nor the domain object had to grow a field for it.*
So why do the two keep getting confused between Messaging and Transport layer, between Ecotone and Symfony Messenger? Because for simple cases they look the same. A flow with a single message handler shows no difference at all: one message goes in, one handler receives it, done. The difference becomes more and more obvious as flows grow beyond a single handler, and the more advanced flow - the greater the difference.
---
## Dictate routing in business logic
Say a message should reach different handlers depending on its content. On Symfony Messenger, which handler runs is decided by the message class: handlers bind to the class, and that binding is fixed up front. A decision the business makes at runtime — "digital orders take a different path" — has no class to live in, so it lands on you: code has to decide, then create the right message to reroute into each flow, then dispatch again.
```php
// Symfony Messenger take on dynamic routing: decide in code, then repack
// the same data 1:1 into the class of the chosen flow, dispatch again.
use Symfony\Component\Messenger\Attribute\AsMessageHandler;
use Symfony\Component\Messenger\MessageBusInterface;
#[AsMessageHandler]
final class HandlePlaceOrder
{
public function __construct(private MessageBusInterface $bus) {}
public function __invoke(PlaceOrder $order): void
{
if ($order->isDigital) {
$this->bus->dispatch(new DeliverDigitalOrder(
$order->orderId,
$order->productId,
$order->customerEmail,
));
} else {
$this->bus->dispatch(new ShipPhysicalOrder(
$order->orderId,
$order->productId,
$order->customerEmail,
));
}
}
}
```
*Deciding, repacking the same data 1:1, dispatching again — per branch.*
Notice what the two branches actually do: nothing. The data does not change at all — **every property is repacked 1:1**, and `DeliverDigitalOrder` and `ShipPhysicalOrder` exist only so the same payload can reach a different handler. More often than not, this kind of routing simply does not get built — or it grows into complex, hard-to-test end to end code.
> With messaging this becomes easy, because it comes down to rerouting the message to a different channel. In Ecotone a router is a method that returns the name of the channel the same message should continue on — the `PlaceOrder` travels on untouched:
```php
// Ecotone: a Router returns the channel the message should be routed to.
final class OrderRouter
{
#[Router(inputChannelName: 'order.place')]
public function route(PlaceOrder $order): string
{
return $order->isDigital
? 'order.deliverDigital'
: 'order.shipPhysical';
}
}
```
*Routing as business logic: return the channel, the layer delivers.*
A router can also return several channel names, fanning the same message out to multiple flows. The handler on the other side never learns who decided, and the router never learns what happens next. The channel does the wiring.
---
## Async is about execution, not the message
So far the flows were chains. Events introduce the other shape: publish–subscribe. When `OrderWasPlaced` happens, several flows react — notify the customer, update the orders-list read model. Each subscriber is its own feature, its own flow. And this is usually the moment we want to go asynchronous.
> Here the messaging layer draws a line worth seeing clearly: **a message is a data record**. It carries what happened — it does not state how it wants to be executed. Asynchronicity is a property of the execution, not of the data.
On Symfony Messenger, asynchronous is declared on the message: the class is routed to a transport.
```yaml
# messenger.yaml: the MESSAGE is what goes async — the class routes
# to a transport, and every handler subscribed to it rides that delivery.
framework:
messenger:
routing:
App\Event\OrderWasPlaced: async
```
*Async declared where the class is routed: on the message.*
```php
// Both subscribers share the one delivery of OrderWasPlaced:
// same transport, same retry policy, same dead letter, same consumer.
#[AsMessageHandler]
final class NotifyCustomer
{
public function __invoke(OrderWasPlaced $event): void { /* send email */ }
}
#[AsMessageHandler]
final class UpdateOrdersList
{
public function __invoke(OrderWasPlaced $event): void { /* update read model */ }
}
```
*Two features, one delivery — they ride together.*
In Ecotone the event stays a data record, and each handler declares its own execution — that is what `#[Asynchronous]` marks:
```php
// Ecotone: async is marked on the EXECUTION. Each handler picks its own
// channel and receives its own copy of the event — or stays synchronous.
final class OrderSubscribers
{
#[Asynchronous('notifications')]
#[EventHandler(endpointId: 'order.notify')]
public function notifyCustomer(OrderWasPlaced $event): void { /* send email */ }
#[Asynchronous('projections')]
#[EventHandler(endpointId: 'order.project')]
public function updateOrdersList(OrderWasPlaced $event): void { /* update read model */ }
#[EventHandler]
public function audit(OrderWasPlaced $event): void { /* same event, synchronous */ }
}
```
*Each handler declares its own execution; the event message never says how it wants to be run.*
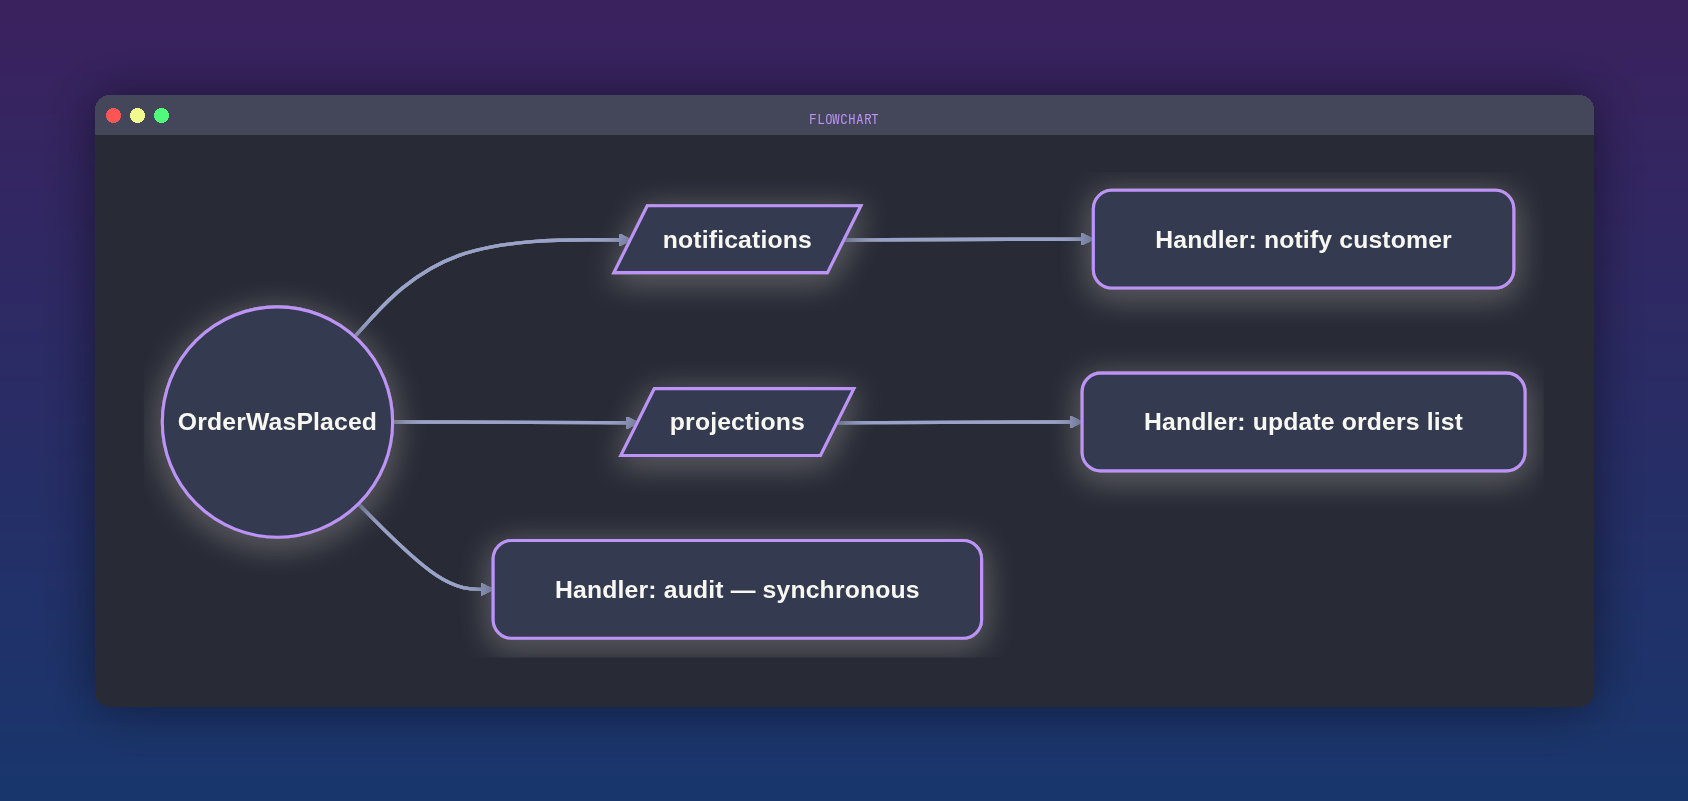
Each asynchronous handler receives its own copy of the event, delivered over its own channel. That makes isolation the default, not a project: when sending the email fails and retries, the orders-list projection is not touched — it already consumed its own copy. Each flow retries alone, delays alone, scales alone, dead-letters alone — and can even stay synchronous while its sibling goes async, because the message never said how it wanted to be executed.
---
## Testing the flow, piece by piece
The messaging model pays one more dividend that rarely makes it into comparisons: testing. When flows are built from handlers bound to channels, you can pick the part of the flow you want to test, isolate it out, and run against just that.
First, the transport-layer version. Testing our loan flow with the scoring step asynchronous means testing across a transport, and the usual glue looks like this — an in-memory transport, assertions against what was sent, and a hand-built worker to pump the queued message through the second step:
```php
// Symfony Messenger: testing a flow whose second step is async —
// in-memory transport ('in-memory://' in the test env), then a
// hand-built worker to pump the message through.
$bus = self::getContainer()->get(MessageBusInterface::class);
$bus->dispatch(new LoanApplication('123', 25000));
/** @var InMemoryTransport $transport */
$transport = self::getContainer()->get('messenger.transport.async');
self::assertCount(1, $transport->getSent());
// run the async step: a real Worker, told to stop after one message
$eventDispatcher = new EventDispatcher();
$eventDispatcher->addSubscriber(new StopWorkerOnMessageLimitListener(1));
(new Worker(['async' => $transport], $bus, $eventDispatcher))->run();
// ...now assert on what ScoreLoanApplicationHandler did
```
*Infrastructure standing between the test and the question it asks.*
In Ecotone the test speaks the flow's own language. You choose the classes under test, back the channel with an in-memory queue, and release the asynchronous step by hand — synchronously, inside the test:
```php
// Ecotone: pick the flow, run it, release the async step in the test.
$ecotone = EcotoneLite::bootstrapFlowTesting(
[LoanApplicationProcess::class],
[LoanApplicationProcess::class => new LoanApplicationProcess($verifier, $scoring)],
enableAsynchronousProcessing: [
SimpleMessageChannelBuilder::createQueueChannel('scoring'),
],
);
$ecotone->sendCommandWithRoutingKey('loan.apply', new LoanApplication('123', 25000));
$ecotone->run('scoring'); // executes score — and decide follows over the wiring
// ...assert on the outcome
```
*Pick the flow, run it, release the async step by hand.*
This is also how every Ecotone behavior in this article was checked while writing it — including the isolation proof a few paragraphs back: the same bootstrap, a failing subscriber, two `run()` calls. The flow you ship is the flow you test, one piece at a time.
---
## The outbox is channel composition
Once flows go asynchronous, another question appears, and it decides whether your system can be trusted: the database change and the message about it must agree. Publish before the transaction commits, and a rollback leaves your system announcing something that never happened. Commit first and publish after, and a broker outage right between the two loses the message: the order exists, but the rest of the system will never hear about it.
The known answer is the outbox pattern: store the outgoing message in the database, inside the same transaction as the business change. On Symfony Messenger the closest built-in move is routing the message to the Doctrine transport, so the insert rides the business transaction:
```yaml
# messenger.yaml: the Doctrine transport becomes the outbox — the insert
# joins the business transaction, and the database becomes the queue.
framework:
messenger:
transports:
outbox: 'doctrine://default'
routing:
App\Message\OrderWasPlaced: outbox
```
*The outbox in the transport model: the outgoing message routed to the Doctrine transport.*
That works — but now the queue is the database: workers poll the table, and every consumer you add polls it harder. Manageable at moderate scale, yet the load lands on the very database you were protecting, and it grows with the traffic you meant to offload.
An outbox is not only about storing messages in a database, though. What you actually want is to store in the database yet handle from the broker, so consumers scale against RabbitMQ, SQS or Kafka, not against your writes. Because in Ecotone channels are named building blocks, that combination is composition — a Combined Channel:
```php
#[ServiceContext]
public function orderChannel(): CombinedMessageChannel
{
return CombinedMessageChannel::create(
'orders',
['database_channel', 'rabbit_channel'], // outbox first, broker second
);
}
```
*One named channel composed from two: database for atomicity, broker for consumption.*
A handler goes asynchronous over the combined channel like over any other:
```php
#[Asynchronous('orders')]
#[EventHandler(endpointId: 'notifyAboutNewOrder')]
public function notifyAboutNewOrder(OrderWasPlaced $event): void
{
// stored with the business transaction, handled on the broker
}
```
*Same attribute as any async handler; the outbox is the channel's concern.*
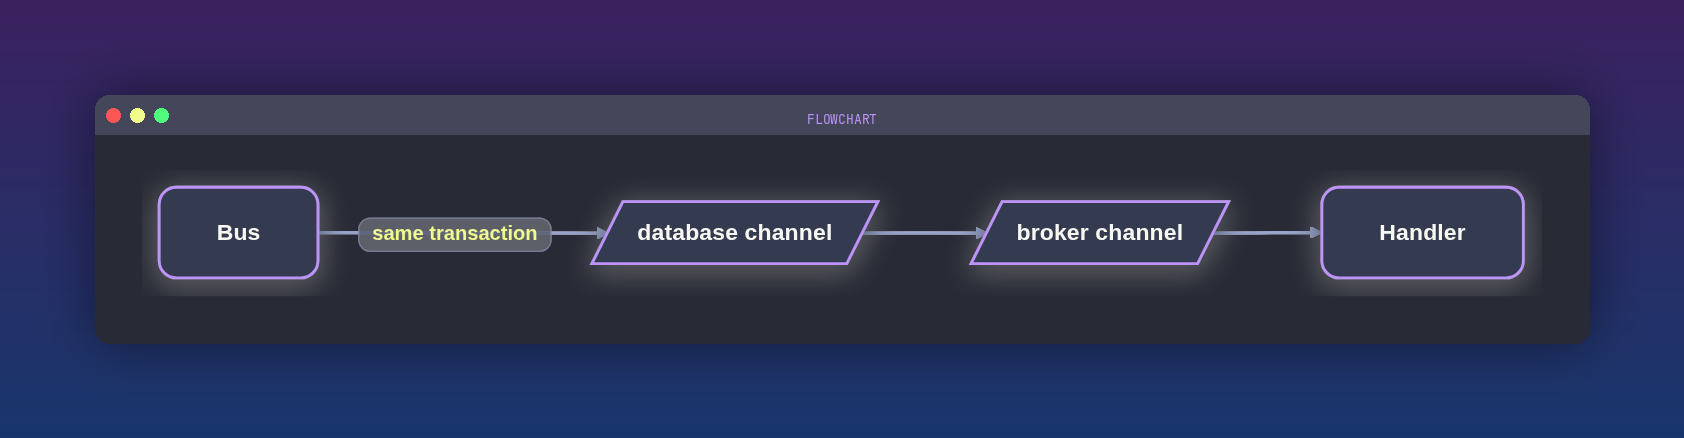
The message is written to the database channel in the same transaction as your business state, then forwarded to the broker channel, and handled there. The stored message and the committed change go together, and scaling workers is a broker concern again, not database load.
---
## Messaging is not only about async
It would be easy to walk away thinking the messaging layer is a story about asynchronous processing. **The layer is about communication, whether that communication happens asynchronously or synchronously.** The flow is a chain of channels either way; async is just a property of a channel. And that means everything the layer gives — retries, dead letter, interception — is available even when the whole flow runs synchronously.
Take a payment webhook. The provider calls your HTTP endpoint and you handle it right there, in the same request, no queue in sight. But a webhook is precious: if handling throws and you answer with an error, you are betting on the provider's redelivery policy. What you want is the resilience of a queue, without the queue.
In Ecotone the CommandBus itself is an entrypoint into the messaging layer, so you can extend it and shape the flow it opens. Retries and the dead letter are core open-source Ecotone on asynchronous flows; what follows brings them to a fully synchronous one as a single interface, and this extended bus is part of Ecotone Enterprise — judge for yourself whether it earns that. A bus built for receiving payment webhooks:
```php
#[InstantRetry(retryTimes: 2)]
#[ErrorChannel('dbal_dead_letter')]
interface PaymentWebhookBus extends CommandBus
{
}
```
*Two attributes shape the whole flow behind this bus.*
```php
// The webhook controller — a fully synchronous flow
public function paymentWebhook(Request $request, PaymentWebhookBus $bus): Response
{
$bus->sendWithRouting('payment.webhook.received', $request->toArray());
return new Response();
}
```
*The controller stays a controller; the resilience lives in the flow it opens.*
There is no command class here, and that is not an omission. A routing key and an array are enough: what flies over the channel is simply the payload of the Message, so the handler can type-hint an array just as well as a class.
Handling still happens inside the request, synchronously. But the flow is now shaped the way we wanted: a transient failure — a deadlock, a hiccup on an external call — is retried instantly before anyone hears about it. An unrecoverable failure does not bubble up as a 500: the message lands in the dead letter, stored for review and replay, this can happen, because we store it as a Message - and Message can be stored in Dead Letter Storage no matter if it's being executed synchronously or asynchronously.
---
## Adopt it one flow at a time
One practical note before the last stop: adopting a messaging layer is not a rewrite. Ecotone runs alongside Symfony Messenger in the same application — nothing about your existing handlers has to move. Pick one flow, the one whose redispatching hurts most, build it on channels, and let the rest follow only when it earns it. Ecotone can even use your existing [Symfony Messenger transports as its message channels](https://docs.ecotone.tech/modules/symfony/symfony-messenger-transport?ref=blog.ecotone.tech), so the infrastructure you already run keeps serving.
---
## Ecotone is an architecture layer
Everything so far was the messaging layer: channels, bindings, flows wired once. That layer is why any kind of flow your system may need can be formed. But Ecotone builds one level higher still: on top of the messaging layer it provides a whole architecture layer, not a messaging platform only.
The architecture layer is a set of building blocks that wire directly into your flows. Command Handlers and Event Handlers are the standard ones. Beyond them: Aggregates, which receive Commands directly and send Events out. Sagas, long-running processes that subscribe to Events and drive a flow over time. Projections, which read from Event Sourcing streams to build read models. And Orchestrators, which decide a flow dynamically from a set of conditions.
An Aggregate shows the model best: the Command lands on the Aggregate directly, no service plumbing in between, and the Events it records flow out over channels of their own.
```php
#[Aggregate]
final class Order
{
use WithEvents;
#[Identifier]
private string $orderId;
private function __construct(string $orderId)
{
$this->orderId = $orderId;
$this->recordThat(new OrderWasPlaced($orderId));
}
#[CommandHandler]
public static function place(PlaceOrder $command): self
{
return new self($command->orderId);
}
}
```
*Command straight to the Aggregate; events out over their own channels.*
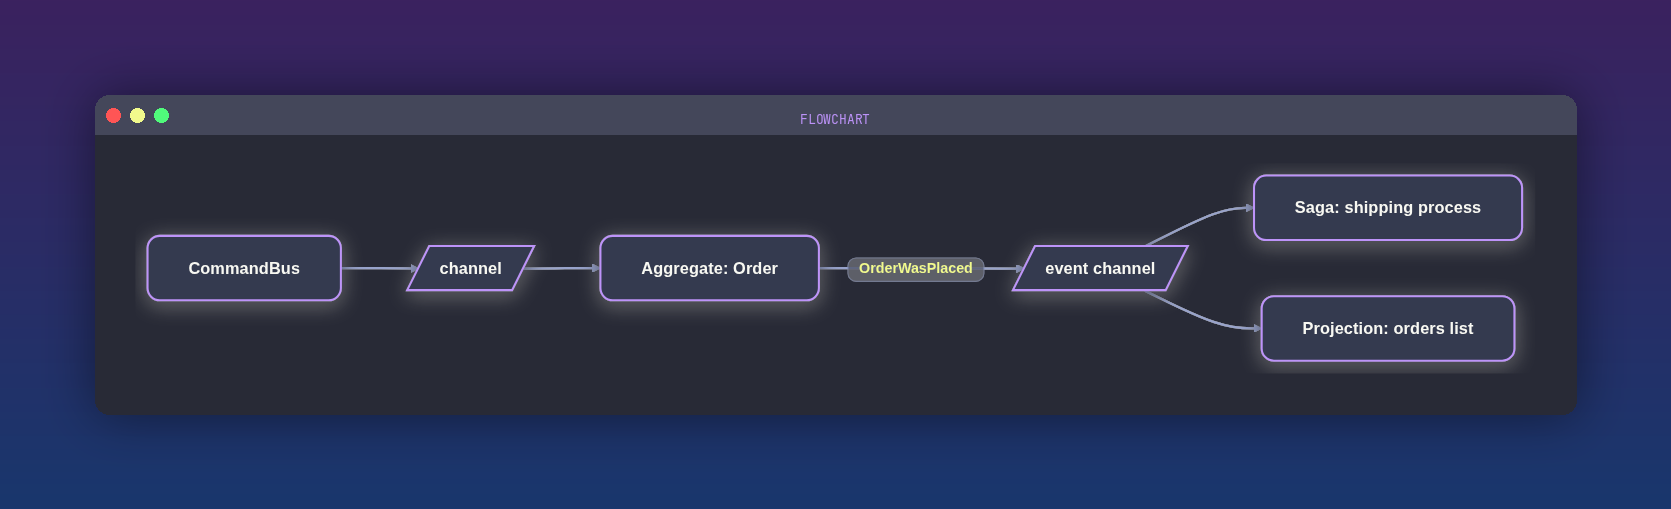
An Orchestrator — part of Ecotone Enterprise — makes the flow itself a runtime decision. It returns the list of channels the message should travel through, and the messaging layer executes them step by step:
```php
final class OrderProcessing
{
#[Orchestrator(inputChannelName: 'order.process')]
public function decide(PlaceOrder $order): array
{
return $order->isDigital
? ['order.verify', 'order.deliverDigital']
: ['order.verify', 'order.reserveStock', 'order.ship'];
}
}
```
*Return the steps, the layer walks them.*
**You do not think about building and wiring these blocks anymore; the messaging layer underneath covers that for you.** And because they are built on that layer, every block inherits its abilities: retries on failure, a dead letter when an unrecoverable failure happens, going asynchronous by adding an attribute:
```php
#[Aggregate]
final class Order
{
// ...
#[Asynchronous('orders')]
#[CommandHandler(endpointId: 'order.cancel')]
public function cancel(CancelOrder $command): void
{
// retried on failure, dead-lettered when unrecoverable
}
}
```
And there are of different patterns which we can combine together, as if messaging layer provides given feature, you can use it with any building block you want:
```php
#[Aggregate]
final class Order
{
// ...
#[Delayed(new TimeSpan(hours: 24))]
#[Asynchronous('orders')]
#[EventHandler(endpointId: 'order.expire')]
public function expire(OrderWasPlaced $event): void
{
// cancel out the Order if not completed within 1 day. This will be executed automatically due to Delayed attribute after 24 hours.
}
}
```
That is what the architecture layer means: the blocks are yours to pick, and the wiring, with everything the wiring grants, is already there.
---
## Wrapping up
At first glance Ecotone can look similar to a transport layer. It is the kind of difference that reveals itself in layers: the longer you work with it, the more you find already wired — until you realize the architecture layer has been carrying work you used to own.
That is the honest answer to "so it's like Symfony Messenger?". Things that looked like a challenge, or were simply too complex to justify building — dynamic routing, the outbox, isolated subscriber flows — become simple and straightforward once handlers bind to channels instead of messages. They were always possible on a transport layer; they just cost application logic at every step. You can build flows on any abstraction. The right one is the one where the flow's hard parts stop being your code.
And if Ecotone's messaging layer makes you curious, you do not have to commit to anything: [you can run Ecotone over your existing Symfony Messenger transports](https://docs.ecotone.tech/modules/symfony/symfony-messenger-transport?ref=blog.ecotone.tech) and adopt it one flow at a time.
---
*About the author: Dariusz Gafka is a Software Architect and author of the* [*Ecotone Framework*](https://github.com/ecotoneframework/ecotone?ref=blog.ecotone.tech)*. He writes about event sourcing, CQRS, and PHP architecture patterns.*
### How Ecotone Hits 157,266 Confirmed Messages per second in PHP
URL: https://blog.ecotone.tech/how-ecotone-hits-over-150k-confirmed-messages-in-one-second-in-php/
Last updated: 2026-08-12T04:25:56.000Z
*Updated on 2026-08-07*
PHP has a reputation on the publishing side: a handful of messages is fine, but once a system needs to push thousands, the usual instinct is to reach for another language. So today I want to show you how Ecotone changes that math: the same `#[CommandHandler]` that published events one call at a time now moves 10,000 broker-confirmed messages in 64 milliseconds (157,266 msg/s to Kafka from a single PHP process). The speed comes from the broker's own high-throughput features, enabled in configuration, while your handler stays simple and out of those concerns.
> **TL;DR:** Ecotone's high-throughput publishing is enabled with one builder call per channel — `withHighThroughputPublishing()`. Handlers keep publishing events exactly as before; Ecotone gathers them, sends one provider-native batch, and collects every broker confirmation before the transaction commits. Measured: Kafka 157,266 msg/s, RabbitMQ 67,143, from one PHP process.
📌
High-throughput publishing is a paid Ecotone Enterprise capability. Trial licences are available at [ecotone.tech/pricing#trial](https://ecotone.tech/pricing?ref=blog.ecotone.tech#trial); the benchmark demo is [public and runnable](https://github.com/SimplyCodedSoftware/ecotone-publishing-throughput-demo?ref=blog.ecotone.tech).
## Table of contents
- [Publishing message by message](#publishing-message-by-message)
- [What brokers offer instead: two mechanisms](#what-brokers-offer-instead-two-mechanisms)
- [Batching: gather and send together](#batching-gather-and-send-together)
- [Non-blocking confirmation: stop waiting between messages](#non-blocking-confirmation-stop-waiting-between-messages)
- [Both together: where the headline numbers come from](#both-together-where-the-headline-numbers-come-from)
- [How Ecotone wires it in: the handler stays as it is](#how-ecotone-wires-it-in-the-handler-stays-as-it-is)
- [What Ecotone does between publish and commit](#what-ecotone-does-between-publish-and-commit)
- [Taking explicit control with publishDeferred](#taking-explicit-control-with-publishdeferred)
- [Consumers never see the batch](#consumers-never-see-the-batch)
- [Why people accept lost messages](#why-people-accept-lost-messages)
- [Batching the outbox relay](#batching-the-outbox-relay)
- [Wiring the relay into your stack](#wiring-the-relay-into-your-stack)
- [Trade-offs and limits of high-throughput publishing](#trade-offs-and-limits-of-high-throughput-publishing)
- [Common questions about the Ecotone approach](#common-questions-about-the-ecotone-approach)
## Publishing message by message
The default on every publishing path is one broker call per message. Each `publish()` serializes the message, sends it, and waits for the broker's confirmation before your code continues:
```php
foreach ($orders as $order) {
$eventBus->publish(new OrderWasPlaced($order->id));
}
```
*Each iteration pays a full broker round-trip before the next one starts.*
Notice what this API cannot express: send everything, keep working, and await the confirmations once all other work is completed. Every publish is a full stop. A handler that emits 10,000 events pays that stop 10,000 times, sequentially, inside the request, while the database transaction holds its locks. The broker is rarely the limit — any broker in this article can ingest far more than one PHP process sends. The cost is the sequencing of the round-trips, and that sequencing is why the publishing side is where PHP systems feel slow first.
## What brokers offer instead: two mechanisms
The brokers themselves solved this long ago; the per-message API just cannot reach the solution. Two independent mechanisms exist, and they attack different parts of the cost:
- **Batching** gathers the messages an operation produces and hands the broker one write instead of N. The round-trips collapse from N to one.
- **Non-blocking confirmation** keeps sending without stopping for each acknowledgement, then collects all confirmations in a single pass at the end. The sending never stops; the waiting happens once.
Compared to message-by-message publishing, every message is still confirmed by the broker; what changes is *when* the waiting happens and *how many* round trips there are. A provider only gets the mechanism its protocol actually has:
| Provider | Batching | Non-blocking confirmation |
| Kafka | native batch produce | delivery reports collected at the end |
| RabbitMQ | one publisher-confirms round trip | confirms collected at the end |
| SQS | native batch send requests, sent concurrently | responses collected at the end | | Postgres | one multi-row INSERT | not offered — the INSERT confirms itself |
| Redis | one scripted round trip | not offered — the reply is the confirmation |
Redis and Postgres confirm the write in the reply to the write. There is no separate acknowledgement arriving later, so there is nothing to defer: batching is their whole feature. Kafka, RabbitMQ and SQS have both mechanisms — and because the two are independent, the [public demo](https://github.com/SimplyCodedSoftware/ecotone-publishing-throughput-demo?ref=blog.ecotone.tech) measures each on its own before combining them.
## Batching: gather and send together
Batching means the messages produced during an operation are collected and travel as **one** write at the end. Each provider maps that write onto its own primitive: a native batch produce on Kafka, a batch send request on SQS, a multi-row INSERT on Postgres, one scripted round trip on Redis, a single publisher-confirms round trip on RabbitMQ. The number of broker round-trips drops from N to one.
**The result.** Redis and Postgres are the honest place to read this mechanism on its own, because batching is the only mechanism they have:
| Provider | Per-message publishing | Batched |
| Redis | 32,184 msg/s | **115,638 msg/s** |
| Postgres | 16,421 msg/s | **53,711 msg/s** |
Redis lands second in the whole demo, behind only Kafka, without any deferred-confirmation mode at all. The less forgiving your infrastructure, the more collapsing the round-trips is worth.
## Non-blocking confirmation: stop waiting between messages
The second mechanism leaves every message as its own write — no batch anywhere — but the process no longer stops for each confirmation before writing the next. Deliveries are registered as pending and awaited in a single pass at the end of the scope. What is deferred is the *waiting*, not the sending. It also composes with batching: several batches can be on the wire back to back, with one wait at the end covering all of them.
What that means underneath differs per broker:
- **Kafka** produces each message without flushing, and drains delivery reports while it keeps producing. The flush and the wait happen once, at the end.
- **RabbitMQ** writes each message to the socket as before, but the publisher confirms are coalesced — one wait for all of them instead of a stop after every publish.
- **SQS** dispatches its requests concurrently (with a cap on how many are in flight at once) and collects the responses together, instead of one HTTP round-trip at a time.
**The result.** This is the mechanism with the widest spread, and it is a good illustration of why the transport matters:
| Provider | Per-message publishing | Non-blocking confirm |
| Kafka | 9,053 msg/s | **23,421 msg/s** — 2.6x |
| RabbitMQ (amqp-ext) | 13,754 msg/s | **20,261 msg/s** — 1.5x |
| RabbitMQ (amqp-lib) | 9,776 msg/s | **15,252 msg/s** — 1.6x |
| SQS (LocalStack) | 660 msg/s | **1,143 msg/s** — 1.7x |
Read down that column and you can see where each transport spends its time. Kafka gains the most at 2.6x, because producing without flushing lets it keep working while delivery reports drain. The AMQP transports and SQS gain 1.5x to 1.7x: each message is still its own write, so only the confirmation wait is coalesced, never the write itself. That is exactly why this is a separate mechanism from batching.
## Both together: where the headline numbers come from
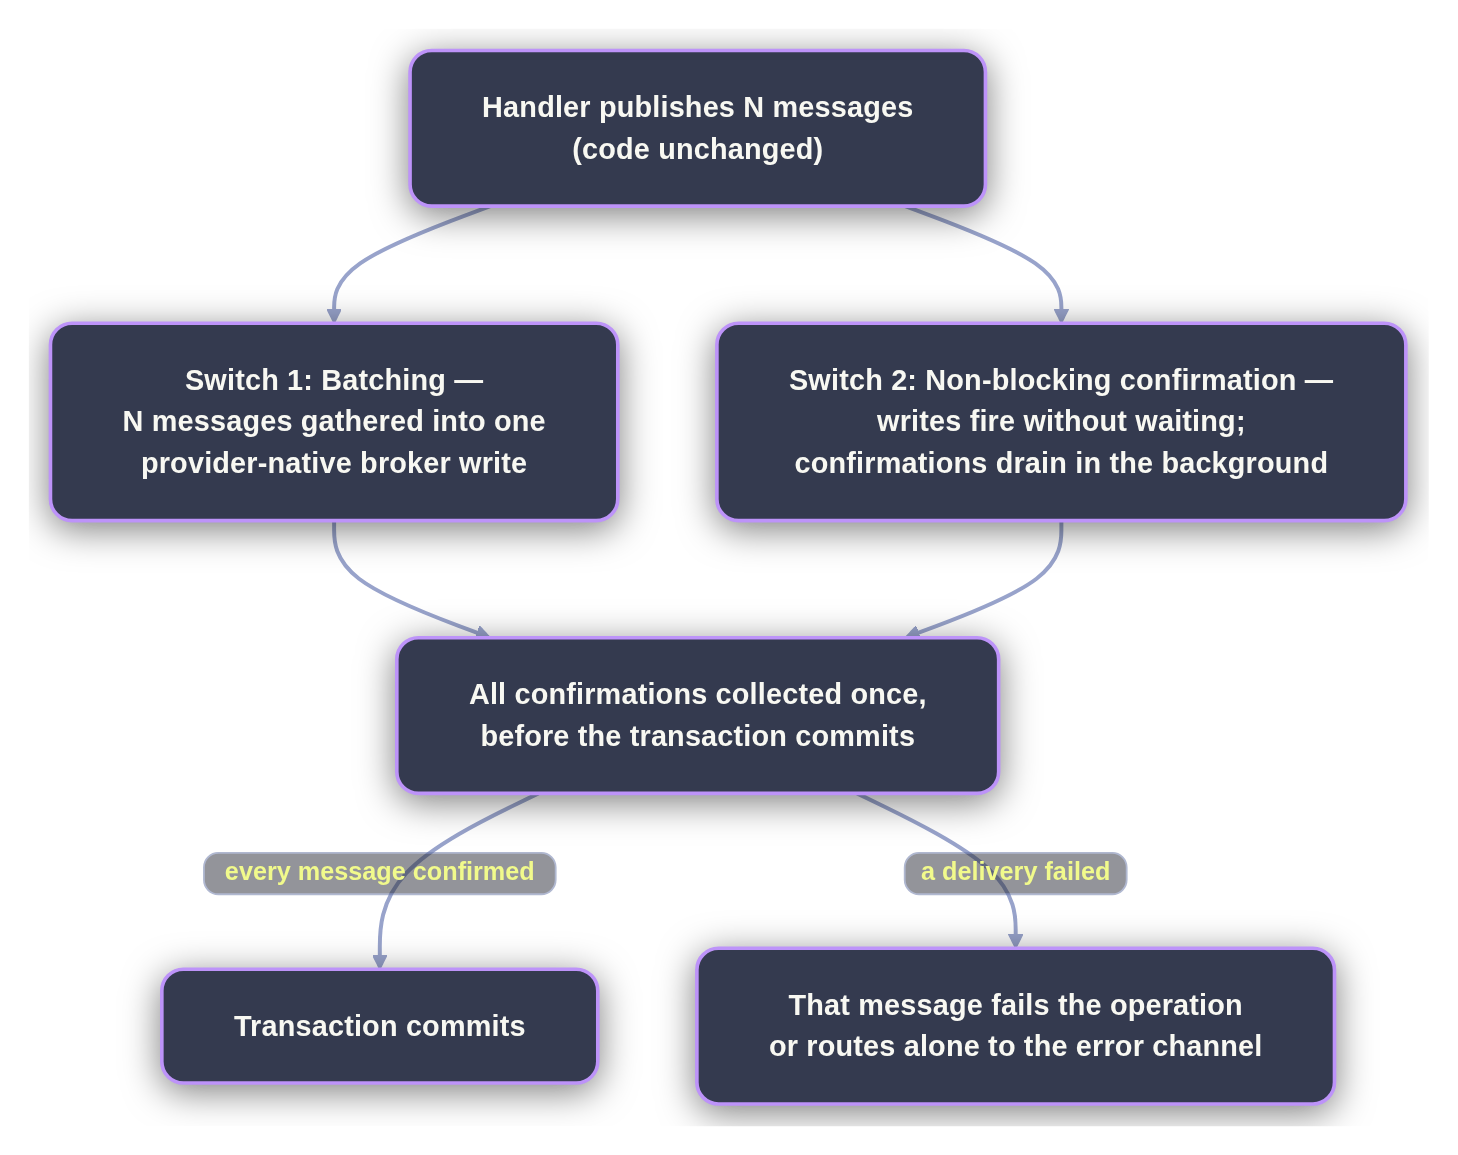
The mechanisms compose cleanly: the batch removes the round-trips, the deferred confirmation removes the waiting between what is left, and every confirmation is still collected before the operation completes. No guarantee is traded away for the combination — a failed delivery still fails the operation, or routes only failed messages to the error channel.
**The result**, one PHP process, 10,000 messages per run, every delivery confirmed before the clock stops:
| Provider | Batched + non-blocking |
| Kafka | **157,266 msg/s** — 10,000 confirmed in 64ms |
| RabbitMQ (amqp-ext) | **67,143 msg/s** — 10,000 confirmed in 149ms |
| RabbitMQ (amqp-lib) | **36,294 msg/s** |
| SQS (LocalStack) | **7,549 msg/s** |
Redis and Postgres have no row here, and that is not an omission: with no confirmation to defer, their batched numbers above already are their best case.
The numbers leave one question open: what these mechanisms cost inside your codebase — batch objects to build, futures to thread through the domain layer, a flush to remember. That price is what usually keeps them out of business code.
## How Ecotone wires it in: the handler stays as it is
Here is the handler after high-throughput publishing is enabled:
```php
#[CommandHandler]
public function place(PlaceOrder $command, EventBus $eventBus): void
{
$eventBus->publish(new OrderWasPlaced($command->orderId));
}
```
*There is no diff against the message-by-message version. That is the point.*
No batch objects in the business code, no futures to thread through your domain layer, no "collect these and flush later" service. The loop from the first section keeps looping exactly as written; Ecotone gathers everything published during the operation and applies batching and non-blocking confirmation underneath.
Enabling it is one builder call on the channel or publisher configuration:
```php
final class MessagingConfiguration
{
// Message Channels — events published from handlers are gathered,
// sent as one native batch, and confirmed before the operation completes
#[ServiceContext]
public function ordersChannel(): KafkaMessageChannelBuilder
{
return KafkaMessageChannelBuilder::create('orders')
->withHighThroughputPublishing();
}
// Message Publisher — enables publishDeferred() with a Future
#[ServiceContext]
public function orderPublisher(): AmqpMessagePublisherConfiguration
{
return AmqpMessagePublisherConfiguration::create()
->withHighThroughputPublishing();
}
}
```
*Configuration is the only place batching exists. Business code stays broker-agnostic and batch-agnostic.*
The same call is available across the supported channels — Kafka, RabbitMQ, SQS, Redis, and the Postgres-backed channel:
```php
KafkaMessageChannelBuilder::create('orders')->withHighThroughputPublishing();
AmqpBackedMessageChannelBuilder::create('orders')->withHighThroughputPublishing();
SqsBackedMessageChannelBuilder::create('orders')->withHighThroughputPublishing();
RedisBackedMessageChannelBuilder::create('orders')->withHighThroughputPublishing();
DbalBackedMessageChannelBuilder::create('orders')->withHighThroughputPublishing();
```
*Per-channel opt-in. Channels without the call keep the standard synchronous path.*
The opt-in being per-channel rather than global is what lets throughput stay a targeted decision: the order events that fan out by the thousand get the batched path, while a low-volume channel keeps the simplest possible flow. And the decision lives next to the channel definition, where an architecture reviewer will actually look for it.
The two mechanisms stay independently switchable, and the signature tells you what the provider can do:
```php
KafkaMessageChannelBuilder::create('orders')
->withHighThroughputPublishing(
batchPublishing: true,
nonBlockingConfirmation: true,
confirmationTimeoutInMilliseconds: 5000,
);
```
*Redis and Postgres take no arguments — there is nothing to choose.*
## What Ecotone does between publish and commit
Since the handler code carries no hints, the interesting question is what happens underneath. The flow:
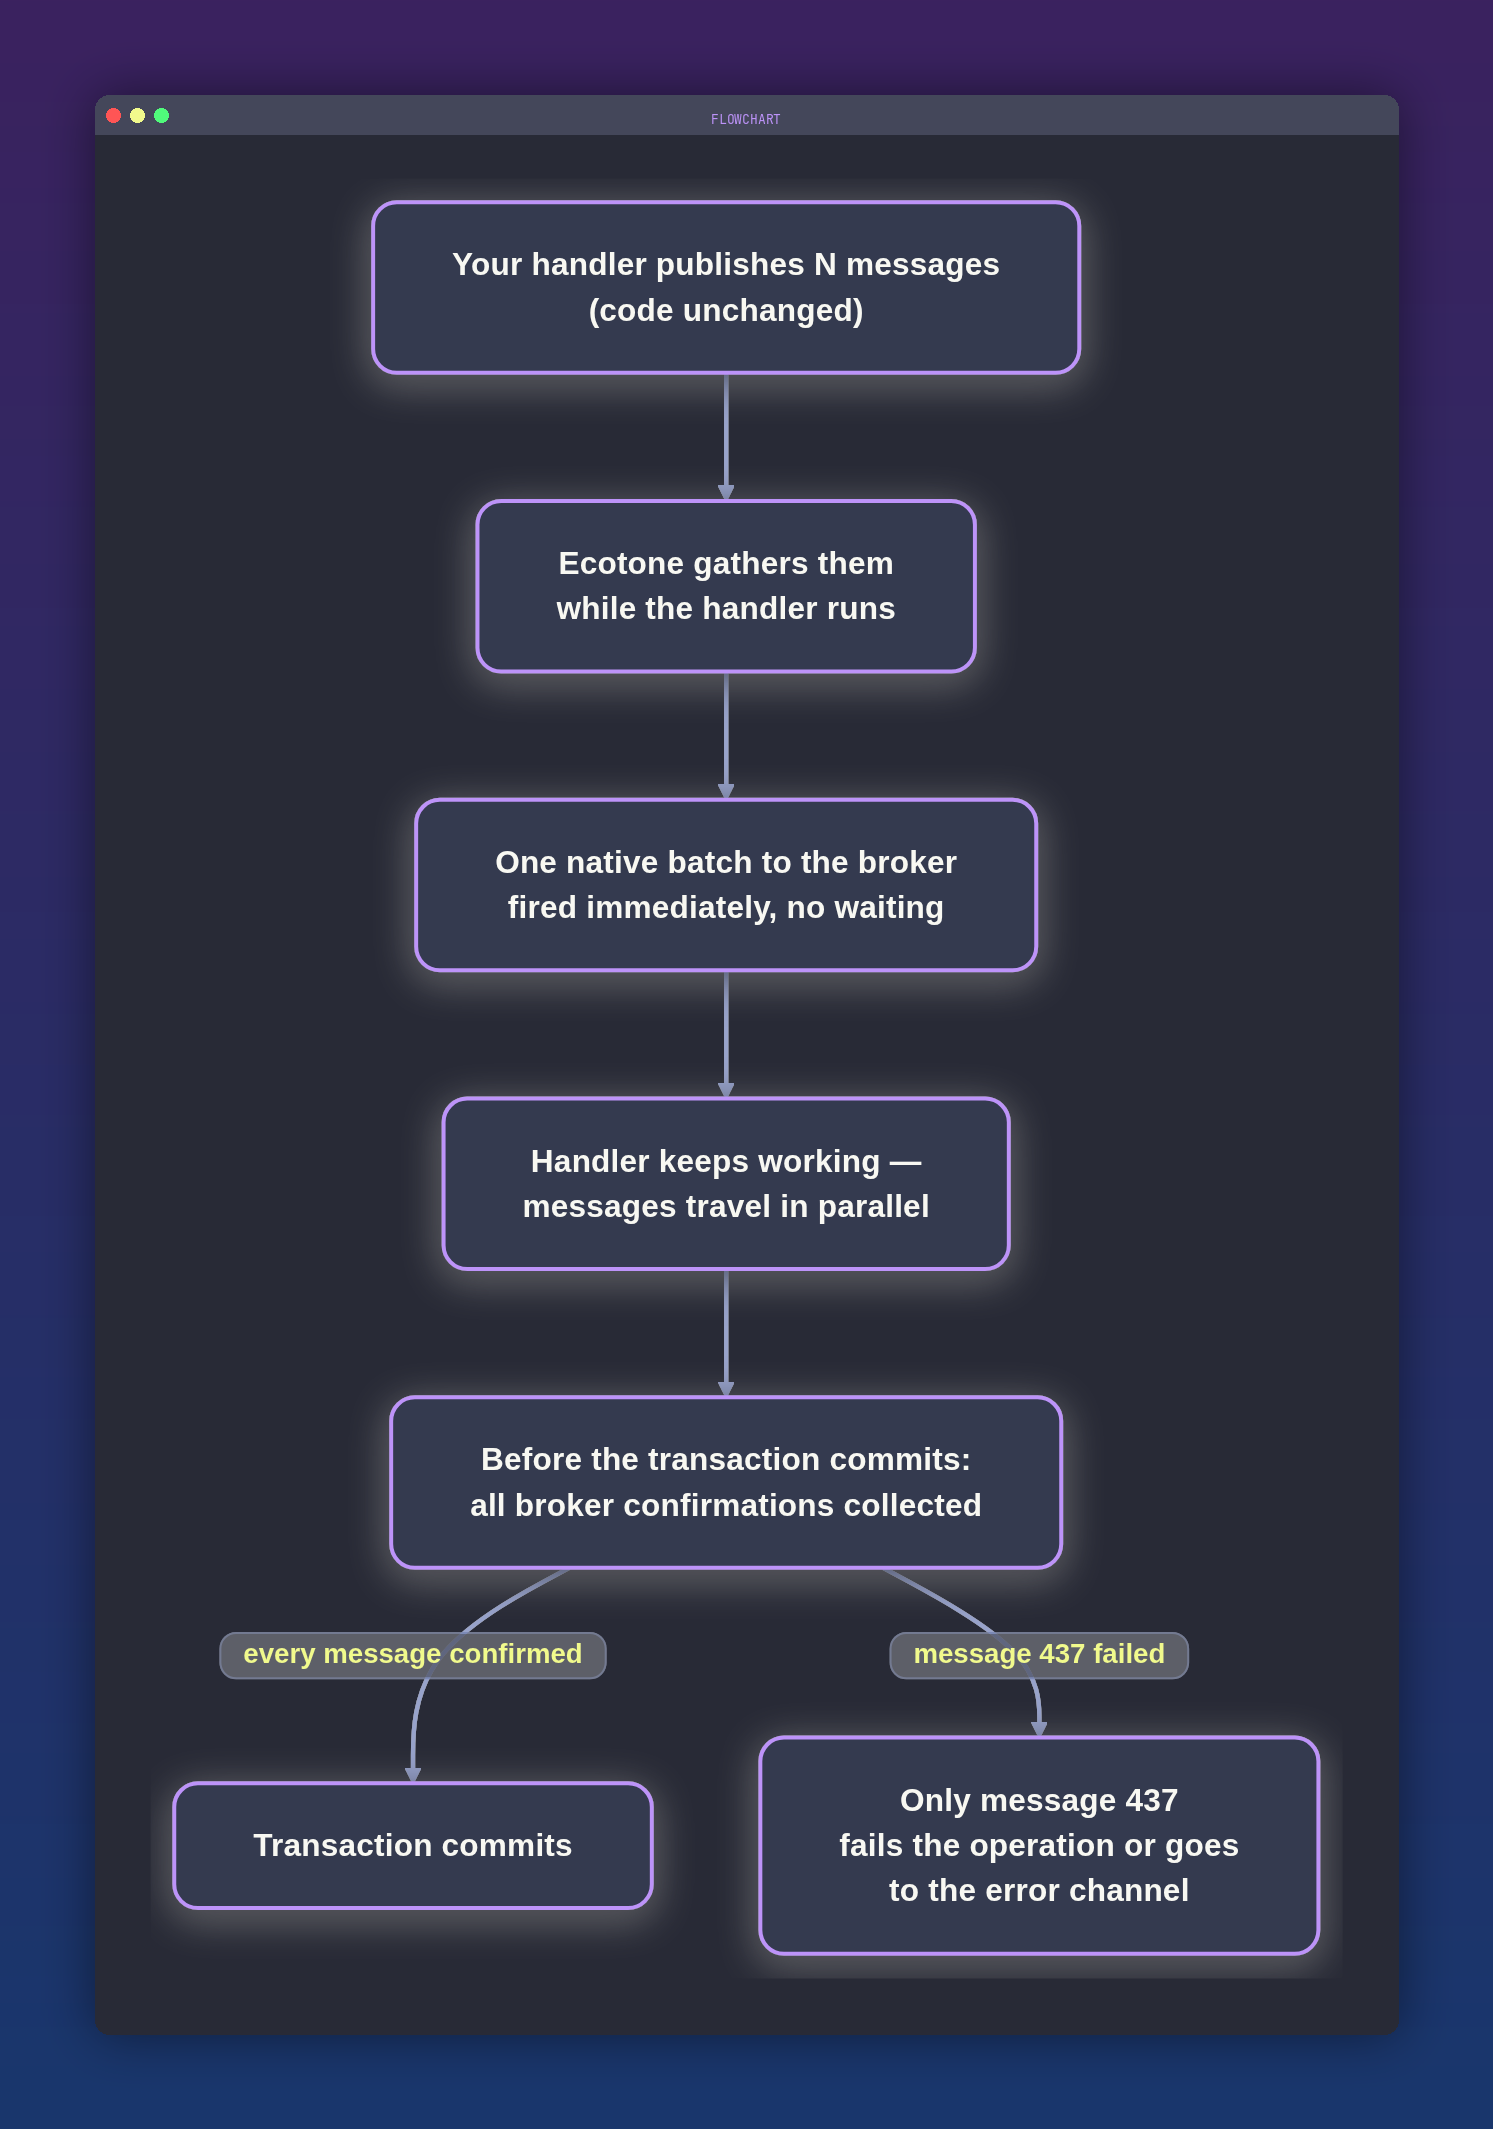
The one-sentence version: **the waiting happens once, right before the commit.** Messages fire to the broker the instant the handler emits them and travel while it keeps working, and Ecotone collects all broker confirmations in a single pass at the transaction boundary.
Logging a handler run shows the order plainly:
```
transaction started
command handler executed
published batch of 2 messages to broker
delivery confirmations awaited
transaction committed
```
*The confirmation wait happens once, after the handler and before the commit.*
Two properties fall out of this design that matter more than the speed:
**No message leaves unconfirmed.** The transaction cannot commit until every message is confirmed by the broker. You never end up with committed state whose events silently failed to reach the outside world.
**Failure stays per-message.** If message 437 of 10,000 is rejected, either the operation fails (no error channel configured, transaction rolls back) or exactly that message routes to the error channel and into retries or the dead letter store — individually. The other 9,999 are unaffected. Hand-rolled batching schemes almost always collapse this into batch-level success or failure, which means duplicates on re-publish or silent loss.
Ecotone also finds the outermost transaction boundary on its own. Nested handlers and buses publishing within the same operation do not each await; one collection pass covers everything published inside.
There is one honest challenge to this design: messages reach the broker *before* the commit, so a transaction that fails at its very last step has already published events about a change that never happened. Collecting confirmations cannot close that window — only writing the message and the state change in the same transaction can, and that is where the outbox comes in a bit later in the article.
## Taking explicit control with publishDeferred
The configuration-only path covers handlers. When you want to drive batching yourself (imports, migrations, the benchmark itself), the publisher exposes the explicit form:
```php
$future = $messagePublisher->publishDeferred(
BatchMessage::fromEntries([
['payload' => $firstOrder],
['payload' => $secondOrder, 'headers' => ['priority' => 5]],
])
);
// ... do other work — messages are already travelling ...
$future->resolve(); // throws PublishingFailedException listing only the messages that failed
```
*You choose the batch contents and the moment to await. Per-message metadata still works inside a batch.*
`publishDeferred` returns a Future. The messages are on the wire immediately; `resolve()` is where you pay the wait, and on failure the exception names exactly which messages failed rather than waving at the batch. This is the API the public benchmark uses to hit 157,266 confirmed msg/s on Kafka and 67,143 on RabbitMQ from a single process. Redis and Postgres do not offer `publishDeferred()`: with no separate confirmation to defer, there is no Future to resolve — their batched path is the configuration one.
## Consumers never see the batch
One API, but no lowest-common-denominator transport: each provider gets its own fast path, and none of it leaks past the wire. Nothing about batching survives the wire: the consumer side receives individual messages, retries individual messages, and dead-letters individual messages. No consumer, projection, or subscriber changes when a publisher turns this on.
## Why people accept lost messages
Everything so far kept one guarantee fixed: the operation does not complete until the broker confirmed every message. Plenty of systems give that guarantee up, and speed is usually the justification. One version publishes to the broker only after the response is already sent — the request feels fast, and a process that dies between the response and the publish loses those messages with no error and no log entry. Another publishes directly to the broker mid-transaction and hopes the commit follows: when it rolls back instead, the system has announced an order that never existed. Both are the same trade — robustness sold for throughput, silently, at the worst possible place.
The pattern that refuses that trade is the **outbox**: write the messages into the same database transaction as the business change, and let a separate process relay them to the broker. The message and the state change commit or roll back together, so nothing can be lost, nothing false can be announced — and the window from earlier, a commit failing after the messages already reached the broker, is gone: the messages only leave once the commit succeeded. The reason people still avoid it is what happens after the commit: the relay usually consumes the outbox like any other channel, one message per poll cycle, deserializing and republishing each one on its own. The robust option earned a reputation for being slow, and that reputation is what pushes teams into the shortcuts above.
## Batching the outbox relay
The relay's problem is the first section's problem one level down, so the same two mechanisms apply. Instead of polling per message, a dedicated publishing endpoint claims a block of rows straight from the database — `FOR UPDATE SKIP LOCKED` on PostgreSQL — groups them by target and hands the target whole batches. The rows travel in wire format, so nothing is deserialized on the way through, and with high-throughput publishing on the target channel, a claimed block becomes one native broker batch.
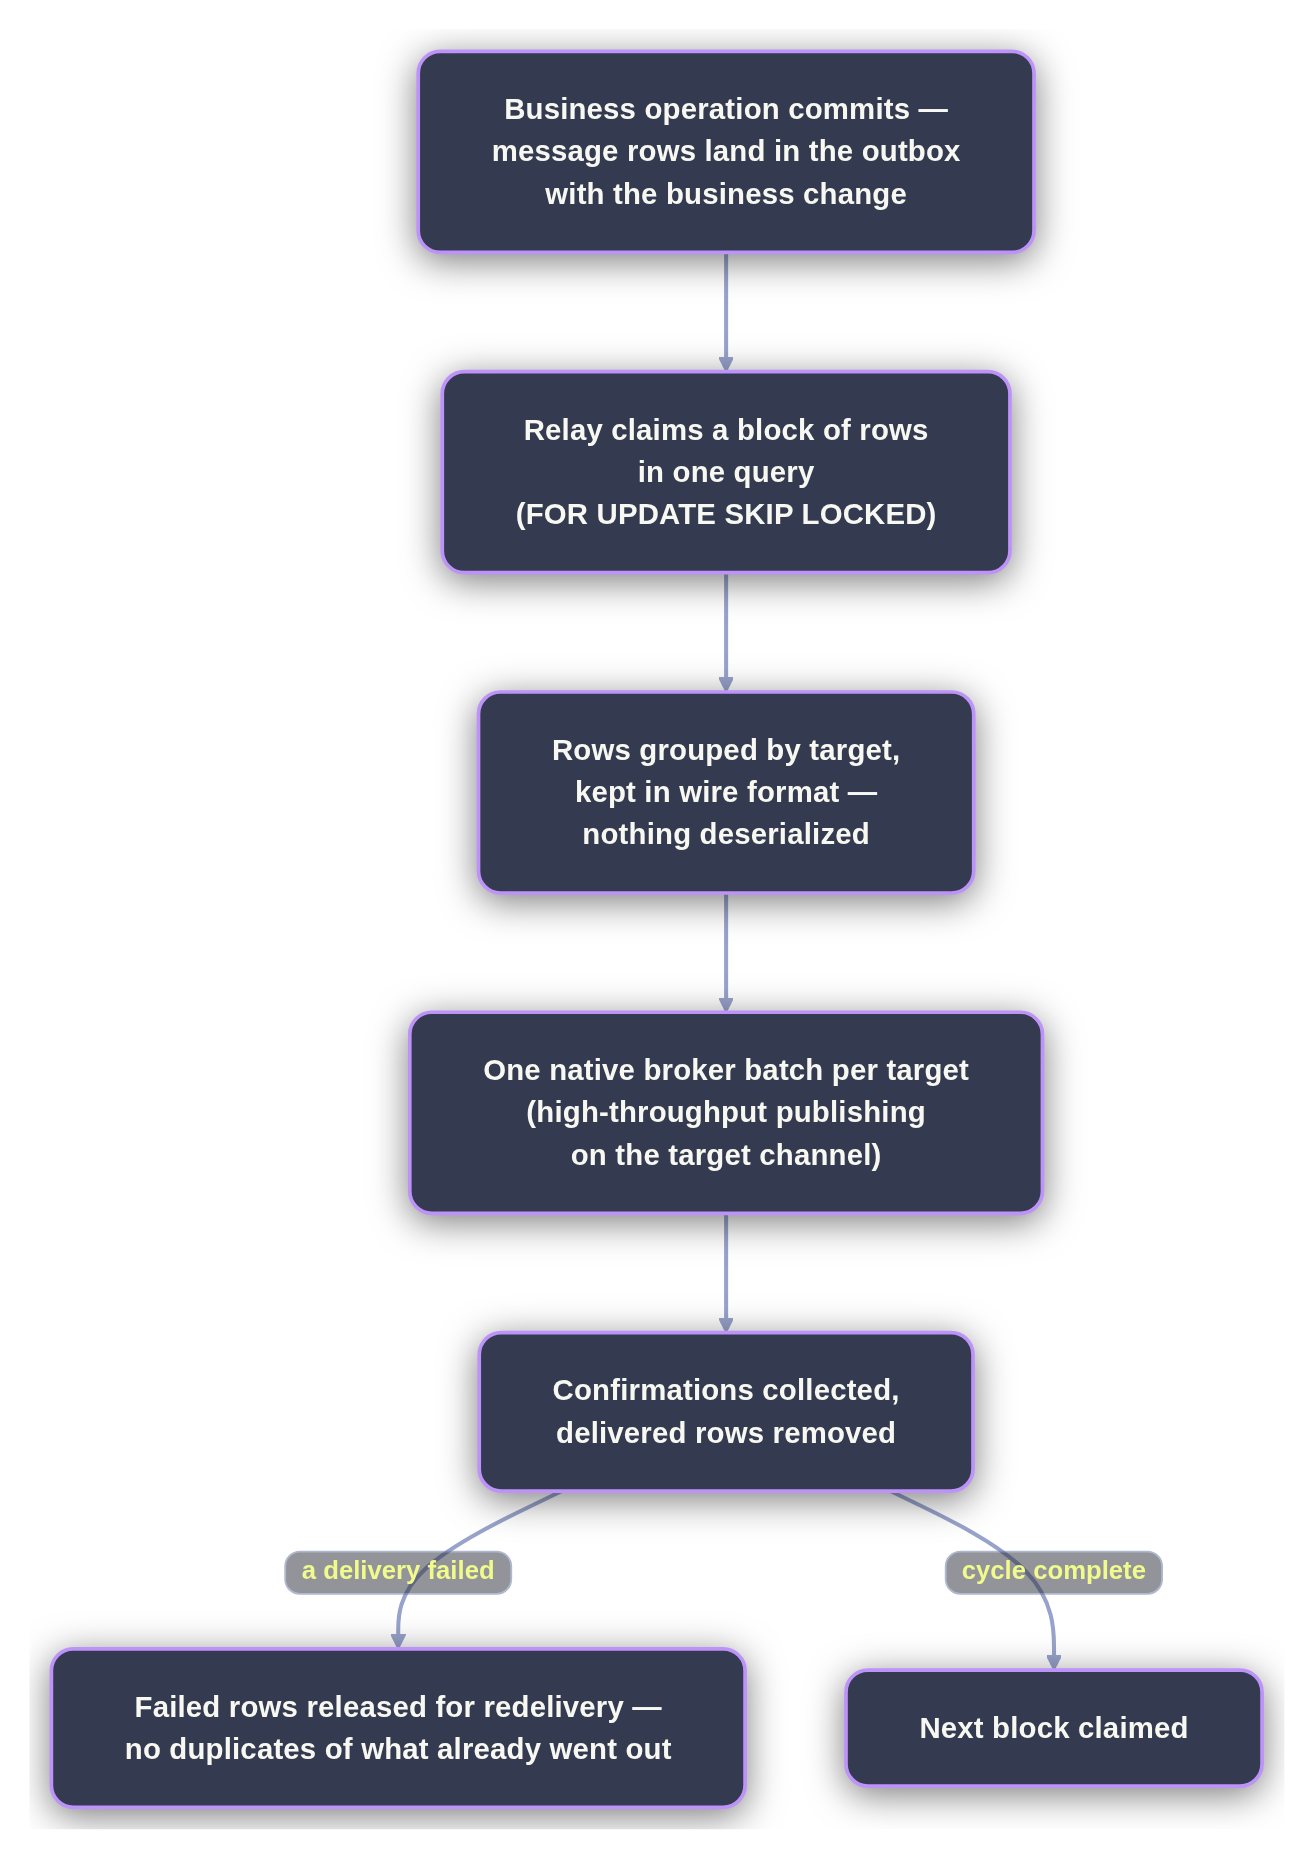
Delivery stays at-least-once, and the outbox is its own retry store: a failed delivery is released for redelivery rather than duplicating what already went out, and a connection failure rolls the whole cycle back so a restarted process retries cleanly.
**The result**, 10,000 messages sitting in the outbox waiting to be relayed:
| Relay (Kafka target) | Time to drain 10,000 |
| Message by message | **34.49s** — 290 msg/s |
| Batched, 100 rows per cycle | **0.318s** — 31,461 msg/s |
| Batched, one claim of 10,000 | **0.200s** — 50,052 msg/s |
Two things worth taking from that. The relay is what costs you, not the broker: roughly 3ms per message goes on poll cycles, per-message transactions and the per-message publish, and every target in the demo (RabbitMQ, Kafka, Redis) receives the same 10,000 rows in under a third of a second once the relay claims them in one go. Batch size is the smaller knob: a hundred cycles of a hundred rows cost 1.3x to 1.6x what a single claim does, depending on the target, the trade being that one claim holds the whole batch in memory inside one transaction.
SQS is the exception, at 1.472s for the single-batch relay: its API caps a batch request at 10 entries, so 10,000 messages are still 1,000 HTTP round trips no matter how many rows you claim at once.
## Wiring the relay into your stack
On the Ecotone side the relay is a channel definition rather than a new moving part:
```php
#[ServiceContext]
public function channels(): array
{
return [
OutboxForwardingMessageChannel::create(
referenceName: 'orders',
sourceChannelName: 'outbox',
targetChannelName: 'orderProcessing',
)->withMaxForwardingBatchSize(100),
KafkaMessageChannelBuilder::create('orderProcessing')
->withHighThroughputPublishing(),
];
}
```
*One outbox, one target. The publishing endpoint replaces the outbox channel's consumer.*
Business code does not participate: handlers keep publishing to the `orders` channel exactly as before, the rows land in the outbox inside the business transaction, and the forwarding channel drains them in blocks. Moving a direct-to-broker setup onto this path is configuration work — the code that publishes never learns the outbox exists.
## Trade-offs and limits of high-throughput publishing
Where I would not reach for this, and what it does not solve:
- **It is an Enterprise capability.** The standard synchronous path is free and remains the default on RabbitMQ, Redis, Postgres and SQS; the Kafka module itself is part of Ecotone Enterprise. High-throughput publishing belongs to the paid tier everywhere, with trial licences available.
- **Low-volume channels gain little.** A handler publishing one event per request saves one round-trip's ordering at most. The feature earns its keep where handlers fan out many messages or where publishing sits inside hot request paths.
- **The commit waits for confirmations.** That is the guarantee doing its job, but it means a slow broker still surfaces as latency at the transaction boundary rather than disappearing. You are moving the wait, not deleting it.
- **The transport still matters.** On RabbitMQ the `enqueue/amqp-ext` connection reached 67,143 msg/s against `enqueue/amqp-lib`'s 36,294, because php-amqplib encodes the protocol in pure PHP. One builder call enables the feature; it cannot make up a 1.8× difference in the transport underneath it.
## Common questions about the Ecotone approach
What happens if the process dies with unresolved futures?Confirmations are still collected on shutdown, and unresolved deliveries are logged. Nothing is silently dropped on the way down.What if I publish outside any transaction or handler scope?The publish simply awaits synchronously, as it always did. The batched path does not depend on the happy path holding; it degrades to standard behavior.Do I need to change consumers, retries, or dead letter handling?No. The batch exists only on the wire. Consumers receive individual messages, and all failure tooling keeps operating per message.
## Wrapping up
The fastest way to judge this is to run it: the [demo is public](https://github.com/SimplyCodedSoftware/ecotone-publishing-throughput-demo?ref=blog.ecotone.tech), runs on Docker Compose against five brokers in six configurations, and every number in this article comes from it. High-throughput publishing is a paid Ecotone Enterprise capability, and trial licences are available at [ecotone.tech/pricing#trial](https://ecotone.tech/pricing?ref=blog.ecotone.tech#trial) — so the next step I would suggest is enabling it inside your own stack and measuring against your own brokers. The handlers you already have qualify unchanged; the wiring is the builder call from this article.
[Read the Ecotone documentation](https://docs.ecotone.tech/?ref=blog.ecotone.tech)
---
*About the author: Dariusz Gafka is a Software Architect and author of the* [*Ecotone Framework*](https://github.com/ecotoneframework/ecotone?ref=blog.ecotone.tech)*. He writes about event sourcing, CQRS, and PHP architecture patterns.*
### Tempest + Ecotone: One Declarative Foundation
URL: https://blog.ecotone.tech/tempest-ecotone-one-declarative-foundation/
Last updated: 2026-07-27T07:00:28.000Z
*Updated on 2026-07-22*
Tempest describes itself as a framework designed to **get out of your way** — you write application code, and discovery finds it. Ecotone sits one layer higher and makes the matching promise: full business focus — **you write business logic, and the architecture wiring is handled**. Those are two phrasings of one foundation idea, declarative configuration: you declare intent in code, and the framework derives everything else.
This article is about what happens when the two meet.
`composer require ecotone/tempest` does not add a dependency so much as **install an architecture layer into the foundation**. I did build a [demo e-commerce application](https://github.com/ecotoneframework/tempest-ecotone-demo?ref=blog.ecotone.tech) to show how this work in practice, and described the features and practices used in this article.
> **TL;DR:** Tempest and Ecotone are built on the same foundation — declarative configuration. Tempest applies it to the application layer and gets out of your way; Ecotone applies it to the architecture layer and enables full business focus. `composer require ecotone/tempest` installs that layer into Tempest: CQRS, async processing with retries and a dead letter, event sourcing, projections, workflows, per-message delayed delivery, and an outbox with deduplication for free — and a runnable e-commerce demo shows what that looks like in practice.
## Table of contents
- [One foundation: declarative configuration](#one-foundation-declarative-configuration)
- [Installing the architecture layer](#installing-the-architecture-layer)
- [The shop, concept by concept](#the-shop-concept-by-concept)
- [The count](#the-count)
- [Transferable lessons](#transferable-lessons)
## One foundation: declarative configuration
Ecotone now has a first-class integration for [Tempest](https://tempestphp.com/?ref=blog.ecotone.tech) — a new package, `ecotone/tempest` ([documentation](https://docs.ecotone.tech/modules/tempest?ref=blog.ecotone.tech)). What makes this integration different from a typical framework adapter is that both sides already work the same way. In Tempest you write a controller, a model, a console command — discovery finds it, no registration. In Ecotone you write a class with `#[CommandHandler]` on a method — the framework finds it, builds the bus, routes the message, manages the transaction. Neither side asks you to describe your application to it; both derive the wiring from what you declared in code.
That shared foundation is why the composition looks like layers rather than glue:
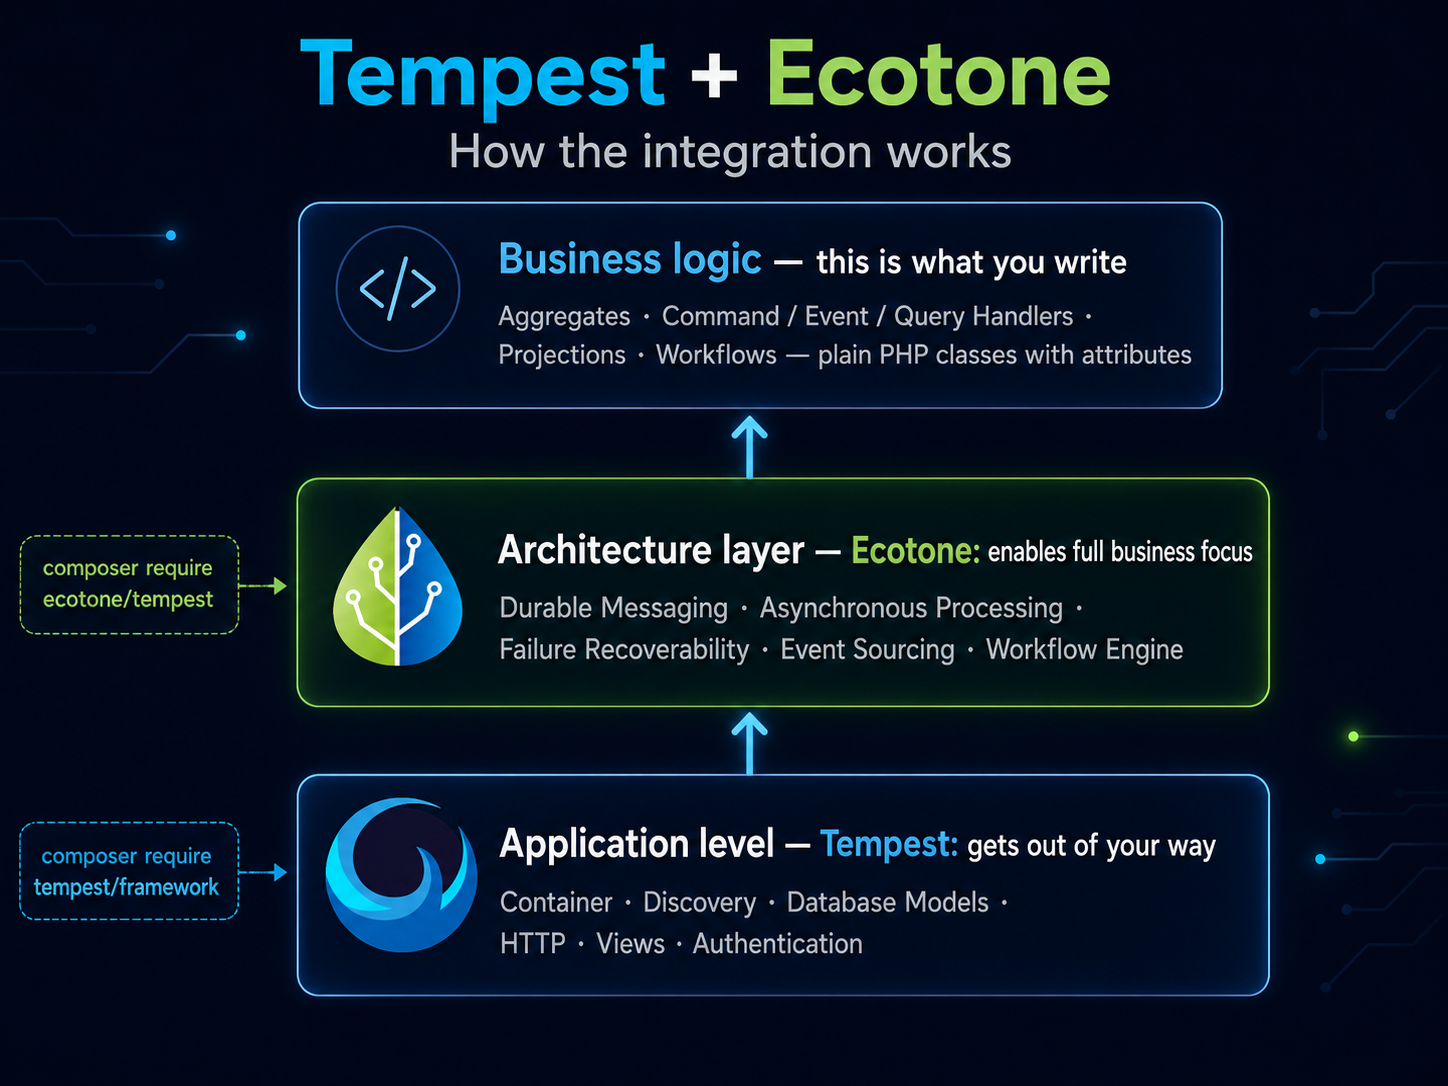
**A pedestal, built bottom-up: Tempest is the foundation layer, one composer require installs the Ecotone architecture layer on top of it, and everything above the two is yours — business logic, and only business logic.*
The result is checkable as a size claim: an application with enterprise-level messaging architecture where the application code holds business logic and almost nothing else. There is no configuration layer to minimize; it simply isn't there.
The entire setup:
```bash
composer require ecotone/tempest
```
*One command. No service provider, no bundle registration, no YAML.*
A config file exists, but it is optional — the composer require alone gives you a fully working integration. Claims like that are cheap on a slide, which is why everything below comes from a browsable shop rather than snippets: product grid, cart, checkout, orders dashboard, shipment tracking, real emails landing in a local inbox. The whole application is public — [ecotoneframework/tempest-ecotone-demo](https://github.com/ecotoneframework/tempest-ecotone-demo?ref=blog.ecotone.tech) — so you can clone it, run `docker compose up`, play with it, and count the classes yourself.
ℹ️
Prerequisites — PHP 8.5, Tempest, `ecotone/tempest`. The demo additionally uses `ecotone/dbal`, `ecotone/pdo-event-sourcing` and `ecotone/jms-converter` on Postgres.
## Installing the architecture layer
The diagram's middle layer is what the composer require actually delivers. Ecotone brings its whole platform — durable channels, retries with backoff, dead-lettering, per-message delayed delivery, a query bus, event sourcing — and every piece of it is declared the same way the foundation is: attributes on plain classes, discovered, never registered.
```php
final class PlaceOrderHandler
{
#[CommandHandler('order.place')]
public function place(string $orderId): void
{
// store the order in the database
}
}
```
*A handler is a plain class with one attribute — discovered, routed and wrapped in a transaction without any registration.*
Here is the full path a request takes, from the browser down to the stored order — and who owns each step:
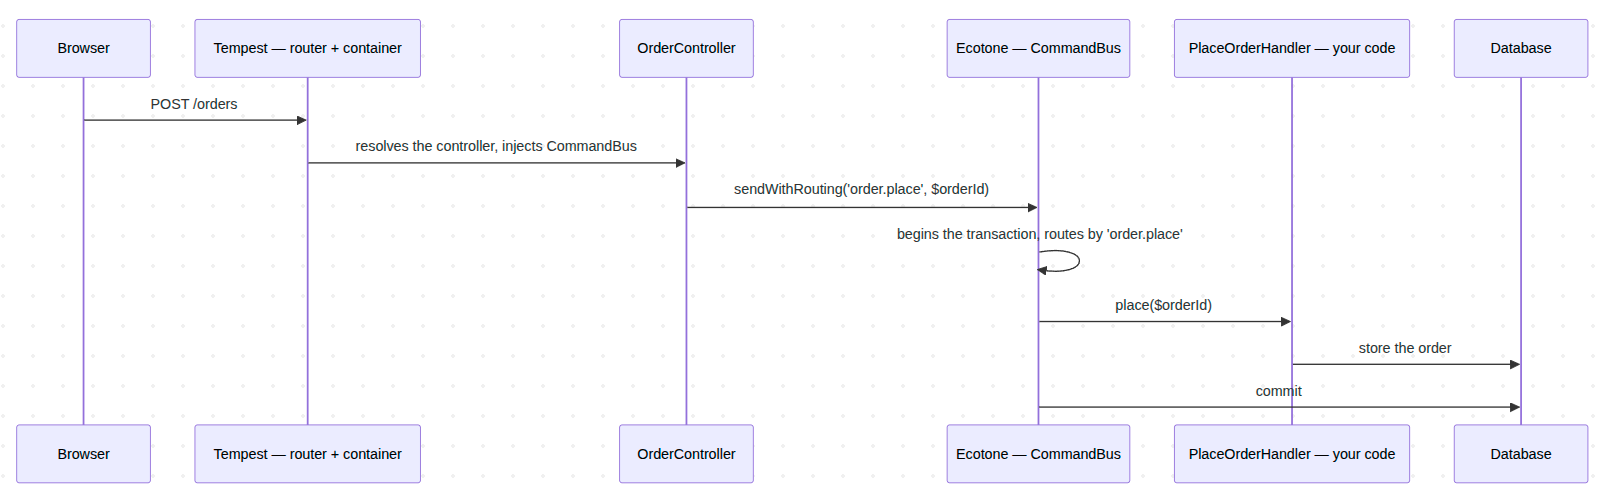
*Tempest carries the request to your controller; Ecotone carries the command to your handler, inside a transaction; the only code you wrote is the controller call and the handler body.*
Where does discovery get its scan paths? From what you already wrote. When no namespaces are configured, Ecotone derives them from Tempest's `Composer` object — the PSR-4 roots of your composer.json. The database connection comes from Tempest's own `DatabaseConfig` through `TempestConnectionReference::defaultConnection()`, so Ecotone's transactions wrap Tempest ORM writes on one shared PDO connection. You declared both things once; the integration reads them instead of asking again.
The buses arrive the same way. Every Ecotone gateway is injectable from Tempest's container with zero registration:
```php
final class OrderController
{
public function __construct(
private CommandBus $commandBus,
) {}
#[Post('/orders')]
public function place(string $orderId): Redirect
{
$this->commandBus->sendWithRouting('order.place', $orderId);
return new Redirect('/orders');
}
}
```
*Tempest does the dependency injection; Ecotone provides the gateways. `QueryBus` and `EventBus` inject the same way.*
The split is clean. Tempest solves HTTP, DI, forms, database models, console. Ecotone adds, on top of the same models and the same container, the messaging layer an application needs when it grows.
---
## The shop, concept by concept
What we are building: a shop where a customer browses products, fills a cart and checks out. The checkout records an order; stock drops immediately; a notification appears on the dashboard; a confirmation email arrives in the inbox; the warehouse prepares a shipment whose history is an event stream feeding the read model on screen; and thirty seconds after the shipment is dispatched, the customer gets a review request.
It is an ordinary-looking application, which is the point — here is the dashboard a user actually sees:
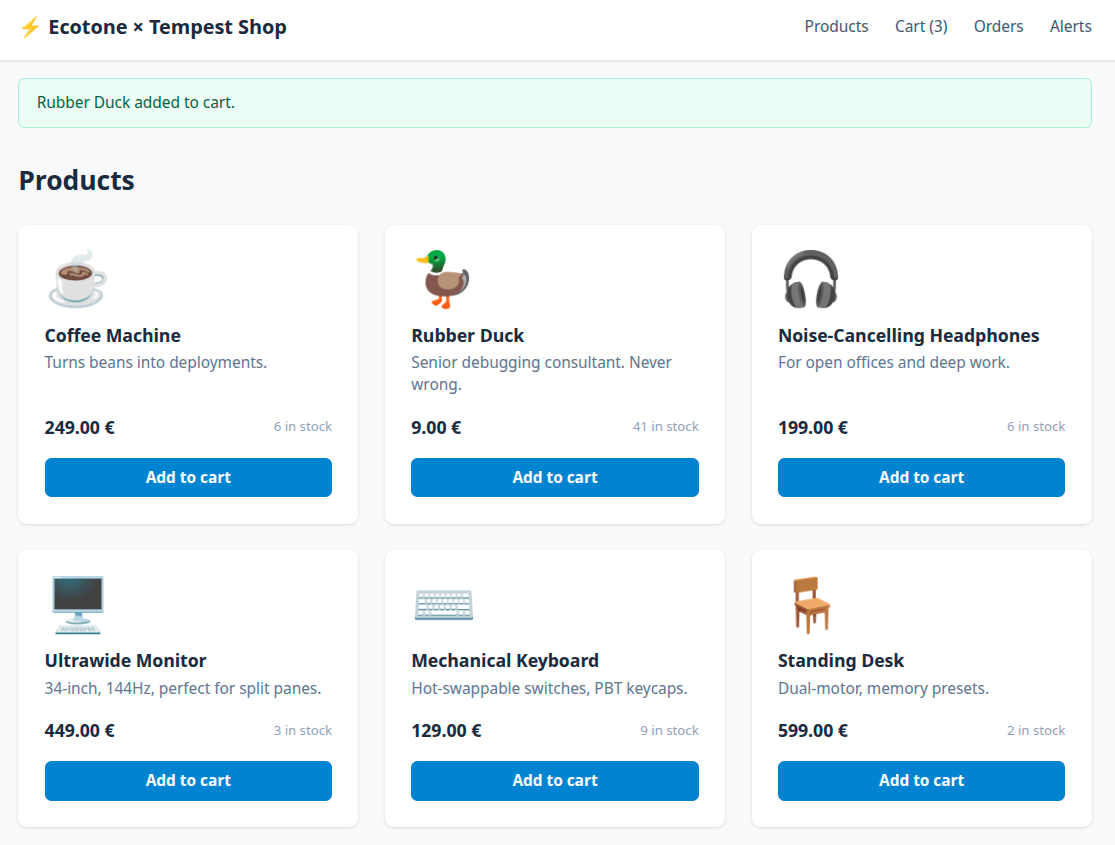
Demo Application Tempest + Ecotone
Every panel on that page comes from a different mechanism explained below: the tiles are a query, the shipments are a projection over an event stream, the notifications were written by a background worker. None of that is visible to the person clicking. One business flow, end to end:
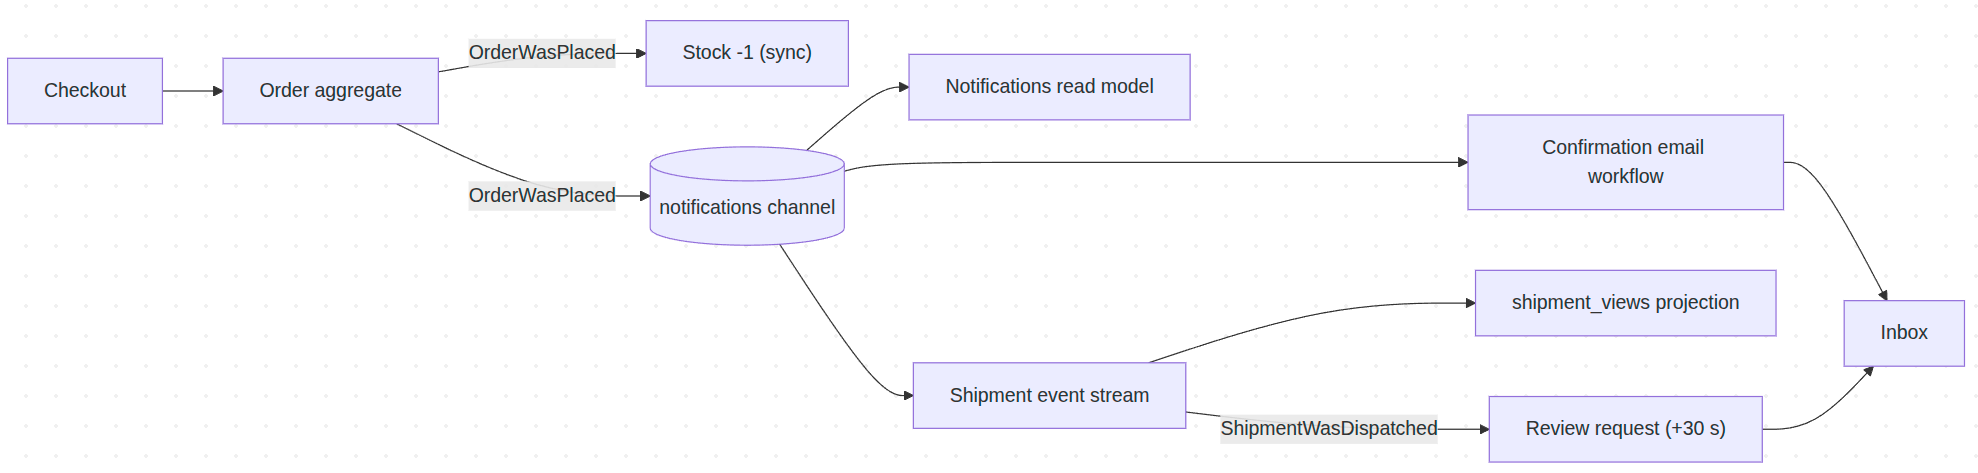
*The whole flow. Each section below delivers one highlighted piece of it.*
### Installation
Rolling out Tempest was one command: `composer create-project tempest/app app` — a working skeleton with routing, views, console. Adding Ecotone was one more: `composer require ecotone/tempest`.
### The aggregate is the Tempest model
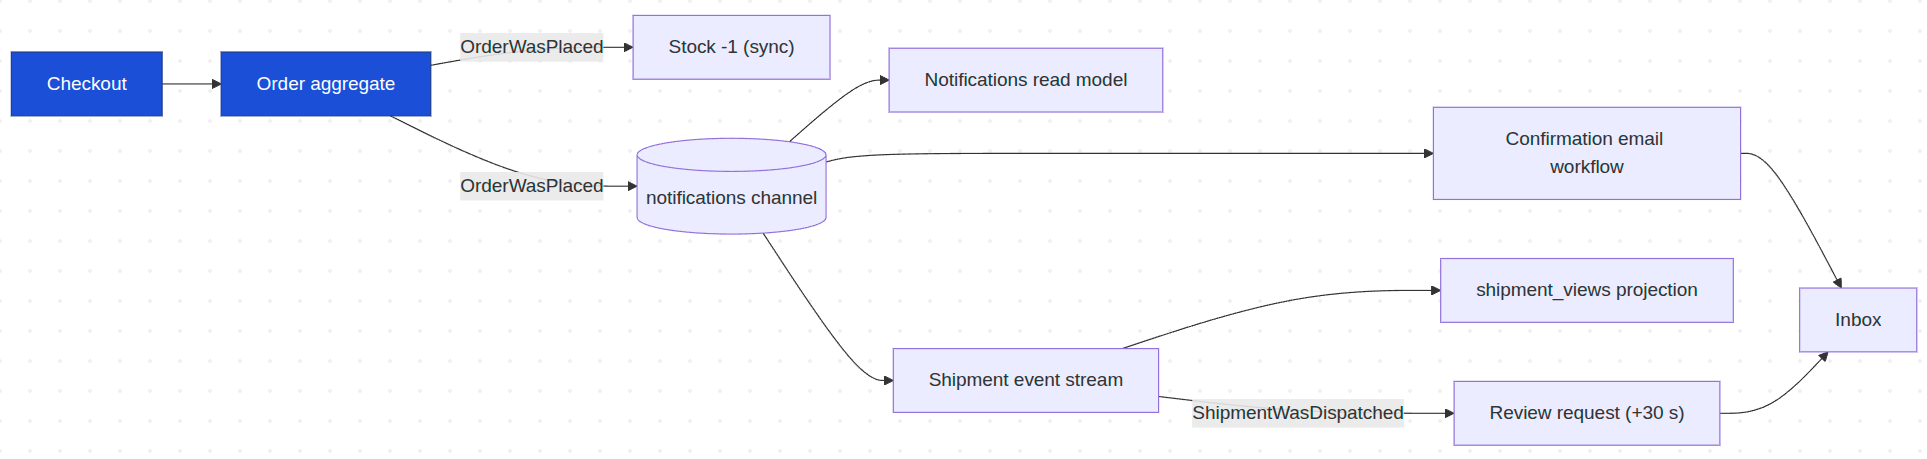
*We are here.*
Checkout needs somewhere to send `PlaceOrder` — and this is the strongest single moment in the integration, so look closely:
```php
#[Aggregate]
final class Order
{
use IsDatabaseModel;
public PrimaryKey $id;
public string $user_id;
public int $total_price;
public bool $is_cancelled;
#[CommandHandler]
public static function place(PlaceOrder $command): self
{
$order = new self();
$order->user_id = $command->userId;
$order->total_price = $command->totalPrice;
$order->is_cancelled = false;
$order->save();
return $order;
}
#[IdentifierMethod('id')]
public function getId(): int
{
return $this->id->value;
}
#[CommandHandler(routingKey: 'cancel_order')]
public function cancel(): void
{
$this->is_cancelled = true;
}
#[QueryHandler('is_cancelled')]
public function isCancelled(): bool
{
return $this->is_cancelled;
}
}
```
*One final class where both frameworks meet: `#[Aggregate]` from Ecotone, `IsDatabaseModel` from Tempest. The static `place()` factory is the creation handler — a command creates the aggregate, and `save()` goes through Tempest's own persistence.*
Look at `cancel()`. It mutates state. That is all it does. No fetch, no save, no repository injection. Sending a command to it looks like this:
```php
$orderId = $commandBus->send(new PlaceOrder(userId: 'user-1', totalPrice: 100));
$commandBus->sendWithRouting('cancel_order', metadata: ['aggregate.id' => $orderId]);
$queryBus->sendWithRouting('is_cancelled', metadata: ['aggregate.id' => $orderId]); // true
```
*Ecotone loads the model by id, calls the handler, saves it back — through Tempest's own persistence.*
There is no repository class to write. `TempestRepository` — Ecotone's built-in repository, shipped with the integration — makes any model using `IsDatabaseModel` usable as an aggregate directly. Checkout in the controller is three lines: build `PlaceOrder` from the cart, send it, redirect with the returned order id.
### Event handler: subscribing to what happened
*We are here.*
The aggregate records `OrderWasPlaced`. Subscribing to it is one attribute on a plain class — this synchronous handler decrements stock in the same transaction as the order:
```php
final class StockLevelUpdater
{
#[EventHandler]
public function whenOrderWasPlaced(OrderWasPlaced $event): void
{
foreach ($event->items as $line) {
$product = Product::findById($line->productId);
if ($product === null) {
continue;
}
$product->stock = max(0, $product->stock - $line->quantity);
$product->save();
}
}
}
```
*No subscription config, no event map — the parameter type is the subscription.*
### Asynchronous event handler
*We are here.*
The same event also drives handlers that should not block checkout. Adding `#[Asynchronous('notifications')]` moves a handler to a background worker consuming a database-backed channel — the consistency model is chosen per handler:
```php
final class NotificationRecorder
{
#[Asynchronous('notifications')]
#[EventHandler(endpointId: 'notification.order_placed')]
public function whenOrderWasPlaced(OrderWasPlaced $event): void
{
Notification::create(
message: sprintf('Order #%d placed by %s', $event->orderId, $event->customerName),
type: 'order_placed',
);
}
}
```
*One attribute picks the consistency model per handler.*
And this is the moment the integration gets registered. The `notifications` channel the attribute refers to is declared in the application's only Ecotone configuration — one small class, two one-line methods: bridge Tempest's Postgres config into Ecotone, and declare the durable channel:
```php
final class MessagingConfiguration
{
#[ServiceContext]
public function connection(): TempestConnectionReference
{
return TempestConnectionReference::defaultConnection();
}
#[ServiceContext]
public function notificationsChannel(): DbalBackedMessageChannelBuilder
{
return DbalBackedMessageChannelBuilder::create('notifications');
}
}
```
*`#[ServiceContext]` methods are discovered like everything else. The channel runs on the same Postgres connection Tempest's models use.*
Three async handlers hang off the same event: this one writes the notifications read model, one starts the confirmation-email workflow, one starts shipment preparation. The worker is Ecotone's own CLI entrypoint — `./tempest ecotone:run notifications` — with no app code behind it.
### Event sourcing and a projection
*We are here.*
`Shipment` is an `#[EventSourcingAggregate]`: its state is not a table row but the stream of events in the Postgres event store. Command handlers return events; `#[EventSourcingHandler]` methods rebuild the state from them:
```php
#[EventSourcingAggregate]
final class Shipment
{
use WithAggregateVersioning;
#[Identifier]
private string $orderId;
private string $customerName = '';
private string $customerEmail = '';
private bool $dispatched = false;
#[CommandHandler]
public static function prepare(PrepareShipment $command): array
{
return [new ShipmentWasPrepared(
orderId: $command->orderId,
customerName: $command->customerName,
packageCount: $command->packageCount,
customerEmail: $command->customerEmail,
)];
}
#[CommandHandler(routingKey: 'shipment.dispatch')]
public function dispatch(): array
{
if ($this->dispatched) {
return [];
}
return [new ShipmentWasDispatched(
orderId: $this->orderId,
customerName: $this->customerName,
customerEmail: $this->customerEmail,
)];
}
#[EventSourcingHandler]
public function applyPrepared(ShipmentWasPrepared $event): void
{
$this->orderId = $event->orderId;
$this->customerName = $event->customerName;
$this->customerEmail = $event->customerEmail;
}
#[EventSourcingHandler]
public function applyDispatched(ShipmentWasDispatched $event): void
{
$this->dispatched = true;
}
}
```
*Handlers return events; state is rebuilt from the stream. The `dispatched` guard makes the Dispatch button idempotent — clicking twice records nothing twice.*
The UI never reads the stream directly. A `#[Projection]` derives the read model — and the read model is a plain Tempest model:
```php
#[Projection('shipment_list', Shipment::class)]
final class ShipmentListProjection
{
#[EventHandler]
public function whenShipmentWasPrepared(ShipmentWasPrepared $event): void
{
ShipmentView::create(
order_id: $event->orderId,
customer_name: $event->customerName,
package_count: $event->packageCount,
status: 'prepared',
);
}
#[EventHandler]
public function whenShipmentWasDispatched(ShipmentWasDispatched $event): void
{
$view = ShipmentView::find(order_id: $event->orderId)->first();
$view->status = 'dispatched';
$view->save();
}
}
```
*The projection writes `ShipmentView` — a Tempest `IsDatabaseModel` — so the dashboard queries it like any other table.*
### Workflow: async emails end to end
*We are here.*
The email pipeline is three small steps connected by channel names, and each step owns exactly one concern. The event handler composes the CONTENT — and only the content. It does not know the recipient; it passes the notification forward with the id needed to find out:
```php
#[Asynchronous('notifications')]
#[EventHandler(endpointId: 'order_confirmation.start', outputChannelName: 'notification.enrich')]
public function start(OrderWasPlaced $event): EmailNotification
{
return new EmailNotification(
orderId: (string) $event->orderId,
subject: sprintf('Order #%d confirmed', $event->orderId),
html: /* ...items and total rendered to HTML */,
);
}
```
*Content and an id. No recipient, no mailer, no bus.*
The next step enriches the message HEADERS with the account details. With `changingHeaders: true`, the returned array is merged into the headers while the payload passes through untouched:
```php
final readonly class AccountDetailsEnricher
{
#[InternalHandler(
inputChannelName: 'notification.enrich',
outputChannelName: 'email.send',
changingHeaders: true,
)]
public function enrich(EmailNotification $notification): array
{
$order = Order::findById((int) $notification->orderId);
return [
'customerEmail' => $order->customer_email ?? '',
'customerName' => $order->customer_name ?? '',
];
}
}
```
*A pipeline step that only adds knowledge. The payload flows on unchanged.*
And the last step is a prepared building block: it reads the payload plus the enriched headers, builds the `GenericEmail`, and sends through Tempest's own `Mailer`:
```php
#[InternalHandler(inputChannelName: 'email.send')]
public function send(
EmailNotification $notification,
#[Header('customerEmail')] ?string $customerEmail,
#[Header('customerName')] ?string $customerName,
Mailer $mailer,
): void {
if ($customerEmail === null || $customerEmail === '') {
return;
}
$mailer->send(new GenericEmail(
subject: $notification->subject,
to: $customerEmail,
html: sprintf('Hi %s!
', $customerName) . $notification->html,
));
}
```
*The send block never changes — any notification in the application can flow through it. The delayed review request in the next section reuses this exact chain.*
And the end of the chain is a real email, sent by the background worker through Tempest's `Mailer` — here caught by Mailpit, next to the delayed review request from the section below:
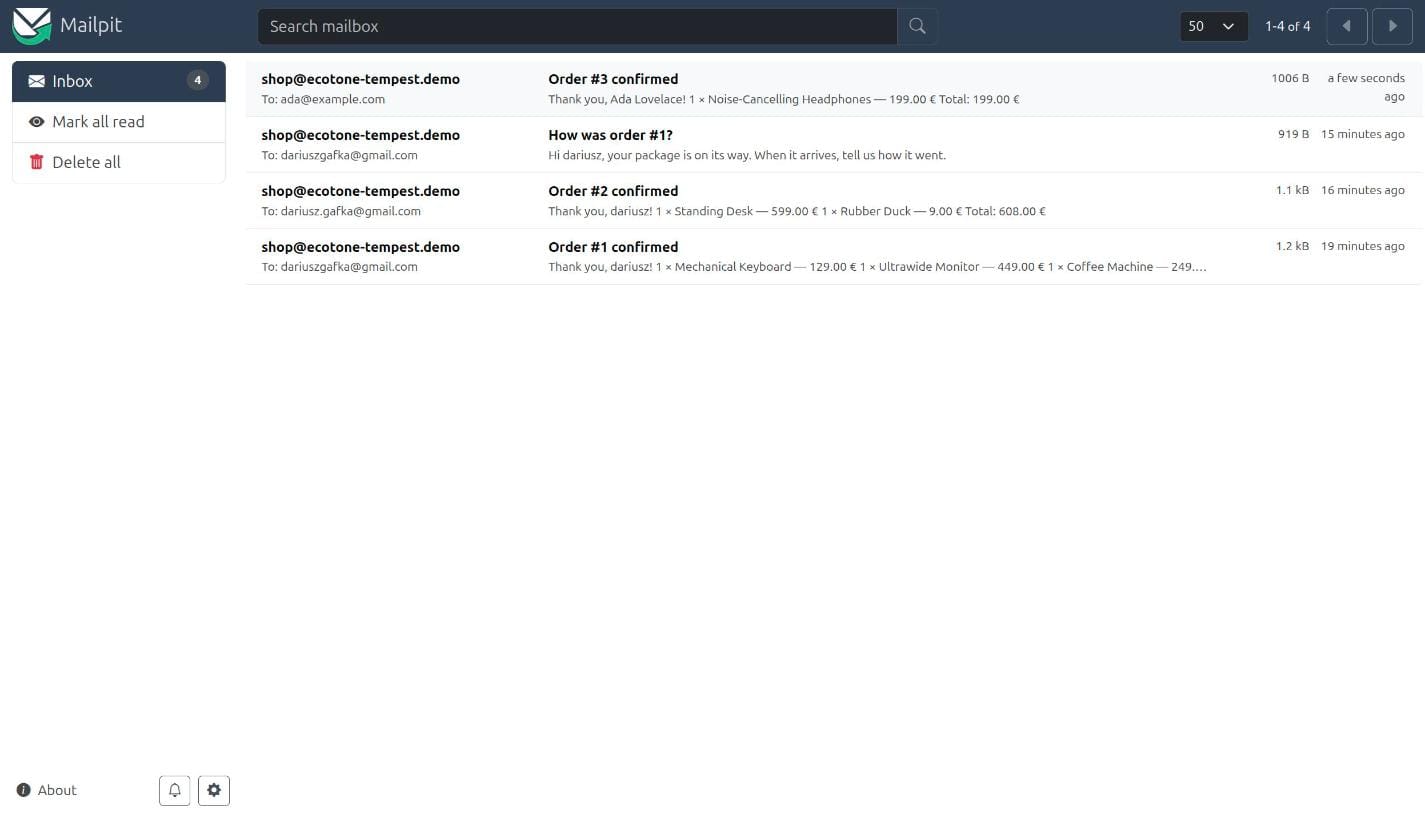
### Delayed messages
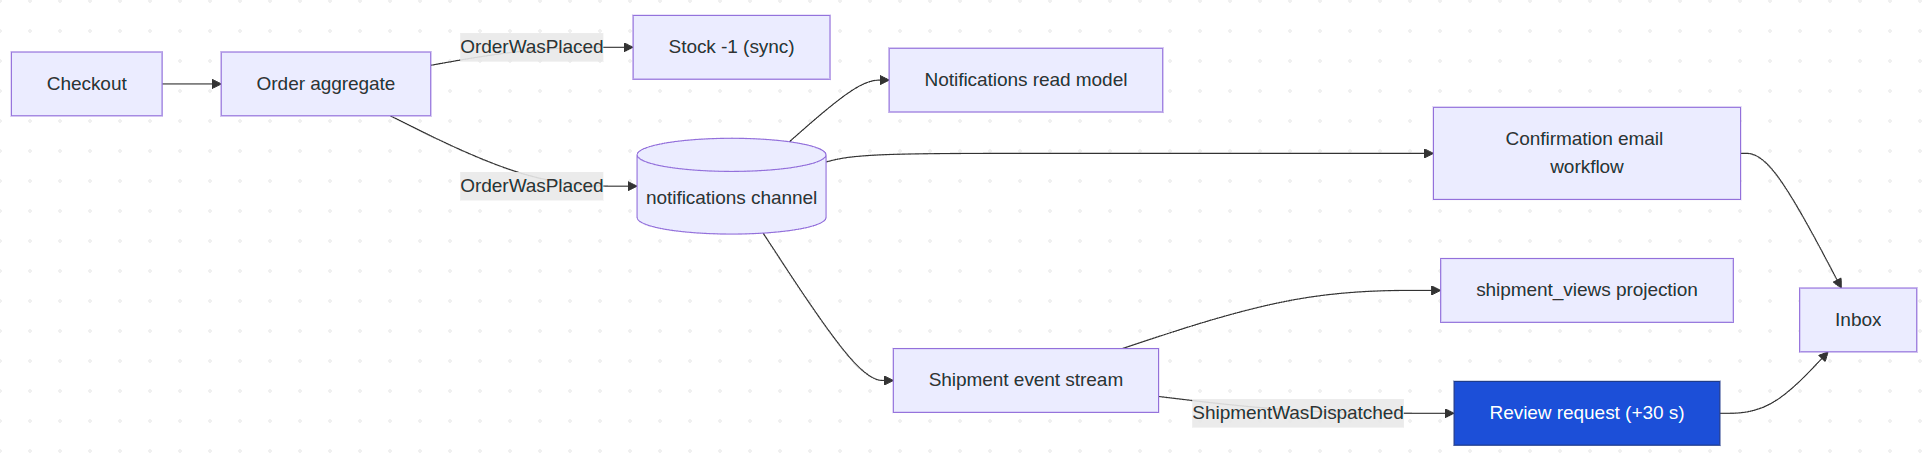
*We are here.*
Thirty seconds after a shipment is dispatched, the customer gets a review request. This is not a recurring job for a scheduler: it is one specific message, due once, thirty seconds after its own trigger. It waits inside the durable channel — surviving worker restarts — and is released when due:
```php
#[Delayed(new TimeSpan(seconds: 30))]
#[Asynchronous('notifications')]
#[EventHandler(endpointId: 'review_request.on_shipment_dispatched', outputChannelName: 'notification.enrich')]
public function requestReview(ShipmentWasDispatched $event): EmailNotification
{
return new EmailNotification(
orderId: $event->orderId,
subject: sprintf('How was order #%s?', $event->orderId),
html: 'Your package is on its way. When it arrives, tell us how it went.
',
);
}
```
*One attribute replaces the scheduler — and the whole delayed email is eight lines of content, because enrichment and sending come from the pipeline it flows through.*
### When the mail step fails: retries, dead letter, alerts page
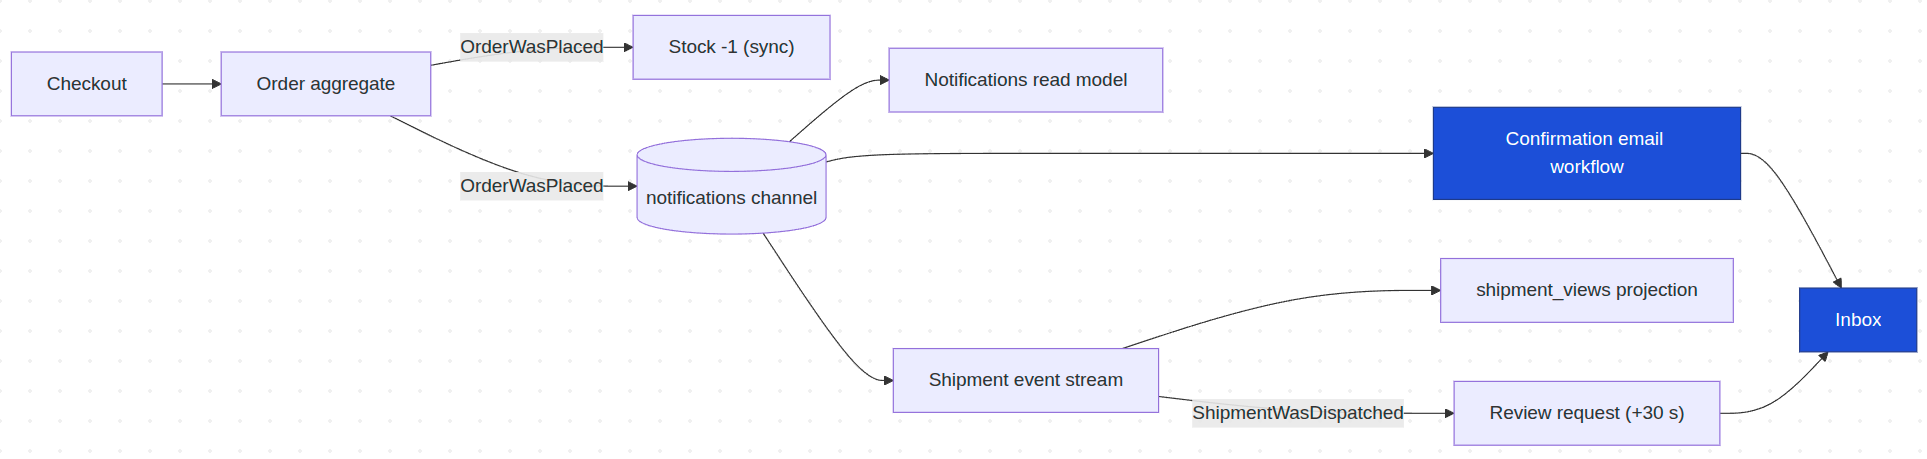
*We are here — the one step in this flow that talks to the outside world, and therefore the one that fails.*
The checkout form has a "simulate an email delivery failure" checkbox:
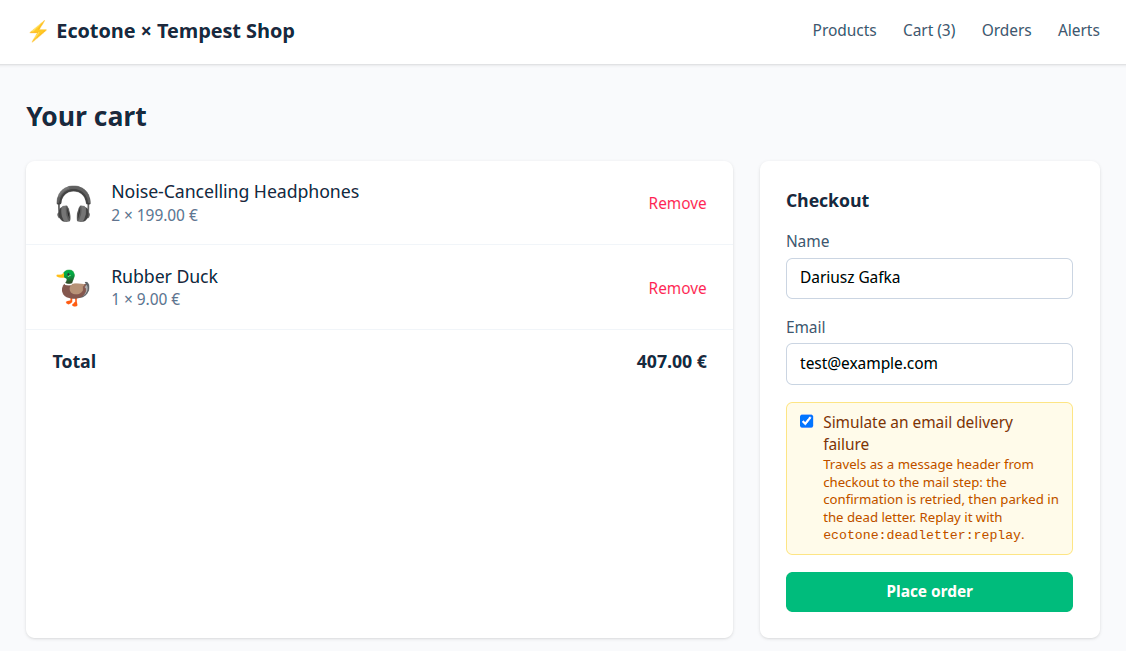
It is sent as metadata on the command, and that metadata propagates automatically in Ecotone. Therefore without any additional code we catch it in Event Handler sending Mail and do simulated failure.
Tick it and the send throws. The message is retried after one second, retried again after three, and then parked in a database-backed dead letter with its stacktrace. The order placed right behind it, without the box ticked, gets its email immediately — same channel, no blockage, and the worker keeps running. That behavior is a third `#[ServiceContext]` method on the same config class from earlier:
```php
#[ServiceContext]
public function errorHandling(): ErrorHandlerConfiguration
{
return ErrorHandlerConfiguration::createWithDeadLetterChannel(
'errorChannel',
RetryTemplateBuilder::exponentialBackoff(initialDelay: 1000, multiplier: 3)
->maxRetryAttempts(2),
'dbal_dead_letter',
);
}
```
*No retry loops in handlers, no dead-letter migration, no supervisor watching the worker.*
Recovery is a console command, because Ecotone's commands are discovered by Tempest like any other:
```bash
./tempest ecotone:deadletter:list # what is parked, when it failed, why
./tempest ecotone:deadletter:show # full payload and stacktrace
./tempest ecotone:deadletter:replay
```
But operations work is not always CLI work, and this is where the layering pays off again: the dead letter is not a private mechanism, it is a service. `DeadLetterGateway` injects into any Tempest controller, so the demo turns it into a page:
```php
final readonly class AlertsController
{
public function __construct(private DeadLetterGateway $deadLetter) {}
#[Get('/alerts')]
public function index(): View
{
return view('./alerts.view.php', errors: $this->deadLetter->list(limit: 50, offset: 0));
}
#[Post('/alerts/{messageId}/replay')]
public function replay(string $messageId): Redirect
{
$this->deadLetter->reply($messageId);
return new Redirect('/alerts');
}
}
```
*Two routes and a view. Each entry is an `ErrorContext` — message id, failure time, exception class and message, file, line, stacktrace — so the template has everything an operations screen needs.*
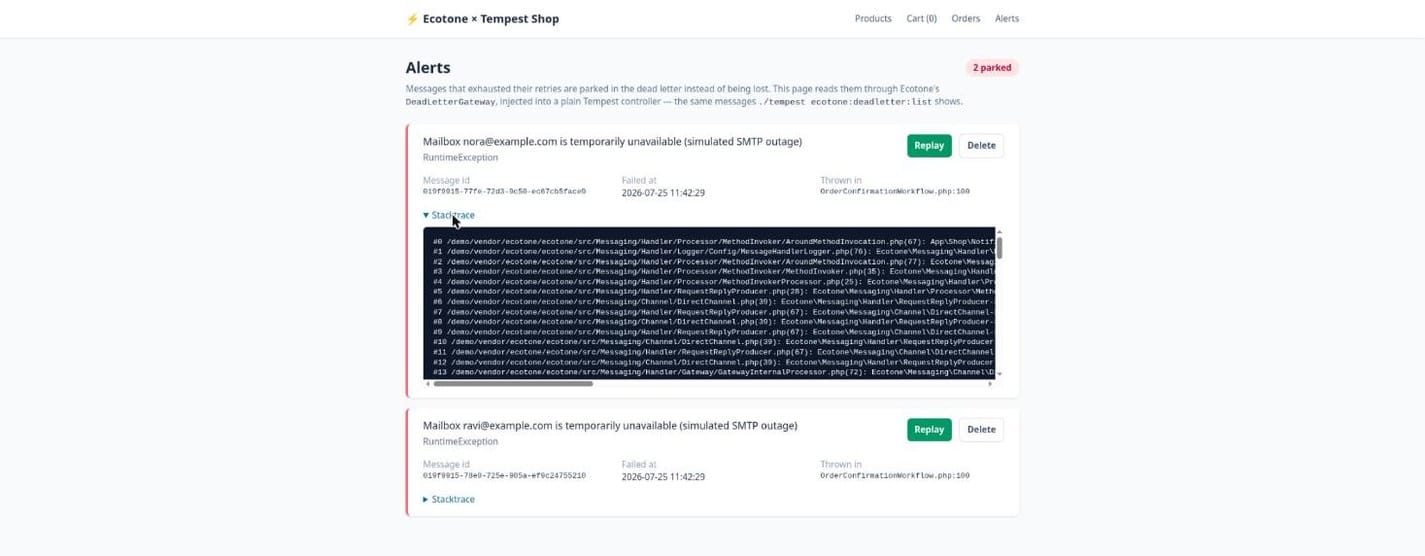
One detail worth stealing even if you never use this page: a replayed message carries the header `ecotone.dlq.message_replied`, readable as a normal `#[Header]` parameter. Recovery can therefore behave differently from the first attempt — skip a step that already succeeded, relax a guard, tag the result. A handler gets to see how a message reached it, not only what it carries.
### Outbox and deduplication
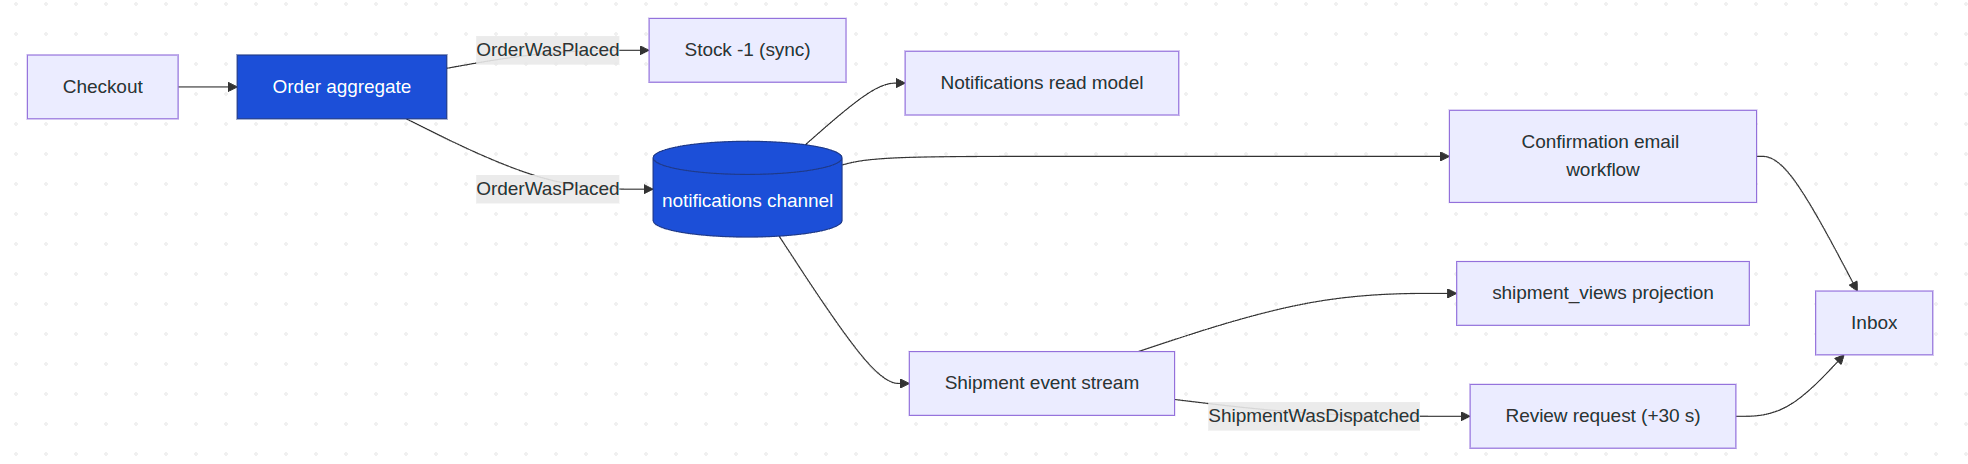
*We are here.*
Stop the worker and place an order. The order row and its event messages are committed in the same Postgres transaction, because the channel is database-backed — `select count(*) from enqueue where queue='notifications'` shows them waiting. Start the worker; the table drains and the emails go out. The dual-write problem ("order saved, event lost") cannot happen here, and nothing was configured to make that true. Redelivered messages are skipped through the `ecotone_deduplication` table — also zero code.
### Multi-tenancy
Beyond this flow, the package also covers tenant separation. When you need it, a single message header routes commands, queries, transactions and business-interface SQL to the right tenant database:
```php
$commandBus->send(new RegisterCustomer(1, 'John Doe'), metadata: ['tenant' => 'tenant_a']);
$commandBus->send(new RegisterCustomer(2, 'John Doe'), metadata: ['tenant' => 'tenant_b']);
$queryBus->sendWithRouting('customer.getAllRegistered', metadata: ['tenant' => 'tenant_a']); // [1]
```
*Tenant routing decided by one metadata header, and is automatically propagated to asynchronous flows.*
## The count
The application's entire messaging layer:
- one state-stored aggregate (`Order`)
- one event-sourced aggregate (`Shipment`)
- commands and events as plain readonly objects
- four event handlers
- one projection
- one query service
- one workflow, plus the enrichment step it flows through
- one config class: connection, channel, error handling
That is about a dozen small classes. Everything else in the codebase is Tempest UI: controllers, views, a session cart — including the alerts page, which is two routes on top of `DeadLetterGateway`. There is no custom worker command, no repository, no serializer configuration, no queue wiring. The architecture list reads like a system that needs a platform team; the diff reads like a weekend project.
The count also survived the resiliency additions. Retries with dead-lettering came in as one `#[ServiceContext]` method on the existing config class; the delayed review email is one method on the existing workflow class; the outbox and deduplication needed no code at all. The feature list grew, the class list did not.
## Transferable lessons
1. **Declarative + declarative composes; imperative + declarative fights.** The integration is thin because neither side adapts to the other's philosophy. When picking tools to combine, alignment of principles matters more than feature lists.
2. **Zero config means reading what the app already declares.** PSR-4 roots, database config — the developer wrote them once; the integration derives from them instead of asking twice.
3. **A framework choice does not have to mean an ecosystem ceiling.** The "good fit, once more mature" objection assumes every capability must come from the framework's own ecosystem. A portable architecture layer breaks that assumption: the same Ecotone code runs on Laravel, Symfony, and now Tempest.
4. **Enterprise-grade is a property of the architecture, not the amount of code.** Transactions shared with the ORM connection, dead-letter support, tenant routing — none of it written by the application.
## Wrapping up
Tempest gaining CQRS is the small news. The bigger news is what two discovery-based frameworks make possible when composed: an enterprise-level feature list carried by application code that holds only business logic. If you have been telling yourself that this architecture is for teams with a platform group, count the classes again.
[Explore Ecotone for Tempest](https://docs.ecotone.tech/modules/tempest?ref=blog.ecotone.tech)
---
*About the author: Dariusz Gafka is a Software Architect and author of the* [*Ecotone Framework*](https://github.com/ecotoneframework/ecotone?ref=blog.ecotone.tech)*. He writes about event sourcing, CQRS, and PHP architecture patterns.*
### Ecotone's support for Closures in Attributes
URL: https://blog.ecotone.tech/ecotones-support-for-closures-in-attributes/
Last updated: 2026-07-20T19:40:40.000Z
*Updated on 2026-07-20*
You need a message delayed by whatever the command says: `$command->delayInMilliseconds`. That is one line of logic. Until now, expressing it meant either an expression string your IDE cannot see into, or a middleware class with a constructor, a registration, and a file of its own. This is a walk through what that exchange rate used to look like in practice, and what it looks like now that Ecotone executes real closures inside attributes.
> **TL;DR:** Every `expression` property in Ecotone now accepts a typed `Closure` instead of a Symfony expression string. Closures run with message-handler-style parameter resolution (`#[Payload]`, `#[Header]`, `#[Reference]` injection), so a dynamic delay, header, dedup key, or SQL parameter is one refactorable line where it is needed, with no middleware.
## Table of contents
- [Before: the price of one computed value](#before-the-price-of-one-computed-value)
- [After: the delay that reads itself](#after-the-delay-that-reads-itself)
- [Deriving a header with a service](#deriving-a-header-with-a-service)
- [SQL parameters from two fields](#sql-parameters-from-two-fields)
- [Why the closures stay small](#why-the-closures-stay-small)
- [When I would still write the string](#when-i-would-still-write-the-string)
- [Wrapping up](#wrapping-up)
## Before: the price of one computed value
Declarative configuration is a good deal right up until the first value that has to be computed. A static delay is one attribute argument. A delay that depends on the command payload used to give you two options.
Option one, the expression string:
```php
#[Delayed(expression: 'payload.delayInMilliseconds')]
```
*Looks harmless. It is a string.*
Rename `delayInMilliseconds` to `delayMs` and every real usage updates through your refactoring tool, except this one. PHPStan cannot check it. Autocomplete cannot complete it. The break is silent and surfaces at runtime, only on the code path that dispatches this particular command. In Symfony land the community verdict on expression syntax is on record: "even more ugly (and goodbye to static analysis)."
Option two, the middleware class. A real class implementing the middleware contract, reading the payload, attaching a delay stamp, registered in dispatch configuration. It type-checks beautifully. It is also a separate file, in a separate layer, executed at a distance from the handler it configures, and it exists to carry one line of logic.
Both directions are compensating for the same gap, which we can solve with Closures in Attributes.
ℹ️
Prerequisites — PHP 8.5+, Ecotone 1.320+ with an Enterprise licence for closure expressions, basic familiarity with asynchronous message handling
## After: the delay that reads itself
PHP 8.5 made closures legal inside attributes, and [Ecotone PR #678](https://github.com/ecotoneframework/ecotone-dev/pull/678?ref=blog.ecotone.tech) makes them work as expressions. The same dynamic delay:
```php
#[Delayed(expression: static function (#[Payload] NotifyCustomer $command): int {
return $command->delayInMilliseconds;
})]
#[Asynchronous('async')]
#[CommandHandler('customer.notify', endpointId: 'customerNotifyEndpoint')]
public function notify(NotifyCustomer $command): void {}
```
*The delay logic sits on the handler it delays, typed end to end.*
Three things changed, and all of them are tooling-visible. The parameter is typed `NotifyCustomer`, so autocomplete works inside the closure. The return type is `int`, so PHPStan verifies you are returning something `#[Delayed]` can use. And the property access is real code, so a rename refactor reaches it. The one line of logic costs one line.
Note what did not change: the handler itself is untouched. No fake parameters, no base-class hooks, no `getDelay()` override. The [delayed messaging behavior](https://docs.ecotone.tech/modelling/asynchronous-handling?ref=blog.ecotone.tech) is still declared where the handler is declared.
## Deriving a header with a service
The above was a simple case, because in most the cases it maps to single property. The more interesting case is a value that needs a collaborator.
Now the closure asks for what it needs:
```php
#[CommandHandler('order.place')]
public function placeOrder(
PlaceOrder $command,
#[Header('token', expression: static function (#[Header('token')] string $token, #[Reference] TokenService $tokenService): string {
return $tokenService->normalize($token);
})] string $token,
): void {}
```
*`#[Header]` binds the raw header, `#[Reference]` injects the service; the handler receives the normalized value.*
## SQL parameters from two fields
The same mechanism reaches into the DBAL business interface. Building a SQL parameter from two method arguments used to be an expression string doing string concatenation inside a string, which is as pleasant as it sounds. Now:
```php
#[DbalWrite('INSERT INTO persons (person_id, name) VALUES (:personId, :fullName)')]
#[DbalParameter('fullName', expression: static function (string $firstName, string $lastName): string {
return ucfirst($firstName) . ' ' . ucfirst($lastName);
})]
public function insert(int $personId, string $firstName, string $lastName): void;
```
*Closure parameters map to the interface method's arguments by name.*
The full list of attributes that accept closures now: `#[Payload]`, `#[Header]`, `#[Reference]`, `#[Fetch]`, `#[AddHeader]`, `#[Delayed]`, `#[TimeToLive]`, `#[Deduplicated]`, `#[DbalParameter]`, and `#[WithTenantResolver]`. Dynamic dedup keys and per-tenant connection resolution fall out of the same feature — the two cases that generated the loudest "attributes are static by definition" complaints in the Laravel multi-tenant world.
## Why the closures stay small
The design decision that makes this hold up in practice: closures are executed like message handlers, not like bare callbacks. The new `AttributeExpressionExecutor` runs each closure through the same parameter-resolution pipeline handlers use. `#[Payload]` converts the payload, `#[Header]` and `#[Headers]` bind metadata, `#[Reference]` resolves services, `#[ConfigurationVariable]` pulls configuration, a `Message` type-hint hands over the whole message, and an unannotated first parameter defaults to the payload.
That pipeline is why every closure in this article is one statement long. Conversion, binding, and lookup are the framework's job; the closure holds only the derivation. It also means there is no new API to learn — if you know how Ecotone handler parameters resolve, you already know how attribute closures resolve. One mental model.
The trade-offs, named. Closure expressions are an Enterprise feature; without a licence, bootstrap throws a `LicensingException` immediately rather than letting the first production message fail. Expression strings still work (the properties are `string|Closure`), so nothing forces a migration. And under the hood the container never serializes your closure; it stores a reference to the declaring class, method, or parameter and re-reads the attribute via reflection, which is what keeps cached containers working.
## When I would still write the string
Honesty section. If the expression is `'payload.id'`, the string is shorter and the closure buys you little. Where closures earn their keep is anywhere a rename could land, anywhere a type conversion matters, and anywhere you were about to write infrastructure. And where neither belongs: actual business logic. A closure with branching in an attribute is business logic hiding in an annotation; that goes in the handler. The feature is for derivations, and the moment a derivation stops fitting on one line, extract it into a service and inject it with `#[Reference]`.
## Wrapping up
The exchange rate was the problem: one line of logic for one class of infrastructure, or one line of logic for one unanalyzable string. Typed closures in attributes bring it back to one for one. Try converting a single expression string in a codebase you own and run PHPStan on the result — the diff is small and the difference in confidence is not.
[Explore the Ecotone docs](https://docs.ecotone.tech/?ref=blog.ecotone.tech)
---
*About the author: Dariusz Gafka is a Software Architect and author of the* [*Ecotone Framework*](https://github.com/ecotoneframework/ecotone?ref=blog.ecotone.tech)*. He writes about event sourcing, CQRS, and PHP architecture patterns.*
### Evolve Live Projections Without Downtime
URL: https://blog.ecotone.tech/evolve-live-projections-without-downtime/
Last updated: 2026-05-18T07:34:44.000Z
It is Friday afternoon. Your `ticket_list` projection has been running in production for six months. Then someone flags a problem: part of the dashboard no longer matches what the events say happened. A handler bug slipped in months ago and quietly miscategorized rows. Or maybe the product team asks for a new derived column — `priority`, computed from rules around `TicketWasRegistered`.
Different cause, same outcome: **the data in your projection table is now incorrect or incomplete, and you need a way to fix it safely.**
> Deployments are straightforward when the projection logic stays the same. The problem starts when the logic changes and you need to replay events to rebuild the projection. As the event log grows, re-runs become slower: what once took minutes eventually takes hours, and what takes hours today may eventually take days.
This means we need clear strategies for replaying projections effectively, so the whole process remains smooth, safe, and predictable.
## Why Projection Rebuilds Shape Team Behavior
Imagine you spent two days waiting. The dashboard was empty for most of it. The replay finally finishes at 3 AM, and the numbers do not match what you expected. Now you have to fix the handler, reset again, and wait another two days. Meanwhile, the column you were supposed to ship by Friday is still empty.
And of course there is more, what when something fails mid-rebuild - for example old Event cannot be deserialized, or there is bug in the projection handler. Does the whole process get stuck waiting for someone to come and investigate the next morning?
What if the volume of events grows? Do you have means to scale the rebuild together with the growth?
> And here is what happens consequently. **The way your projecting system works defines how your team treats it.**
If a rebuild takes days, people will do everything they can to avoid running one. They will batch projection changes into rare "rebuild windows." They will modify projection table directly without running changes through rebuild. They will manually patch rows to fix individual bugs. **Each of those workarounds chips away at the guarantee that "your read model is just a function of your events."** Once enough manual patches accumulate, nobody trusts a rebuild anymore — because nobody knows if the result will look the same as what is in production.
So let's look at how to deal with all of this. We will start from the foundation — rebuild — and progressively layer on the extensions that make it recoverable, scalable, and safe enough to run alongside a live projection. **Each step keeps the process maintainable and the team supported, so replay becomes a tool the team reaches for, not one they schedule around.**
## The No-Rebuild Tactic — Default Values as a Quick Win
Before reaching for any replay strategy, ask one question: **does the new (or corrected) column actually need to be computed from history, or is a sensible default good enough for existing rows?**
If "good enough" is on the table, you can skip replay entirely. This is the cheapest migration available, and it deserves the first slot in this article because most teams jump past it.
> The trick lives in the `#[ProjectionInitialization]` hook. Most teams write it once as a `CREATE TABLE` and never touch it again. But Ecotone re-runs the hook every time we run projection initialization — so if you write it to be idempotent *and* schema-aware, the same hook becomes a lightweight migration tool
```php
#[ProjectionInitialization]
public function init(#[ProjectionName] string $projectionName): void
{
$this->connection->executeStatement(
"CREATE TABLE IF NOT EXISTS {$projectionName} (
ticket_id VARCHAR(36) PRIMARY KEY,
status VARCHAR(25),
priority VARCHAR(25) NOT NULL DEFAULT 'normal'
)"
);
$this->connection->executeStatement(
"ALTER TABLE {$projectionName}
ADD COLUMN IF NOT EXISTS priority VARCHAR(25) NOT NULL DEFAULT 'normal'"
);
}
```
*The `CREATE TABLE IF NOT EXISTS` covers fresh deployments. The `ALTER TABLE ... ADD COLUMN IF NOT EXISTS` covers projections that were created before the column existed — it is a no-op when the column is already there.*
And to execute that we run projection init:
```bash
bin/console ecotone:projection:init ticket_list
```
What this buys you: every historical row gets `priority = 'normal'` instantly when the deployment lands. New events flow through your updated handler and set the real value going forward. No replay. No double-storage. No rebuild window. No coordination with operations.
**This is a conversation to have with Product to know whatever we can apply this technique.** A five-minute negotiation around "is the default acceptable for historical rows?". If yes, ship the ALTER and move on. If no, then next strategies will show what to do instead.
## Blue-Green Deployments — The Safest Path
The idea is simple: deploy `ticket_list_v2` alongside `ticket_list_v1`. Both read from the same Event Store. V1 keeps serving traffic while V2 catches up in the background. If V2 is wrong, V1 is untouched. No data loss, no corruption, no frantic hotfix at 2 AM.
It gives us ability to switch to V2 when we are ready, without any downtime.
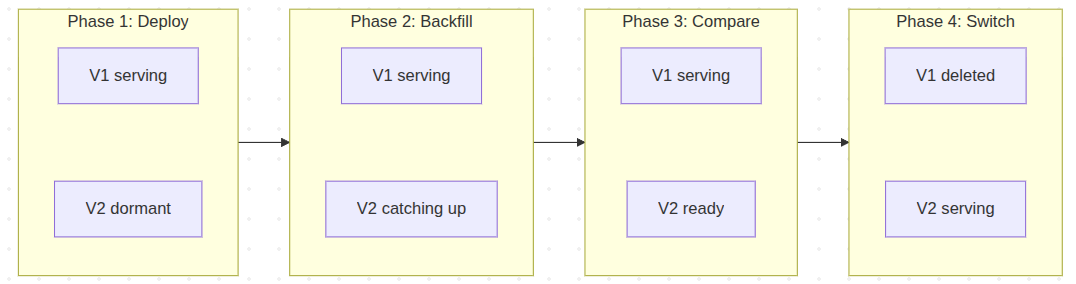
**V1 serves live traffic throughout — V2 catches up in the background before the switchover*
Two attributes make this work. `#[ProjectionDeployment]` controls the deployment lifecycle:
```php
#[ProjectionV2('ticket_list_v2')]
#[FromAggregateStream(Ticket::class)]
#[ProjectionDeployment(manualKickOff: true)]
class TicketListV2Projection
{
// Updated handlers with the new priority column
}
```
**`manualKickOff: true`** means the projection will not auto-initialize on deployment — you control when it starts, when it backfills, and when it is promoted to serve traffic. Until then, V2 sits there as deployed code waiting for your command.
### Dynamic Table Names
Here is the technique that makes blue-green projections elegant: V1 lives in one class, V2 *extends* it and only overrides what changed. Each class declares its own projection name through `#[ProjectionV2(...)]`, and `#[ProjectionName]` injects that name into every lifecycle hook and event handler — so the same code path writes to its own table per version.
The V1 class declares the schema and the original handlers:
```php
#[ProjectionV2('ticket_list_v1')]
#[FromAggregateStream(Ticket::class)]
class TicketListProjection
{
public function __construct(protected Connection $connection) {}
#[ProjectionInitialization]
public function init(#[ProjectionName] string $projectionName): void
{
$this->connection->executeStatement(
"CREATE TABLE IF NOT EXISTS {$projectionName} (
ticket_id VARCHAR(36) PRIMARY KEY,
status VARCHAR(25),
priority VARCHAR(25)
)"
);
}
#[EventHandler]
public function onTicketRegistered(
TicketWasRegistered $event,
#[ProjectionName] string $projectionName
): void {
$this->connection->insert($projectionName, [
'ticket_id' => $event->ticketId,
'status' => 'open',
'priority' => 'normal', // ← buggy: always 'normal'
]);
}
(...) // Many other handlers
}
```
V2 extends V1 and replaces only the handler that needed to change:
```php
#[ProjectionV2('ticket_list_v2')]
#[ProjectionDeployment(manualKickOff: true)]
class TicketListV2Projection extends TicketListProjection
{
#[EventHandler]
public function onTicketRegistered(
TicketWasRegistered $event,
#[ProjectionName] string $projectionName
): void {
$this->connection->insert($projectionName, [
'ticket_id' => $event->ticketId,
'status' => 'open',
'priority' => $this->derivePriorityFrom($event), // ← correct logic
]);
}
}
```
*V2 inherits `init`, `delete`, and every other handler from V1\. Only the one handler that needed fixing is overridden — the diff in code is the diff in behavior, and that is exactly what reviewers and tests should focus on.*
And initialize each:
```bash
bin/console ecotone:projection:init ticket_list_v1
# V2 creates its fresh table independently.
bin/console ecotone:projection:init ticket_list_v2
```
Because each class declares its own projection name through `#[ProjectionV2(...)]`, deploying both produces two completely separate tables. No conflicts. Both projections process the same events from the same Event Store, writing to independent storage. You can query both tables, compare row counts, spot-check edge cases — all while V1 continues serving production traffic.
Now you just have two tables, side by side, and you switch when you are ready. If V2 produces wrong results — wrong priority calculations, missing rows, whatever — V1 is completely untouched. Roll back by deleting V2\. Done.
### How V2 Catches Up to Real-Time
From here, the question that always comes up: V1 is moving forward in real-time while V2 is reading history from event zero. How does V2 ever catch up — and what happens when it does?
With both tables initialized, V2 is sitting at position zero — empty. You trigger the catch-up explicitly:
```bash
bin/console ecotone:projection:backfill ticket_list_v2
```
Each projection has its own independent position tracker. V1's position points somewhere near the current head of the event store. V2 starts at zero. Once the backfill command kicks in, V2 reads events in batches, applies them through your handlers, writes to `ticket_list_v2`, and commits the new position — all in one transaction per batch. Meanwhile, new events keep arriving, and V1 keeps consuming them in real-time.
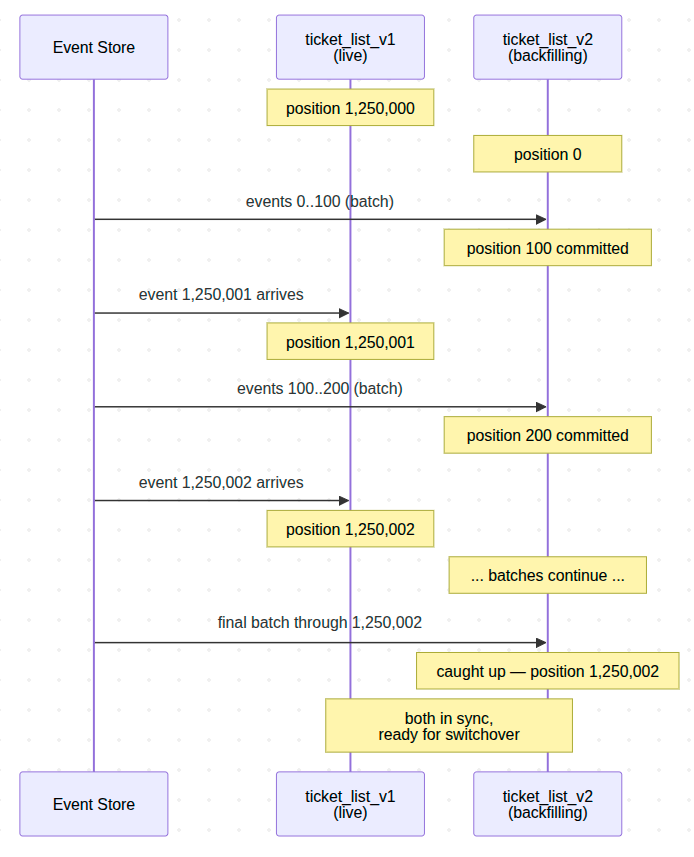
**V2 reads history while V1 reads real-time. Each batch commits position transactionally — failure resumes from the last commit, not from zero.*
Three consequences worth understanding.
**Ordering is not a problem.** V1 and V2 both read the same events from the same store in the same order. The fact that V2 reads them later does not change what V2 sees. Both arrive at the same read-model state for the same input — V2 just gets there on a delay.
**Failure during backfill is not catastrophic.** Each batch commits position transactionally with the projection writes. If a worker dies mid-batch, the database rolls back the partial writes and the position stays at the last successful commit. Restart the worker and it picks up from there — no manual cleanup, no replay from zero.
It's worth to understand deeper reason for `manualKickOff` being introduced — without it, **deploying V2 would let *any other action* in the system kick the projection into life**: a worker booting up, an incoming event, a scheduled trigger. For a globally tracked projection that has to catch up on millions of events, that is exactly what you do not want. An async projection coming up unexpectedly can monopolise its queue for half an hour while it grinds through history, blocking every unrelated message behind it. `manualKickOff: true` makes V2 dormant until *you* decide it is time — initialization, backfill, and going live all become explicit, scheduled actions instead of side effects of a deploy.
## *Backfill — Catching Up a Brand-New Projection*
Backfill populates a brand-new one that has never run before. You deploy a new projection class and need to catch it up with history.
Backfill does catch up projection to very last event
To run backfill we would use console command:
```bash
bin/console ecotone:projection:backfill ticket_list_v2
```
The synchronous backfill reads events from position zero in configurable batches — reusing the same position-tracking mechanism from earlier in this series. After backfill completes, the projection is fully caught up and begins processing new events as they arrive. Simple, predictable, and perfectly fine for smaller event stores.
### Async Backfill with Parallel Workers
For large event stores with millions of events, synchronous backfill may take too long. By setting **asyncChannelName**, the backfill command dispatches messages to a channel instead of processing inline.
```php
#[ProjectionV2('ticket_list_v2')]
#[FromAggregateStream(Ticket::class)]
#[ProjectionBackfill(
backfillPartitionBatchSize: 100,
asyncChannelName: 'backfill_channel'
)]
class TicketListV2Projection
{
// Same handlers as above
}
```
and then we would run backfill as follows:
```bash
# Dispatches backfill messages to the channel
bin/console ecotone:projection:backfill ticket_list_v2
# Start multiple workers for parallel processing
bin/console ecotone:run backfill_channel -vvv
```
And now the backfill will happen in the background.
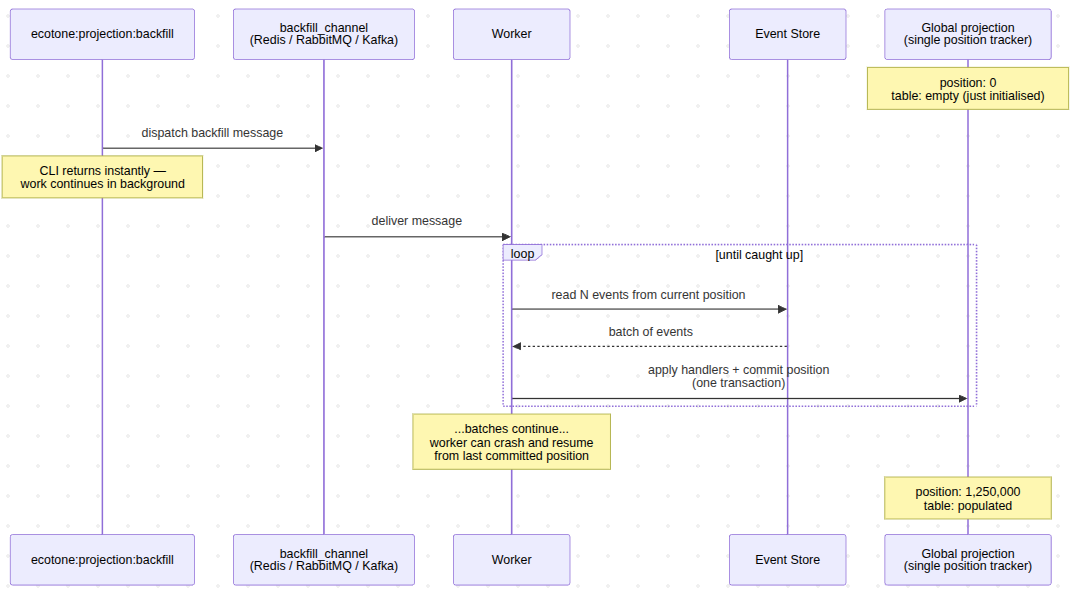
Backfill process happening in the background
We can scale this process even more with partitioned projections, which we will discuss in a moment. But let's now take a look on the whole "*switchover process*".
## The Switchover Workflow
Here is the step-by-step migration.
- **Step 1 — Deploy V2 code** with `#[ProjectionDeployment(manualKickOff: true)]`. Nothing happens on deployment. V1 continues serving traffic normally.
- **Step 2 — Initialize V2.** Create the V2 table:
```bash
bin/console ecotone:projection:init ticket_list_v2
```
*This triggers the `#[ProjectionInitialization]` hook, creating the `ticket_list_v2` table.*
- **Step 3 — Backfill V2.** Populate V2 with all historical events:
```bash
bin/console ecotone:projection:backfill ticket_list_v2
```
- **Step 4 — Compare.** This is the step that earns its keep, and it deserves more than "query both tables." Row counts are a sanity check, not a verification. Real verification looks like this:
- **Step 5 — Set V2 live.** Remove `manualKickOff`, deploy. V2 now processes new events as they arrive, just like any other live projection.
- **Step 6 — Switch traffic.** Update your query handlers to read from `ticket_list_v2`.
- **Step 7 — Delete V1:**
```bash
bin/console ecotone:projection:delete ticket_list_v1
```
*This triggers `#[ProjectionDelete]` which drops the `ticket_list_v1` table and removes its position tracking.*
You may wonder why `manualKickOff` is actually important here, it's crucial from context of globally tracked projections, as those have to go over whole event stream.
This means that we may need to catch hundreds or millions of events, and if such process would be accidentally called for async projection for example, it could block the queue for hours. With this we can run via dedicated CLI or dedicated rebuild channel, to avoid blocking any other parties.
## *Rebuild* — When You Are Confident
Blue-green with two Projections is the safest path, but it is not free. Two tables means double storage during the migration. Backfill means double write throughput. Real verification means dedicated engineering time. When significant changes are made to projection logic, it is safer to use blue-green deployment, but when we are just fixing a bug in handler for example, it is often better to use rebuild.
If you fixed a bug in a handler and you are confident the fix is correct, you do not need to run two projections side by side. You just need to reset and replay.
```bash
bin/console ecotone:projection:rebuild ticket_list
```
*The rebuild command triggers the reset hook, then replays all events from position zero — both wrapped in a single transaction so the projection never observes a half-reset, half-replayed state.*
This calls `#[ProjectionReset]` first, then replays from position zero — and both run inside one transaction. That transactional guarantee is what makes rebuild safe: readers never see a partially-cleared table or a half-replayed state. But the *scope* of that transaction is what decides whether rebuild is viable for your projection.
### Global Projections: Bounded by the Length of One Transaction
For a global projection, the `#[ProjectionReset]` hook clears the whole table — there is no per-aggregate scoping:
```php
#[ProjectionV2('ticket_list')]
#[FromAggregateStream(Ticket::class)]
class TicketListProjection
{
#[ProjectionReset]
public function reset(#[ProjectionName] string $projectionName): void
{
$this->connection->executeStatement(
"TRUNCATE TABLE {$projectionName}"
);
}
}
```
**Without* *`#[Partitioned]`* *, the reset hook truncates the entire projection table. Ecotone wraps that truncate and the full replay-from-zero in a single transaction.*
The rebuild transaction has to cover the whole table — clear every row, then re-apply every historical event before committing. The projection table stays locked for the whole window. Readers either block waiting for the transaction to finish or, depending on isolation level, keep seeing the pre-rebuild data without any of the corrections applied.
For small projections with a few thousand events, the lock is brief enough that this may be perfectly acceptable. For large global projections, the transaction simply will not finish in any reasonable time — use blue-green instead. However for partitioned projections this solution is gold.
### Partitioned Projections: One Aggregate per Transaction
Partitioned projections flip this constraint. Instead of one transaction covering the whole projection, Ecotone scopes the reset-plus-replay transaction to a *single aggregate*. Each partition is rebuilt independently, in its own short-lived transaction, while every other partition continues serving reads normally.
Because a single aggregate's event stream is small — tens or hundreds of events, not millions — each transaction completes quickly without blocking any changes along the way. The total work is the same as a global rebuild, but it is sliced into pieces small enough that no single transaction ever has to hold the whole projection hostage.
The mechanism is the `#[ProjectionReset]` hook receiving `#[PartitionAggregateId]`, so the reset deletes one aggregate's data instead of truncating the table:
```php
#[Partitioned]
#[ProjectionV2('ticket_details')]
#[FromAggregateStream(Ticket::class)]
#[ProjectionRebuild(partitionBatchSize: 50)]
class TicketDetailsProjection
{
#[ProjectionReset]
public function reset(
#[PartitionAggregateId] string $aggregateId
): void {
$this->connection->executeStatement(
'DELETE FROM ticket_details WHERE ticket_id = ?',
[$aggregateId]
);
}
}
```
*The reset hook is partition-aware — it deletes one aggregate's rows. Ecotone wraps that delete and the subsequent replay of the aggregate's events in a single transaction, then moves to the next aggregate.*
There is a second non-obvious win that matters even more under failure. If one aggregate fails unrecoverably during rebuild — a handler bug specific to that aggregate's event sequence, a corrupted snapshot, a constraint violation no other partition would hit — only *that* partition is blocked. The rest of the rebuild keeps going. You do not lose hours waiting for manual intervention before the next aggregate can be processed. You fix the failing handler (or the data), re-trigger the few partitions that failed, and the rebuild finishes. Compare that to a global rebuild where one bad event at hour eleven means starting over from event zero.
## Scaling Rebuild with Async Workers
So far, partitioned rebuild already gives you short per-aggregate transactions and local failure recovery. But it still runs sequentially — one aggregate after another. For a projection with thousands or millions of aggregates, sequential is still hours of wall-clock time.
This is where `asyncChannelName` enters. Instead of processing partitions inline, Ecotone batches them into messages and dispatches them to a channel. Multiple workers consume the channel in parallel — each pulling a batch, rebuilding the aggregates in it, and committing.
```php
#[ProjectionRebuild(
partitionBatchSize: 50,
asyncChannelName: 'rebuild_channel'
)]
```
*`partitionBatchSize: 50` packs 50 aggregate IDs into each message. `asyncChannelName` ships those messages to a channel rather than processing them in-process. The channel itself is whatever transport you have wired into Ecotone — Redis, RabbitMQ, Kafka, AMQP, SQS — the rebuild does not care which.*
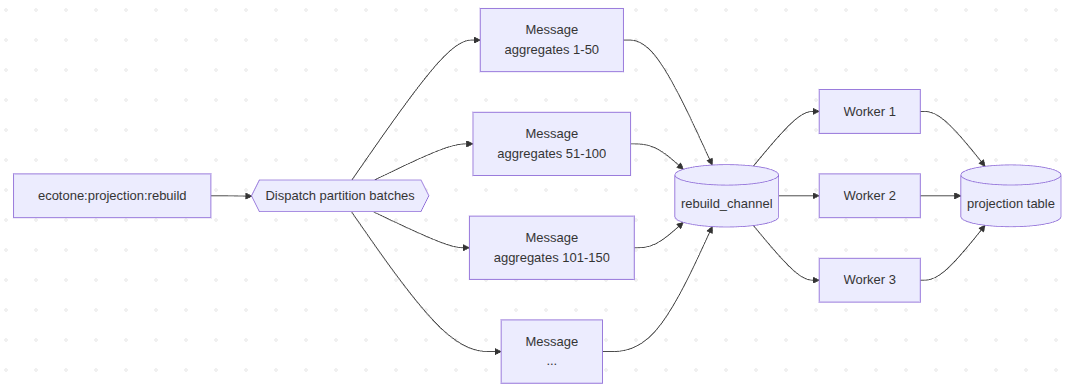
**Each message carries a batch of aggregate IDs to rebuild. Workers pull from the channel in parallel — three workers mean three batches rebuilt at once, each one a string of short per-aggregate transactions.*
With 1,000 aggregates and `partitionBatchSize: 50`, Ecotone dispatches 20 messages. Three workers means three batches in flight at any moment; ten workers means ten. The total work is the same — 1,000 aggregates — but the rebuild finishes in three times less time than sequential.
Of course this scalable solution is not only for rebuild, and can be used for backfill the same way.
## Series Conclusion
The promise of event sourcing has always been simple: your read model is just a function of your events. In practice that promise only holds if replay is cheap enough to actually run — otherwise teams quietly patch tables, batch changes into rebuild windows, and the foundation erodes one workaround at a time. The work across this series was about closing that gap. Once replay becomes a normal operation instead of a calendar event, projections finally behave like what they were always supposed to be: a view of your events you can throw away and rebuild on the same afternoon you find the bug.
That is the bar we built ProjectionV2 to clear. Pick the strategy that fits your change, ship the fix, and move on with the rest of your day.
That was the last article in the series on Ecotone's Projection System. Across the five parts we went deep — not just over the surface of `#[ProjectionV2]`, `#[Partitioned]`, `#[ProjectionDeployment]`, `#[ProjectionBackfill]`, but underneath them, into the mechanisms those declarative attributes are quietly orchestrating: position tracking, batch transactions, per-partition scoping, channel dispatch, lifecycle hooks.
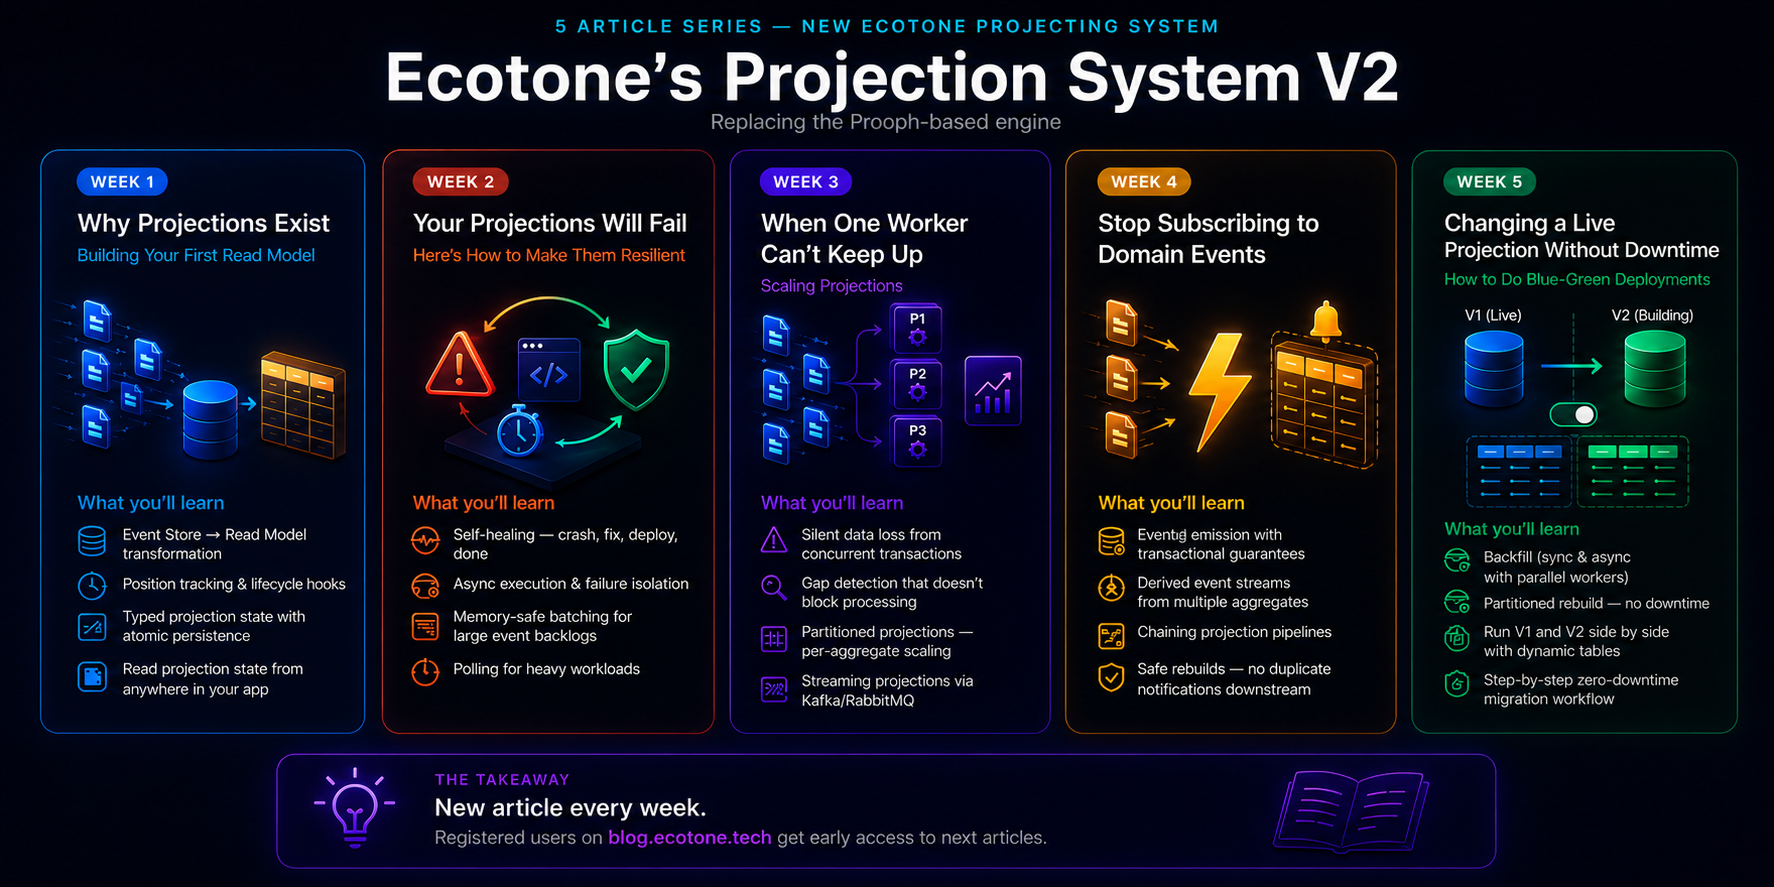
Take a look on the past articles to explore given areas of Ecotone's projecting system
The aim of sharing those was to get people familar with different practices and solutions we've applied to Ecotone, and to show that those can actually be straight-forward to work with. I hope you've enjoyed the reading, and that you feel more confident now into using Event Sourcing in production ready systems.
### Stop Subscribing to Domain Events
URL: https://blog.ecotone.tech/stop-subscribing-to-domain-events/
Last updated: 2026-05-06T08:02:44.000Z
You have a wallet balance projection. It listens to `MoneyWasAdded` and `MoneyWasWithdrawn`, computes the current balance, and writes it to a read model table. A notification service pushes a WebSocket update whenever a user's balance changes.
But are you sure, that once your Event Subscriber was triggered to fetch the balance and send it over websocket it will actually be valid one?
## The Race Condition Nobody Warns You About
So what would be the obvious approach to trigger action when we want to react on Event: subscribe the notification service to the same domain events the projection uses. `MoneyWasAdded` fires, the notification service picks it up, sends a push to the user's browser.
The user sees the notification. They tap it. The page refreshes.
And shows the **old balance**.
The notification arrived before the projection finished updating the read model. The user is now staring at a number that contradicts the message they just received. They refresh again. Still old. They refresh a third time — now it is correct.
It gets worse when we need to send notification (email, sms, mail etc) which includes the actual balance. The notification service does not have the computed value — it only has the raw event saying money was added. So it reaches for data from Projection Read Model, which is not yet up to date. Sending outdated balance to the Customer.
So solve that we may reach for different workarounds:
**Version the read model and retry.** Stamp each row with a version, attach the same version to the notification event, and have consumers retry until the read model has caught up. The race is gone — but every notification now triggers a retry loop hitting the database, and most of those reads are wasted because the projection has not finished yet. You have not removed the polling, you have moved it out of the timer and into the consumer.
**Make projections synchronous.** Update every read model in the same transaction as the command. The user always sees fresh data. But every projection is now on the critical path of every write. Action latency grows with each projection you add — and it keeps growing, because new projections keep landing. Worse, a slow or failing projection blocks writes entirely. The isolation between read and write models is gone, and that isolation was the reason you separated them in the first place.
**Enrich the events.** Pack the projected fields into the domain event itself, so subscribers do not need to load anything. Now `MoneyWasAdded` carries the new balance, the user's tier, and whatever else current consumers happen to need. Every new subscriber adds new requirements. Events grow until they are no longer events — they stop describing what happened in the domain and start describing what consumers want to know. And what if we calculate the balance wrong, now we have wrong balance in the Event Stream.
The above solutions will work to some degree, each will bring it's own pains, but still it's good to have those in your toolkit - as no architecture is ideal. However in this article we won't be focusing on workarounds, and we will take a look different approach which is not so well known to solve this problem.
So the real problem is not the notification itself. The problem is that your projection computes **derived facts** — and nothing else in your system has access to those facts at the moment they become true.
## Event Emission from Projections
What we actually need is a triggering event that carries the *computed* balance, emitted only after the projection has updated the read model. A derived fact, not a raw domain occurrence.
> The shape of the solution is straightforward: let the projection do its job first, then announce what changed. The domain event arrives, the projection updates the read model, and only then does it emit a derived event for everyone else to react to.

**The projection processes the domain event and updates the read model first. Only after that does it emit a derived event carrying the computed balance — so by the time any consumer sees it, the read model already reflects the new state.*
In Ecotone, you inject `EventStreamEmitter` into your projection's event handlers. After updating the read model, you call `emit()` to publish derived events.
```php
#[ProjectionV2('wallet_balance')]
#[FromAggregateStream(Wallet::class)]
class WalletBalanceProjection
{
public function __construct(
private DocumentStore $documentStore
) {}
#[EventHandler]
public function whenMoneyWasAdded(
MoneyWasAddedToWallet $event,
EventStreamEmitter $emitter
): void {
$wallet = $this->getWalletFor($event->walletId);
$wallet = $wallet->add($event->amount);
$this->saveWallet($wallet);
$emitter->emit([
new WalletBalanceWasChanged(
$event->walletId,
$wallet->currentBalance
)
]);
}
}
```
*The projection updates the read model first, then emits a derived event carrying the computed balance.*
The `emit()` method stores the event in a stream named `project_{projectionName}` — in this case, `project_wallet_balance`. Any service can subscribe to that stream like it would to any other event stream.
> The emitted event must live in the **same storage as the read model**. Push it straight to Kafka or RabbitMQ and the event flies out before the projection commits — the subscriber picks it up, queries the read model, and sees stale data. The same race we set out to fix. The projection's own stream acts as the outbox; a relay can ship events to a broker afterwards.
The race condition from our opening example becomes structurally impossible. When the notification service receives `WalletBalanceWasChanged`, the read model is guaranteed to already reflect that balance.
Subscribing to emitted events works like subscribing to any other event:
```php
class WalletNotificationService
{
#[EventHandler]
public function when(
WalletBalanceWasChanged $event
): void {
// Send WebSocket push — the read model
// is guaranteed to reflect this balance
}
}
```
*The notification service subscribes to the derived event. By the time it fires, the read model already contains the updated balance.*
### The Cost of Per-Event Emission
There is a price tag on the pattern above. Every projected event now does three things: read the current state, write the updated read model, and emit a derived event. That is at least one extra write to the event stream per domain event — on top of the read model update that was already there. At low volume nobody notices, but with higher volume it becomes significant.
Worse, most of those emissions are noise. If a wallet receives twenty `MoneyWasAdded` events in the same batch, do you really want to emit twenty `WalletBalanceWasChanged` events?
This is exactly what `#[ProjectionState]` was built for. Instead of reading and writing the read model on every event, you carry the computed state in memory across the batch and persist it once at the end. Combine that with emission inside `#[ProjectionFlush]` and you announce changes only when there is something worth announcing.
```php
#[Partitioned]
#[ProjectionV2('wallet_balance')]
#[FromAggregateStream(Wallet::class)]
class WalletBalanceProjection
{
#[EventHandler]
public function whenWalletInitialized(
WalletWasInitialized $event,
#[ProjectionState] array $wallet = []
): array {
return [
'walletId' => $event->walletId,
'balance' => 0,
];
}
#[EventHandler]
public function whenMoneyWasAdded(
MoneyWasAddedToWallet $event,
#[ProjectionState] array $wallet
): array {
$wallet['balance'] += $event->amount;
return $wallet;
}
#[ProjectionFlush]
public function flush(
#[ProjectionState] array $wallet,
EventStreamEmitter $emitter
): void {
$this->saveWallet($wallet);
$emitter->emit([
new WalletBalanceWasChanged(
$wallet['walletId'],
$wallet['balance']
)
]);
}
}
```
*Event handlers accumulate state in memory. The flush handler runs once per batch per partition — a single read model write and a single emission, regardless of how many events arrived.*
Twenty events into the same wallet now produce one read model write and one `WalletBalanceWasChanged` event carrying the final balance. The race condition guarantee still holds — flush and emission share the same transaction — but you are no longer paying per-event for it.
> Notice there is **no read from the read model** anywhere in this projection. Ecotone carries the state for you between events and persists it on flush. You decide whether to emit based on the state you already have in memory — no `getWalletFor()`, no extra query just to figure out what changed.
### What Happens When You Rebuild
Say your wallet balance projection has been running for two years. Millions of events processed, millions of `WalletBalanceWasChanged` events emitted. Downstream consumers — notifications, compliance checks, analytics — have processed all of them.
Now you need to rebuild. Maybe you added a new field to the read model. You reset the projection and replay from the beginning.
Without suppression, every single historical event gets re-emitted. Your notification service sends two years of balance change alerts to every user. Your compliance system re-triggers every check it has already completed. Your analytics pipeline double-counts everything.
Ecotone prevents this automatically. **During a rebuild, emitted events are suppressed.** The projection replays and reconstructs its read model, but `emit()` calls produce nothing. Once the rebuild catches up to the live stream, emission resumes normally. No duplicate notifications. No phantom events flooding downstream consumers.
> This is a key difference from using the `EventBus` directly — the `EventBus` would happily republish every event during replay. The `EventStreamEmitter` knows the difference between "processing historical events" and "processing new events," and only emits for the latter.
## Remapping into New Event Streams
Raw event streams are fine-grained. Each aggregate produces its own stream of domain events: `OrderWasPlaced`, `PaymentWasReceived`, `ShipmentWasDispatched`. But downstream consumers rarely want that granularity. They want to know: "Is this order fully completed?"
That answer requires correlating events from Order, Payment, and Shipping aggregates. A projection is the natural place to do that correlation — subscribe to multiple streams, accumulate state in `#[ProjectionState]`, and emit a single derived event from `#[ProjectionFlush]` once all conditions are met.
```php
#[ProjectionV2('order_lifecycle')]
#[FromAggregateStream(Order::class)]
#[FromAggregateStream(Payment::class)]
#[FromAggregateStream(Shipment::class)]
class OrderLifecycleProjection
{
#[EventHandler]
public function whenOrderPlaced(
OrderWasPlaced $event,
#[ProjectionState] array $order = []
): array {
return [
'orderId' => $event->orderId,
'ordered' => true,
'paid' => false,
'shipped' => false,
];
}
#[EventHandler]
public function whenPaymentReceived(
PaymentWasReceived $event,
#[ProjectionState] array $order
): array {
$order['paid'] = true;
return $order;
}
#[EventHandler]
public function whenShipped(
ShipmentWasDispatched $event,
#[ProjectionState] array $order
): array {
$order['shipped'] = true;
return $order;
}
#[ProjectionFlush]
public function flush(
#[ProjectionState] array $order,
EventStreamEmitter $emitter
): void {
if ($order['ordered']
&& $order['paid']
&& $order['shipped']
) {
$emitter->linkTo('completed_orders', [
new OrderFullyCompleted($order['orderId'])
]);
}
}
}
```
*Each order's progress accumulates in `#[ProjectionState]` as events arrive across the three aggregates. No `trackStep()`, no `allStepsComplete()`, no helper to duplicate across handlers — the state is right there in memory. `#[ProjectionFlush]` checks once per batch and writes a single `OrderFullyCompleted` into the `completed_orders` stream when the order is done.*
Notice the switch from `emit()` to `linkTo('completed_orders', ...)`. The `EventStreamEmitter` interface offers both: `emit()` writes to the projection's own stream (`project_{name}`), while `linkTo()` writes to any stream name you choose. Same transactional guarantee, same rebuild suppression — just a stream you name yourself. Instead of dropping the derived event into the projection's own stream, we are publishing it under a name we chose deliberately. The projection becomes an **event translator** — converting low-level domain events from three aggregates into a single high-level business fact, written to a stream that describes what it contains rather than where it came from.
That naming choice is what turns this into a high-level abstraction. You can build a stream of "the things our business considers important" — `completed_orders`, `cancelled_subscriptions`, `kyc_approved_customers` — and feed each one from whatever combination of raw aggregates and projections it takes to compute. Consumers do not see the choreography. They see facts.
This is also where the design starts paying off across team boundaries. Streams like `completed_orders` do not have to be consumed by your own code at all — they can become the **public API** other teams build on. The reporting team subscribes to it for their dashboards. Finance ingests it into the books. A data pipeline pulls it into the warehouse. None of them need to know that an order is currently spread across three aggregates with their own internal vocabularies, and none of them break when you split, merge, or rename those aggregates tomorrow.
> Your domain events stay where they belong — internal to the bounded context that produces them, free to evolve as the domain evolves. The `completed_orders` stream becomes the contract you maintain for the outside world: stable, intention-revealing, and decoupled from the implementation behind it.
## Sharing Events Across Applications
The same mechanism extends across application boundaries. Another application — a billing system, a fraud-detection service, a CRM — wants to react when an order is fully completed. It runs in its own process, owns its own database, and has no business calling into yours to ask for details.
If all you publish is an order ID, every consuming application has to call back to fetch the rest. That couples them to your HTTP API, your read model schema, and your availability — exactly the boundaries event-driven integration was supposed to avoid. So the published event needs to carry enough for a remote application to act on its own.
By the time `#[ProjectionFlush]` runs, the projection has everything it could need: the order ID from the placed event, the amount and currency from the payment event, the carrier and timestamp from the shipment event. Pack what the contract requires into the published event, and let your domain events stay terse.
```php
#[ProjectionFlush]
public function flush(
#[ProjectionState] array $order,
EventStreamEmitter $emitter
): void {
if ($order['ordered']
&& $order['paid']
&& $order['shipped']
) {
$emitter->linkTo('completed_orders', [
new OrderFullyCompleted(
orderId: $order['orderId'],
customerId: $order['customerId'],
totalAmount: $order['totalAmount'],
currency: $order['currency'],
paidAt: $order['paidAt'],
shippedAt: $order['shippedAt'],
carrier: $order['carrier'],
)
]);
}
}
```
*The published `OrderFullyCompleted` carries everything a remote application needs to act on the order without calling back into your system. The domain events that fed the projection — `OrderWasPlaced`, `PaymentWasReceived`, `ShipmentWasDispatched` — stay focused on diffs.*
This is the same idea as the "enrich the events" workaround from the opening of the article — except aimed at the right target. Enriching domain events was a bad idea because it pulled subscribers into your internal schema and forced events to grow to fit consumers you had not even met yet. Enriching a published stream is the opposite move: you decide what the contract carries, you control how it evolves, and the domain events behind it stay clean.
End to end, you now have a real boundary:
- **Internal domain events** — crisp, diff-shaped, describing what changed inside an aggregate.
- **Projections** — correlate across aggregates, accumulate state, compute derived facts.
- **Public streams** — `completed_orders`, `kyc_approved_customers`, `cancelled_subscriptions` — carrying everything an outside application needs to act.
A billing application subscribes for invoicing. A fraud service subscribes to flag suspicious patterns. A partner integration relays the event downstream. Each one acts on the data in the event itself, never querying your read models, never depending on your aggregate shapes, never blocking your domain from evolving. Your application stays isolated. Theirs stay self-sufficient.
## Derived Streams as Input for Other Projections
Once projections emit events, you can chain them. Projection A reads from aggregate streams and emits derived events. Projection B subscribes to A's output stream and builds further derived views.
Picture a pipeline: raw domain events flow into a `wallet_balance` projection, which emits `WalletBalanceWasChanged`. A `high_value_wallets` projection subscribes to that stream and maintains a list of wallets above a threshold. A `risk_assessment` projection subscribes to the high-value list changes and triggers compliance checks.

**Each projection in the chain consumes events and produces derived facts that feed the next stage*
The natural concern: is this fragile? If the middle projection fails, does the whole pipeline collapse?
No — and this is where the foundations from earlier articles pay off. Each projection in the chain is independently resumable through position tracking. Each is independently recoverable through self-healing. Each can be independently scaled through partitioning.
A failure in one projection pauses its downstream consumers. But when it recovers, it catches up from where it stopped, and the downstream projections resume automatically. No manual intervention. No coordinated restart sequence. The chain is **resilient by construction**, not by accident.
Think of it like a river system. If a dam upstream temporarily stops flow, the downstream lakes do not drain — they simply wait. When the dam reopens, water flows again and every reservoir fills back to where it should be. Each node in the pipeline is autonomous and tracks its own state.
This is where the rebuild suppression from earlier becomes critical again. If you rebuild the `wallet_balance` projection in the middle of this chain, downstream projections do not receive a flood of re-emitted events. The suppression applies at each level independently — you can rebuild any single projection without cascading side effects through the pipeline.
## What Comes Next
Your projections emit derived events, chain into pipelines, feed downstream consumers, and publish enriched streams to other applications.
Along the way we have brushed against the harder operational questions. **Rebuild suppression** stops a replay from flooding downstream consumers with years of re-emitted events. Transactional emission keeps every consumer in lockstep with the read model. But the moment you actually have to evolve a projection in production — add a column derived from the original event, fix a bug in the calculation, change what a field means — none of those guarantees, on their own, tell you how to do it without taking the system down or applying today's logic to yesterday's data.
The next article shows those mechanisms in practice. We will tackle **blue-green deployments for projections** — deploying `ticket_list_v2` next to `ticket_list_v1`, backfilling V2 in the background while V1 keeps serving, comparing both tables, and switching only when V2 is provably correct. Around that, we will look at how `#[ProjectionName]` lets a single class power both versions writing to different tables, how `#[ProjectionDeployment]` keeps the new projection dormant until you say go, how **partitioned rebuilds** clear and recompute one aggregate at a time so the read model stays available, and how **async backfill with parallel workers** turns an overnight replay into a coffee break.
In short - Evolving live projections without breaking the consumers that depend on them — that is the next piece.
### When One Worker Can't Keep Up: Scaling Projections
URL: https://blog.ecotone.tech/when-one-worker-cant-keep-up-scaling-projections/
Last updated: 2026-04-29T06:19:13.000Z
Scaling event sourcing projections isn't just about adding workers. The first problem you hit when moving from "one request at a time" to "many in parallel" isn't throughput — it's correctness. And the way you solve it is itself your first scaling decision: the choice directly sets your scaling ceiling.
The problem of concurrent writes may lead to projection losing an event with: No error. No log entry. No exception. The read model will be permanently wrong, and you will not find out until someones reports the problem.
Simple event sourcing libraries and home-built solutions often have no awareness of this problem. The projection logic looks correct in development — because your dev environment runs one request at a time. It is only under production concurrency that events start silently disappearing.
This connects directly to scalability. The decision on how to solve this problem shapes how your projections will scale – which is why we need to discuss it first.
## How Global Tracking Projections Work
A **global tracking projection** reads from a single ordered log – your Event Store stream. That stream contains every event written, regardless of which aggregate produced it. Tickets, Orders, Users, Payments – all interleaved into one sequence.
Each event gets a unique, monotonically increasing **sequence number** the moment it is appended. The projection's job is straightforward:
1. Read the next batch of events after its last known position
2. For each event, run any matching handlers
3. Store the new position -- the highest sequence number processed
On the next run, it picks up where it left off.
**One log, many aggregates, monotonically increasing sequence numbers. The projection tracks a single position across the entire stream.*
This model is simple and works perfectly – when one process writes events at a time. It is what most tutorials show. Then production hits, and concurrent writes happen.
## The Concurrent Transaction Problem
Two users register tickets at the same time. Two database transactions start in parallel:
1. **TX1** writes an event for Ticket-A. The database assigns it **position 10**. TX1 is doing extra work -- a constraint check, a trigger -- and has not committed yet.
2. **TX2** writes an event for Ticket-B. The database assigns it **position 11**. TX2 commits immediately.
3. **The projection runs.** It queries the Event Store for events after position 9\. It sees position 11 -- TX2's event is visible. But position 10 is invisible. TX1 has not committed. The row exists but is locked inside an uncommitted transaction.
4. The projection processes event 11 and advances its position to 11.
5. **TX1 finally commits.** Event 10 is now visible. But the projection already moved past it. It will never go back.
Event 10 is lost. Silently. Your read model is permanently inconsistent with your Event Store. The projection skipped an event because it was not visible at the exact moment the query ran. All of your SELECTs against that read model are now broken – and they will stay broken.
**TX1's slow commit creates an invisible event — the projection skips position 10 permanently*
Under concurrent writes, this is guaranteed to happen. The only question is how your system handles it when it does.
## Gap Detection
Three approaches exist in the ecosystem. Two are common. One actually solves the problem fundamentally.
### No Gap Detection
Ignore it. The projection reads visible events, advances its position, moves on. Invisible events are permanently skipped. **Silent data loss.** Your read model diverges from the Event Store with no error, no log entry, nothing. Teams discover it months later when a customer reports a wrong balance -- and the only solution is to rebuild the projection from scratch.
This often happens from lack of awareness about the problem focusing only on the happy path, and you would be suprised how many event sourcing libraries have this as their default behavior.
### Time-Based Blocking
When the projection detects a gap, it **stops and waits** until the gap fills or a timeout expires. This blocks **all progress** – every event behind the gap waits, even from unrelated events.
Waiting for gaps to become visible
Time-Based blocking can be implemented using two approaches generic on the code level with a time delay, or on database feature based on transaction visibility. This feature may however becomes problematic in high concurrency scenarios, as each Projection will be waiting for the gaps to fill - **even if waiting for Events which are not even relevant to the projection.**
Blocking is **stream-wide**, not handler-aware. A Ticket projection will block on a slow Order transaction it doesn't even subscribe to.
> *Time-based blocking waits even for events the projection doesn't subscribe to — a slow Order transaction stalls projections which subscribe do different events*
### Database-Level Write Locking
A different angle on the same problem: instead of detecting gaps after they happen, prevent them from ever existing. Use a database-wide advisory lock so only one transaction can write to the Event Store at a time.
If only one transaction writes at a time, gaps are structurally impossible. The auto-increment column advances contiguously. Projections never need to detect anything – they just read in order.
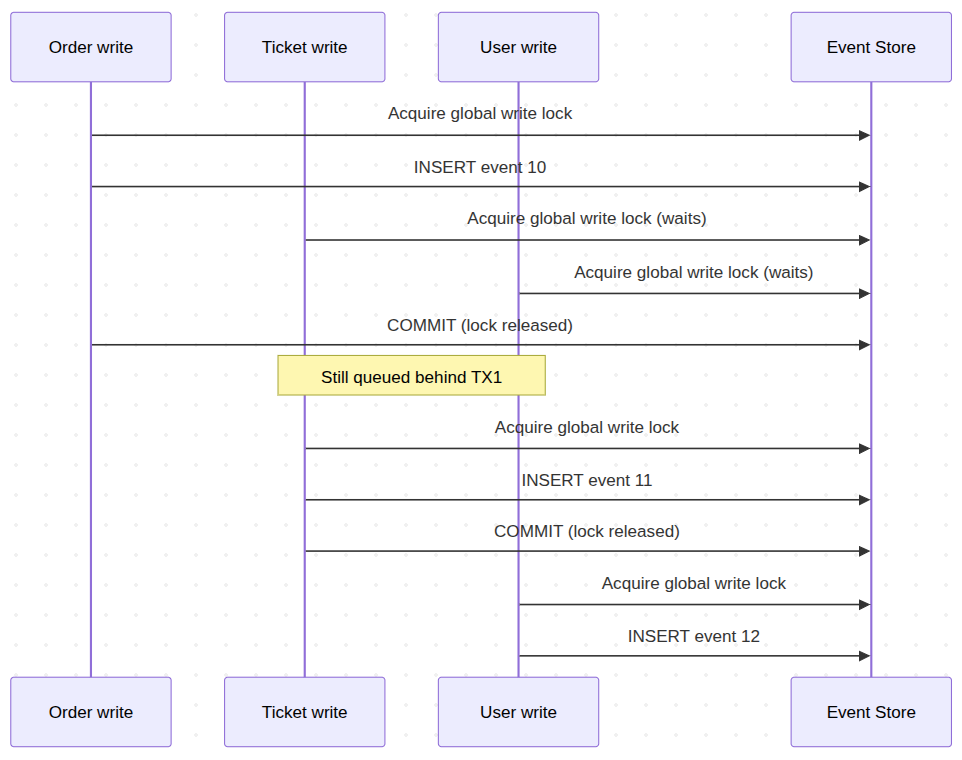
Three unrelated aggregates -- Order, Ticket, User -- serialise on the same global lock. Only one can write at a time, regardless of whether they have anything to do with each other.
This works correctly. Gaps cannot happen, projections never need to detect anything, no special infrastructure is required.
> With this approach each transaction has to wait for another to finish - and with more load, more transactions will be hanging. We basically solved down our write side, because of the problems on the read side. The worst part if we've traded-off failure isolation, as right now if one of those transaction will dead-lock, we will basically bring down all the other.
### Track-Based Non-Blocking (Ecotone's Approach)
Ecotone **records** the gap and keeps making progress.
When the projection sees position 11 but not position 10, it processes event 11 and stores its position in a compact format:
```text
"11:10"
```
*Position format: "current position : known gaps" – the projection is at position 11 with a recorded gap at 10*
This means: "I have processed up to position 11, but position 10 is a known gap." On the next run, the projection checks its gap list first. If TX1 has committed and event 10 is now visible, it processes event 10 and removes it from the gap list. If still missing, the gap stays and the projection continues processing new events.
Multiple concurrent gaps are tracked as a comma-separated list:
```text
"15:10,12,14"
```
*Multiple gaps tracked simultaneously – the projection is at position 15 with gaps at 10, 12, and 14*
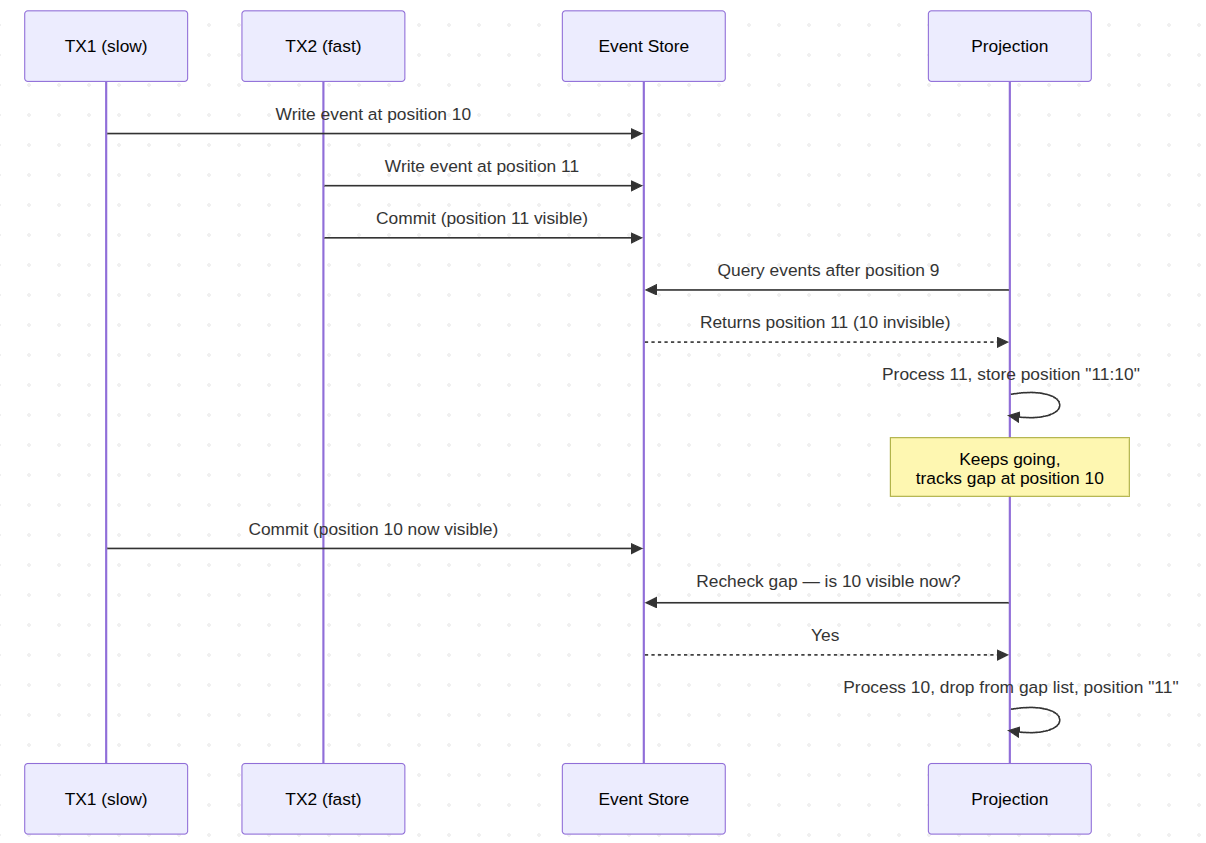
Track-based non-blocking: the projection records the gap, keeps moving forward, and revisits the gap on the next pass
The projection **never blocks**. It makes continuous forward progress on available events while maintaining positions to revisit. Gaps resolve naturally as slow transactions commit – in practice, within milliseconds.
### Gap Cleanup
Not every gap will be filled. A rolled-back transaction leaves a permanently empty position. Ecotone cleans up stale gaps with two strategies:
- **Offset-based cleanup**: gaps more than N positions behind the current position are removed. If your projection is at position 10,000, a gap at position 50 is not a pending transaction -- it is a permanent hole.
- **Timeout-based cleanup**: gaps older than a configured threshold are removed. A gap that has existed for minutes is not a slow transaction. It is a rollback.
Both strategies keep the gap list bounded, even under sustained concurrent writes.
## Partitioned Projections
Gap detection is a workaround for a problem caused by interleaving. Events from different aggregates share one global sequence – and concurrent writes across them are what creates the gaps in the first place. Within a single aggregate, gaps cannot happen at all: the Event Store's optimistic locking guarantees strict version ordering. So we can sidestep the entire problem by tracking each aggregate independently.
To see why this is possible, look at what is actually inside the stream. Every event carries two identifiers beyond its global sequence number: an **aggregate\_id** (which aggregate it belongs to) and an **aggregate\_version** (its position within that aggregate's own history). The global sequence is shared across everything, but the (aggregate\_id, version) pairs form natural partitions inside the same stream.
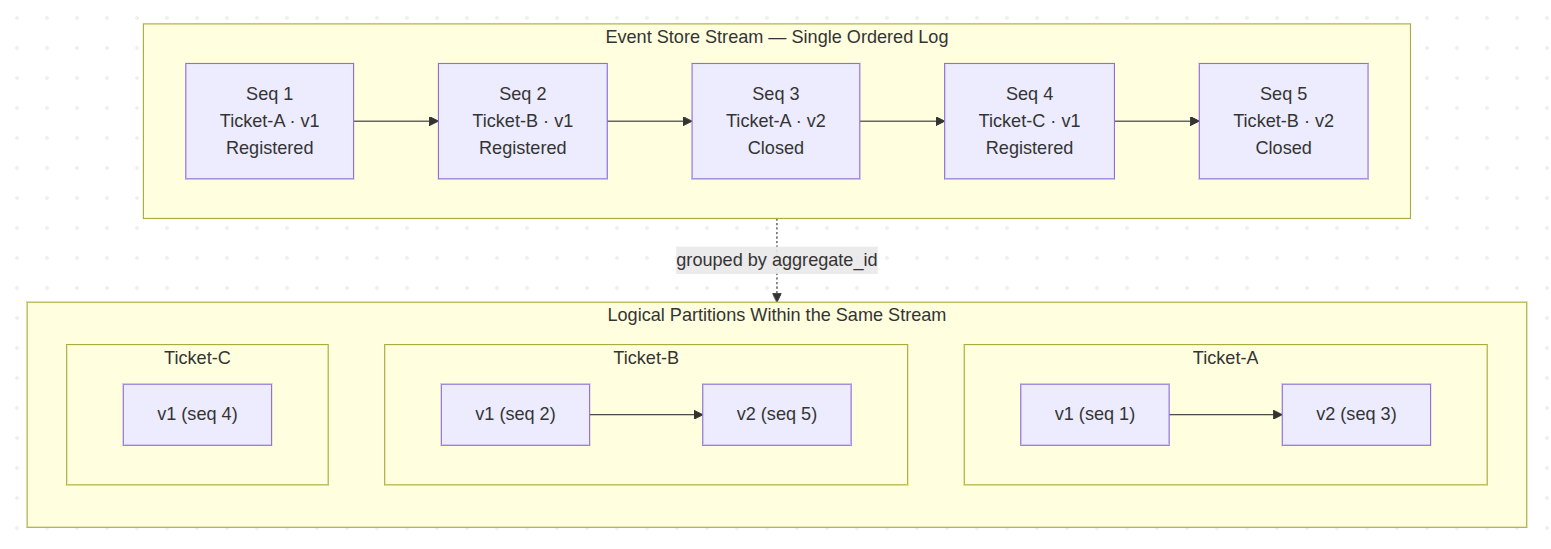
**Same physical stream, two views: globally sequenced events (top) form independent partitions when grouped by aggregate\_id (bottom). Each aggregate's version sequence is monotonic and gap-free.*
A partitioned projection stops tracking the global sequence number. Instead, it keeps one position per aggregate\_id – the aggregate\_version of the last event it processed for that aggregate. There is no shared cursor for workers to fight over.
```php
#[Partitioned]
#[ProjectionV2('ticket_list')]
#[FromAggregateStream(Ticket::class)]
class TicketListProjection
{
public function __construct(private Connection $connection) {}
#[EventHandler]
public function onTicketRegistered(TicketWasRegistered $event): void
{
$this->connection->insert('ticket_list', [
'ticket_id' => $event->ticketId,
'ticket_type' => $event->type,
'status' => 'open',
]);
}
#[EventHandler]
public function onTicketClosed(TicketWasClosed $event): void
{
$this->connection->update(
'ticket_list',
['status' => 'closed'],
['ticket_id' => $event->ticketId]
);
}
}
```
*In Ecotone Framework adding #\[Partitioned\] describes that projection should track position per aggregate id – each aggregate instance gets its own position tracker*
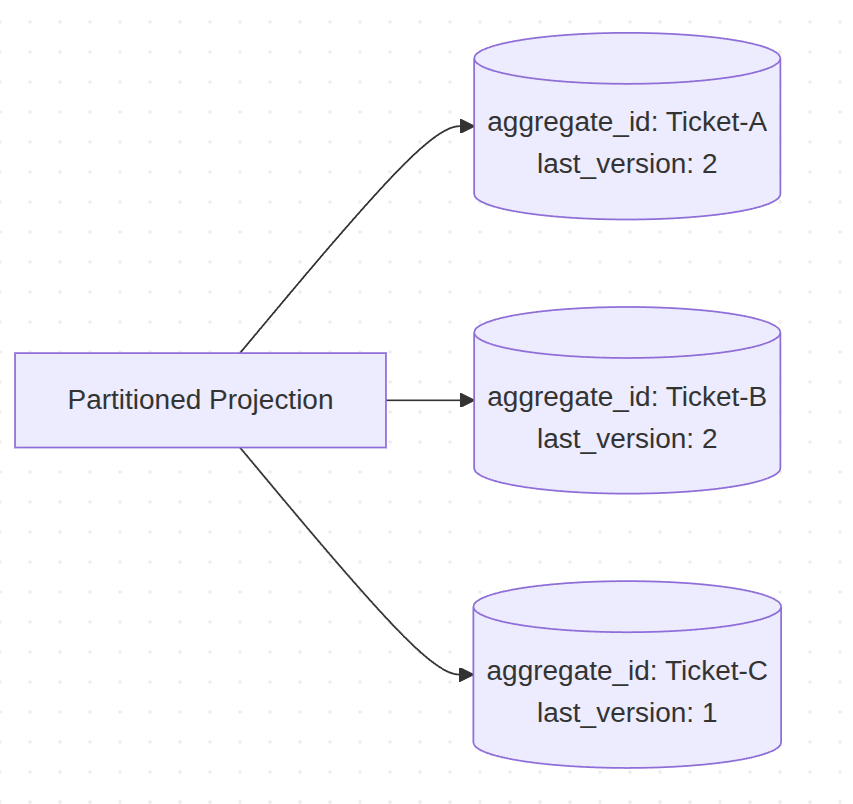
**One projection, one tracker per aggregate\_id – each holding the last aggregate\_version processed for that aggregate. New aggregates simply add new trackers.*
Here is the key insight: **partitioned projections do not need gap detection at all**. There are no concurrent writes to the same aggregate -- the Event Store prevents it at the database level. Two transactions writing to the same aggregate? One fails and has to retry - meaning no gaps.
Gaps only occur when events from **different aggregates** interleave in a global stream. Within a partition, the sequence is always strictly ordered: version 1, version 2, version 3\. The entire class of problems that gap detection solves simply does not exist here.
## Filtering Power
Eliminating gaps does not only simplify correctness -- it unlocks an optimization that global projections fundamentally cannot use: **filtering events at the database**.
A global projection has to fetch every event in the stream, even ones its handlers do not care about. The reason is gap detection. Filter at the database query -- "only give me TicketRegistered and TicketClosed" -- and the projection loses the ability to tell gaps apart from filtered-out events. A missing sequence number could be a slow transaction creating a real gap to track, or it could be an OrderShipped event that was correctly excluded by the filter. The two cases are indistinguishable. So global projections fetch the full firehose and discard the irrelevant events at runtime.
Partitioned projections do not need to detect gaps. Versions within an aggregate are strictly ordered -- there is nothing to detect. That removes the constraint, and Ecotone uses it automatically: it inspects the projection's `#[EventHandler]` methods, derives the subscribed event types, and pushes that filter down into the Event Store query.
```sql
-- Global projection: must fetch every event
SELECT * FROM events WHERE sequence > :last_position;
-- Partitioned projection: filter to only subscribed events
SELECT * FROM events
WHERE sequence > :last_position
AND event_type IN ('TicketRegistered', 'TicketClosed');
```
*Ecotone derives the event\_type filter from the projection's #\[EventHandler\] declarations. The database does the filtering, not PHP.*
The savings compound at scale. Take a 50 million event stream where Ticket events represent 5% of total volume. Twenty times less network I/O. Twenty times less deserialization. Twenty times less memory churn. A backfill that used to read 50 million rows from the database now reads 2.5 million – before any worker parallelism is even applied. On a stream where the projection's events are 1% of total volume, the gap is a hundredfold.
## Scaling Through Partitioning
Per-aggregate position tracking does more than eliminate gaps -- it unlocks horizontal scaling.
A global projection has exactly one position for the entire stream. Adding more workers does not help: only one worker can advance the cursor at a time. Extra workers create lock contention, not throughput.
Global tracked projections, follow whole stream event by event, therefore there are no slices that could scale this process
A partitioned projection has one position per aggregate. Different workers can hold different aggregates simultaneously, with no shared state between them. Worker 1 advances Ticket-A's position. Worker 2 advances Ticket-B's. They never touch each other's data.
**Partitioned: parallel lanes, each worker can handle it's own partition concurrently*
Throughput scales with worker count – up to the number of distinct aggregates being written to. A system with thousands of active tickets and 8 workers will see roughly 8x the projection throughput of a single-worker setup. Add more workers, process more partitions in parallel.
This matters most when you deploy a **new projection** against a stream that already has years of history. Backfilling a fresh read model from scratch is the worst-case scaling scenario: there is no live trickle to keep up with -- there is a mountain of historical events waiting to be processed before the projection is usable. With a global projection, that mountain is climbed by a single worker, sequentially, regardless of how much hardware you throw at it. A stream with hundreds of millions of events can take **days** to catch up.
With partitioning, you can spin up dozens of workers to chew through different aggregates in parallel. Rebuild process that took days can take hours. the one that hours can take minutes. The same property that makes live processing scale also collapses backfill time – which is often the difference between "we can deploy this projection on Monday" and "we need a maintenance window and a four-day catch-up plan."
## High-Performance Projections with Flush State
Even with partitioning and filtering, rebuilding a read model from millions of historical events is expensive if you commit on every single event. Each commit is a database round-trip, a transaction boundary, index updates. A system processing 500K events per hour can hit memory pressure fast if each event triggers its own write.
The solution: **accumulate state in memory** across a batch and persist it once.
```php
#[Partitioned]
#[ProjectionV2('ticket_list')]
#[FromAggregateStream(Ticket::class)]
#[ProjectionExecution(eventLoadingBatchSize: 1000)]
class TicketListProjection
{
public function __construct(private Connection $connection) {}
#[EventHandler]
public function onTicketRegistered(
TicketWasRegistered $event,
#[ProjectionState] array $ticket = []
): array {
return [
'id' => $event->ticketId,
'status' => 'open',
'version' => 1,
];
}
#[EventHandler]
public function onTicketClosed(
TicketWasClosed $event,
#[ProjectionState] array $ticket = []
): array {
$ticket['status'] = 'closed';
$ticket['version'] = $ticket['version'] + 1;
return $ticket;
}
#[ProjectionFlush]
public function flush(#[ProjectionState] array $ticket = []): void
{
if (empty($ticket)) {
return;
}
if ($ticket['version'] === 1) {
$this->connection->insert('ticket_list', [
'ticket_id' => $ticket['id'],
'status' => $ticket['status'],
'version' => $ticket['version'],
]);
} else {
$this->connection->update(
'ticket_list',
['status' => $ticket['status'], 'version' => $ticket['version']],
['ticket_id' => $ticket['id']]
);
}
}
}
```
*Per-partition state: each ticket's events accumulate into a single ticket record (id, status, version). #\[ProjectionFlush\] persists once per batch -- version 1 means a freshly registered ticket (INSERT), anything higher is an existing ticket being updated.*
Because the projection is `#[Partitioned]`, the `#[ProjectionState]` is **per aggregate** \-- one ticket's state, not a global aggregator. Each `#[EventHandler]` receives the current ticket and returns its updated form. No database writes happen during event handling. After each batch, Ecotone calls `#[ProjectionFlush]` once per partition with the final accumulated ticket state -- a single INSERT or UPDATE per ticket.
For a ticket that goes through registration, three status changes, and closure -- five events -- you get one database write instead of five. Across a backfill of millions of tickets, that compounds.
Combined with partitioning: parallel workers, each driving their own aggregate's lifecycle through memory and persisting only the final state per batch.
## Use the Database Only When Needed
A traditional global projection runs on a schedule. Every few seconds it polls: "any new events?" Most of the time the answer is no, and the query was wasted -- a scan over an empty range, a position read, a position write. Multiply that across dozens of projections, all polling continuously, and the database is being pushed *just to confirm there is nothing to do*.
Partitioned projections in Ecotone work differently. A projection is triggered by **activity**, not by a clock -- and only on the partitions that actually had activity.
**Synchronous (inline) projections** run as part of the same transaction that persists the event. The aggregate writes its event, the projection updates the read model, both commit together -- no polling worker, no separate process, no idle queries. And because each aggregate has its own partition, an inline projection on Ticket-A does not block writes happening on Ticket-B at the same moment. Other aggregates flow freely.
**Asynchronous partitioned projections** decouple the projection from the write path. The aggregate appends its event and returns immediately. Ecotone delivers that event to the projection through its messaging infrastructure, once the event happens. Two consequences:
- **Speed**: the write transaction does not wait for the projection. Append latency stays low even if the projection is slow, behind, or temporarily down.
- **Reliability**: a bug in the projection does not poison the event append. The event is safely persisted regardless of what the projection does with it afterwards. You can fix the projection, replay it, and recover -- the source of truth was never at risk.
But in context of scalability - the most importantly, the projection is **woken by the event itself**.
**The event is pushed to the projection through a message channel the moment it is appended. The aggregate\_id rides along to route the work to the correct partition.*
On append, the Event Store publishes a trigger to the channel. The channel wakes the projection, which then pulls the events for its partition straight from the Event Store. The database is queried only when there is actually something to fetch – never on a timer.
> This is the difference between "ten projections each polling the database every second" and "ten projections that only run when there is something to do." On a system with bursty traffic, the idle cost drops to zero.
The only Events that actually wake up the Projection to pull events from Event Store, are actually the ones that projection subscribes to. A projection that handles two event types out of ten across the system, is woken exactly when those two arrive – never for the other eight. Dispatch is driven by the projection's `#[EventHandler]` declarations, not by a generic "any event" trigger.
The guarantee composes: a projection's database is touched only when one of its subscribed events is actually appended. No subscribed events for an hour? No database queries from that projection for an hour. The projection sits at zero cost until there is real work to do.
## Skipping Deserialization
Every event handler that takes a typed event class -- `TicketWasRegistered $event` – triggers a deserialization step: Ecotone reads the JSON payload from the Event Store and hydrates a PHP object. For a single event, the cost is invisible. For a backfill of fifty million events, it is one of the largest CPU expenses outside of the database itself.
Ecotone supports an alternative: identify the event by its **name** in the `#[EventHandler]` attribute, type-hint the parameter as `array`, and Ecotone hands the raw payload straight to the handler – no class, no reflection, no hydration.
```php
#[Partitioned]
#[ProjectionV2('ticket_list')]
#[FromAggregateStream(Ticket::class)]
class TicketListProjection
{
public function __construct(private Connection $connection) {}
#[EventHandler('ticket.registered')]
public function onTicketRegistered(array $event): void
{
$this->connection->insert('ticket_list', [
'ticket_id' => $event['ticketId'],
'status' => 'open',
'version' => 1,
]);
}
#[EventHandler('ticket.closed')]
public function onTicketClosed(array $event): void
{
$this->connection->update(
'ticket_list',
['status' => 'closed', 'version' => $event['version']],
['ticket_id' => $event['ticketId']]
);
}
}
```
*Events are addressed by their stored name (`ticket.registered`, `ticket.closed`) instead of by PHP class. Ecotone delivers the raw associative array straight from the Event Store with no class deserialization step.*
There is a second reason this matters beyond throughput: **the event class no longer has to exist**. If the domain model has moved on – the original `TicketWasRegistered` class was deleted in a refactor, the aggregate now uses different events – a projection that reads the historical events as arrays will keep working. You do not need to keep dead PHP classes alive just to satisfy a projection. The event name in the Event Store is the only contract that matters.
On a rebuild of tens of millions of events, the deserialization shortcut alone can shave a meaningful slice off total CPU time. Combined with filtering at the database, partitioning across workers, and flush-state batching, it is the last layer of overhead to remove before the projection is bound only by the Event Store's I/O.
## Streaming Projections — Bypassing the Database Entirely
That last bound – the Event Store's I/O – is itself a ceiling. Every event read still goes through the database: a query plan, a network round-trip, position updates persisted back to disk. For the vast majority of systems however, the techniques covered above are enough to limit I/O from the Event Store so that it is no longer a bottleneck. However if you want to avoid any extra load on your Database coming from projections, then you need streaming projections.
**Streaming projections** solve removes database from the read path entirely. In this mode, the projection consumes events from a message broker (Kafka) instead.
```php
#[Streaming('orders_channel')]
#[ProjectionV2('external_orders')]
class ExternalOrdersProjection
{
#[EventHandler]
public function onOrderReceived(
OrderReceived $event
): void {
// Events come from broker, not database
}
}
```
*The `#[Streaming]` attribute replaces `#[FromAggregateStream]`. Events are delivered by the broker when they arrive, they are not fetched from the Database Event Store.*
> Ecotone does **not** manage position state in the database for streaming projections as that would kill the purpose. In this case Kafka tracks consumer offsets, meaning no extra database calls to persist the last processed position.
### Feeding a Streaming Channel from the Event Store
You do not need an external event source. Ecotone provides `EventStreamingChannelAdapter` \-- a bridge that reads from your database Event Store and forwards events to a streaming channel.
```php
#[ServiceContext]
public function eventStoreFeeder(): EventStreamingChannelAdapter
{
return EventStreamingChannelAdapter::create(
streamChannelName: 'product_stream_channel',
endpointId: 'product_stream_feeder',
fromStream: 'product_stream',
);
}
```
*The adapter polls the Event Store and pushes events to the streaming channel. Run it as a background process.*
The feeder is the only process that talks to the database. Once events land in the streaming channel, projections subscribe to that channel and are **pushed** events as they arrive – they never query the Event Store themselves.
**One feeder pulls from the database. The streaming channel fans events out to every subscribed projection – the database sees one reader regardless of how many projections exist.*
```bash
bin/console ecotone:run product_stream_feeder -vvv
# Start any number of streaming projections — each is push-driven by the channel
bin/console ecotone:run product_catalog -vvv
bin/console ecotone:run product_search_index -vvv
bin/console ecotone:run product_pricing -vvv
bin/console ecotone:run product_inventory -vvv
```
For the overwhelming majority of systems, you will never need to reach this far. Partitioning, filtering, flush state, and event-driven dispatch handle the workloads that real applications actually encounter.
The value of having streaming as an option is not that you will use it tomorrow – it is that the foundation you are building today does not have to be torn down if you ever do. Same projection class, same event handlers, same partitioned read model: a single `#[Streaming]` attribute is the only thing that changes when you decide to swap the database for Kafka. No rewrites. No new contracts. No migration plan. One annotation, a different transport underneath.
## What Comes Next
We have solved correctness with gap detection, scaling with partitioning, batching with flush state, idle cost with event-driven dispatch, CPU with array handlers, and database I/O with streaming. The projection itself now performs.
But projections do not live alone. The moment a read model is updated, other parts of the system want to know **when it changes** and **what changed** \-- and that raises three uncomfortable questions:
- **Subscribers see stale state.** A consumer reacts to a domain event -- `MoneyWasAdded` fires, the consumer queries the read model for the new balance -- and gets the *old* one, because the projection has not finished updating yet. Does this mean every projection that anyone reads from has to run synchronously, blocking the write path on every read model update?
- **External teams want to build on your events.** Reporting, compliance, analytics -- another team wants to subscribe to the events you publish and build their own read models from them. Those events instantly become a contract. Every renamed field, restructured aggregate, or split event breaks a downstream service. Are you doomed to either freeze your domain model forever, or coordinate every event change across half the company?
- **Subscribers want more than "what changed".** Raw domain events tell you *that* something happened, not *what the resulting state now is*. A notification service that wants to push the user's new balance does not just need `MoneyWasAdded` \-- it needs the computed balance. So you start enriching every event with state -- balance, status, totals -- inflating each one with whatever any consumer might ever want. Are we really forced to end up with Events describing snapshots of our system?
Each of these has a clean answer that does not require synchronous projections, frozen contracts, or bloated event payloads. And in next article we will look deep into how actually Projections can help us solve these problems, rather than being the cause of them.
### Your Projections Will Fail — Make Them Resilient
URL: https://blog.ecotone.tech/your-projections-will-fail-make-them-resilient/
Last updated: 2026-04-21T07:46:16.000Z
There is a design decision that separates projections that recover from crashes automatically from projections that need manual intervention every time something breaks: does the projection process the event message it received directly, or does it use that message as means to fetch Events from the Event Store?
Simple projection systems process the message directly. If Message is lost, or handled in parallel, there is a big chance the order will be lost, and Read Model will end up being incorrect. To recover we would need to manually reset and replay.
On the other side, Projections that always tracks their current committed position — get self-healing for free. And in this article, I will show what we can build on top of such architecture: async execution, failure isolation, batching, and recovery that does not require manual intervention at 3 AM.
## Each Projection Keeps Its Own Bookmark
Position tracking is the core concept in Event Sourcing projections. Every projection has its own position tracker — a small record that remembers the number of the last event it handled. After it successfully processes an event, the projection
stores the updated position so that next time it runs, it knows where to resume. Keeping and persisting that position is what makes a projection recoverable at all.
The position tracker is per-projection, not global. Three projections reading the same stream will each track their position independently. One might be caught up at event #100\. Another at #87 because it is slower. A third stuck at #42 because it
keeps crashing on a bad event.
Each Projection tracks his own position
When a projection runs, it reads its position, asks the Event Store for everything after it, and processes forward. When it commits, the position advances. If it crashes, the position stays where it was — the events are still in the store, unchanged, waiting.
This per-projection position tracker is the seed for everything that follows. Self-healing works because the projection knows exactly where it stopped. Failure isolation works because each projection fails against its own position, not a shared one. Batching works because the position can be committed every N events instead of every one.
The rest of this article is about what becomes possible once you have that foundation.
## Breaking the Coupling
Let's start by discussing synchronous (often called inline) vs asynchronous Projections. When a projection runs synchronously inside your command handler, everything is coupled. Performance, reliability, failure propagation – all of it.
**Synchronous: the user waits for the projection*
Assume three projections triggered by the same event. One has a bug. In synchronous mode, that one broken read model rolls back the entire command handler transaction. A perfectly valid business operation fails because of a reporting dashboard. The fix is to break the coupling entirely.
Three synchronous atomic Projections
> This gives us immediate consistency, as Projections are always up to the date with Events in Event Store. However consequence of this is lack of failure isolation, as when one Projection fails it roll-backs changes to other Projections and to storing the original Event itself.
Let's consider however what would happen if we would make those Projections Asynchronous.
**Asynchronous: the projection runs in the background after the response*
Take the exact same projection and add one attribute:
```php
#[Asynchronous('projections')]
#[ProjectionV2('ticket_list')]
#[FromAggregateStream(Ticket::class)]
class TicketListProjection
{
public function __construct(private Connection $connection) {}
#[EventHandler]
public function onTicketRegistered(TicketWasRegistered $event): void
{
$this->connection->insert('ticket_list', [
'ticket_id' => $event->ticketId,
'ticket_type' => $event->type,
'status' => 'open',
]);
}
#[EventHandler]
public function onTicketClosed(TicketWasClosed $event): void
{
$this->connection->update(
'ticket_list',
['status' => 'closed'],
['ticket_id' => $event->ticketId]
);
}
}
```
*A standard synchronous projection — the only change to make it async is the #\[Asynchronous\] attribute.*
That is it. The projection code is identical. The lifecycle hooks stay the same. You add `#[Asynchronous('projections')]` and the projection moves from synchronous in-process execution to a background worker. You configure a message channel, start a worker with `bin/console ecotone:run projections`, and the projection processes events in the background.
Now when an event is published, it gets delivered to the message channel. The worker picks it up and triggers the projection. But – and here is that key insight again each projection does receives it's own copy of the Event - and is **being triggered in full isolation**.
in Ecotone - each asynchronous projection is being triggered in full isolation. Failures do not cascade.
> After consuming Event from the Channel, Projection goes to the Event Store and fetches all events starting from its last committed position. The message is just a nudge. "Something happened. Go check."
Now let's discuss in more details what happens within single isolated Projection trigger during failure.
## Self-Healing: To make our lifes easier
Your `TicketListProjection` has been running fine for days, processing events up through position 41\. Then event #42 arrives. A `TicketWasRegistered` with a ticket type that is 30 characters long. Your database column allows 25.
The projection crashes.
The failed batch rolls back. The projection's position stays at 41\. Events #43, #44, #45 keep arriving in the Event Store. Tickets are being created, closed, updated. Business continues. But the trigger messages keep coming into the channel, and every attempt to process fails on event #42\. The retry logic kicks in -- once, twice, three times. Same crash every time.
With the trigger-based approach which reads last successful projection position, recovery is: fix the column to `VARCHAR(100)`, deploy.
The next trigger message arrives or we replay triggering Message from Dead Letter. The projection reads from the Event Store starting at position 41 – its last committed position. Event #42 processes successfully this time. Then #43\. Then #44, #45, and everything else that accumulated overnight. **The projection catches up automatically. No reset command. No backfill script. No data migration. No runbook.**
Projection catches up after failure
*The projection resumes from its last committed position — no manual intervention needed*
> The system can be broken for hours, events kept flowing. And when we are ready recovery will be: fix the code, deploy, done. The Event Store is your source of truth, events are never lost - The projection simply picks up where it left off and continues.
Now let's discuss how smaller batches can ensure our Projection won't crash once we reach certain limit of events.
## Batching: Lock Duration and Memory Are the Real Enemy
You deploy a new projection to a system that already has 500,000 events. The projection starts from position zero. Processing all of that in a single transaction locks your database tables for minutes and accumulates everything in memory. Without clearing state between batches, the process grows unbounded until OOM kills it — especially if you are using ORM, where the EntityManager holds references to every entity it has seen.
Ecotone solves both problems with configurable batch processing. **It automatically flushes and clears the Doctrine Entity Manager** (If we use it) at batch boundaries, preventing memory leaks during long catch-up runs:
```php
#[Asynchronous('projections')]
#[ProjectionV2('ticket_list')]
#[FromAggregateStream(Ticket::class)]
#[ProjectionExecution(eventLoadingBatchSize: 500)]
class TicketListProjection
{
public function __construct(
private EntityManagerInterface $em
) {}
#[EventHandler]
public function onTicketRegistered(TicketWasRegistered $event): void
{
$ticket = new TicketListEntry(
$event->ticketId,
$event->type,
'open'
);
$this->em->persist($ticket);
}
#[EventHandler]
public function onTicketClosed(TicketWasClosed $event): void
{
$ticket = $this->em->find(TicketListEntry::class, $event->ticketId);
$ticket->status = 'closed';
$this->em->persist($ticket);
}
#[ProjectionFlush]
public function flush(): void
{
// add any custom flush logic here (will be called after each batch)
}
}
```
ProjectionExecution states the event loading batch size
*Batch configuration — events are processed 500 at a time. Ecotone flushes and clears the EntityManager between batches automatically.*
> The projection loads 500 events, processes them, flushes the EntityManager, saves its position, and commits. Then the next 500\. For 500,000 events, that is 1,000 small transactions instead of one catastrophic one. The EntityManager is cleared between batches, so memory stays flat regardless of how many events you process.
The failure behavior matters here. Batch 1 (events 1-500) commits successfully. Batch 2 (events 501-1000) fails on event 750\. The entire second batch rolls back. But batch 1 is safe — already committed. On the next run, the projection resumes from event 501\. **Previous batches are never lost.**
This is where batching and self-healing work together. A projection catching up on 500,000 events processes 400,000 successfully across 800 batches. Then it hits a bad event. Without batching, you would lose all progress and start over. With batching, you lose one batch of 500 events. The other 400,000 are committed and safe. Fix the bug, deploy, and the projection picks up from batch 801.
## Polling Projections: The difference
So far we have been discussing Async Event-Driven Projections - which are based on Message Channels. This means we choose whatever Projections should be triggered via RabbitMQ, Redis, Kafka etc.
It's important to understand the difference between Async Projections vs Polling Projections - as polling ones are the most common implementation in simple Event Sourcing libraries.
> **Async Event-Driven Projections are only triggered when there is something to project.** Polling Projections on other hand are running in separate process continuously fetching your database for Events - event if there are none.
The difference is that polling generates load on your database - even when not necessary, and async querying Event Store only when there is something to project.
> The second difference is that single Message Channel can be shared between multiple Projections, yet for Polling we are having separate worker process only for given dedicated Projection.
The third difference comes down to what happen in case of failure.
> When failure happen on Async, we may kick off delayed retry or land the triggering Message in the Dead Letter. In case of Polling we will continuously fetch the Event and fail which most likely spam logs and will be wasteful on your system resources.
Considering those differences you may actually ask, whatever Polling Projections make any sense. Polling is simple concept that can be used when no do not want to introduce Message Broker int our stack - as it does fetches the Events directly from the Event Store. Each Projection runs as separate process in this stack, giving the process full resources - which can be useful in heavy projections, that we may want to isolate from other ones.
> If we decide to do Polling we are not locked with the choice. Polling are simple to deploy therefore it could be our first pick, yet once we grow we can decide to switch to Async Projections. It will comes down to switching attribute - Ecotone will take care of projection position - so Projection can continue from last known position.
So assuming that we want to run the Polling Projection:
```php
#[ProjectionV2('heavy_analytics')]
#[FromAggregateStream(Order::class)]
#[Polling('analytics_poller')]
class HeavyAnalyticsProjection
{
#[EventHandler]
public function onOrderPlaced(OrderWasPlaced $event): void
{
// Heavy aggregation logic -- runs in dedicated process
}
}
```
*A polling projection with its own dedicated consumer*
```bash
bin/console ecotone:run analytics_poller -vvv
# Laravel
artisan ecotone:run analytics_poller -vvv
```
Set up is straight-forward, we add polling attribute and we can already run the Projection.
## What Comes Next
Ecotone Projections self-heals, isolates failures, and batches intelligently. For most systems, this is enough. You can go to production with confidence that recovery is a deploy away, and one broken projection cannot take down your command side.
But "most systems" has a ceiling, and you hit it faster than you expect.
- What happens when you have millions of events - will a single position tracker be able to deal with it?
- What when concurrent transactions starts to happen - are you sure your Projections won't skip over an Event?
- What if you need to rebuild large-volume Projection - will it trigger millions of insert and updates on the database?
The next article covers all of the above — the scaling and correctness problems which once solved, will give you confidence that no matter of the scale - you will be able to handle that.
### Why Projections Exist — Your First Read Model
URL: https://blog.ecotone.tech/why-projections-exist-your-first-read-model/
Last updated: 2026-04-16T06:20:37.000Z
Event Sourcing gives you a complete history of everything that happened in your system. What it does not give you is a way to query it.
Sooner or later, someone asks for a list of open tickets or a dashboard showing today's orders — and you realize your append-only event log has no "current state" column. You need a read model. And to build a read model from events, you need a projection.
## The Git Mental Model
Think of it like **Git**. Your Event Store is the **commit history** — every change ever made, in order, immutable. But when you open your IDE, you do not see commits. You see the **working directory** — the current state of all files, derived from that history.
A **projection** is `git checkout`. It takes the commit history and materializes a working directory — a **read model** — that you can actually query. The read model is always a function of the history. And just like `git checkout`, you can rebuild it from scratch at any time.
Different representation of your Events -> Read Model
*The projection continuously transforms the append-only Event Store (commit history) into a queryable Read Model (working directory)*
This analogy goes further. When you add a second read model, you are creating a second working directory from the same commits — a different view of the same truth. When you reset a projection, you clear the working directory and rebuild it from scratch. When you deploy a new projection months after launch, the full event history is there, waiting to be materialized into a fresh read model.
## Your First Projection
Here is how this looks with Ecotone's ProjectionV2\. Two attributes, a few event handlers, and the framework takes care of tracking, initialization, and recovery:
```php
#[ProjectionV2('ticket_list')]
#[FromAggregateStream(Ticket::class)]
class TicketListProjection
{
public function __construct(private Connection $connection) {}
#[EventHandler]
public function onTicketRegistered(TicketWasRegistered $event): void
{
$this->connection->insert('ticket_list', [
'ticket_id' => $event->ticketId,
'ticket_type' => $event->type,
'status' => 'open',
]);
}
#[EventHandler]
public function onTicketClosed(TicketWasClosed $event): void
{
$this->connection->update(
'ticket_list',
['status' => 'closed'],
['ticket_id' => $event->ticketId]
);
}
}
```
*The complete TicketListProjection — event handlers that build the read model*
That is it. No manual subscription, no event bus wiring, no registration. `#[ProjectionV2('ticket_list')]` names the projection. `#[FromAggregateStream(Ticket::class)]` tells it which event stream to read. Ecotone routes events by type-hint — `TicketWasRegistered` goes to `onTicketRegistered`, `TicketWasClosed` goes to `onTicketClosed`. Drop this class in your source directory and Ecotone auto-discovers it through its compiled container — no runtime scanning overhead.
The projection also needs lifecycle hooks — creating its table on first run, cleaning up on delete, clearing data on reset:
```php
#[ProjectionInitialization]
public function init(): void
{
$this->connection->executeStatement(<<connection->executeStatement(
'DROP TABLE IF EXISTS ticket_list'
);
}
#[ProjectionReset]
public function reset(): void
{
$this->connection->executeStatement(
'DELETE FROM ticket_list'
);
}
```
*Lifecycle hooks for initialization, deletion, and reset — the attribute names tell the story*
The `#[ProjectionInitialization]` method runs automatically before the first event is processed. `#[ProjectionDelete]` is a full teardown — drop the table. `#[ProjectionReset]` clears data but keeps the table structure, then the projection replays from the beginning.
## Position Tracking
Each projection stores its last-processed position — a bookmark in the event stream. After a restart, it asks the Event Store: "Give me everything after position 47." No replay from zero, no duplicate processing. Ecotone manages this entirely — you never track offsets yourself.
This means **new projections** are free to deploy at any time. Deploy one six months after launch, and it will build itself from the complete event log — replaying every historical event to construct the read model from scratch. After a failure, the projection resumes from its last committed position. No progress lost.
## CLI Commands
For deployments and debugging, Ecotone provides CLI commands (shown for Symfony — Laravel uses `artisan` instead of `bin/console`):
```bash
bin/console ecotone:projection:init ticket_list
# Delete a projection — drops the table and tracking metadata
bin/console ecotone:projection:delete ticket_list
# Backfill — replay all historical events from the beginning
bin/console ecotone:projection:backfill ticket_list
```
*The three essential projection commands: init, delete, and backfill*
The most common workflow after fixing a projection bug: reset it (clears data, rewinds position), then let the next trigger replay everything. For larger datasets, `backfill` gives you more control.
## Multiple Event Streams
Read models can subscribe to events from multiple aggregates — not just a single aggregate. A calendar overview needs events from both `Calendar` and `Meeting` aggregates. Stack the attributes:
```php
#[ProjectionV2('calendar_overview')]
#[FromAggregateStream(Calendar::class)]
#[FromAggregateStream(Meeting::class)]
class CalendarOverviewProjection
{
#[EventHandler]
public function onCalendarCreated(
CalendarWasCreated $event
): void {
// insert into calendar overview
}
#[EventHandler]
public function onMeetingScheduled(
MeetingWasScheduled $event
): void {
// add meeting to the calendar overview
}
}
```
*A projection that combines events from Calendar and Meeting aggregates into a single read model*
Instead of joining tables at query time, you pre-join as events flow in. The read model is always ready to serve — no joins, no cross-table lookups, because the denormalization happened when the event arrived.
Without projections, you would JOIN `calendars` and `meetings` tables at query time — and every dashboard load pays that cost. With a combined projection, the JOIN happens once, when the event arrives. Every subsequent read is a simple SELECT against a pre-built table.
## Projection State — Where It Gets Interesting
Everything up to this point is the baseline — most projection libraries handle event handlers, lifecycle, and position tracking in some form. The next feature is where Ecotone adds something you would otherwise build yourself: typed projection state with atomic persistence and a gateway for reading it.
Not every projection needs a database table. Sometimes you need a counter, a running total, a summary that accumulates across events. Creating a whole table for a single integer — and writing the repository, the queries, managing the schema — is busywork.
Ecotone solves this with **projection state** — a typed object that is persisted automatically, with no external storage to manage:
```php
final class CounterState
{
public function __construct(
public int $ticketCount = 0,
public int $closedTicketCount = 0,
) {}
}
```
*A simple typed class to hold the projection's internal state*
```php
#[ProjectionV2('ticket_counter')]
#[FromAggregateStream(Ticket::class)]
class TicketCounterProjection
{
const NAME = 'ticket_counter';
#[EventHandler]
public function onRegistered(
TicketWasRegistered $event,
#[ProjectionState] CounterState $state,
): CounterState {
$state->ticketCount += 1;
return $state;
}
#[EventHandler]
public function onClosed(
TicketWasClosed $event,
#[ProjectionState] CounterState $state,
): CounterState {
$state->closedTicketCount += 1;
return $state;
}
}
```
*A stateful projection that counts tickets without needing a database table*
The `#[ProjectionState]` attribute injects the current state. You return the updated state, Ecotone persists it. No repository classes, no manual serialization. The state can be a typed class (as shown) or a plain array — Ecotone handles serialization either way.
But here is the critical part: the state is **saved atomically with the position update**. If the process crashes between two events, the position and state either advance together or not at all. No window where the bookmark moved forward but the counter is stale. No possibility of double-counting after a restart.
With atomic persistence, this entire class of bugs does not exist. The framework handles the transaction boundary so you do not have to think about it.
### The Gateway Pattern
A counter nobody can read is useless. `#[ProjectionStateGateway]` solves this. You define an interface, and Ecotone generates the implementation:
```php
interface CounterStateGateway
{
#[ProjectionStateGateway('ticket_counter')]
public function getCounter(): CounterState;
}
```
*A gateway interface for reading projection state — Ecotone auto-generates the implementation*
This gateway is registered in your dependency container automatically. Inject it into any service, controller, or command handler. Call `getCounter()`. You get a deserialized, typed `CounterState` object back.
No repository classes. No database queries. No glue code. Define the interface, add the attribute, and the framework handles the plumbing. The typed state class means your IDE autocompletes the properties. Your static analysis catches type errors at build time, not at runtime. Your tests can mock the gateway interface like any other dependency.
Compare this to the alternative: create a table, write a repository, add a migration, wire it into your container, write the serialization logic, manage the transaction boundary with the projection position. For a counter. The gateway pattern collapses all of that into an interface with one attribute.
## What Comes Next
There is something I have carefully avoided mentioning. Everything in this article runs **synchronously** — inside the same process, the same HTTP request, as your command handler. Every time a ticket is registered, the projection fires immediately.
Now think about what that means. That first extra projection you add doubles the amount of code that runs inside your write path. Five projections? Five times the work before your API can respond.
What happens when one of those projections is slow? What if it throws an exception — does it roll back the event too? What if your projection writes to the same database in a transaction with your aggregate, and the projection fails halfway through?
These are not hypothetical problems. I have seen teams end up with projection code that is more fragile than the CRUD it replaced — precisely because execution modes were treated as an afterthought. Ecotone treats them as a first-class concept.
Next article: synchronous vs. asynchronous execution, and why getting this choice wrong is worse than not having projections at all.
### DDD Was Never the Problem. Your Rules Were.
URL: https://blog.ecotone.tech/ddd-was-never-the-problem-your-rules-were/
Last updated: 2026-03-30T07:08:25.000Z
There are two versions of Domain Driven Design.
The first one — the one most developers encounter — is a **maze of abstractions**. Separate domain models and persistence models connected by fragile mappers. Application services that do nothing but load, call, save, publish. Interfaces for dependencies that haven't changed in a decade. It's exhausting. It's expensive. And it's the reason "DDD is over-engineering" became a meme.
The second version is the one I discovered after years of building the first. It has fewer files than CRUD. Every line expresses a business rule. **No ceremony, no boilerplate, no layers that exist just to exist.**
If you gave up on DDD because of the first version, I'd like to walk you through the second.
## The Problem Everyone Sees
Search any developer forum for opinions on DDD and you'll find a chorus: "DDD is over-engineering." "It leads to a gazillion classes." "20-50x more code for no reason."
These aren't uninformed takes. They come from developers who tried DDD, followed the rules as taught, and got burned. The problem is real. but it's not DDD that failed them — **it's a specific, dogmatic interpretation that front-loads abstraction, multiplies classes, and delivers complexity without proportional value.**
Let me show you what they actually look like in code, so we can see what we're really dealing with.
### 1\. Creating layers of boilerplate code
My first DDD project followed the rules to the letter. Each layer had to be separate. Each layer had its own data objects. Data was remapped between layers all the way to the Domain. We believed this provided isolation and decoupling.
It provided neither.
Here's what placing an order looked like. Start at the Controller — a Request DTO comes in:
```php
class PlaceOrderRequest
{
public function __construct(
public readonly string $customerId,
public readonly array $products,
) {}
}
```
The Controller maps it to an Application DTO and passes it to the Application Service:
```php
class PlaceOrderApplicationAction
{
public function __construct(
public readonly string $customerId,
public readonly array $products,
) {}
}
```
And then in the Application Handler, we remap everything again — this time into Domain objects — just to pass those arguments to the Aggregate:
```php
class PlaceOrderHandler
{
public function __construct(
private OrderRepositoryInterface $repository,
private EventBusInterface $eventBus,
) {}
public function handle(PlaceOrderApplicationAction $action): void
{
$order = Order::place(
OrderId::generate(),
CustomerId::fromString($action->customerId),
ProductList::fromArray($action->products)
);
$this->repository->save($order);
}
}
```
On the upper layers we map our DTO Request to Application DTO, then in the Handler we map it again to Domain objects.
Following this approach have not made layers independent, we simply created illusion of decoupling. Things between layers are still having the same reason to change, as they are coupled to the same data - just with extra translation steps between them.
> Having different representations of the same data does not decouple the layers. It just creates hidden dependency - which requires extra work when changing the structure.
Adding a single property — say, a `discountCode` — forced changes across **every layer**. The Request DTO, the Application DTO / the Command, the Handler, the Aggregate — all had to change in lockstep.
> I've also seen projects that took this even further — keeping a "pure" Domain Aggregate separate from a Persistence Entity (e.g., a Doctrine ORM `OrderEntity`), connected with additional mapping code to achieve "decoupling". This creates even more representation of the same data, leading to application wide refactors when data changes.
Let's now jump to the second point - code abstraction.
### 2\. Over-abstracting code
The next common pitfall in DDD projects is overloading the codebase with design patterns and abstractions. Patterns like Factory, Builder, Strategy are valuable tools — but when applied without questioning whether they earn their keep, they become a tax on every feature.
Take the Factory pattern. It's quite popular to create a Factory interface for things like identity generation. Even something as simple as `AccountId` gets its own Factory:
```php
interface AccountIdFactoryInterface
{
public function generate(): AccountId;
}
class UuidAccountIdFactory implements AccountIdFactoryInterface
{
public function generate(): AccountId
{
return new AccountId(Uuid::uuid4()->toString());
}
}
```
Two classes, an interface, Factory need to be wired in places where we need to generate it. The intent is to decouple us from the UUID library. But UUID has been the standard for quite some time now, and it's a pure computation — no I/O, no state. What exactly are we protecting ourselves from? A simple `AccountId::generate()` with the UUID encapsulated inside would do the same job.
> In some projects I've even eliminated custom Identifier Objects completely, and used `Uuid` directly to keep the Domain explicit and avoid unnessecry classes
This over-abstraction doesn't stop at Factories and Builders — it creeps into the Domain itself. Strategy patterns introduced "just in case" we might switch an implementation later. Interfaces wrapping things that have one concrete implementation and will never have another. **The Domain — the part of our system that should be the most concrete, the most explicit, the most readable — becomes a maze of indirection.**
But here's the thing: if we ever do need to swap an implementation, we can introduce the abstraction at that point. It's a straightforward refactoring. What we can't easily undo is the cost of carrying unnecessary abstractions across every feature, every day, from day one.
> The Domain should be the most concrete part of our application. It should just scream what it does — leaving no question marks, no layers of indirection, no ambiguity. Leave the abstractions for building frameworks and libraries. That's where they fit best.
And now we arrived at the final point - "Domain Purity".
### 3\. Purity becomes the obsession
The next pitfall is when purity becomes the main goal of why we are building the Application. Every decision gets filtered through "is this pure enough?"
This starts on the top - Application layer, the representation of our abstractions being in use, where Application Service became the mandatory ceremony for every action:
```php
class MarkOrderAsShippedHandler
{
public function __construct(
private OrderRepositoryInterface $repository,
private EventBusInterface $eventBus,
) {}
public function handle(MarkOrderAsShipped $command): void
{
$order = $this->repository->get(
OrderId::fromString($command->orderId)
);
$order->markAsShipped();
$this->repository->save($order);
foreach ($order->getRecordedEvents() as $event) {
$this->eventBus->publish($event);
}
}
}
```
In reallity, this handler does one thing: change a status. But the orchestration — load, call, save, publish — dwarfs it. And every single handler in the system looks nearly identical.
> The problem is not that we want to be "pure." The problem is what we define as pure. This whole Handler is not really our business logic — it's orchestration logic, repetitive and automatable. Our Domain is that one line `$order->markAsShipped()` buried inside all of this.
The same purity mindset applies to Aggregates themselves. To keep the Domain "free from infrastructure," the ORM mapping gets pushed into external XML or YAML files:
```xml
```
The reasoning: "Attributes couple the Domain to infrastructure." - but what did we actually achieve? The mapping still exists — we just moved it to a separate file. The coupling is still there. When we add a field to the Aggregate, we still have to update the mapping. We haven't removed the dependency, we've hidden it — making it less visible, less explicit, and easier to forget.
**Attributes are metadata - they don't change the business logic inside the Aggregate.** `cancel()` works exactly the same whether there's an `#[ORM\Column]` above a property or an XML file somewhere in a config folder. If using attributes makes development more explicit and simpler for you — there is no reason to remove them in the name of purity.
Purity had become a dogma. It's often more important than what business logic we actually wanted to implement. Every feature became a boilerplate celebration — and the business rules, the thing DDD was supposed to elevate, becomes buried somewhere deep in the call stack.
> When the ceremony exceeds the complexity of the problem, something has gone fundamentally wrong.
## The Turning Point: Asking a Different Question
I've done the things described in this article, one way or another. Layers of boilerplate, over-abstraction, purity dogma — I've been through all of it. And after years of this, I think I understand why.
> I do think that comes from asking the wrong question: **"How can we make things more pure?"**
That question leads exactly where you'd expect. More layers. More interfaces. More separation. More abstractions. More files. It leads to the feeling that so many developers have — that DDD is unnecessary complexity, pushing people to create huge amounts of classes and abstractions that serve no real purpose. And honestly? When purity is the goal, they're right. Yet it is unnecessary complexity.
But what if we asked a different question?
> **"How can we fully focus on business logic?"**
This question leads somewhere completely different. It pushes you to eliminate everything that isn't business logic. The layers of boilerplate? Gone — they were orchestration, not business rules. The over-abstraction? Gone — it was indirection that obscured what the code actually does. The purity dogma? Gone — it was protecting us from changes that never came, at a cost we paid every day.
When you follow this question to its conclusion, you end up in a place where the only thing you write is business logic. Everything else is handled for you.
### Colocate what belongs together
Start with persistence. If using Attributes in Aggregates speeds up the work and doesn't affect our business logic — there is no reason to skip it:
```php
#[ORM\Entity]
#[ORM\Table(name: 'orders')]
class Order
{
#[ORM\Id]
#[ORM\Column(type: 'string')]
private string $orderId;
#[ORM\Column(type: 'string')]
private string $customerId;
#[ORM\Column(enumType: OrderStatus::class)]
private OrderStatus $status;
public function cancel(): void
{
if ($this->status === OrderStatus::SHIPPED) {
throw new \DomainException("Cannot cancel shipped order");
}
$this->status = OrderStatus::CANCELLED;
}
}
```
Doctrine ORM attributes on your Aggregate — they're metadata. They don't change what `cancel()` does. They just tell the ORM how to store the data, right next to the data itself. One file, one place to change. Add a field, and you add it once — the mapping and the business logic live together because they change together.
And if `Active Record` is your way of working — Eloquent, for example — the same reasoning applies. There is no real reason to create separate mapping layers, having a separate Aggregate object and a separate Database object. They are still coupled to the same schema. We just create more work by splitting them apart, and more places where things can go wrong.
> If adding something along side our model doesn't affect our business logic, it's not impurity — it's pragmatism.
### Aggregates are Message Handlers
The next piece of the puzzle came from Alan Kay. The man who coined "Object-Oriented Programming" later said he regretted the name. It put the focus on objects — their structure, their relationships, their hierarchies. But that was never the point.
> "The big idea is messaging. \[...\] The key in making great and growable systems is how its modules communicate rather than what their internal properties and behaviors should be." — Alan Kay
In Kay's original vision, OOP was about objects communicating through messages. Not method calls on data structures. Messages. Inputs and outputs flowing through the system.
In Messaging, **Message Handlers are the entrypoints** — the things that receive messages and act on them. In DDD, **Aggregates are the entrypoints** — the guards that ensure business logic is fulfilled and protected. They are the same thing, viewed from a different perspective.
Commands — `PlaceOrder`, `CancelOrder`, `ApplyDiscount` — are messages. They describe business actions in business language. Events — `OrderWasPlaced`, `OrderWasCancelled` — are messages too. Commands are the input. Events are the output. Two sides of the same pipe.
> When you connect them — when you make the Aggregate the Command Handler directly — something powerful happens. There is no layer in between anymore. **Calling a Command is calling the Aggregate. It's 1:1.** You cannot bypass the business logic, because there is no middleman to skip or shortcut through. The Application Service that used to sit between them — receiving the Command, loading the Aggregate, calling the method, saving, publishing — was just a mechanical relay. Remove it, and the system becomes both simpler and safer.
This insight — combining Messaging with DDD — drove the design of Ecotone Framework to completely erase the ceremony from DDD. Let me show you what changes when you follow this path.
## The Surprise: Fewer Files Than CRUD
This is what surprises everyone, including DDD advocates. Let me show you what the Aggregate actually looks like when you treat it as the Command Handler:
```php
#[Aggregate]
class Order
{
#[Identifier]
private string $orderId;
private string $customerId;
private OrderStatus $status;
#[CommandHandler]
public static function place(PlaceOrder $command): self
{
$order = new self(
OrderId::generate(),
$command->customerId,
OrderStatus::PLACED,
);
$order->recordThat(new OrderWasPlaced($order->orderId));
return $order;
}
}
```
*One file. Domain logic, persistence, command handling — all colocated. Events are returned from the method. The framework handles loading, saving, transactions, and event publishing.*
No Application Service. No repository wiring. No manual event dispatching. The `#[CommandHandler]` attribute tells Ecotone to route Commands directly here. Static factory methods handle creation. Instance methods handle actions on existing Aggregates — Ecotone resolves the target instance from the Command's identifier automatically:
```php
#[Aggregate]
class Order
{
#[CommandHandler]
public function cancel(CancelOrder $command): array
{
if ($this->status === OrderStatus::SHIPPED) {
throw new \DomainException("Cannot cancel shipped order");
}
$this->status = OrderStatus::CANCELLED;
return [new OrderWasCancelled($this->orderId)];
}
```
*An action method on the Aggregate. Ecotone loads the right instance based on the Command's identifier, calls the method, saves the Aggregate, and publishes the returned events — all automatically.*
Now count the files for adding a new feature — say, "cancel order." One new Command class, one method added to the Aggregate, one action added to the Controller — **1 new file and 2 edits.**
```php
// The only new file
class CancelOrder
{
public function __construct(
#[TargetIdentifier]
public readonly string $orderId,
) {}
}
```
Compare that to the 8-10 files we saw earlier. The "simpler" CRUD approach has more files. The "complex" DDD approach has fewer.
But we can take this further.
### Step 1: Routing eliminates Command classes
For action commands that just change the state of Aggregate, do we really need a dedicated Command class? Since Commands are Messages, we can use routing. The Aggregate method gets a routing key, and the Controller sends the message directly:
```php
// In the Aggregate
#[CommandHandler("order.cancel")]
public function cancel(): array
{
if ($this->status === OrderStatus::SHIPPED) {
throw new \DomainException("Cannot cancel shipped order");
}
$this->status = OrderStatus::CANCELLED;
return [new OrderWasCancelled($this->orderId)];
}
```
```php
// In the Controller
#[Route('/orders/{orderId}/cancel', methods: ['POST'])]
public function cancel(string $orderId, CommandBus $commandBus): Response
{
$commandBus->send(
command: [],
routingKey: "order.cancel",
metadata: ["aggregate.id" => $orderId]
);
return new Response(200);
}
```
No Command class at all. The `aggregate.id` metadata tells Ecotone which Aggregate instance to load. For a simple status change, the new feature is **0 new files — just 2 edits**.
### Step 2: Pass payload directly — skip transformation
When the Command does carry data, we still don't need to manually deserialize it. However with Ecotone we can pass the raw JSON payload and content type to the Command Bus, and Ecotone will deserialize it directly into the Command class:
```php
#[Route('/orders', methods: ['POST'])]
public function place(Request $request, CommandBus $commandBus): Response
{
$commandBus->sendWithRouting(
routingKey: "order.place",
command: $request->getContent(),
commandMediaType: "application/json"
);
return new Response(201);
}
```
No Request DTOs. No manual mapping. No transformation layer. The JSON goes straight to the Command Handler, deserialized by the framework. The Controller becomes a thin pass-through — which is exactly what it should be.
We can push this even further.
### Step 3: A single Controller for everything
If the Controller is just passing a routing key and a payload, we don't need a Controller per Aggregate. We can have one Command Controller and one Query Controller for the entire application:
```php
#[Route('/api/{routingKey}', methods: ['POST'])]
public function command(
string $routingKey,
Request $request,
CommandBus $commandBus
): Response {
$result = $commandBus->sendWithRouting(
routingKey: $routingKey,
command: $request->getContent(),
commandMediaType: "application/json",
metadata: $request->query->all()
);
return new Response($result);
}
```
One Controller. Every new feature is just a method on the Aggregate. The routing key from the URL maps directly to the `#[CommandHandler]` routing key. The framework handles everything else.
Think about what this means. Adding a new business action to the system — a new rule, a new operation, a new capability — is **one method on the Aggregate**. That's it. No new files. No wiring. No boilerplate. Just business logic.
Therefore the new feature is **0 new files — just 1 edit**.
## What We Actually Needed
Look at where we started and where we ended up.
The first version of DDD — the one with 8-10 files per feature — put all the focus on the things outside of the Domain. Request DTOs, Application DTOs, Handlers, Repository interfaces, Repository implementations, Mappers, XML configs. From a high level, all of these non-business things distracted us from actually delivering features. We spent more time wiring infrastructure than writing business rules. The Domain became a small piece buried under layers of ceremony.
The second version eliminates all of that. The boilerplate — gone. The orchestration code — gone. The translation layers — gone. What's left is pure business logic. Where we can take it to the degree where business logic becomes the only code we need to write.
And here's what matters: we don't give anything up. Database transactions are still there — handled automatically. Event publishing is still there - available for us, Middlewares are still there — interceptors with `#[Before]`, `#[After]`, `#[Around]`. Access to DI Services is still there — inject them directly into handler method parameters when you need them.
> This way of doing DDD makes building systems easier than common CRUD applications. Not in theory. In practice. Fewer files, fewer moving parts, fewer places for bugs to hide — and every line of code focused on what actually matters: our business logic.
If you've been burned by DDD before, I'd invite you to try [Ecotone Framework](https://docs.ecotone.tech/?ref=blog.ecotone.tech). To see how to build systems that are fully focused on the business domain, so that you can get the feeling of building Enterprise grade applications in a way that is simpler than CRUD.
### Make your Domain speak the business language
URL: https://blog.ecotone.tech/make-your-domain-speak-the-business-language-2/
Last updated: 2026-03-20T22:16:43.000Z
You join a new project. The team tells you it's built with Domain-Driven Design. You open the `Domain/` folder expecting to learn what the system does — and instead you find: `Aggregates/`, `ValueObjects/`, `Repositories/`, `Services/`, `Events/`, `Exceptions/`. You've learned nothing about the business. You've learned a lot about the team's DDD vocabulary.
This is one of the most common structural patterns in DDD codebases, and in my experience, it actively works against the thing DDD is supposed to accomplish.
## The Pattern That Feels Right But Isn't
Domain-Driven Design exists for one reason: to align software with business reality so developers and domain experts speak the same language. The folder structure of your domain layer is the first thing a new developer sees. It shapes how they think about the system before they read a single line of code.
So what happens when that structure looks like this?
```
Domain/
├── Aggregates/
│ ├── Order.php
│ ├── Wallet.php
│ └── Account.php
├── ValueObjects/
│ ├── Money.php
│ ├── Currency.php
│ ├── OrderId.php
│ └── WalletId.php
├── Repositories/
│ ├── OrderRepository.php
│ └── WalletRepository.php
├── Services/
│ ├── BalanceCalculator.php
│ └── PricingService.php
├── Events/
│ ├── OrderPlaced.php
│ └── WalletCredited.php
└── Exceptions/
├── InsufficientFundsException.php
└── OrderAlreadyShippedException.php
```
*A typical DDD codebase organized by technical building block — it tells you about DDD patterns, not about what the system does.*
It looks tidy. Symmetrical. Organized. It satisfies that developer craving for clean classification — forks with forks, knives with knives.
But a domain model isn't a utility drawer. It's a map of business capabilities. And this structure scatters every business concept across six directories. Want to understand how wallets work? Pull from `Aggregates/`, `ValueObjects/`, `Repositories/`, `Services/`, `Events/`, and `Exceptions/`. The domain layer — which should be the most readable part of the system — becomes a scavenger hunt.
A business expert looking at this folder tree learns absolutely nothing about what the system does. They learn it has aggregates and value objects. That's DDD jargon, not business language. The ubiquitous language is missing from the one place it should be most visible.
## Organizing by Business Capability
The solution, which I instead is to organize the domain layer around the Aggregate root and the concepts that gravitate around it. Each sub-module represents a business capability.
```
Domain/
├── Wallet/
│ ├── Wallet.php
│ ├── WalletId.php
│ ├── Money.php
│ ├── WalletRepository.php
│ ├── WalletCredited.php
│ ├── WalletDebited.php
│ ├── BalancePolicy.php
│ └── InsufficientFunds.php
├── Order/
│ ├── Order.php
│ ├── OrderId.php
│ ├── OrderLine.php
│ ├── OrderRepository.php
│ ├── OrderPlaced.php
│ └── PricingService.php
├── Promotion/
│ ├── Promotion.php
│ ├── DiscountRule.php
│ ├── PromotionRepository.php
│ └── PromotionApplied.php
└── Account/
├── Account.php
├── Email.php
├── AccountRepository.php
└── AccountActivated.php
```
*The same codebase organized by business capability — the folder tree now reads like a description of what the system does.*
A new developer opens this and immediately sees: this system deals with Wallets, Orders, Promotions, and Accounts. No DDD knowledge required. A business expert could look at this structure and nod — those are the things the business cares about.
> The Aggregate is the natural center of gravity here, and this isn't an arbitrary choice. In DDD, the Aggregate already defines the consistency boundary — what changes together goes together.
Everything inside a business sub-module exists to support or interact with that Aggregate. Value Objects are its building blocks. Events are what it emits. The Repository is how it's persisted. Exceptions represent its invariant violations. The Aggregate *already is* the organizing principle — the directory structure now simply reflects that reality.
> We can of course make a bit of hybrid approach when the volume of classes is getting too big, but yet still within the module itself. E.g. introduce Domain/Wallet/Event and Domain/Wallet/Command, and the main Model on the top level.
Let me show the difference concretely. Here's how a Wallet looks in the business-capability structure, using [Ecotone Framework](https://ecotone.tech/?ref=blog.ecotone.tech) which supports this approach natively through PHP attributes:
```php
// Domain/Wallet/Wallet.php
namespace Domain\Wallet;
use Ecotone\Modelling\Attribute\Aggregate;
use Ecotone\Modelling\Attribute\Identifier;
use Ecotone\Modelling\Attribute\CommandHandler;
#[Aggregate]
class Wallet
{
#[Identifier]
private WalletId $id;
private Money $balance;
#[CommandHandler]
public static function create(CreateWallet $command): self
{
$wallet = new self();
$wallet->id = new WalletId($command->walletId);
$wallet->balance = Money::zero($command->currency);
return $wallet;
}
#[CommandHandler]
public function credit(CreditWallet $command): void
{
$this->balance = $this->balance->add($command->amount);
}
#[CommandHandler]
public function debit(DebitWallet $command): void
{
if ($this->balance->isLessThan($command->amount)) {
throw InsufficientFunds::forWallet($this->id, $command->amount, $this->balance);
}
$this->balance = $this->balance->subtract($command->amount);
}
}
```
*The Wallet aggregate — every class it references lives in the same `Domain/Wallet/` directory. `#[Aggregate]` tells the framework this is an Aggregate; `#[CommandHandler]` marks business operations. No base class to extend, no repository interface to write — the framework provides that automatically.*
`Money`, `WalletId`, `CreditWallet`, `InsufficientFunds` — all in the same namespace, same directory. No scavenger hunt. The namespace *is* the business context.
And here's the thing about knowing a class's DDD role — you don't need a folder for that:
```php
// Domain/Wallet/Money.php
namespace Domain\Wallet;
final readonly class Money
{
public function __construct(
public int $amount,
public Currency $currency,
) {}
public function add(self $other): self
{
assert($this->currency === $other->currency);
return new self($this->amount + $other->amount, $this->currency);
}
}
```
*Money is obviously a Value Object — immutable, no identity, value-based equality. The code tells you that. The directory's job is to tell you it belongs to the Wallet capability.*
You didn't need a `ValueObjects/` directory to know `Money` is a Value Object. The class makes it self-evident. What the directory *does* tell you is that `Money` belongs to the Wallet business capability — something the class alone cannot communicate.
## How the Framework Reinforces Business Alignment
Ecotone Framework philosophy *naturally eliminates* the gravitational pull toward technical grouping.
Traditional DDD frameworks push toward technical structure almost accidentally. You extend `AggregateRoot`, implement `RepositoryInterface`, register services by namespace convention. Each of these mechanics subtly whispers: "group me with my kind." The `WalletRepository` interface wants to sit next to `OrderRepository`. The base class creates a family resemblance between Aggregates that makes them feel like they belong together. Ecotone sidesteps all of this.
> Ecotone discovers everything through PHP attributes — `#[Aggregate]`, `#[CommandHandler]`, `#[EventHandler]`, `#[QueryHandler]`. It genuinely does not care where your files live. No base class to extend, no interface to implement, no namespace-based registration. The `#[Aggregate]` attribute on a plain PHP class is all it needs.
This means:
- **No framework inheritance in your domain.** Your Aggregate is a plain PHP class, no extending or implementing framework specific classes that emphasize structural types (e.g. BaseAggregate).
- **Attribute-based discovery.** The framework scans for `#[Aggregate]`, `#[CommandHandler]`, `#[EventHandler]`, `#[QueryHandler]`. It does not care about directory structure. You're free to organize entirely by business capability.
- **Command handling lives on the Aggregate.** `#[CommandHandler]` on the `credit()` method means the Aggregate *is* the handler. Meaning there is no even a need for Application layer split, everything gravitates towards your Aggregate.
For event-sourced domains, the same philosophy holds:
```php
// Domain/Wallet/Wallet.php
namespace Domain\Wallet;
use Ecotone\Modelling\Attribute\EventSourcingAggregate;
use Ecotone\Modelling\Attribute\EventSourcingHandler;
use Ecotone\Modelling\Attribute\Identifier;
use Ecotone\Modelling\Attribute\CommandHandler;
#[EventSourcingAggregate]
class Wallet
{
#[Identifier]
private string $walletId;
private Money $balance;
#[CommandHandler]
public static function create(CreateWallet $command): array
{
return [new WalletCreated($command->walletId, $command->currency)];
}
#[CommandHandler]
public function credit(CreditWallet $command): array
{
return [new WalletCredited($this->walletId, $command->amount)];
}
#[CommandHandler]
public function debit(DebitWallet $command): array
{
if ($this->balance->isLessThan($command->amount)) {
throw InsufficientFunds::forWallet($this->walletId, $command->amount, $this->balance);
}
return [new WalletDebited($this->walletId, $command->amount)];
}
#[EventSourcingHandler]
public function applyCreated(WalletCreated $event): void
{
$this->walletId = $event->walletId;
$this->balance = Money::zero($event->currency);
}
#[EventSourcingHandler]
public function applyCredited(WalletCredited $event): void
{
$this->balance = $this->balance->add($event->amount);
}
#[EventSourcingHandler]
public function applyDebited(WalletDebited $event): void
{
$this->balance = $this->balance->subtract($event->amount);
}
}
```
*Switch from `#[Aggregate]` to `#[EventSourcingAggregate]`, return events from command handlers, add `#[EventSourcingHandler]` methods — and you have a fully event-sourced Aggregate. Still a plain PHP class. Still lives in `Domain/Wallet/`.*
The insight that clicked for me: **attributes encode the DDD role, directories encode the business capability.** Each communicates what the other cannot. The `#[Aggregate]` attribute tells you *what it is*; the `Domain/Wallet/` directory tells you *what it's for*. When your framework and your structure each carry the right information, the whole system becomes more legible.
## Handling the Edge Cases
Two practical questions always come up with this approach.
**What about shared concepts?** Some Value Objects like `Currency` or `DateRange` genuinely cross module boundaries. These go in a `Shared/` module. The discipline is: only put something there when it's used by three or more modules. Two usages? Pick the primary owner or duplicate. A small `Shared/` module is healthy. A large one means your boundaries need rethinking.
```
Domain/
├── Shared/
│ └── Currency.php
├── Wallet/
├── Order/
└── Promotion/
```
*Shared concepts get their own small module — but keep it minimal.*
**What about cross-aggregate services?** A `TransferService` that moves money between wallets — where does it live? Usually in `Wallet/`. It operates on Wallets, uses Wallet language, enforces Wallet invariants. If it truly spans multiple Aggregates with equal weight, it might warrant its own module (`Domain/Transfer/`). And that's actually a discovery moment — you just found a business concept that was hidden when everything sat in a generic `Services/` folder.
This is one of the surprises that made this approach click for me. When you force yourself to organize by business capability, you're forced to *name* things in business terms. That `DiscountCalculationService` sitting in `Services/` — where does it go? Probably `Promotion/`. But it depends on Order data too. Is there a `Pricing/` concept hiding here? The structure becomes a tool for domain exploration, not just code organization.
## The Trade-Offs Worth Acknowledging
In my experience, the most common objection is: "But I want to see all my repositories at a glance!" The question to ask back is: *when do you actually need that?* If you're working on wallet features, you need `WalletRepository`. You find it in `Wallet/`. If you're doing a cross-cutting infrastructure concern like switching the ORM, you grep for `interface.*Repository` — the directory structure is irrelevant for that task anyway. The desire to "see all repositories" is a technical impulse, not a business need.
Another trade-off: you'll sometimes duplicate similar Value Objects across modules. `Money` in Wallet and `Price` in Order might look alike. But they represent different business concepts with potentially different invariants. This duplication is correctness, not a smell. The DRY principle applies within a boundary, not across boundaries - and it's actually about not duplicating knowledge, not the code.
Early in a project, you'll also get boundaries wrong. That's fine. The cost of moving a class between business sub-modules is low — change the namespace, update imports. The cost of having the wrong organizational axis (technical vs. business) is a codebase that trains every developer to think in the wrong terms.
## Why This Matters Beyond Folder Structure
1. **Organize by reason for change, not by technical classification.** When a business requirement changes, you want all affected code in one place. This principle extends far beyond DDD.
2. **Your directory structure is a communication tool.** It shapes mental models before anyone reads a line of code. Choose what it communicates carefully.
3. **Don't encode metadata as structure.** A class being a Value Object is metadata you can discover by reading it. Directory hierarchy should encode relationships and boundaries — things you can't discover from a single class.
4. **The Aggregate is a natural module boundary.** In any architecture — microservices, modular monoliths, packages — the consistency boundary naturally defines what belongs together.
5. **Resist premature classification.** Creating `ValueObjects/` and `Services/` folders on day one forces you to categorize before you understand the domain. Start with business modules and let the patterns emerge.
## The Shift That Matters
The biggest misconception I see is that the technical split *feels* more DDD-ish. You read the book, learn about Aggregates and Value Objects and Domain Services, and immediately create folders named after these patterns. It feels like you're doing DDD properly — look, the patterns are right there in the folder names. But DDD's central message was never "categorize things by pattern." It was "align your software with the business domain."
When I restructured projects from technical to business sub-modules, something shifted in how teams talked about the code. Instead of "I added a new Value Object to the ValueObjects folder," developers started saying "I added a new concept to the Wallet module." The directory structure started doing what the Ubiquitous Language was always supposed to do — it shaped how people thought about the system.
Your folder tree is the first piece of documentation a developer reads, and unlike a wiki page, it never goes stale. Make it speak the language of the business, not the language of the DDD textbook.
### Ecotone Agentic Skills on your command
URL: https://blog.ecotone.tech/building-event-sourcing-ddd-cqrs-with-agentic-skills-in-php/
Last updated: 2026-02-19T14:27:53.000Z
*There is a moment in The Matrix that pretty much describes current situation with AI.*
Neo sits in an old, worn leather chair. Tank plugs a data cable into the socket on the back of Neo’s head. Lines of code race across the screen. Neo’s body jerks a little, and his eyes blink fast. Then he says three words:
*"I know Kung Fu."*
Morpheus, unsurprised, nods: *"Show me."*
It's pure cinema. But if you strip away the leather and the green-tinted cinematography, what you're watching is actually a story about **context-specific knowledge transfer**. Neo didn't download the entire internet. He didn't get a general education in "fighting." He received exactly the skills he needed, precisely when he needed them, in a format his mind could immediately apply.
What if we could do that with software architecture?
Not kung fu. Not martial arts. But Domain-Driven Design. Command Query Responsibility Segregation. Event Sourcing. Sagas. Projections. The kind of patterns that separate weekend projects from production systems that handle millions of events.
This is how **Agentic Skills work in Ecotone**.
## Part 1: Loading Knowledge Into Your Mind
Picture this: you're working on a feature. A customer needs order management with full audit history. Event sourcing would be perfect here, but there's a problem. You've read the theory. You know event sourcing means storing state changes as a sequence of events instead of current state. You understand why it matters for auditability and temporal queries.
But theory and implementation? Those are different planets.
If you don’t know fully the actual patterns the framework expects, or if you’re creating something you’ve not enough experience in, you may feel unsured whatever the path is correct. And with AI, that uncertainty multiplies, as it speeds up the way to the goal. The AI might generate code that looks sophisticated but misses crucial details. It might hallucinate solutions which combined together make no sense, or you may find that things should have been done differently long after they have landed on production.
This is the context pollution problem.
When you dump 5,000 lines of framework documentation into your AI's context window, something counter-intuitive happens. More information creates less accuracy. The AI sees everything at once: basic tutorials, advanced patterns, edge cases, migration guides, deprecated approaches. It can't distinguish what matters for your specific task from what doesn't. So it averages. It hedges. It produces code that's generically plausible instead of specifically correct.
**Ecotone Skills work differently. They do follow official** [**Agentic Skills specification**](https://agentskills.io/home?ref=blog.ecotone.tech)**.**
> A Skill is a modular knowledge package designed specifically for AI coding assistants. Not for humans. For AI. Think of it as structured learning compressed into exactly the format an AI model needs to generate precise, pattern-compliant code.
To install new skills, we simply follow our Coding Agent inbuilt Commands:
> /plugin install ecotone-skills@ecotone
[AI Integration | Ecotone - DDD, CQRS, Event Sourcing in PHPEcotone - DDD, CQRS, Event Sourcing in PHP](https://docs.ecotone.tech/other/ai-integration?ref=blog.ecotone.tech#ecotone-skills)
Look on how to install Ecotone skills for different coding agents
This works because Ecotone has implemented patterns as Building Blocks — high-level abstractions with declarative configuration. You don't wire together low-level infrastructure and configurations. You declare intent through attributes like **#\[CommandHandler\]**, **#\[EventSourcingAggregate\]**, or **#\[Saga\]**, and the framework handles the rest.
> Because Ecotone's knowledge is already well organized — each Building Block representing a clear, self-contained pattern - it can be packaged into downloadable skill.
When we download Ecotone's skills, under the hood we get access to over 17 different skills including:
- A Skill for Event Sourcing
- A Skill for Workflows
- A Skill for Asynchronous Processing
But downloading the skill does not meant activating it, it becomes available but yet dormant. To understand how it's being activated, we first need to understand how the structure of the Skill looks like.
## Part 2: Knowledge Ready to Use
The brain now has access to the knowledge, before we will understand how we can reach for that knowledge, let's first discuss the three layered structure of Skills:
**Layer 1: Metadata (name and description):** This loads when you start your session. It tells Coding Agent (Claude Code, Cursor, Codex etc) that the Skill exists and *when to activate it.* Think of this as the chapter titles in a textbook. You see what's available without loading everything into memory.
**Layer 2: Body (actual examples):** This is the core knowledge: what this pattern is, when to use it, how the Building Blocks work, and canonical code examples. *This loads automatically when Coding Agent detects relevant context.*
**Layer 3: Deep references (additional files carrying more details):** These load on demand when the AI needs exact API signatures or full implementation examples. Most tasks never need this layer. When you do, it's targeted: just the specific reference that answers the specific question.
**AI agents loads only Metadata of your Skills as part of the process.** This is because they want to know what they know. This gives them enough context to ask for more details, when it becomes needed. Meaning if we focus on building Event Sourcing feature, it does not mean we need to now focus on communication between Services (Applications).
```yaml
---
name: ecotone-asynchronous
description: >-
Implements asynchronous message processing in Ecotone: message channels,
#[Asynchronous] attribute, #[Poller] configuration, delayed messages,
priority, time to live, scheduling, and dynamic channels. Use when
running handlers in background, configuring message queues, async
processing, delayed delivery, scheduling, priority, TTL, or dynamic
channel routing.
---
```
> **The main idea behind skills is to keep your Context small and relevant to what you're working on.**
Instead of 5,000 lines of generic documentation, your AI loads 150-300 lines of precise patterns exactly when it needs them. Instead of statistical guessing based on documentation fragments, it follows exact templates with real code examples. Instead of "this is probably how aggregates work in Ecotone," it knows: here's the attribute, here's the method signature, here's how events are applied, here's the test pattern.
> Think about the parallel to Neo in that chair. He's not reading a book about kung fu. He's not watching tutorial videos. He's not learning through repetition and practice. Knowledge is being loaded directly into the exact neural pathways that can use it. Structured. Precise. Immediately actionable.
The knowledge is available, we only load the Metadata of skills to be aware of what we know, the next question when do we actually load the full details about the Skill (description and deep references).
## Part 3: I know Kung Fu
So once you've downloaded the skills, they become available for activation.
When you type: "Create an event-sourced aggregate for order management."
> Your Coding Agents backed up the Model will detects the keywords. If it will recognize the patterns, approaches or techniques described by one of your Skill's Metadata, it will reach for the whole skill body.
What will happen under the hood, is that `ecotone-aggregate` and `ecotone-event-sourcing` Skills will load automatically. Not the entire Ecotone documentation. Not a generic blog post about event sourcing theory. Not some random code examples that may or not be relevant. It will actually load specific patterns for building event-sourced aggregates with Ecotone's Building Blocks, as it will match your intent with Skill's metadata.

Automatic Skill loading in Claude Code
The second option is to load the Skill manually. This is especially useful if our Coding Agent have not picked specific Skill automatically, or we want to be full precise on the Skill.

Loading the Skill manually in Claude Code
And then your Event Sourcing Skill is loaded, your Coding Agent will know how to implement: Aggregate class with the right attributes, command handlers that record events, event handlers that apply state changes, proper encapsulation. That will be Production-ready code.
## The Multiplication Effect
Let's combine all of those information together.
**Building Blocks alone** give you clear, maintainable patterns that reduce cognitive load, boilerplate, and framework learning curve.
**AI alone** gives you fast code generation and ability to follow on the patterns.
**Building Blocks + Skills** give you something neither achieves independently: **AI that generates production-quality, framework-correct, tested code — on the first try.**
Asks for a complete feature:
*"Create an event-sourced Ticket aggregate that handles creation and closing, with a projection that tracks open ticket counts per assignee, and send async email when Ticket is created."*
With Skills loaded, the AI produces:
1. An `#[EventSourcingAggregate]` with `TicketCreated` and `TicketClosed` events, correct factory method, and `#[EventSourcingHandler]` methods for state reconstruction
2. A `#[Projection]` with the proper stream source, event handlers that maintain the read model, and partition configuration
3. `#[Asynchronous]` Event Handler being able to send Email, when Ticket is Created
4. Complete test coverage using `EcotoneLite::bootstrapFlowTesting()`
Each piece follows Ecotone conventions exactly. The aggregate uses static factory methods for creation. The projection handles idempotency. The async configuration includes proper error channel setup. The tests verify the full flow from command to read model.
The knowledge isn't simplified or dumbed down. It's the same patterns that power large-scale production systems. Skills just make that knowledge *instantly accessible* through the tool you're already using.
Install Ecotone. Open your AI assistant. Describe what you need. And when the code appears — correct, tested, production-ready — you'll understand exactly how Neo felt.
*"I know Event Sourcing."*
*Show me.*
### AI Isn't the Problem. Your Architecture Is
URL: https://blog.ecotone.tech/ai-isnt-the-problem-your-architecture-is/
Last updated: 2026-02-09T18:53:13.000Z
AI coding assistants have created a velocity paradox. Developers ship code **55% faster**, but that AI-generated code shows **41% higher churn rates** (rotation of the code). When you're adding features at twice the speed, architectural mistakes compound at twice the rate too.
This isn't an argument against AI tools—they're transformative. It's an argument for investing in architecture that can absorb rapid change without collapsing under its own weight.
> Whatever practices you follow—AI multiplies them. Follow solid patterns, and you build resilient systems faster than ever. Follow ad-hoc approaches, and you accumulate technical debt at unprecedented speed.
The question becomes: how do you ensure AI multiplies the right patterns?
## The acceleration is real—and it's changing everything
[The Stack Overflow 2025 Developer Survey](https://survey.stackoverflow.co/2025/ai?ref=blog.ecotone.tech) confirms this AI becomes new norm now: **84% of developers** use or plan to use AI tools, with **51% using them daily**.
But velocity without structure creates debt. [GitClear's analysis](https://www.gitclear.com/ai%5Fassistant%5Fcode%5Fquality%5F2025%5Fresearch?ref=blog.ecotone.tech) of 211 million lines of changed code found AI-generated code has a **41% higher churn rate**—code that gets reverted or substantially rewritten within two weeks. The [DORA Report](https://cloud.google.com/blog/products/devops-sre/announcing-the-2024-dora-report?ref=blog.ecotone.tech) quantified this at organizational scale: **25% increase in AI adoption correlates with 7.2% decrease in delivery stability**.
> MIT professor Armando Solar-Lezama captured it precisely—AI is "a brand new credit card that will allow us to accumulate technical debt in ways we were never able to do before."
The pattern is clear: AI amplifies whatever architectural approach you've established. The solution isn't to slow down—it's to build on foundations where the default path leads to resilient code.
## Why declarative abstractions matter for AI-assisted development
Here's what experienced developers are discovering: AI tools perform dramatically better when working with well-structured, pattern-driven code. One of the most effective way to get better performance day after day is to create context files: providing style guides, examples, and rules files.
> Messaging frameworks provide structure at a deeper level than style guides. They encode architectural patterns into declarative conventions that AI tools recognize and reproduce correctly.
Consider what a declarative annotation communicates.
**In Ecotone:**
```php
#[CommandHandler]
public function placeOrder(PlaceOrder $command): void
```
**In Axon:**
```java
@CommandHandler
public void handle(PlaceOrderCommand command)
```
**In NServiceBus:**
```csharp
public class PlaceOrderHandler : IHandleMessages
```
Each tells both humans and AI: this code handles commands, receives typed command objects, and the framework manages routing, serialization, and error handling.
> When you ask AI to add "Order Canceling" it generates code that fits the established pattern—not because it was explicitly instructed, but because the pattern is unambiguous.
We will discuss three different Frameworks that provides abstractions on top of well known Messaging patterns: **Ecotone** for PHP, **Axon Framework** for Java/Kotlin, and **NServiceBus** for .NET.
- **Ecotone** embraces pure declarative configuration through PHP 8 attributes. Business code contains no framework base classes, no infrastructure interfaces—just attributes declaring intent. This creates the cleanest separation between what your code does and how the framework delivers it.
- **Axon Framework** follows a similar annotation-driven philosophy for its core patterns, with imperative APIs available when complex features require direct framework interaction. This hybrid approach balances simplicity for common cases with full control when needed.
- **NServiceBus** takes a more interface-driven approach typical of the .NET ecosystem, where handlers implement framework interfaces and configuration happens through fluent APIs. This style provides excellent IDE discoverability while maintaining the separation between business logic and messaging infrastructure.
The common thread: all three guide developers toward consistent, predictable patterns that AI tools can recognize and extend reliably.
## Workflows: Where ad-hoc solutions create the most debt
Real business processes span multiple steps, services, and time periods. An order involves payment, inventory, shipping, and notifications—each potentially failing independently.
> Without standardized workflow coordination, teams create ad-hoc solutions for each process, each with its own error handling, its own state management, its own failure modes.
This is exactly where AI-assisted velocity becomes dangerous. Generate code quickly without workflow patterns, and you get a proliferation of inconsistent approaches. Each new feature adds its own retry logic, its own compensation handling, its own way of tracking multi-step progress. The codebase becomes a patchwork of similar-but-different solutions.
One of the solution that Messaging frameworks provide to solve this are **sagas**—a standardized pattern for coordinating long-running processes. The framework handles state persistence, message correlation, timeout management, and failure recovery. Your code declares business logic; the infrastructure handles coordination.
In Axon, a saga declares its triggers through annotations:
```java
@Saga
public class OrderFulfillmentSaga {
@StartSaga
@SagaEventHandler(associationProperty = "orderId")
public void handle(OrderPlacedEvent event) {
// Saga starts, framework handles correlation and persistence
}
@SagaEventHandler(associationProperty = "orderId")
public void handle(PaymentReceivedEvent event) {
// Framework routes by orderId, manages state
}
@EndSaga
public void handle(OrderCompletedEvent event) {
// Saga ends, framework cleans up
}
}
```
Ecotone uses the same declarative approach with PHP attributes:
```php
#[Saga]
final class OrderFulfillmentSaga
{
#[Identifier]
private string $orderId;
#[EventHandler]
public static function startWhen(OrderWasPlaced $event): self { /* ... */ }
#[EventHandler]
public function whenPaymentReceived(PaymentWasReceived $event): void { /* ... */ }
}
```
NServiceBus uses interface implementation with explicit correlation:
```csharp
public class OrderFulfillmentSaga : Saga,
IAmStartedByMessages,
IHandleMessages
{
protected override void ConfigureHowToFindSaga(SagaPropertyMapper mapper)
{
mapper.MapSaga(s => s.OrderId).ToMessage(m => m.OrderId);
}
}
```
The syntax differs, but the pattern is consistent: declare which events start, continue, and complete the workflow. Let the framework handle the rest. When AI generates saga code in these frameworks, it generates code that follows the established pattern—with proper correlation, lifecycle management, and state handling.
## Event Sourcing: Audit trails as architectural default
Event sourcing stores every state change as an immutable event. Instead of updating "current state," you append events describing what happened. This creates complete audit trails, enables time-travel debugging, and makes system behavior explicitly traceable.
But event sourcing's real value in the AI era is subtler: it makes side effects explicit. Traditional state-stored systems hide what changed. Event-sourced systems make change visible by design. When AI generates code that emits events, it generates code that documents its own effects.
Ecotone provides native event sourcing where aggregates return events with pure functions from command handlers:
```php
#[EventSourcingAggregate]
class Wallet
{
#[CommandHandler]
public function withdraw(WithdrawMoney $command): array
{
if ($command->amount > $this->balance) {
throw new InsufficientFundsException();
}
return [new MoneyWasWithdrawn($this->walletId, $command->amount)];
}
#[EventSourcingHandler]
public function applyWithdraw(MoneyWasWithdrawn $event): void
{
$this->balance -= $event->amount;
}
}
```
Axon was purpose-built for event sourcing and follows the same separation:
```java
@Aggregate
public class Wallet {
@CommandHandler
public void handle(WithdrawMoneyCommand cmd) {
if (cmd.getAmount() > this.balance) {
throw new InsufficientFundsException();
}
apply(new MoneyWithdrawnEvent(walletId, cmd.getAmount()));
}
@EventSourcingHandler
public void on(MoneyWithdrawnEvent event) {
this.balance -= event.getAmount();
}
}
```
Command handlers emit events—they never modify state directly. The framework persists events to an append-only store and reconstructs aggregate state by replaying them. This separation forces explicit declaration of what changed.
Both frameworks also provide projections—transforming event streams into read-optimized views. In Ecotone:
```php
#[Projection('wallet_balance', Wallet::class)]
class WalletBalanceProjection
{
#[EventHandler]
public function whenWithdrawn(MoneyWasWithdrawn $event, WalletBalanceRepository $repository): void
{
$repository->updateBalance($event->walletId, -$event->amount);
}
}
```
In Axon:
```java
@ProcessingGroup("wallet-balance")
public class WalletBalanceProjection {
@EventHandler
public void on(MoneyWithdrawnEvent event, @Autowired WalletBalanceRepository repository) {
repository.updateBalance(event.getWalletId(), -event.getAmount());
}
}
```
Projections let you build specialized read models for different query needs—all derived from the same event stream, all automatically kept in sync.
NServiceBus takes a different approach—it's a messaging framework rather than an event sourcing framework. Teams using NServiceBus for event sourcing integrate with dedicated event stores like EventStore, Marten, or SqlStreamStore. NServiceBus then handles event distribution after the external store persists them:
```csharp
public class WalletHandler : IHandleMessages
{
private readonly IEventStore _eventStore;
public async Task Handle(WithdrawMoney message, IMessageHandlerContext context)
{
var wallet = await _eventStore.LoadAggregate(message.WalletId);
var events = wallet.Withdraw(message.Amount);
await _eventStore.AppendEvents(message.WalletId, events);
foreach (var evt in events)
await context.Publish(evt);
}
}
```
This separation of concerns—external store for event persistence, NServiceBus for reliable event distribution.
> When AI generates code in event-sourced systems, it generates code that produces named, typed events describing what happened. The pattern guides toward explicitness even when the developer (or AI) doesn't consciously think about debugging and auditability.
## Reliable communication: Infrastructure-level resilience
Distributed systems fail. Networks partition, services crash, databases timeout. Without framework support, each feature needs its own error handling—and AI-generated error handling tends toward optimistic happy paths.
This is where messaging frameworks provide perhaps their most important value: resilience that doesn't depend on individual implementation quality.
When you configure Ecotone's retry policy with delayed retries and dead letter handling:
```php
#[ServiceContext]
public function errorConfiguration()
{
return ErrorHandlerConfiguration::createWithDeadLetterChannel(
'errorChannel',
RetryTemplateBuilder::exponentialBackoff(initialDelay: 1000, multiplier: 2)
->maxRetryAttempts(3),
DbalDeadLetterChannel::create('dead_letter')
);
}
```
Or NServiceBus recoverability:
```csharp
endpointConfiguration.Recoverability()
.Immediate(i => i.NumberOfRetries(3))
.Delayed(d => d.NumberOfRetries(2).TimeIncrease(TimeSpan.FromSeconds(30)));
```
Or Axon's dead letter queue:
```yaml
axon:
eventhandling:
processors:
order-processing:
dlq:
enabled: true
```
Every handler in your application gains automatic resilience. You don't implement retries per feature. AI doesn't need to remember to add retry logic. The framework handles it at the infrastructure level.
> The same applies to outbox patterns for atomic message publishing and deduplication for exactly-once processing. These are configured once and apply everywhere. They're not patterns that developers must remember to implement—they're infrastructure that protects every message automatically.
This matters enormously for AI-assisted development. When AI generates a message handler, it generates a handler protected by framework-level resilience. The AI doesn't need to understand distributed systems failure modes. The architecture handles it.
## The multiplication effect
The throughput gains from AI coding assistants are real and substantial. Teams that harness them effectively will outpace those that don't. But "effectively" requires architecture that shapes what gets multiplied.
Without messaging frameworks, AI multiplies:
- Ad-hoc error handling that varies by feature
- Implicit coupling hidden in direct method calls
- State changes scattered across the codebase with no audit trail
- Custom workflow coordination for each multi-step process
With messaging frameworks, AI multiplies:
- Consistent handler patterns with standardized structure
- Explicit message contracts that document component boundaries
- Event-driven changes that create automatic audit trails
- Saga patterns that coordinate workflows predictably
> The frameworks don't constrain what you can build—they guide how you build it. When you ask AI to add a feature, the surrounding patterns shape the generated code toward consistency, resilience, and maintainability.
## Start with patterns, scale with confidence
The question isn't whether to use AI coding assistants—that ship has sailed. The question is what patterns AI will multiply in your codebase.
Messaging frameworks encode decades of enterprise patterns into declarative conventions. They separate business logic from infrastructure concerns. They provide resilience at the architecture level rather than the implementation level. They create codebases where the default path leads to robust, maintainable systems.
When you're shipping at AI-assisted velocity, these aren't nice-to-haves. They're the scaffolding that determines whether that velocity builds something lasting or accelerates toward collapse.
Whatever practices you follow, AI multiplies them. Choose patterns worth multiplying.
### What If 80% of Your Workflow Code Shouldn't Exist?
URL: https://blog.ecotone.tech/three-different-ways-to-build-workflows/
Last updated: 2026-02-03T13:43:51.000Z
I'm going to make a claim: **You don't need a workflows.**
Not for order cancellation timeouts. Not for reminder emails. Probably not even for that multi-step process you're sketching on a whiteboard.
What you need is the right tool for the right job.
## The Simplicity Trap: When You Don't Need a Workflow at All
Before diving into workflow patterns, let's address an uncomfortable truth: **many "workflow" implementations are over-engineered**.
Consider this requirement:
> "Cancel the order if it's not paid within 24 hours."
The typical developer instinct kicks in: design a `scheduled_tasks` table, write a command that queries orders created more than 24 hours ago where status equals unpaid, handle the edge case where payment arrives during your batch run, set up a cron job...
**Stop. This isn't a workflow problem. It's a delayed action.**
With Ecotone, this becomes a single handler with a `#[Delayed]` attribute:
```php
#[Delayed(new TimeSpan(days: 1))]
#[Asynchronous('async')]
#[EventHandler(endpointId: 'cancelUnpaidOrder')]
public function cancelIfUnpaid(
OrderWasPlaced $event,
OrderRepository $orderRepository
): void
{
$order = $orderRepository->get($event->orderId);
if ($order->isPaid()) {
return; // Payment arrived, nothing to do
}
$order->cancel('Payment not received within 24 hours');
$orders->save($order);
}
```
That's it. When an order is placed, this handler gets scheduled to run exactly 24 hours later, for specific Order. No polling, no custom scripts and cron jobs.
> If your requirement is 'do X after Y time passes,' you don't need workflow. You need a delayed action: one handler, one attribute, zero state management.
With Ecotone multiple Handlers can subscribe to same Event with different timings
```php
// Process payment immediately
#[Asynchronous('payments')]
#[EventHandler(endpointId: 'processPayment')]
public function processPayment(OrderWasPlaced $event): void
{
// Executes immediately
}
// Send confirmation after 30 minutes (gives time for payment processing)
#[Delayed(new TimeSpan(minutes: 30))]
#[Asynchronous('notifications')]
#[EventHandler(endpointId: 'sendConfirmation')]
public function sendOrderConfirmation(OrderWasPlaced $event): void
{
// Executes 30 minutes later
}
// Follow up if not shipped after 3 days
#[Delayed(new TimeSpan(days: 3))]
#[Asynchronous('notifications')]
#[EventHandler(endpointId: 'shippingReminder')]
public function remindAboutShipping(OrderWasPlaced $event): void
{
// Executes 3 days later
}
```
Each handler operates independently. If the shipping reminder fails, it doesn't affect payment processing. If you need to change the confirmation delay from 30 minutes to an hour, you modify one attribute—no migration scripts, no configuration files to update.
Basically the most common problem we may face - delayed action, becomes solved by putting single attribute on top of the method.
### Dynamic Delays for Real Business Logic
Sometimes the delay isn't fixed. Subscription renewals depend on billing cycles. Delivery timeouts vary by shipping method. Ecotone supports expression language for runtime calculation:
```php
#[Delayed(expression: 'payload.getRenewalDate()')]
#[Asynchronous('subscriptions')]
#[EventHandler(endpointId: 'processRenewal')]
public function renewSubscription(SubscriptionWasCreated $event): void
{
// Triggers at the DateTime returned by getRenewalDate()
}
```
We could even delegate calculating the delay to external Service available in our Dependency Container
```php
#[Delayed(expression: "reference('delayingService').calculate(payload.id))]
#[Asynchronous('subscriptions')]
#[EventHandler(endpointId: 'processRenewal')]
public function renewSubscription(SubscriptionWasCreated $event): void
{
// Triggers at the DateTime returned by getRenewalDate()
}
```
This pattern handles an enormous range of "do something later" requirements without any workflow infrastructure. Before reaching for state machines or saga patterns, ask yourself: **is this actually a multi-step process, or just a delayed action?**
## Stateless Workflows: When Steps Must Flow Together
Some processes genuinely require multiple steps that must execute in sequence. Image processing pipelines. Data validation flows. Multi-stage approval processes where each stage transforms the data for the next.
The instinct here is often to reach for a state machine. Tomas Votruba, creator of Rector, [voiced what many feel about that path](https://tomasvotruba.com/blog/how-we-maintain-dozens-of-symfony-workflows-with-peace?ref=blog.ecotone.tech):
> *"Yet, there is not a single post about how terrible the configuration is... Workflows configuration with a fractal array of strings. It's like a minefield for a developer who's tasked with adding a new line there."*
>
> *"I've seen 700+ lines long definitions and I'm scared to even look at it."*
The problem with state machines for workflows is fundamental: **state machines focus on state, not behavior**. The actual business logic—the thing you're building the workflow for—gets pushed to the edges, scattered across transition event handlers.
Ecotone offers a different approach: stateless workflows based on Input and Output - meaning **Pipe and Filters approach**. Instead of storing workflow state in a database, each message carries its own routing information. No workflow tables to manage. No cleanup procedures. No migrations when logic changes. No huge configuration files.
Here's an image processing pipeline:
```php
class ImageProcessingWorkflow
{
#[CommandHandler('process.image', outputChannelName: 'validate.image')]
public function startProcessing(ProcessImage $command): ProcessImage
{
return $command;
}
#[InternalHandler(
inputChannelName: 'validate.image',
outputChannelName: 'resize.image'
)]
public function validateImage(ProcessImage $command): ProcessImage
{
if (!$this->isValidFormat($command->imageData)) {
throw new InvalidImageException('Unsupported image format');
}
return $command;
}
#[InternalHandler(
inputChannelName: 'resize.image',
outputChannelName: 'upload.image'
)]
public function resizeImage(ProcessImage $command): ProcessImage
{
$resized = $this->imageService->resize(
$command->imageData,
$command->targetWidth,
$command->targetHeight
);
return $command->withImageData($resized);
}
#[InternalHandler(inputChannelName: 'upload.image')]
public function uploadImage(ProcessImage $command): void
{
$this->storage->upload($command->imageData, $command->targetPath);
}
}
```
The `#[InternalHandler]` attribute creates handlers that aren't exposed via the Command Bus—they're internal to the workflow. Messages flow from one step to the next through the `outputChannelName` connections.
### Adding Asynchronous Processing to Workflow Steps
Any step can become asynchronous by adding the `#[Asynchronous]` attribute:
```php
#[Asynchronous('image-processing')]
#[InternalHandler(
inputChannelName: 'resize.image',
outputChannelName: 'optimize.image'
)]
public function resizeImage(ProcessImage $command): ProcessImage
{
// Now processed asynchronously
}
```
This is powerful for pipelines where some steps are fast (validation) and others are slow (resizing large images). The slow steps can run on dedicated workers without blocking the fast ones.
## Orchestrators: When Workflow Definition Should Be Separate from Steps
The input/output channel approach works well, but the workflow definition is embedded in each handler's `outputChannelName`. For complex workflows with many steps, conditional branching, or runtime variations, Ecotone provides **Orchestrators**.
With Orchestrators, the workflow definition becomes explicit and separate from step implementation:
```php
class OrderOrchestrator
{
#[Orchestrator(inputChannelName: 'process.order')]
public function processOrder(Order $order): array
{
return [
'validate.order',
'process.payment',
'reserve.inventory',
'send.confirmation',
'audit.transaction'
];
}
}
```
**The business process becomes the code itself.** Each step then is implemented as a focused, testable handler:
```php
class OrderProcessingSteps
{
#[InternalHandler(inputChannelName: 'validate.order')]
public function validateOrder(OrderData $order): OrderData
{
if (!$order->hasItems()) {
throw new InvalidOrderException('Order must contain items');
}
return $order;
}
#[Asynchronous("async")]
#[InternalHandler(inputChannelName: 'process.payment')]
public function processPayment(OrderData $order, PaymentService $paymentService): OrderData
{
$result = $paymentService->charge($order->getTotal());
return $order->markAsPaid($result->getTransactionId());
}
#[InternalHandler(inputChannelName: 'reserve.inventory')]
public function reserveInventory(OrderData $order, InventoryService $inventory): OrderData
{
$inventory->reserve($order->getItems());
return $order->markAsReserved();
}
}
```
### Dynamic Workflows: Runtime Decisions
Real business processes aren't static. Customer types evolve, regulations change, new requirements emerge. Orchestrators handle this naturally:
```php
#[Orchestrator(inputChannelName: 'process.order')]
public function processOrder(OrderData $order): array
{
$workflow = ['validate.order', 'process.payment'];
// Premium customers get additional steps
if ($order->getCustomer()->isPremium()) {
$workflow[] = 'apply.premium.discount';
$workflow[] = 'priority.inventory.check';
if ($order->getTotal() > 1000) {
$workflow[] = 'executive.approval';
}
}
// International orders need customs documentation
if ($order->isInternational()) {
$workflow[] = 'customs.documentation';
$workflow[] = 'international.shipping.calculation';
}
$workflow[] = 'reserve.inventory';
$workflow[] = 'send.confirmation';
return $workflow;
}
```
The same orchestrator elegantly handles premium customers, international orders, high-value transactions—each with their specific requirements clearly expressed and easily modifiable. What steps will Workflow trigger, can be easily tested in isolation, ensuring dynamic flow for given scenarios follow given path.
### Orchestrator Gateways: API-Driven Workflows
For maximum flexibility, Orchestrator Gateways allow constructing workflows entirely at runtime based on external input:
```php
interface DocumentProcessingGateway
{
#[OrchestratorGateway]
public function processDocument(array $steps, Document $document): ProcessingResult;
}
```
Now your API can accept workflow definitions from clients:
```php
class DocumentController
{
public function __construct(
private DocumentProcessingGateway $gateway
) {}
public function processDocument(Request $request): JsonResponse
{
$document = Document::fromRequest($request);
// Build workflow based on request parameters
$steps = ['validate.document', 'extract.content'];
if ($request->get('requires_approval')) {
$steps[] = 'legal.review';
if ($document->getValue() > 100000) {
$steps[] = 'executive.approval';
}
}
if ($request->get('priority') === 'urgent') {
$steps[] = 'priority.processing';
}
$steps[] = 'finalize.document';
// Execute the dynamically built workflow
$result = $this->gateway->processDocument($steps, $document);
return new JsonResponse(['status' => $result->getStatus()]);
}
}
```
This enables A/B testing workflow variations, customer-specific processing, and feature flags—all without code changes.
## Sagas: When State Must Persist Across Events
Order fulfillment. Subscription management. Approval workflows with human-in-the-loop steps. These processes share a common characteristic: **they must track state over time and react to events that arrive in unpredictable order**.
An order might receive payment confirmation before inventory reservation completes. A subscription renewal might fail, requiring retry logic that remembers how many attempts have been made. An approval process might wait days for a manager's response.
Richard McDaniel, creator of Laravel Workflow, [described discovering Temporal for these problems](https://dev.to/rmcdaniel/from-idea-to-1000-stars-how-laravel-workflow-took-off-bb?ref=blog.ecotone.tech):
> *"Their PHP SDK was a breath of fresh air. You could write workflows like regular PHP code, yield async steps, and the system would magically resume where it left off. It was elegant... I was sold."*
Then came the reality check:
> *"I pitched it to the DevOps team. And hit a brick wall. They stared at me like I'd suggested launching a spaceship to run PHP jobs. Temporal required a Kubernetes cluster or a subscription to their cloud service."*
This tension—between Temporal's powerful durability model and PHP ecosystem realities—is real. Ecotone's Saga pattern offers a middle ground: stateful workflow coordination without external infrastructure dependencies.
### Building a Saga
A Saga is a PHP class with an identifier that persists state across events:
```php
#[Saga]
final class OrderFulfillmentProcess
{
use WithEvents;
#[Identifier]
private string $orderId;
private OrderStatus $status;
private bool $paymentReceived = false;
private bool $inventoryReserved = false;
private int $paymentRetryCount = 0;
private function __construct(string $orderId)
{
$this->orderId = $orderId;
$this->status = OrderStatus::PLACED;
}
#[EventHandler]
public static function startWhen(OrderWasPlaced $event): self
{
return new self($event->orderId);
}
#[EventHandler]
public function whenPaymentSucceeded(PaymentWasSuccessful $event): void
{
$this->paymentReceived = true;
$this->tryToFulfill();
}
#[EventHandler]
public function whenInventoryReserved(InventoryWasReserved $event): void
{
$this->inventoryReserved = true;
$this->tryToFulfill();
}
private function tryToFulfill(): void
{
if ($this->paymentReceived && $this->inventoryReserved) {
$this->status = OrderStatus::READY_FOR_SHIPMENT;
$this->recordThat(new OrderReadyForShipment($this->orderId));
}
}
}
```
The Saga starts when `OrderWasPlaced` is published. It then listens for `PaymentWasSuccessful` and `InventoryWasReserved` events—which might arrive in any order. Only when both conditions are met does it transition to `READY_FOR_SHIPMENT`.
After that we can either send a Command using Command Bus, or simply record an Event from within the Saga, which relates subscribes can react on.
### Timeouts and Deadlines
Sagas can enforce business deadlines by combining event handlers with delays:
```php
#[Delayed(new TimeSpan(days: 7))]
#[Asynchronous('async')]
#[EventHandler(endpointId: 'orderTimeout')]
public function handleOrderTimeout(OrderWasPlaced $event): void
{
if ($this->status === OrderStatus::PLACED) {
$this->status = OrderStatus::CANCELLED;
$this->recordThat(new OrderWasCancelled(
$this->orderId,
'Order not completed within 7 days'
));
}
}
```
Seven days after order placement, this handler checks if the order is still in `PLACED` status. If so, it cancels. If the order already progressed, the check passes harmlessly.
### Event Correlation
Ecotone automatically correlates events to Sagas when property names match. The `OrderWasPlaced` event has an `orderId` property; the Saga has an `#[Identifier]` property named `orderId`. Ecotone routes the event to the correct Saga instance automatically.
For events with different property names, use **identifierMapping**.
```php
#[EventHandler(identifierMapping: ['orderId' => 'payload.id']))]
public function handleOrderTimeout(OrderWasPlaced $event): void
{
if ($this->status === OrderStatus::PLACED) {
$this->status = OrderStatus::CANCELLED;
$this->recordThat(new OrderWasCancelled(
$this->orderId,
'Order not completed within 7 days'
));
}
}
```
Now `orderReference` maps to the Saga's `orderId` identifier. We could also use metadata header, or execute Service from Dependency Container to do the mapping.
## Testing Without the Pain
A common lament in PHP developer forums captures the testing dilemma perfectly: *"You want to test that unpaid orders get cancelled after 24 hours. Your options: mock everything until the test proves nothing, or actually wait 24 hours."*
Ecotone provides `EcotoneLite` for testing workflows with simulated time:
```php
public function test_order_cancelled_after_24_hours_without_payment(): void
{
$orderId = Uuid::uuid4()->toString();
$testSupport = EcotoneLite::bootstrapFlowTesting([
OrderFulfillmentProcess::class
], enableAsynchronousProcessing: true);
$testSupport
->publishEvent(new OrderWasPlaced($orderId))
->releaseAwaitingMessagesAndRunConsumer(
'async',
releaseAwaitingFor: new TimeSpan(days: 1)
);
$events = $testSupport->getRecordedEvents();
$this->assertContainsInstanceOf(
OrderWasCancelled::class,
$events
);
}
```
The `releaseAwaitingFor` parameter simulates time passage for delayed messages. Tests run in milliseconds while verifying behavior that would take 24 hours in production. In-memory channels replace RabbitMQ or database queues, making tests fast, deterministic, and infrastructure-independent.
## Choosing the Right Pattern
The three patterns address different levels of process complexity:
**Delayed Messages** work for standalone scheduled actions:
- Send reminder email after 3 days
- Cancel unpaid order after 24 hours
- Retry failed API call with exponential backoff
- Trigger subscription renewal at billing date
No workflow state needed—just defer a single handler's execution.
**Pipe&Filters and Orchestrators** (Stateless Workflows) fit sequential pipelines:
- Image processing (validate → resize → optimize → upload)
- Data import (parse → validate → transform → store)
- Document generation (gather data → render → convert → deliver)
Messages carry their routing; no database involvement in workflow progression.
**Sagas** (Stateful Workflow) handle complex coordination:
- Order fulfillment with payment, inventory, and shipping
- Subscription management with billing cycles and grace periods
- Approval workflows with multiple human decision points
- Any process where events arrive in unpredictable order
State persists across events; decisions depend on accumulated context.
The key insight: **start with the simplest pattern that handles your requirements**. Most "workflow" needs are actually delayed actions. Many multi-step processes are stateless pipelines. Reserve Sagas for genuine coordination challenges.
## Conclusion
At the beginning of this article, I stated that you don't need workflows. This relates to what's typically understood as workflow architecture—stateful solutions running on state machines or external services.
You shouldn't need a Kubernetes cluster to cancel unpaid orders after 24 hours. You shouldn't fear adding a step because the config file is already 400 lines. You shouldn't be in need to maintain different versions of workflows for most common cases.
Delayed messages, the Pipes & Filters approach, and Orchestrators will solve most business workflows in a stateless way—without cron polling, without workflow tables, without infrastructure your DevOps team will reject. And when genuine complexity demands it, Sagas let you handle workflows statefully while keeping the same declarative style.
Having these different tools in your toolkit means choosing the right abstraction for the problem, not forcing every process through the same heavyweight machinery. Start simple. Add complexity only when the business requires it.
### Your Legacy PHP Codebase Isn't Hopeless
URL: https://blog.ecotone.tech/your-legacy-php-codebase-isnt-hopeless/
Last updated: 2026-01-26T14:32:18.000Z
You open a file that should be a simple list of functions and find a 2,000-line monolith of nested loops and if-statements. Comments like `// Temporary fix` from years before. Presentation, database queries, and business logic living together in what one developer described as a "glorious spaghetti mashup."
You ship a small bug fix. Suddenly, two other features break. Every deployment feels like gambling. The business depends on this app—it brings in revenue, customers use it daily—but nobody feels confident working on it.
**Well, you're not alone. And your codebase isn't hopeless.**
## The Industry's Dirty Secret
Let's start with some numbers based on Composer Statistics, to see where we are standing as PHP community:
- **\~13% of Composer installs** are still running completely end-of-life PHP versions (7.x and 8.0)
- **\~27% are on EOL** or security-only versions (including PHP 8.1)
- **Over 50% of the top 1,000 PHP packages** still support PHP versions that no longer receive security updates
This isn't a "you" problem. This is an industry-wide condition. The codebase you inherited? Someone wrote it under deadline pressure with the tools and knowledge they had at the time. The mess you're maintaining? It grew organically over years, touched by dozens of hands, with employee turnover erasing institutional knowledge along the way.
The original developers weren't bad. They were trying to ship. Just like you.
> The legacy software modernization market is projected to reach **$27.3 billion by 2029**
> ResearchAndMarkets.com Report
## The Trap: Rewrite or Suffer
When developers hit a certain threshold of pain, they start dreaming of rewrites. A fresh start. Freedom from technical debt. Modern frameworks from day one. Elegant solutions unburdened by historical compromises.
But the data on rewrites is sobering:
- According to the [Standish Group CHAOS Report](https://cdn1-public.infotech.com/agile/CHAOSReport2015-Final.pdf?ref=blog.ecotone.tech), projects developed from scratch have only a **23% success rate**, *which equals the failure rate*. The remaining 54% are problematic (over budget, late, or reduced scope)
- A [McKinsey/Oxford study of 5,400 IT projects](https://www.mckinsey.com/capabilities/tech-and-ai/our-insights/delivering-large-scale-it-projects-on-time-on-budget-and-on-value?ref=blog.ecotone.tech) found that **17% of large IT projects go so badly they threaten the company's very existence**, with average overruns of 45% over budget and delivering 56% less value than predicted
- The same Standish data reveals small, **incremental changes have only a 4% failure rate**
Joel Spolsky famously called rewrites "*the single worst strategic mistake that any software company can make.*" The crufty-looking parts of your codebase often embed hard-earned knowledge about corner cases and weird bugs. Every "temporary fix from 2014" likely solved a real problem that will resurface in your shiny rewrite.
So you're stuck: rewrite and face those odds, or suffer indefinitely?
**There's a third option.**
## The Third Path: Incremental Transformation
What if you could modernize your codebase one method at a time, keeping the system running throughout? What if you could introduce enterprise patterns—CQRS, message-driven architecture, proper testing—without a feature freeze?
This is what we'll explore. And we'll use concrete examples with Ecotone, a PHP framework designed specifically for this incremental journey.
The approach is simple:
1. **Identify a painful area** of your codebase
2. **Extract that logic** into a message handler using a simple attribute
3. **Test it in isolation** with zero infrastructure
4. **Switch it to async** when needed—with a single line change
5. **Repeat**
Let's see what this looks like in practice.
## Example 1: The 800-Line Order Controller
Here's what legacy code typically looks like. Maybe this feels familiar:
```php
class OrderController
{
public function placeOrder(Request $request)
{
// 50 lines of validation
$data = $request->all();
if (empty($data['customer_id'])) {
return response()->json(['error' => 'Customer required'], 400);
}
// ... more validation ...
// 100 lines of order creation
$order = new Order();
$order->customer_id = $data['customer_id'];
$order->status = 'pending';
$order->created_at = date('Y-m-d H:i:s');
// ... assign 15 more fields ...
DB::beginTransaction();
try {
$order->save();
// 80 lines of inventory check
foreach ($data['items'] as $item) {
$product = Product::find($item['product_id']);
if ($product->stock < $item['quantity']) {
throw new \Exception('Insufficient stock');
}
$product->stock -= $item['quantity'];
$product->save();
$orderItem = new OrderItem();
// ... more assignments ...
$orderItem->save();
}
// 60 lines of payment processing
$paymentGateway = new PaymentGateway(config('payment.key'));
$result = $paymentGateway->charge(
$data['payment_token'],
$order->total
);
if (!$result->success) {
throw new \Exception($result->error);
}
$order->payment_id = $result->transaction_id;
$order->status = 'paid';
$order->save();
// 40 lines of notification
$customer = Customer::find($data['customer_id']);
Mail::send('emails.order-confirmation', [
'order' => $order,
'customer' => $customer
], function ($message) use ($customer) {
$message->to($customer->email);
$message->subject('Order Confirmation');
});
// 30 lines of analytics
Analytics::track('order_placed', [
'order_id' => $order->id,
'total' => $order->total,
'items_count' => count($data['items'])
]);
// 20 lines of loyalty points
$customer->loyalty_points += floor($order->total / 10);
$customer->save();
DB::commit();
return response()->json(['order_id' => $order->id]);
} catch (\Exception $e) {
DB::rollback();
Log::error('Order failed: ' . $e->getMessage());
return response()->json(['error' => $e->getMessage()], 500);
}
}
}
```
This controller does at least 7 different things:
- Validation
- Order creation
- Inventory management
- Payment processing
- Email notifications
- Analytics tracking
- Loyalty points calculation
Testing it requires a real database, a payment gateway, an email server, and analytics integration. One bug in loyalty points affects the entire order flow. Sending emails synchronously slows down the response. And good luck understanding this six months from now.
## Step 1: Identify the First Extraction
Don't try to fix everything at once. Pick **one piece** that causes pain. Let's start with the notification—it's slow, and if it fails, should it really prevent the order from completing?
First, we create a simple event and handler:
```php
// The event: a simple data object
class OrderWasPlaced
{
public function __construct(
public readonly string $orderId,
public readonly string $customerId,
public readonly float $total
) {}
}
// The handler: focused on one thing
class OrderNotificationHandler
{
public function __construct(
private Mailer $mailer,
private CustomRepository $customerRepository,
) {}
#[EventHandler]
public function sendConfirmation(OrderWasPlaced $event): void
{
$customer = $this->customerRepository->find($event->customerId);
$this->mailer->send('emails.order-confirmation', [
'orderId' => $event->orderId,
'customerName' => $customer->name,
'total' => $event->total
], $customer->email);
}
}
```
That's it. One attribute: `#[EventHandler]`. Ecotone discovers it automatically. No configuration files. No service registration boilerplate.
We can extract Interfaces for Mailer and CustomerRepository which under the hood will call our `Mailer::send` or `Customer::find` which will make our testing a bit easier in next steps. But if your tooling has ability to mock those even with static methods, then we will be fine without interfaces here.
## Step 2: Publish the Event from Your Existing Code
Now modify your existing controller minimally:
```php
class OrderController
{
public function __construct(
private EventBus $eventBus // Injected by Ecotone
) {}
public function placeOrder(Request $request)
{
// ... all your existing code ...
// Publish the event (one line added)
$this->eventBus->publish(new OrderWasPlaced(
$order->id,
$customer->id,
$order->total
));
DB::commit();
return response()->json(['order_id' => $order->id]);
}
}
```
Your legacy code still works exactly as before. But now the notification logic lives in its own class, with clear dependencies, doing one thing well.
## Step 3: Test It in Isolation
Here's where the magic happens. That notification handler? You can test it **right now**, without Docker, without RabbitMQ, without a running application:
```php
class OrderNotificationHandlerTest extends TestCase
{
public function test_sends_confirmation_email_when_order_placed(): void
{
// Arrange: set up test doubles
$customerRepository = $this->createMock(CustomerRepository::class);
$customerRepository->method('find')
->willReturn(new Customer(
id: 'cust-123',
name: 'John Doe',
email: 'john@example.com'
));
$mailer = $this->createMock(Mailer::class);
// Expect: the mailer should be called with correct params
$mailer->expects($this->once())
->method('send')
->with(
'emails.order-confirmation',
$this->callback(fn($data) =>
$data['orderId'] === 'order-456' &&
$data['customerName'] === 'John Doe'
),
'john@example.com'
);
// Act: run through Ecotone's test harness
$messaging = EcotoneLite::bootstrapFlowTesting(
[OrderNotificationHandler::class],
[
CustomerRepository::class => $customerRepository,
Mailer::class => $mailer
]
);
$messaging->publishEvent(new OrderWasPlaced(
orderId: 'order-456',
customerId: 'cust-123',
total: 99.99
));
// Assert: verification happens in the mock expectation
}
}
```
Your tests run in **milliseconds**. No database. No message queue. No external services. Just pure business logic verification.
## Step 4: Switch to Async (One Line)
Your notification works. It's tested. Now you want to make it asynchronous so it doesn't slow down the order response. Add **one attribute**:
```php
class OrderNotificationHandler
{
#[Asynchronous('notifications')] // ← That's it
#[EventHandler]
public function sendConfirmation(OrderWasPlaced $event): void
{
// Exactly the same code
}
}
```
Configure the channel once for your entire application:
```php
class MessagingConfiguration
{
#[ServiceContext]
public function asyncChannels(): array
{
return [
// Start with database queue (no extra infrastructure)
DbalBackedMessageChannelBuilder::create('notifications'),
// Or use RabbitMQ when ready
// AmqpBackedMessageChannelBuilder::create('notifications'),
];
}
}
```
**Your tests still pass with one small change now.** Ecotone's `bootstrapFlowTesting` handles both cases async and synchronous calls:
```php
$messaging = EcotoneLite::bootstrapFlowTesting(
[OrderNotificationHandler::class],
[
CustomerRepository::class => $customerRepository,
Mailer::class => $mailer
],
enableAsynchronousProcessing: true,
);
$messaging->publishEvent(new OrderWasPlaced(
orderId: 'order-456',
customerId: 'cust-123',
total: 99.99
));
$messaging->run('notifications'); // this will trigger our Notification Handler
```
## Step 5: Repeat for Each Concern
Now extract the next piece.
Analytics tracking:
```php
class AnalyticsHandler
{
#[Asynchronous('analytics')]
#[EventHandler]
public function trackOrderPlaced(OrderWasPlaced $event): void
{
Analytics::track('order_placed', [
'order_id' => $event->orderId,
'total' => $event->total
]);
}
}
```
Loyalty points:
```php
class LoyaltyPointsHandler
{
#[EventHandler]
public function awardPoints(OrderWasPlaced $event): void
{
$points = (int) floor($event->total / 10);
$customer->loyalty_points += $points;
$customer->save();
}
}
```
Each extraction makes your system more:
- **Testable** (isolated units with clear dependencies)
- **Understandable** (one class, one responsibility)
- **Resilient** (failures in analytics don't break orders)
- **Flexible** (easy to swap implementations)
> Each Asynchronous Event Handler receives copy of OrderWasPlaced Event Message. This means, if it fails - it fails in full isolation, and retries will not affect any other Handler.
## The Bigger Picture: Extracting Command Handlers
Events are great for side effects. But what about the core business logic? Let's tackle the order creation itself.
The approach is the same: **move first, improve later**. Don't rewrite — relocate.
### Step A: Create the Command (Just a Data Bag)
```php
class PlaceOrder
{
public function __construct(
public readonly string $customerId,
public readonly array $items,
public readonly string $paymentToken
) {}
}
```
### Step B: Move Your Existing Code Into a Handler
Here's the key insight: **you don't need to refactor the code yet**. Just move it:
```php
class OrderHandler
{
public function __construct(private EventBus $eventBus) {}
#[CommandHandler]
public function placeOrder(PlaceOrder $command): string
{
// Check inventory (yes, still hitting DB directly - that's fine for now)
foreach ($command->items as $item) {
$product = DB::table('products')
->where('id', $item['product_id'])
->lockForUpdate()
->first();
if ($product->stock < $item['quantity']) {
throw new \Exception("Insufficient stock for {$product->name}");
}
DB::table('products')
->where('id', $item['product_id'])
->decrement('stock', $item['quantity']);
}
// Calculate total (same ugly loop as before)
$total = 0;
foreach ($command->items as $item) {
$product = DB::table('products')->find($item['product_id']);
$total += $product->price * $item['quantity'];
}
// Create order record
$orderId = DB::table('orders')->insertGetId([
'customer_id' => $command->customerId,
'total' => $total,
'status' => 'pending',
'created_at' => now()
]);
// Process payment (still using that old PaymentService)
$paymentService = app(PaymentService::class);
$result = $paymentService->charge($command->paymentToken, $total);
DB::table('orders')
->where('id', $orderId)
->update(['status' => 'paid', 'transaction_id' => $result['id']]);
// Publish event (this triggers all those handlers we extracted earlier)
$this->eventBus->publish(new OrderWasPlaced($orderId, $command->customerId, $total));
return $orderId;
}
}
```
Yes, it's still messy. **That's okay.** You've achieved something important:
- The logic is now in an isolated class
- It publishes `OrderWasPlaced`, triggering all those handlers we extracted earlier
- It's testable with `EcotoneLite::bootstrapFlowTesting()`
- The controller no longer knows how orders work
*(Note: The `app(PaymentService::class)` call isn't ideal — you'd eventually inject it through the constructor. But for now, the existing code works and that's what matters.)*
```php
class OrderController
{
public function __construct(private CommandBus $commandBus) {}
public function placeOrder(Request $request): JsonResponse
{
$orderId = $this->commandBus->send(new PlaceOrder(
customerId: $request->input('customer_id'),
items: $request->input('items'),
paymentToken: $request->input('payment_token')
));
return response()->json(['order_id' => $orderId]);
}
}
```
**That's it.** Your controller is now 10 lines. The business logic lives in a command handler that you can test and improve independently.
You could wrap it in the Database transaction if required, but if you install Ecotone's dbal Module, all Command Handlers and inner Event Handlers will wrapped by transaction by default - therefore we don't need to do so.
### Step C: Refactor When You're Ready (Not Before)
Now that the code is extracted, you can improve it incrementally:
- Extract an `InventoryService` when you need to reuse stock logic
- Create an `OrderRepository` when you add a second handler that needs orders
- Write tests that cover this functionality
But none of that is required to get the benefits of testability and separation today.
### Step D: Testing the Complete Flow
Even with messy code, you can now test the **entire flow** synchronously:
```php
class OrderFlowTest extends TestCase
{
public function test_complete_order_flow(): void
{
$messaging = EcotoneLite::bootstrapFlowTesting([
OrderHandler::class,
OrderNotificationHandler::class,
AnalyticsHandler::class,
LoyaltyPointsHandler::class,
], [
// Provide test doubles for whatever services your code uses
PaymentService::class => new FakePaymentService(),
Mailer::class => new FakeMailer(),
]);
// Execute the command
$orderId = $messaging->sendCommand(new PlaceOrder(
customerId: 'cust-123',
items: [['product_id' => 'prod-1', 'quantity' => 2]],
paymentToken: 'tok_visa'
));
// Verify events were published
$events = $messaging->getRecordedEvents();
$this->assertCount(1, $events);
$this->assertInstanceOf(OrderWasPlaced::class, $events[0]);
$this->assertEquals($orderId, $events[0]->orderId);
( do other assertions )
}
}
```
At first we define list of classes taking part in this test suite. This is really powerful especially with a lot of dependencies and things happening in the flow. We limit only up to the point that actually want to test.
And in this scenario we test from the entrypoint which is Command, and we can assert any part of the logic that happens under the hood. Same event flow, same assertions—but in milliseconds, with no infrastructure - even for asynchronous processing.
## Handling Legacy Database Code
Ecotone has a pattern for raw SQL queries scattered everywhere too:
```php
// Before: SQL mixed with business logic
$orders = DB::select("
SELECT * FROM orders
WHERE customer_id = ?
AND status = 'pending'
ORDER BY created_at DESC
", [$customerId]);
// After: Declarative business interface
interface OrderQueries
{
#[DbalQuery(
"SELECT * FROM orders
WHERE customer_id = :customerId
AND status = 'pending'
ORDER BY created_at DESC"
)]
public function getPendingOrders(string $customerId): array;
#[DbalQuery(
"SELECT * FROM orders WHERE id = :orderId",
fetchMode: FetchMode::FIRST_ROW
)]
public function findById(string $orderId): ?array;
}
```
Ecotone implements the interface automatically. You get type safety, clear contracts, and testable code—while keeping your existing database schema.
You could directly type hint with result object and Ecotone will do the mapping, so we don't need to deal with arrays. The same works for collections of returned objects using docblocks:
```php
// After: Declarative business interface
interface OrderQueries
{
#[DbalQuery(
"SELECT * FROM orders
WHERE customer_id = :customerId
AND status = 'pending'
ORDER BY created_at DESC"
)]
/**
* @return PersonNameDTO[]
*/
public function getPendingOrders(string $customerId): array;
#[DbalQuery(
"SELECT * FROM orders WHERE id = :orderId",
fetchMode: FetchMode::FIRST_ROW
)]
public function findById(string $orderId): ?PersonNameDTO;
}
```
## Adding Resilience Without Rewriting
One of the biggest pain points with legacy code is error handling. What happens when the payment gateway times out? When the email server is down? When RabbitMQ loses connection?
With Ecotone, you add resilience declaratively:
```php
// Automatic retries
#[ServiceContext]
public function retryConfiguration(): array
{
return [
InstantRetryConfiguration::createWithDefaults()
->withCommandBusRetry(
enabled: true,
maxRetryAttempts: 3,
retryOnlyForExceptions: [
PaymentGatewayTimeout::class,
DatabaseConnectionException::class
]
)
];
}
```
For async handlers, failed messages go to a dead letter queue automatically:
```php
#[ServiceContext]
public function errorHandling(): array
{
return [
ErrorHandlerConfiguration::createWithDeadLetterChannel(
'errorChannel',
RetryTemplateBuilder::exponentialBackoff(
initialDelayMs: 1000,
multiplier: 2
)->maxRetryAttempts(5),
// if retry strategy will not recover, then send here
"dbal_dead_letter"
)
];
}
```
After 5 retries with exponential backoff, the message is stored in a dead letter table. You can review it, fix the bug, and replay it:
```php
# See what failed
php artisan ecotone:deadletter:list
# Check the details
php artisan ecotone:deadletter:show abc-123
# Replay after fixing the bug
php artisan ecotone:deadletter:replay abc-123
```
Your legacy code gets enterprise-grade resilience without a rewrite.
## The Deduplication Problem
Ever had duplicate orders because a user clicked twice or same webhook event was received twice? Or duplicate emails because a queue message was processed twice? Add one attribute:
```php
#[Deduplicated('orderId')]
#[CommandHandler]
public function placeOrder(PlaceOrder $command): string
{
// Automatically deduplicated based on orderId
// Second call with same orderId is silently ignored
}
```
Idempotency baked in. No manual tracking. No distributed locks to implement.
## Why This Works
The incremental approach succeeds because:
1. **The system keeps running.** No feature freeze. No parallel development of two systems.
2. **Each step is small.** A single handler extraction is a focused PR that reviewers can understand.
3. **Tests prove correctness.** Before you change behavior, you capture it in tests. Refactoring becomes safe.
4. **Value compounds.** Each extraction makes the next one easier. Patterns emerge. Developers learn.
5. **You can stop anytime.** Even if you only extract 30% of your code, that 30% is now testable and maintainable.
6. **Modern patterns attract talent.** CQRS, event-driven architecture, DDD—these are resume-worthy skills.
## Getting Started Today
You don't need permission for a big initiative. You don't need a roadmap approved. You need one composer command and one extraction.
```php
# Laravel
composer require ecotone/laravel
# Symfony
composer require ecotone/symfony-bundle
# Standalone
composer require ecotone/ecotone
```
The standalone can be used with any other Framework, therefore can be used even with internal frameworks.
> If you're working on legacy PHP that isn't supported by Ecotone's current version, you can install an older version and upgrade once you're ready. This works because Ecotone maintains a high-level declarative API that's decoupled from the framework internals. The API hasn't changed in over 5 years.
---
## Conclusion: Your Codebase Has a Future
Those legacy systems, despite their flaws, have been successfully running businesses for years. They deserve respect for their longevity—and they deserve a path forward.
The patterns you've seen in this article aren't theoretical. They're the same patterns used at scale by companies processing millions of messages. And they're accessible to any PHP developer, starting today, in any existing codebase.
You don't have to rewrite everything. You don't have to suffer indefinitely. You can transform your application one handler at a time, testing each step, shipping continuously, and actually enjoying the process.
Remember those numbers from the beginning? Projects rewritten from scratch have only a 23% success rate. Incremental modernization, on the other hand, has a 53% success rate and only a 9% failure rate.
**By choosing incremental transformation over a rewrite, you've already more than doubled your odds of success.** You've the tools and knowledge, so now it's your time to punch that 2,000-line controller right in the face. The odds are on your side—go and make it happen!
### Vibe coding Enterprise PHP Applications
URL: https://blog.ecotone.tech/vibe-coding-enterprise-php-applications/
Last updated: 2026-01-14T22:21:01.000Z
Everyone's talking about vibe coding — describing what you want in natural language and letting AI generate the code. Solo developers are shipping features in hours and Startups are prototyping before lunch.
But here's what nobody mentions at the demo stage: **most vibe-coded applications are architectural disasters waiting to happen.**
The AI produces code that runs. It does the thing. But under the surface:
- Business logic tangles with infrastructure
- There's no clear path to scaling
- Error handling assumes sunny days forever
- Testing is an afterthought — if it exists at all
- One change breaks three unrelated features
> AI learned from the internet, and most internet code is tutorial-grade: optimized for "make it work" rather than "make it last."
So vibe coders face an uncomfortable tradeoff: ship fast and pray, or slow down and learn architecture patterns that take years to master. But what if there's a third option? **What if the framework itself guided you toward good design — whether you understood it or not?**
## Enterprise Patterns Without the Enterprise Learning Curve
Enterprise patterns like: CQRS, Event Sourcing, Sagas, Workflows Message-Driven architecture — exist because they solve real problems at scale:
- **Event Sourcing** captures every change as immutable fact, enabling audits, replays, and debugging
- **Sagas and Workflows** coordinate complex processes across multiple services without distributed transactions
- **Message-driven architecture** decouples components so failures don't cascade
The traditional path to using these patterns:
1. Read the books
2. Try implementing them yourself
3. Fail, learn, try again
That's 2-3 years and several failed attempts to reach competency in those areas.
**Ecotone compresses this to a Composer install:**
```php
composer require ecotone/ecotone
```
**The patterns are baked in.** You don't implement CQRS — you use it. You don't build event sourcing infrastructure — you add an attribute. You don't build messaging integrations — you state **what**, and Ecotone handles **how**.
## Architecture That Guides, Not Just Enables
Ecotone is a PHP framework built on a radical idea: **enterprise patterns should be the default, not the exception.**
> Most frameworks give you tools and say "good luck." They don't guide you toward architecture that's scalable and fault-tolerant by design. Ecotone does — these qualities aren't features, they're the foundation.
Let's look at command handlers:
```php
#[CommandHandler]
public function placeOrder(PlaceOrder $command): void
{
// This method does ONE thing
}
```
This is one of Ecotone's key building blocks — the default way to expose business capabilities. But there's more than meets the eye. When you send a command like this, Ecotone under the hood:
- It connects to the Messaging System — meaning it can now be wrapped with powerful features like database transactions, message deduplication, and retries, using a simple config switch or an extra attribute.
- Every message automatically includes metadata: Message ID, Causation ID, and Correlation ID. This makes tracking and connecting to monitoring systems trivial.
- Since execution now flows through messaging, switching to asynchronous is as simple as adding a single \`#\[Asynchronous\]\` attribute.
In Ecotone, there is no other way to expose business capabilities than through Messaging. All applications, modules, and classes communicate through Messages — and this matters enormously for vibe coding. **The AI isn't fighting against bad habits in the training data. It's guided by a framework that makes the right path the easy path.**
## Vibe your way to Enterprise-Grade
Let's now take a look on example of Order Processing, and some key differences, based on what AI can generate for us.
### **Typical vibe-coded version (fragile):**
```php
class OrderController
{
public function placeOrder(Request $request)
{
$order = new Order($request->get('products'));
$this->orderRepository->save($order);
// Everything jammed together
$this->mailer->send($order->customerEmail(), 'Order confirmed!');
$this->inventory->decrease($order->products());
return new Response('Order placed!');
}
}
```
Problems:
- If the Invetory API is slow, the customer waits
- If email fails, the whole order fails
- Testing requires mocking everything
- Changing one thing risks breaking others
### **Ecotone version (enterprise-grade):**
```php
class OrderService
{
#[CommandHandler]
public function placeOrder(PlaceOrder $command): void
{
$order = new Order($command->orderId, $command->products);
$this->orderRepository->save($order);
$this->eventBus->publish(new OrderWasPlaced(
$order->id(),
$order->customerEmail(),
$order->products()
));
}
}
class NotificationService
{
#[Asynchronous('notifications')]
#[EventHandler]
public function onOrderPlaced(OrderWasPlaced $event): void
{
$this->mailer->send($event->customerEmail, 'Order confirmed!');
}
}
class InventoryService
{
#[Asynchronous('inventory')]
#[EventHandler]
public function onOrderPlaced(OrderWasPlaced $event): void
{
foreach ($event->products as $product) {
$this->inventory->decrease($product->id, $product->quantity);
}
}
}
```
What the Ecotone version gives you:
- **Immediate response** — customer doesn't wait for email servers
- **Failure isolation** — Inventory outage doesn't break orders
- **Independent scaling** — high notification volume? Add notification workers
- **Focused testing** — test `OrderService` without touching `NotificationService`
- **Self-documenting** — the attributes tell you what's async, what handles what
And here's the key insight: **the AI can generate both versions equally easily.** But only one of them will survive contact with production.
## Ensuring your Application works
Vibe coding without tests is like driving blindfolded.
The AI generates code. Does it work? You run it manually. It breaks.
You describe the error. The AI "fixes" it — often introducing new bugs.
You're now in a hallucination feedback loop.
**Tests break this cycle.**
When you have focused, fast tests, the AI gets immediate, precise feedback. Not "something's wrong somewhere" but "this specific assertion failed because this specific behavior changed."
However most testing approaches are terrible for vibe coding:
- **Integration tests** require setting up databases, queues, external services — massive friction
- **Async testing** means running actual workers, waiting, checking results — slow and flaky
- **Tightly coupled code** means testing one thing requires setting up ten unrelated things
Ecotone solves all of this:
### Testing Isolation
Notice what's happening:
```php
public function test_order_placement_sends_notification(): void
{
$messagingSystem = EcotoneLite::bootstrapFlowTesting([
OrderService::class,
]);
$messagingSystem->sendCommand(new PlaceOrder(
orderId: '123',
products: ['widget']
));
$recordedEvents = $messagingSystem->getRecordedEvents();
$this->assertCount(1, $recordedEvents);
$this->assertInstanceOf(OrderWasPlaced::class, $recordedEvents[0]);
}
```
1. **Choose exactly which classes to test** — `OrderService` or more depending on scenario
2. **No meaningless side effects** — you're not setting up state for things you're not testing thanks to isolation
3. **Testing Input and Outputs** \- We sending Command, expecting Events, logic is encapsulated inside. Those kind of tests survive changes and refactors.
This is surgical testing. The AI can generate a test, run it, see exactly what failed, and fix precisely that thing.
### Testing Async Flows Synchronously
Ecotone lets you test asynchronous code and switch the components easily
```php
public function test_order_placement_sends_notification(): void
{
$mailer = new StubMailer();
$messagingSystem = EcotoneLite::bootstrapFlowTesting(
[
OrderService::class,
NotificationHandler::class,
],
[
new NotificationHandler(),
Mailer::class => $mailer
]
enableAsynchronousProcessing: true
);
$messagingSystem->sendCommand(new PlaceOrder(
orderId: '123',
products: ['widget']
));
$this->assertCount(0, $mailer->countMails());
$messagingSystem->run('async');
$this->assertCount(1, $mailer->countMails());
}
```
Notice what's happening:
1. **No queue workers** — async handlers execute synchronously in the test
2. **Easily replace actors** — We simply switched for this particular test case Mailer implementation
3. **Synchronous testing**— We are not in need to run Workers in other processes, we simply run the Worker from within the test
This is crucial for reliable testing that gives the output directly to the AI tool we use, as we don't run any external workers. Whatever fails - fails within this process, giving immediate feedback to the AI Model.
> **Vibe coding loves this.** When the AI generates code and immediately runs synchronous tests that complete in milliseconds, it can iterate rapidly toward correct behavior without spiraling into hallucinated "fixes."
## The Token Efficiency Advantage
Here's something that individual vibe coders care about deeply: **AI tokens cost money and time.** Every line of boilerplate the AI generates is:
- Tokens spent on infrastructure code instead of business logic
- More surface area for bugs
- More code to understand when things break
- Longer feedback loops
**Without Ecotone** — generating a message queue setup:
```php
// AI generates 50-100 lines of:
// - Queue connection configuration
// - Message serialization
// - Worker process management
// - Retry logic
// - Error logging
// ... and probably gets several things wrong
```
**With Ecotone** — same functionality:
```php
#[Asynchronous('orders')]
#[CommandHandler]
public function placeOrder(PlaceOrder $command): void
{
// Just business logic
}
```
*One attribute - the infrastructure is handled*. Ecotone will provide Worker Process to consume Messages, will set up Message Channel in the Broker, do deserialization and serialization, wiring if needed. This means that it's indeed single attribute, that handles all the complexity for you.
This means:
- **Fewer tokens burned** on boilerplate
- **Less code to generate** means fewer opportunities for hallucination
- **Faster feedback loops** because tests are simpler
- **No "guide the AI" dance** toward enterprise patterns — they're the default
When you're paying per token and waiting for responses, this efficiency compounds dramatically over a development session.
### All the infrastructure set up for you
Let's take a look on one more example, using Ecotone's Event Sourcing.
```php
#[EventSourcingAggregate]
class Wallet
{
#[Identifier]
private string $walletId;
private int $balance = 0;
#[CommandHandler]
public static function create(CreateWallet $command): array
{
return [new WalletWasCreated($command->walletId)];
}
#[CommandHandler]
public function deposit(DepositMoney $command): array
{
return [new MoneyWasDeposited($this->walletId, $command->amount)];
}
#[CommandHandler]
public function withdraw(WithdrawMoney $command): array
{
if ($command->amount > $this->balance) {
throw new InsufficientFunds();
}
return [new MoneyWasWithdrawn($this->walletId, $command->amount)];
}
#[EventSourcingHandler]
public function applyCreated(WalletWasCreated $event): void
{
$this->walletId = $event->walletId;
}
#[EventSourcingHandler]
public function applyDeposit(MoneyWasDeposited $event): void
{
$this->balance += $event->amount;
}
#[EventSourcingHandler]
public function applyWithdraw(MoneyWasWithdrawn $event): void
{
$this->balance -= $event->amount;
}
}
```
That's a complete audit trail of every financial transaction. And it takes zero infrastructure work, as Ecotone will bind this Aggregate to Event Stream, set up Event Streams in Database and serialize and deserialize Events for us.
**Meaning we can fully focus on the flow we vibe code, and the rest will be done for us.**
And I just have to show, how easy it's for AI Models to generate tests for this:
```php
public function test_wallet_tracks_balance(): void
{
$ecotone = EcotoneLite::bootstrapFlowTesting([Wallet::class]);
$ecotone->sendCommand(new CreateWallet('wallet-1'));
$ecotone->sendCommand(new DepositMoney('wallet-1', 100));
$ecotone->sendCommand(new DepositMoney('wallet-1', 50));
$ecotone->sendCommand(new WithdrawMoney('wallet-1', 30));
$events = $ecotone->getRecordedEvents();
$this->assertCount(4, $events);
$this->assertInstanceOf(WalletWasCreated::class, $events[0]);
$this->assertInstanceOf(MoneyWasDeposited::class, $events[1]);
$this->assertInstanceOf(MoneyWasDeposited::class, $events[2]);
$this->assertInstanceOf(MoneyWasWithdrawn::class, $events[3]);
}
```
## Why Ecotone + AI Works
Several factors make Ecotone unusually suited for vibe coding:
### 1\. Five Years of Stable API
Ecotone has maintained same API for user-land features since it was open sourced — meaning for five years. Ecotone due to it's design based on declarative configuration have allowed userland applications to grow decoupled from the framework and vice versa.
AI models learned from historical code. Frameworks that break APIs between versions create a problem: the AI learned the old way, but the old way does not work anymore.
### 2\. Enterprise Examples as Training Data
Most PHP examples online demonstrate basic CRUD. The AI learned from those, so it generates more of the same.
Ecotone's documentation, blog posts, examples has always demonstrated enterprise patterns. When AI generates Ecotone code, it reaches for CQRS and event-driven patterns because that's what Ecotone examples look like.
The training data is inherently higher quality.
### 3\. Constraints as Guardrails
Ecotone's design philosophy guides toward good architecture through constraints:
- Command is handled exactly one Handler — single-purpose by design
- Events are published, not returned — proper decoupling
- Async is declared, not implemented — consistent patterns
The AI can't easily generate antipatterns because the framework makes them awkward.
## Summary
Previously, there was a hard line between "startup code" and "enterprise code." Startups moved fast with fragile architectures. Enterprises moved slow with robust architectures. You picked your tradeoff.
Ecotone blurs this line. Enterprise patterns become a Composer install. And vibe coding lets anyone — regardless of architectural expertise — generate code that uses those patterns correctly.
> A solo developer with an AI assistant can now generate applications more robust and scalable than what many teams craft by hand over months.
**Now you can build systems like the big companies do.** Without their resources. Without even understanding how — at first.
The architecture is in the framework. The tests prove it works. The AI does the typing.
That's not cheating. That's evening the odds.
### Implementing Event-Driven Architecture in PHP
URL: https://blog.ecotone.tech/implementing-event-driven-architecture-in-php/
Last updated: 2025-12-26T16:40:58.000Z
Traditional service integration moves routing logic outside the application’s code.
Message brokers, cloud messaging services, and stream-processing topologies become the place where business-critical flows are defined.
However, this comes at a cost of making our **Endpoints - Dumb.**
## *Dumb Endpoints*
We often agree to move routing logic outside the application, because it promises simplicity or speed. It looks simpler because it looks like we no longer need to handle routing ourselves. From a developer’s perspective, we just receive and process a message, while routing happens “somewhere else” — outside the code.
> When important logic is pushed outside the application, the code becomes unaware of the integrations it depends on. This makes changes harder to test and verify. It also lowers confidence when making changes, because modifying something outside the application is always riskier than changing code we fully own and can easily cover with tests.
When we follow the *dumb endpoints* approach, where the application is unaware of routing logic, we eventually end up in a situation where:
1. **Knowledge becomes fragmented** — Only a few people truly understand the full setup and configuration that lives outside the applications being integrated.
2. **Testing becomes painful** — It is no longer easy to test behavior using automated application-level tests. Changes often require modifying external configurations, where testing and verifying correctness is much harder.
3. **Changes become risky** — When changes cannot be easily verified, confidence drops. This slows development and often leads to more bugs and production issues.
The state of the architecture is often accepted as it is, and the problems created by *dumb endpoints* are pushed onto developers. This often leads to situations where more “control” is introduced to prevent further issues — for example, by adding *gatekeepers* who must review and approve every change.
Ironically, this all starts with the promise of speed and simplicity, offered as a trade-off for moving integration logic outside the application.
However, we can achieve both speed and simplicity *while keeping integrations under the control of the application itself*. There is no trade-off required. To do this, we need to follow a different approach — one where **endpoints are no longer *dumb*, but become *smart*.**
## *Smart Endpoints - Dumb Pipes*
This leads us to the **Smart Endpoints, Dumb Pipes** approach.
It reverses the direction of responsibility — instead of moving logic outward, we move it back inward. Applications are no longer dumb. They become smart and decide where messages should go and where they should be consumed from. In this model, the application itself fully controls the integration.
> **To achieve smart endpoints we need to build the logic of routing inside our Applications**. This means using clear abstractions that allow us to orchestrate message flow within the code, rather than external configurations.
To make this possible, messaging needs to be a first-class citizen in our applications.
The messaging abstraction should provide routing capabilities that we can configure as needed and fully test from within the application. Ideally, this abstraction should be decoupled, meaning we are not forced to implement or extend any framework-specific classes.
*Enterprise Integration Patterns* is a great book that defines a set of abstractions for building messaging systems at the programming-language level. I brought these patterns to life in the **Ecotone Framework** **for PHP.**
In the next section, we will explore how to build integrations between applications using a higher-level abstraction built on top of these patterns — the **Service Map**.
## *Service Map*
Now that we’ve established that *smart endpoints* keep routing logic inside the application and provide messaging capabilities directly within the programming language, let’s explore how applications can actually be integrated.
To do this, we will look at one of Ecotone’s features — the **Service Map**.
Service Map is exactly what it sounds like—a map of integrated applications (services) and the pipes (channels) which they communicate through. Here's how to set it up:
```php
#[ServiceContext]
public function serviceMap(): DistributedServiceMap
{
return DistributedServiceMap::initialize()
->withCommandMapping(
targetServiceName: "ticketService",
channelName: "ticket_commands"
);
}
```
**This configuration says:** *"When sending Commands to Ticket Service, use ticket\_commands channel (pipe)"*
> The routing is done at the Application level, not the Message Broker level. This means that we control the process from within the codebase we own, and can easily cover that with tests.

This configuration is for sending Commands, for Event we will be using Event Mapping:
```php
#[ServiceContext]
public function serviceMap(): DistributedServiceMap
{
return DistributedServiceMap::initialize()
->withEventMapping(
channelName: "ticket_events",
subscriptionKeys: ["user.*"],
);
}
```
**This configuration says:** *"When publishing Events, when routing key start with `user` then ticket\_events channel (pipe)"*
Event Mapping allows us to publish Events to specific Channel (Pipe) based on subscription keys.

We can of course have multiple subscription to broadcast events to different Services.
## *Application Code*
With the map configured, publishing is straightforward.
### *Sending side*
For Commands, we target a specific service:
```php
public function onUserRegistered(
string $userId,
DistributedBus $distributedBus
): void {
$distributedBus->convertAndSendCommand(
targetServiceName: "ticketService",
routingKey: "ticket.create",
command: new CreateTicket($userId, "Welcome!")
);
}
```
For Events that multiple services might care about, we publish without a target:
```php
$distributedBus->convertAndPublishEvent(
routingKey: "user.registered",
event: new UserRegistered($userId)
);
```
> Ecotone makes this part of the API: **Commands are sent to a single service**, while **Events can be delivered to many services**.
> The Service Map automatically handles routing based on subscription keys.
### *Receiving side*
On the receiving side, we mark handlers as distributed to accept external messages:
```php
#[Distributed]
#[CommandHandler("ticket.create")]
public function createTicket(CreateTicket $command): void
{
// Create the ticket
}
#[Distributed]
#[EventHandler("user.registered")]
public function onUserRegistered(UserRegistered $event): void
{
// React to user registration
}
```
> The \`#\[Distributed\]\` attribute makes it explicit that these handlers can receive messages from other services. This clarity prevents accidental breaking changes.
I mentioned earlier that this approach does not require sacrificing speed.
We are not building our own integration infrastructure from scratch — instead, we reuse existing systems.
> The key idea is to keep the logic inside the application and treat pipes (channels) as simple transport.
> The channel’s only responsibility is to move messages, not to act as the “mastermind” of orchestration.
We have two message channels (pipes): **`ticket_commands`** and **`event_commands`**.
With the Service Map approach, we can define their implementations in a way that fits our needs, without being tightly coupled to a specific message broker.
This means we can choose — and later switch — the underlying technology if needed.
For example, we might decide to use RabbitMQ or Redis-based channels:
```php
#[ServiceContext]
public function channels()
{
return [
// Amazon SQS Message Channel
SqsBackedMessageChannelBuilder::create("ticket_events"),
// RabbitMQ Message Channel
AmqpBackedMessageChannelBuilder::create("ticket_commands"),
];
}
```
Defining Channel is enough for Ecotone to automatically register Message Consumer for us. From that point on, we can start consuming messages right away:
```bash
bin/console ecotone:run {ticket_commands/ticket_events}
```
## *Streaming Channels*
The Service Map works regardless of whether we use queue-based brokers or streaming platforms under the hood.
When using streaming platforms, we gain additional capabilities thanks to their non-destructive nature, which I described in a [previous blog post](https://blog.ecotone.tech/async-failure-recovery-queue-vs-streaming-channel-strategies/).
In the case of queue-based solutions, we can push messages to each channel as part of the publishing process:
```php
#[ServiceContext]
public function serviceMap(): DistributedServiceMap
{
return DistributedServiceMap::initialize()
->withEventMapping(
channelName: "ticket_events",
subscriptionKeys: ["user.*"],
)
->withEventMapping(
channelName: "order_events",
subscriptionKeys: ["user.*"],
);
}
```

Queue based Event Publishing
When using Kafka or RabbitMQ streaming channels, we can push messages to a single channel, from which multiple services can consume:
```php
#[ServiceContext]
public function serviceMap(): DistributedServiceMap
{
return DistributedServiceMap::initialize()
->withEventMapping(
channelName: "user_events",
subscriptionKeys: ["user.*"],
);
}
```

Multiple Application consuming from single Streaming Channel
Ecotone provides different Message Channels integrations:
- Streaming Channels: Kafka and RabbitMQ
- Queue Channels: RabbitMQ, Amazon SQS, Redis, Database Channels, Symfony Messenger, Laravel Queues
## *Decoupled Data Models*
All communication happens through defined routing keys, whether the message is a Command or an Event. This is intentional and helps keep applications decoupled from each other.
As a result, each application can use models that fit its own needs and include only the data that is truly meaningful from an integration perspective.
```php
// Publisher sends this
$distributedBus->convertAndPublishEvent(
routingKey: "user.billing.changed",
event: new BillingDetailsChanged($userId, $newAddress)
);
// Consumer can use different model
#[Distributed]
#[EventHandler("user.billing.changed")]
public function handle(UserAddressUpdated $event): void
{
// Different class, same routing key
}
```
> Whether models are shared or not should be a project-level decision.
> Ecotone does not force either approach, allowing teams to choose what works best for their specific context.
## Testing Integrations
One of the core ideas I mentioned earlier is making integrations testable at the application level. With Ecotone’s Service Map, we can test integrations using in-memory channels or real integrations, all directly from the application code:
```php
$messaging = EcotoneLite::bootstrapFlowTesting(
[ServiceMapConfig::class],
enableAsynchronousProcessing: [
// Define using which Channel you want to test
SimpleMessageChannelBuilder::createQueueChannel("ticket_commands"),
]
);
$messaging->convertAndSendCommand(
targetServiceName: "ticketService",
routingKey: "ticket.create",
command: new CreateTicket($userId, "Welcome!")
);
// Verify command landed in channel
$message = $messaging->getMessageChannel('ticket_commands')->receive();
$this->assertNotNull($message);
```
The same way we could test out consumption side of things. It's really easy to test any kind of Service Map and cover that with automated tests to ensure that delivery happens as we expect.
## *Other Supporting Features*
We did cover the core part of integration, however together with that Ecotone provides much more features, that ensures that integrations works as expected. For this you may consider exploring:
- Outbox pattern: For transactional consistency
- Dead letter queues: For failed message handling
- Message priorities: For urgent processing
- Scheduled messages: For delayed delivery
For this you may take a look on [Ecotone's documentation page](https://docs.ecotone.tech/?ref=blog.ecotone.tech).
## *Summary*
Choosing the **Smart Endpoints, Dumb Pipes** architecture allows us to take full control of the integration process and keep things simple, testable, and easy to verify for everyone.
The goal is to keep integration logic close to where it is actually used. This helps maintain shared knowledge and a clear understanding of how the system behaves as it evolves.
You can read more about about Service Map under [this link](https://docs.ecotone.tech/modelling/microservices-php/distributed-bus/distributed-bus-with-service-map?ref=blog.ecotone.tech).
Whatever you choose to use Ecotone to deliver this approach or build it yourself, feel free to join [Ecotone's community channel](https://discord.gg/GwM2BSuXeg?ref=blog.ecotone.tech) to discuss different approaches and share the experiences.
### Message Brokers in PHP: From Hundreds of Lines to Just a Few
URL: https://blog.ecotone.tech/message-brokers-in-php-few-lines-integration/
Last updated: 2025-12-14T09:38:05.000Z
Message broker integration in PHP can be wrestling with exchange declarations, queue bindings, consumer configurations, and endless boilerplate. Setting up RabbitMQ, Kafka, or SQS often takes more code than the actual business logic we're trying to run asynchronously.
**But what if that wouldn't need to be a case, what if we can build production ready asynchronous applications with few lines of code?**
## The Problem We've All Faced
Integration between PHP applications using message brokers can be challenging. We enter an area where many things can break and fail. Traditional setups require:
- Declaring exchanges and queues manually
- Configuring consumer acknowledgments
- Managing serialization/deserialization
- Handling connection failures
- Setting up retry mechanisms
Most developers spend hours just getting a basic message to flow through the system.
## Few Lines Is All You Need
With Ecotone Framework, setting up a RabbitMQ (or any other Broker integration) -requires only few lines of code for whole production ready consuming or publishing application.
It all starts with choosing the implementation provider for Asynchronous Message Channel:
```php
AmqpBackedMessageChannelBuilder::create('orders')
```
Let me show you a complete working example. First, define your command:
```php
class PlaceOrder
{
public function __construct(
public string $orderId,
public string $product
) {}
}
```
Then create your handler with the **\`#\[Asynchronous\]\`** attribute:
```php
class OrderHandler
{
#[Asynchronous('orders')]
#[CommandHandler(endpointId: 'orderHandler')]
public function handle(PlaceOrder $command): void
{
echo "Processing order: {$command->product}\n";
}
}
```
> Your business logic stays clean. The \`#\[Asynchronous('orders')\]\` attribute is all that connects your handler to the message broker.
Bootstrap whole Ecotone Application:
```php
$ecotone = EcotoneLite::bootstrap(
classesToResolve: [OrderHandler::class],
containerOrAvailableServices: [
new OrderHandler(),
/** Connection to Message Broker */
AmqpConnectionFactory::class => new AmqpConnectionFactory([
'dsn' => 'amqp://guest:guest@localhost:5672/%2f'
]),
],
configuration: ServiceConfiguration::createWithDefaults()
->withExtensionObjects([
/** We define Message Channel (could be Kafka, SQS etc)
AmqpBackedMessageChannelBuilder::create('orders'),
])
);
```
> That's it. No exchange declarations, no queue bindings, no consumer configuration, no serializations. Ecotone handles everything.
## Publisher
Then to publish all we need to do is to send the Command
```php
$ecotone->getCommandBus()->send(new PlaceOrder('123', 'Milk'));
```
This will go to asynchronous Message Channel
## Consumer
To run the Message Consumer, we will simply use **"run"** method on the Ecotone Application:
```php
$ecotone->run('async');
```
That will run the Consumer and start consuming Messages.
## Serialization Works Out of the Box
```php
$ecotone->getCommandBus()->send(new PlaceOrder('123', 'Milk'));
```
Notice how we're sending a proper PHP object, not a JSON string or array? Ecotone automatically handles serialization when publishing and deserialization when consuming:

## *Switch Message Brokers in Seconds*
Here's where it gets interesting. Want to use Kafka instead of RabbitMQ? Just change one line:
- **RabbitMQ:** `AmqpBackedMessageChannelBuilder::create('orders')`
- **Amazon SQS:** `SqsBackedMessageChannelBuilder::create('orders')`
- **Redis:** `RedisBackedMessageChannelBuilder::create('orders')`
- **Kafka:**`KafkaMessageChannelBuilder::create('orders')`
- **Database**: `DbalBackedMessageChannelBuilder::create('orders')`
> **Your business logic remains completely unchanged.** The handler with \`#\[Asynchronous('orders')\]\` works with any of these brokers.
## Production-Ready Features Built In
When you enable the DBAL module, you get message deduplication automatically. This prevents duplicate processing when messages are redelivered:
```php
DbalConfiguration::createWithDefaults()
->withDeduplication(true)
```
Need automatic retries with dead letter handling? Configure it once:
```php
public function errorConfiguration(): ErrorHandlerConfiguration
{
return ErrorHandlerConfiguration::createWithDeadLetterChannel(
'errorChannel',
RetryTemplateBuilder::exponentialBackoff(1000, 10)
->maxRetryAttempts(3),
'dbal_dead_letter'
);
}
```
> When a message fails, Ecotone retries with exponential backoff. After 3 attempts, it moves to the dead letter queue where you can inspect and replay it later.
## *The Power of Working at a Higher Level*
The solution to message broker complexity lies in working from a higher level abstraction. Ecotone provides this abstraction so we don't need to deal with low-level message broker concepts.
What's left to write is pure business logic itself:
- **Define your commands** as simple PHP classes
- **Mark handlers as asynchronous** with an attribute
- **Send messages** through the Command Bus
You can actually build production ready asynchronous application in seconds, rather than days. As Ecotone will handle queues, serialization, acknowledgments, retries, and error handling.
You can see whole example under this [link](https://github.com/ecotoneframework/quickstart-examples/tree/main/MessageBroker?ref=blog.ecotone.tech).
### Async Failure Recovery: Queue vs Streaming Channel Strategies
URL: https://blog.ecotone.tech/async-failure-recovery-queue-vs-streaming-channel-strategies/
Last updated: 2025-11-28T08:58:59.000Z
In this article we will discuss building asynchronous Systems in depth.
We will tackle why a recovery strategy that works perfectly for queue-based workflows may break for event streaming platforms. We will **see** exactly when resending messages causes duplicate processing, and when it’s actually your best move. And **learn** why defining channel’s purpose isn’t just good practice — it’s the difference between a system that can self-heal and one that requires manual intervention and constant attention.
**We will know what and *why* given failure recovery strategy exists, and which one works in specific scenarios**, and more importantly, **why they fail** when misapplied. And to build this mental model, we will first start by understanding the core differences between Message Channel types.
### Queue Channel

Queue based like solution. All Messages are available together
The most common Messaging Architecture is based on Queue Channels. Queues collects Messages, and in solutions like RabbitMQ provides them for consumption in same order they have been published. **Messages in Queues have destructive nature, meaning if Message is consumed successfully, it will be removed from the Queue.**

Message Consumption flow with Queue based Message Channels
Queue is a shared Channel from which multiple Message Consumers can consume. Scaling up Messages Consumers for same Queue, will parallel the work to speed up message consumption. **Multiple Consumers running against same Queue, is so called Competitive Consumer pattern:**

Queue Message Channel with scaled up Message Consumers
> What’s worth noting here is that with this architecture there is no limit to scaling. If our infrastructure can handle rolling out 100 Message Consumers for the same queue, we can simply do it — the workload will be parallelized across all of those consumers.
**In case of Queues we don’t really want to depend on the order of Message consumption**, as otherwise we would have to bind to only single Consumers and disallow scaling completely. Preserving order is often stated to be required part of the system, however preserving order comes with cost and can actually be considered for subset of features rather than applied globally. We will discuss message order a bit later.
### Event Streaming Channel
The other Channel type which we may face is Event Streaming Channel.
We can discuss it in context of Kafka implementation, as it’s the most used technology in context of Event Streaming Channels — also called Topics.
Event Streaming Channel (Topic) is broken into partitions, which you can imagine as smaller lanes (sub-channels). All messages with the same partition key always go into the same lane, never anywhere else:

Event Streaming Message Channel (Topic). Given account id will always go to the same partition.
**Each partition can have only one active consumer, which keeps message order inside that partition.** If we start more consumers than partitions, the extra ones stay idle because they have no partition to read from.This means consumer scaling is limited by the number of partitions, unlike Queues where scaling is unrestricted.
> With two partitions, we can run at most two consumers.
> Partition count should be chosen when creating the topic, because adding partitions later does not move existing messages. Meaning Messages which landed in partition “X”, may now be assigned partition “Y”, which would break the order.
---
In Kafka-style Event Streaming Channels, messages are not removed after consumption. They remain in the channel and are cleaned only based on retention settings defined on the broker.
**This means consuming a message does not delete it — consumption simply updates the consumer’s committed position.** This is the core design difference between Queues and Event Streaming Channels.

Message Consumer is committing the position
To build correct mental model for this, we need to be more precise here. Event Stream Channels have partitions (sub-channels), therefore what actually happens when we commit position, is that we are committing position within the partition (specific sub-channel):

Event Streaming Message Channel (Topic) is split into partitions
Since messages are not removed after consumption, multiple applications can read the same channel independently.
Each application keeps its own tracking state, identified by a Message Group Name — essentially the name of its consumer group.
> A Message Group lets several consumers share the same tracking, ensuring each message is processed once per group. If you create multiple groups, every group will consume the same message independently.
> RabbitMQ Queues don’t have this concept, so they effectively behave as one Message Group.

****Multiple Message Groups Consumption Model**
Using multiple Message Groups turns the channel into a shared stream, and this changes how we can process and recover messages, as narrows the options for handling failures.
That’s why understanding the channel’s intended purpose matters — far beyond simply choosing Queue or Streaming Channel.
> I talk about RabbitMQ as a Queue and Kafka as a Stream, but both platforms now blur this line.
> RabbitMQ supports [streaming](https://www.rabbitmq.com/docs/streams?ref=blog.ecotone.tech), and Kafka is adding [queue-style channels](https://cwiki.apache.org/confluence/display/KAFKA/KIP-932%3A+Queues+for+Kafka?ref=blog.ecotone.tech#KIP932:QueuesforKafka-Status).
> Because of that, it’s crucial to know how these channel types differ so we can pick the right one for the job.
So far, we’ve focused on what Message Channels can do — *their technical capabilities*, but just as important is *how* we plan to use them — *their actual purpose*.
### Read and Write side of the System
There are two ways of looking at the system:
- **Write side** — Protect invariants, triggers side effects, changes our internal models.
- **Read side** — Serves data for reading, which is built from what happened on the “write side”
Whatever are our Message Channel is related to Read or Write side, will help us understand how we can behave in context of failures.
> **“Write side” is responsible for our business operations, therefore stopping it due to failure means we are stopping the Business from working.**
> On other hand **“Read side” is concerned with building data for reading**, from what happened on the “write side”. Even if it’s stopped, it doesn’t mean that the business is stopped, it means however that our end-users may be making decisions based on stale view.
### Write side
**If our Message Channel was created with purpose of handling write side, it means we care about immediate reaction to business events as they occur.** Each event represents a trigger that initiates specific business workflow or actions.
> Here the goal is to complete the action, not to preserve strict ordering. For example, we shouldn’t stop future payments for an account just because one payment can’t be processed right now. Business continuity matters more than enforcing technical order.
**Use Cases:**
- Triggering business actions (e.g. Welcome email when user registers, Payment processing when order is placed, scheduling future actions)
- Workflow orchestration (e.g. Credit Card approval process, Order processing, data manipulation ETL)
- External Integration Triggers (e.g. Setting up account in 3rd party, Calling another Service to update data, or perform another action)
#### Query side
If our Message Channel was created with purpose of query side, meaning preparing data to read, then we will be interested in the complete timeline of events to reconstruct current state, build derived views, synchronize complete state of system.
> The purpose here is to build a view model that represents past system activity. Failures are acceptable because they don’t interrupt real business actions; they only make the view outdated. And since this data can be naturally eventually consistent, a blockage simply extends that delay.
**Use Cases:**
- Building read models/projections from event history (e.g., customer profile from all their interactions)
- System synchronization / data replication using complete event streams
- Analytics dashboards that aggregate historical patterns
### Shared Channel
A shared channel means the same message can be consumed multiple times, for example by different applications. In practice, this is achieved by using multiple Message Groups.
When multiple Message Groups consume from the same channel, failure handling becomes more complex.
If Application X can’t process a message, Application Y might still succeed.
Resending the failed message back to the channel could cause Application Y to process it twice. Therefore it’s important to define whatever given channel is meant to be shared, as it will require different recovery strategies.
> Kafka-style Event Streaming Channels can act as shared channels because they support multiple Message Groups. A channel becomes shared only when more than one group consumes from it.
> In contrast, RabbitMQ Queue Channels cannot be shared, as they always operate with a single Message Group. However RabbitMQ Stream Channels can be shared.
Failure Recover Strategies
Kafka and RabbitMQ offer strong messaging features, but it’s our responsibility to choose and implement recovery correctly on top of that.
If we choose poorly — or ignore error handling — we will discover the consequences at the worst possible time: in production.
Therefore when failure happens, we need to do something with failed Message, we need to decide what action will we take, and for this we do have different failure recovery strategies, which can be applied in specific use cases.

Message is consumed from Message Channel and fails
> We will now discover what failure recovery strategies we have at hand, we will also see how they have been actually implemented in PHP framework that I am author of — Ecotone.
Release Failure Strategy
When failure happens, we need to do something with failed Message, therefore we need to decide what action will we take.
The simplest solution which we can apply is to “release” the Message for re-consumption.
This option preserves Message and the order (sequence), however our processing becomes blocked till the moment Failed Message is consumed successfully.

Message is released for re-consumption
#### Use Case
Message release allows us to free-up the Message and re-consume it again, meaning Message is preserved even it has failed. This however comes with huge cost, as in case of unrecoverable errors, we will block processing completely.
> In case of Release Failed Strategy, the scope of blocking will differ between Kafka and RabbitMQ. However in both ways System becomes blocked to some degree and will continuously waste resources on handling Message that will always fail.
This recovery strategy works in all scenarios, making it a good last resort when everything else has failed. It won’t introduce unwanted side effects.
However, relying on it alone is not recommended, as it can block the business from operating.

Release strategy works well in all possible scenarios
#### Real life implementation
Ecotone exposes release strategy as “final failure strategy”.
Final failure strategies run only when no other strategy does apply or when no other recovery stategy have succeeded.
With RabbitMQ, releasing a message requeues it for future processing.
With Kafka, releasing resets the consumer offset so the same message is read again on the next poll.
```php
/** RabbitMQ Consumer example */
#[RabbitConsumer(
endpointId: 'transaction_handler',
queueName: 'transactions',
/** Requeue the Message to re-fetch it again */
finalFailureStrategy: FinalFailureStrategy::RELEASE
)]
public function processTransactionEvent(TransactionEvent $event): void
{
// Handle Transaction Event
}
/** Kafka Consumer example */
#[KafkaConsumer(
endpointId: 'transaction_handler',
topics: 'transactions',
/** Keep current offset to re-read the Message */
finalFailureStrategy: FinalFailureStrategy::RELEASE
)]
public function processTransactionEvent(TransactionEvent $event): void
{
// Handle Transaction Event
}
```
You can read more about [final failure strategies here](https://docs.ecotone.tech/modelling/recovering-tracing-and-monitoring/resiliency/final-failure-strategy?ref=blog.ecotone.tech).
### Ignore Failure Strategy
We can also ignore the failed Message in order to unblock the processing.
By ignoring failed Message, we will simply skip it over, meaning that Message will be lost. Therefore this option is only feasible for non-critical Messages which can be lost.

Message is ignored in order to move processing forward
#### Use Case
The use case for ignoring Message is really limited and should only be considered if we are able to simply accept the fact that Message will be lost. We may want to use ignoring strategy for “Write side” — for example while tracking high volume of data, where losing few messages will not affect final results (e.g. tracking temperature changes).
However for building Read side, where we may be building views from incoming Messages, skipping over Messages will cause generated data to be incompletele or simply incorrect. Therefore it should be used with “Read side” Channels.

Ignore Messages works well in all scenarios, where complete order guarantee is not required
#### Real life implementation
Just the same as Release strategy, Ignore strategy should rather be treated as last resort and this is how Ecotone implements it.
We will see a bit later how we can combine different strategies together, however what is important now, is that it’s actually final strategy, when any other strategy does not apply or any other strategy has failed.
This can be implemented by simply acknowledging the Message and moving forward, therefore from technical side it can work the same as succesfull processing.
```php
/** RabbitMQ Consumer example */
#[RabbitConsumer(
endpointId: 'transaction_handler',
queueName: 'transactions',
/** Discarding Messages after failure */
finalFailureStrategy: FinalFailureStrategy::IGNORE
)]
public function processTransactionEvent(TransactionEvent $event): void
{
// Handle Transaction Event
}
/** Kafka Consumer example */
#[KafkaConsumer(
endpointId: 'transaction_handler',
topics: 'transactions',
/** Discarding Messages after failure */
finalFailureStrategy: FinalFailureStrategy::IGNORE
)]
public function processTransactionEvent(TransactionEvent $event): void
{
// Handle Transaction Event
}
```
You can read more about [final failure strategies here](https://docs.ecotone.tech/modelling/recovering-tracing-and-monitoring/resiliency/final-failure-strategy?ref=blog.ecotone.tech).
### Deduplication (Idempotency)
With idempotency, a message that was already processed will be ignored if it appears again.
This protects us from duplicates caused by app failures or broker hiccups.
That’s why idempotency must be part of every Message Broker integration, regardless of which recovery strategy we use.

Message will be redelivered, as failed to be acknowledge in the Broker
#### Use case
There are no limits in context of using idempotency, in general we should strive to achieve it no matter if we are dealing with “write” / “read” or shared Channels. If we want to ensure no Messages will be handled twice, this is our way to do it.
There are different ways to achieve deduplication, depending on the situation:
1\. If we call an external service (e.g., a payment provider), it may support idempotency keys.
2\. In some cases the application itself can ignore repeated actions (e.g., if a customer is already blocked, skip blocking again).
3\. The final option is deduplication at the Message Framework level
Point one and two have to be implemented per feature, and will be specific to actual solution we build. However third option is feature agnostic and is more of architecture level solution, which can be applied to different features, and this one we will actually discuss now.

Deduplication strategy works well in all possible scenarios
#### Real life implementation
All messages should include an identifier so we can uniquely recognize them. Message Brokers do not guarantee this, so developers must implement it themselves. Once a message is identifiable, its ID can be used for deduplication.
In Ecotone, internal messages automatically receive a Message ID, which can be used for this purpose. For Messages coming from outside however, a stable and meaningful ID may not exist, so a custom deduplication key may be required.
By default Ecotone will deduplicate by MessageId, however as we can see above, we can customize this process the way we want. Ensuring that even if the Message does have any Message Id, we still can do deduplication based on other means.
For additional deduplication methods, see [Ecotone’s documentation](https://docs.ecotone.tech/modelling/recovering-tracing-and-monitoring/resiliency/idempotent-consumer-deduplication?ref=blog.ecotone.tech).
### Instant Retry
A common strategy for transient errors is Instant Retry. It ensures when Message has failed, it will be retried immediately up to few times. This way we give ourselves a chance to recover from the failure right away.

Message is retried instantly after failure
#### Use case
The power of this recover strategy is that we are not losing the order. If message handling fails, we try again right away. This works well for brief problems like lost DB connections or external service timeouts.
It’s safe to use this strategy with all the approaches for either “write” or “read” and even “shared channels” (as message is not resend back to the Channel).

Instant Retry strategy works well in all possible scenarios
#### Real life implementation
To use Instant Retry reliably, each attempt must act like a fresh first attempt. That means removing all prior state — rolling back DB changes, clearing propagation data, etc. With a clean start guaranteed, Instant Retry becomes a safe and reusable strategy.
In case of Ecotone this all happens automatically. Ecotone will ensure that database transaction is rolled back, context headers are clean up, and Message is automatically retried.
```php
/** RabbitMQ Consumer example */
#[InstantRetry(retryTimes: 2, exceptions: [NetworkException::class])]
#[RabbitConsumer(endpointId: 'transaction_handler', queueName: 'transactions')]
public function processTransactionEvent(TransactionEvent $event): void
{
// handle
}
/** Kafka Consumer example */
#[InstantRetry(retryTimes: 2)] // no exceptions given, meaing retry on all exceptions
#[KafkaConsumer(endpointId: 'transaction_handler', topics: 'transactions')]
public function processTransactionEvent(TransactionEvent $event): void
{
// handle
}
```
Read more in [Ecotone’s Instant Retry documentation section](https://docs.ecotone.tech/modelling/recovering-tracing-and-monitoring/resiliency/retries?ref=blog.ecotone.tech#instant-retries).
### Resend Failure Strategy
When a message can’t be processed, continuous retries will just block the flow, therefore for this we need different way to handle failures.
One of our toolset for doing so is resending the message to the original channel, in order to unblock current message processing:

Resending Message back to the same Channel, to unblock the processing
#### Use case
This method fits the write side, where unblocking the flow is more important than the order. It does not work well for the read side however, because it disrupts ordering. It won’t work for shared channels either, as other applications would end up reprocessing a message they may already have handled.
Therefore this failure recovery strategy is most suitable when Channel is under control of Single Message Group and is being used for processing business actions. Then resending the Message won’t affect other parties, and handling the Message out of order may actually lead that Message will recover itself automatically (for example 3rd party API went down for few seconds, we’ve proceessed other Messages and on retry it was successful).

Resend strategy works well with “write side” scenarios
#### Real life implementation
This strategy works by sending the original message back to the same channel.
It’s crucial to resend the message exactly as it was — including its identifier.
By preserving the original ID, a message that was already processed can be correctly deduplicated.
```php
/** RabbitMQ Consumer example */
#[RabbitConsumer(
endpointId: 'transaction_handler',
queueName: 'transactions',
/** Resend Message to the original Channel */
finalFailureStrategy: FinalFailureStrategy::RESEND
)]
public function processTransactionEvent(TransactionEvent $event): void
{
// Handle Transaction Event
}
/** Kafka Consumer example */
#[KafkaConsumer(
endpointId: 'transaction_handler',
topics: 'transactions',
/** Resend Message to the original Channel */
finalFailureStrategy: FinalFailureStrategy::RESEND
)]
public function processTransactionEvent(TransactionEvent $event): void
{
// Handle Transaction Event
}
```
You can read more about [final failure strategies here](https://docs.ecotone.tech/modelling/recovering-tracing-and-monitoring/resiliency/final-failure-strategy?ref=blog.ecotone.tech).
### Sending Message to different Channel
We can also send Message to different channel on failure. Moving it from one place to another

Sending Message to different Channel
#### Use case
This solution works nicely for all use cases, “write”, “read” and “shared” channels will work well with this. On failure we simply move the Message from one channel to another which can be private to given Message Group (Application).
The down side of this approach is that we can actually end up with another channel being blocked by failures. Therefore the second channel should still apply other failure recovery patterns, simply moving message there is not enough.
This is good approach when the original Channel is shared one, and we would like to move it to exclusive channel. This way the we will be able to use more failure recovery strategy patterns than we would be able to do on the first channel.

Sending to different channels works well in all possible scenarios
#### Real life implementation
In case of Ecotone we will so called ErrorChannel to which Message should be sent in case of failures. The channel can be of any possible type, we may for example have original Kafka Channel and the second channel as Database Channel.
```php
/** RabbitMQ Consumer example */
#[RabbitConsumer(
endpointId: 'transaction_handler',
queueName: 'transactions',
/** Final failure strategy will be triggered in case sending to Error Channel fails */
finalFailureStrategy: FinalFailureStrategy::RELEASE
)]
#[ErrorChannel('failureChannel')] // define error channel, where to send Message on failure
public function processTransactionEvent(TransactionEvent $event): void
{
// Handle Transaction Event
}
/** Kafka Consumer example */
#[KafkaConsumer(
endpointId: 'transaction_handler',
topics: 'transactions',
/** Final failure strategy will be triggered in case sending to Error Channel fails */
finalFailureStrategy: FinalFailureStrategy::RELEASE
)]
#[ErrorChannel('failureChannel')] // define error channel, where to send Message on failure
public function processTransactionEvent(TransactionEvent $event): void
{
// Handle Transaction Event
}
```
### Resending Message with Delay
We can also resend Message back with delay, to ensure that Message will re-processed after some time:

Resending Message back with delay
#### Use case
Sending Message back to the Channel, works well for “write” side logic, but not for “read” side logic and “shared channels”, as it duplicates the Message within the original Channel.
This solution is gold for “write side” action, as it solve most of transient errors without the need for manual intervention from Developers. For example if 3rd party went down for few minutes, if our retry strategy will define that message should be retried in 10 minutes, we will most likely recover the system automatically.

Resend strategy works well with “write side” scenarios
#### Real life implementation
Ecotone provides integration for resending Messages back to the channel with delay (if Message Broker supports that). We do it using ErrorChannel pointing to retry configuration.
```php
/** RabbitMQ Consumer example */
#[ErrorChannel('delayedRetryChannel')] // define error channel
#[RabbitConsumer(
endpointId: 'transaction_handler',
queueName: 'transactions',
finalFailureStrategy: FinalFailureStrategy::RESEND
// Final failure strategy will be triggered in case sending to Error Channel fails
)]
public function processTransactionEvent(TransactionEvent $event): void
{
// Handle Transaction Event
}
```
Then we define retry configuration, which will resend Message back to the original channel with delay:
```less
#[ServiceContext]
public function errorConfiguration()
{
return ErrorHandlerConfiguration::create(
errorChannelName: "delayedRetryChannel",
delayedRetryTemplate: RetryTemplateBuilder::exponentialBackoff(
initialDelay: 100, // 100ms initial delay for testing
multiplier: 2 // Each retry is 2x longer (100ms, 200ms, 400ms...)
)->maxRetryAttempts(2), // Maximum 2 delayed retry attempts
);
}
```
However in case of Message Channels that do not have ability to retry with delay like Kafka Streaming Channel, we need different way. For this we can combine custom database channel with retries.

Combining original channel with custom retry channel which supports delays
### Dead Letter Strategy
When an unrecoverable failure occurs, retrying the message no longer adds value. At that point if Message can not be ignored, we should move the message to a some storage, which unblocks processing and prevents wasting resources on a message that cannot be handled successfully.
This storage which hold the Message for us for later review is called Dead Letter. Dead Letter can provide set of functionalities like retrying Message or deleting it.

Storing Message in dead letter on failure
#### Use case
This solution works nicely with “write” and “shared” channels. On failure we simply move the Message to Dead Letter and store it for later review. This however does not preserve processing order, therefore using it for “read side” channels won’t work well.
This is good approach when the original Channel is shared one, and we would like to move it to exclusive channel. This way the we will be able to use more failure recovery strategy patterns than we would be able to do on the first channel.

Dead Letter strategy works well with “write side” and shared channels
#### Real life implementation
In case of Ecotone Error Channel can actually act as our Dead Letter, we could implement our own Handler which will store the Message they way we want on failure.
However Ecotone with built-in Dead Letter in the database, that comes with operations like Message retrying and deleting. This works best with combing it with retries, to ensure few tries for automatic recover, and then in case of unrecoverable error pushing Message to dead letter:
```php
#[ServiceContext]
public function errorConfiguration()
{
return ErrorHandlerConfiguration::createWithDeadLetterChannel(
errorChannelName: 'delayedRetryChannel',
delayedRetryTemplate: RetryTemplateBuilder::exponentialBackoff(1, 1)
->maxRetryAttempts(2)
deadLetterChannel: 'dbal_dead_letter' // push to predefined Ecotone Dead Letter
);
}
```
### Summary
The most important part of building asynchronous systems is matching your recovery approach to whether you’re building the **write side** (business actions that can’t stop) or **read side** (views that can be eventually consistent) of your system. Get this wrong, and you’ll either block critical business operations or corrupt your data views.
We’ve covered seven distinct failure recovery strategies — from simple Release and Ignore patterns to sophisticated approaches like Instant Retry, Delayed Resend, and Dead Letter handling. Each works brilliantly in specific scenarios but can be disastrous when misapplied. You can refer to this article article whenever needed, as it’s written in a way that you can simply jump to given given failure recovery strategy and then re-read it possible application.
For PHP based systems, Ecotone provides declarative, attribute-based integration with RabbitMQ and Kafka, handling all the complexity we discussed and more — automatic deduplication, transaction rollbacks, configurable retry strategies, and built-in dead letter management.
Join the Ecotone community on Discord to discuss message-driven architectures, get help with your integration challenges, and stay updated on new features: [https://discord.gg/GwM2BSuXeg](https://discord.gg/GwM2BSuXeg?ref=blog.ecotone.tech)
### Building Workflows in PHP
URL: https://blog.ecotone.tech/building-workflows-in-php/
Last updated: 2025-08-25T20:03:39.000Z
Almost any business requires workflows. Whether you're processing orders, onboarding customers, or handling document approvals, these processes are the beating heart of your application. Yet for most PHP developers, workflows become sources of frustration rather than competitive advantages. Often becoming the most complex part of the system with hard to follow flows, flaky and complex tests, and code complexity which requires expert knowledge of the System in order to make safe changes.
In this article we will tackle how we can build Workflows that are opposite of all the above. We will take a look on workflows that are easy to maintain and follow, which can scale up to the needs of most most demanding environments, and are reliable by nature. But before we will jump to this, let's first discuss traditional approaches to the problem of Workflows.
## Why Traditional Approaches Fail
Many developers try to solve Workflows by creating elaborate service layers:
```php
class OrderProcessingService
{
public function __construct(
private ValidationService $validator,
private PaymentService $payment,
private InventoryService $inventory,
private ShippingService $shipping,
private NotificationService $notification,
private DiscountService $discount,
private AuditService $audit
) {}
public function process(Order $order): void
{
$this->validator->validate($order);
$this->payment->process($order);
$this->inventory->reserve($order);
$this->shipping->schedule($order);
$this->notification->send($order);
$this->audit->log($order);
}
}
```
This looks clean on the surface, but there is fundamental problem with this approach, we've mixed up all the steps together, not giving ourselves a chance to isolate the processing steps. Creating a workflow that is easy to break and hard to recover:
- **Error handling becomes cumbersome** \- what happens when scheduling shipping step fails, how do we handle the failure?
- **Single processing affects overall timing** \- What if payment processing will take more time than usual, or will time out completely?
- **No failure isolation** \- What if a Notification Service is down completely and we can't recover, how can we resume the flow when the Service will be back?
That kind of code will most likely work smooth in development environment, yet can quickly backfire in production. Creating a need for time consuming recovery from the problems it created. Therefore this kind of code will be just beginning of the journey, leading to some more sophisticated solutions.
### The State Machine Complexity Explosion
Desperate to escape service layer chaos, many teams turn to state machines. "Finally," they think, "a structured approach to workflow management"
However state machines demand extensive upfront either in PHP or YAML, which can quickly become hard to maintain:
```yaml
workflows:
order_processing:
type: 'state_machine'
audit_trail:
enabled: true
marking_store:
type: 'method'
property: 'currentState'
supports:
- App\Entity\Order
initial_marking: draft
places:
- draft
- payment_pending
- payment_failed
- payment_completed
- inventory_reserved
- inventory_failed
- shipping_scheduled
- shipped
- completed
- cancelled
- refunded
transitions:
start_payment:
from: draft
to: payment_pending
process_payment:
from: payment_pending
to: [payment_completed, payment_failed]
retry_payment:
from: payment_failed
to: payment_pending
reserve_inventory:
from: payment_completed
to: [inventory_reserved, inventory_failed]
# ... 15 more transitions for a "simple" order process
```
### Where is the behaviour?
State machines solve entity state management, but **workflows are about behaviour not state.**
```php
// State machines ask: "What state is this entity in?"
$currentState = $workflow->getMarking($order)->getPlaces();
// But the actual question that will give us knowledge is: "What happens when we process an order?"
// State machines focus on STATES and TRANSITIONS
$workflow->apply($order, 'process_payment');
$workflow->apply($order, 'reserve_inventory');
// Business workflows and processes focus on STEPS and OUTCOMES
// "First validate, then process payment, then reserve inventory"
// This intent is lost if we put equal sign between state machine and workflow
```
With Business Workflows we focus on behaviour, yet with State Machines we actually focus (as the name implies) on state - data. Therefore instead of our business workflow step indicating behaviour, it indicates state changes.
This means the actual thing for which we build the workflow - "behaviour", becomes pushed the pushes on the edges, and coupled with Framework transition events:
```php
class OrderTransitionHandler
{
#[AsEventListener(event: 'workflow.order_processing.transition.process_payment')]
public function onProcessPayment(TransitionEvent $event): void
{
// Actual reason for which we build workflow - "behaviour", become hidden in transition event handlers
// pushing the "state" on the front, and "behaviour" to the back.
// And binding us to framework events, in order to trigger the behaviour
$order = $event->getSubject();
if ($order->getCustomer()->isPremium()) {
$this->applyPremiumDiscount($order);
$this->schedulePriorityProcessing($order);
}
try {
$this->paymentService->process($order);
} catch (PaymentException $e) {
// Error handling becomes complex state management
$event->getWorkflow()->apply($order, 'payment_failed');
throw $e;
}
}
#[AsEventListener(event: 'workflow.order_processing.transition.reserve_inventory')]
public function onReserveInventory(TransitionEvent $event): void
{
// more business logic hidden in event handlers
}
}
```
> State machines focus on state, not the behaviour. Therefore they may act as supporting tool for visibility, but they are not good candidates for workflow orchestrators.
## Enter Ecotone's Orchestrator
Ecotone introduces Enterprise feature called `Orchestrator`, which promotes building Workflows in visible and maintainable way.
```php
class OrderOrchestrator
{
#[Orchestrator(inputChannelName: "process.order")]
public function processOrder(Order $order): array
{
return [
"validate.order",
"process.payment",
"reserve.inventory",
"send.confirmation",
"audit.transaction"
];
}
}
```
**With Orchestrator, the business process became the code itself.** No hidden logic, no scattered implementations, no complex state management - just pure, explicit business intent.
> Orchestrator defines the Workflows in clear and understandable way, and is separated from the actual step implementation. Making it easy to do modifications and changes.
## Implementing Steps: Clean, Focused, and Testable
Each workflow step becomes a focused, independently testable unit:
```php
class OrderProcessingSteps
{
#[InternalHandler(inputChannelName: "validate.order")]
public function validateOrder(Order $order): Order
{
if (!$order->hasItems()) {
throw new InvalidOrderException('Order must contain items');
}
if (!$order->hasValidPaymentMethod()) {
throw new InvalidOrderException('Valid payment method required');
}
return $order;
}
#[InternalHandler(inputChannelName: "process.payment")]
public function processPayment(Order $order, PaymentService $paymentService): Order
{
$result = $paymentService->charge(
$order->getTotal(),
$order->getPaymentMethod()
);
return $order->markAsPaid($result->getTransactionId());
}
#[InternalHandler(inputChannelName: "audit.transaction")]
public function auditTransaction(Order $order, AuditService $auditService): Order
{
$auditService->logOrderProcessing($order, [
'customer_type' => $order->getCustomer()->getType(),
'total_amount' => $order->getTotal(),
'processing_time' => microtime(true) - $order->getProcessingStartTime()
]);
return $order;
}
}
```
Understanding how Orchestrator achieves this simplicity requires looking at its architecture. Unlike traditional workflow engines that maintain complex state machines or persistent workflow instances, Orchestrator uses a **stateless routing slip pattern** that eliminates the need for state management entirely.
### The Routing Pattern: Carrying Intent in Messages
At its core, Orchestrator works by embedding the workflow steps directly into the message headers. This approach, known as the **Routing Slip pattern**, transforms each message into a self-contained execution plan:

## Benefits of Stateless Routing Approach
### Why Stateless Changes Everything: The Database-Free Approach
Traditional workflow engines create a maintenance nightmare by storing workflow state in databases. Every running workflow becomes a database record that must be managed, migrated, and eventually cleaned up.
**Here's what traditional workflow engines force you to manage:**
```sql
-- Workflow instances table grows endlessly
CREATE TABLE workflow_instances (
id BIGINT PRIMARY KEY,
workflow_type VARCHAR(100),
current_state VARCHAR(50),
created_at TIMESTAMP,
updated_at TIMESTAMP,
execution_context JSON, -- Can become massive
step_history JSON, -- Grows with each step
status VARCHAR(20)
);
-- Result: Millions of records for busy applications
-- Complex queries to find stuck workflows
-- Expensive cleanup procedures
-- Database migrations when workflow logic changes
```
**The hidden costs are staggering:**
- **Database Growth**: Workflow tables can grow indefinitely
- **Cleanup Complexity**: Determining which workflows can be safely deleted becomes a complex operation
- **Query Performance**: Finding and managing workflow instances requires expensive database queries
**Orchestrator eliminates all of this complexity.** Each Message carry its own routing information, which is used to determine next step. Therefore there is no need to store and manage workflow state anymore. Meaning no database storage is involved in workflow processing.
### Scaling Without the Complexity
Traditional workflow engines create challenges when it comes to scaling, as workflow state must be shared across servers. This leads to required coordination, extra database operations, and data synchronizations, which limit ability to scale.
**With Ecotone's Orchestrators each step can be processed without any workflow related synchronization and database queries, as next steps are embedded into Message itself.**
**The scaling benefits are clear:**
- **Horizontal Scaling**: New servers can process workflows in isolation as there is no shared Workflow state
- **Processing isolation**: Step execution is completely independent: No inter-server communication, synchronization, and database locking mechanisms needed
- **Greater Performance** : We avoid fetching and storing the Workflow state with each step
This stateless architecture is what makes Orchestrator so powerful - it eliminates the complexity that workflow engines introduced while providing flexibility and performance.
#### **Zero-Migration Workflow Changes**
The stateless nature means workflow changes are immediately effective. This means there is no need to migrate and keep compatibility between changes. In flight workflow will finish their execution based on previously defined steps, and new ones will follow changed format. **This way of isolated handling eliminates challenges of deploying any changes to the workflow, and provides ability for A/B testing any kind of flow with ease.**
```php
// Version 1: Original workflow
#[Orchestrator(inputChannelName: "process.order")]
public function processOrderV1(Order $order): array
{
return [
"validate.order",
"process.payment",
"send.confirmation"
];
}
// Deployed Version 2: Enhanced workflow - NO MIGRATION REQUIRED
#[Orchestrator(inputChannelName: "process.order")]
public function processOrderV2(Order $order): array
{
$workflow = ["validate.order", "process.payment"];
// New business logic - works immediately
if ($order->getCustomer()->isPremium()) {
$workflow[] = "apply.premium.benefits";
}
$workflow[] = "send.confirmation";
return $workflow;
}
// All new orders use V2 immediately
// No existing workflow instances to migrate
// No complex deployment procedures
// No downtime required
```
## Features
As we've discussed the stateless routing as the core of Orchestrator, we can now take a look at the features that Orchestrator provides.
### Data Passing and Enriching: Flexible Context Management
One of Orchestrator's most powerful features is how it handles data flow between workflow steps. You have complete flexibility in how data moves through your workflow - either by enriching the main payload or by adding metadata without touching the original data.
#### Approach 1: Enriching the Main Payload
The most straightforward approach is to modify and enrich the main business object as it flows through the workflow:
```php
class OrderProcessingSteps
{
#[InternalHandler(inputChannelName: "validate.order")]
public function validateOrder(Order $order): Order
{
if (!$order->hasItems()) {
throw new InvalidOrderException('Order must contain items');
}
// Return enriched order with validation timestamp
return $order->markAsValidated(new DateTime());
}
#[InternalHandler(inputChannelName: "process.payment")]
public function processPayment(Order $order, PaymentService $paymentService): Order
{
$result = $paymentService->charge(
$order->getTotal(),
$order->getPaymentMethod()
);
// Enrich order with payment details
return $order
->markAsPaid($result->getTransactionId())
->addPaymentTimestamp($result->getProcessedAt())
->setPaymentReference($result->getReference());
}
#[InternalHandler(inputChannelName: "apply.premium.benefits")]
public function applyPremiumBenefits(Order $order): Order
{
// Directly modify the order object
return $order
->addDiscount(0.15)
->addFreeShipping()
->addPrioritySupport()
->addExtendedWarranty();
}
}
```
**When to use payload enrichment:**
- The additional data becomes part of the business object's state
- Subsequent steps need the enriched data as part of the main object
- You want a single, comprehensive result object
#### Approach 2: Adding Metadata Without Changing Original Payload
Sometimes you need additional context for processing without modifying the original business object. Use `changingHeaders: true` to add metadata:
```php
class OrderEnrichmentSteps
{
#[InternalHandler(
inputChannelName: "enrich.customer.context",
changingHeaders: true
)]
public function enrichCustomerContext(Order $order): array
{
$customer = $order->getCustomer();
// Return metadata that becomes message headers
return [
'customerTier' => $customer->getTier(),
'loyaltyPoints' => $customer->getLoyaltyPoints(),
'riskScore' => $this->riskService->calculateScore($customer),
'purchaseHistory' => $this->orderService->getCustomerHistory($customer->getId()),
'creditLimit' => $this->creditService->getLimit($customer->getId())
];
}
#[InternalHandler(inputChannelName: "calculate.pricing")]
public function calculatePricing(
Order $order, // Original order unchanged
#[Header('customerTier')] string $tier,
#[Header('loyaltyPoints')] int $points,
#[Header('riskScore')] int $riskScore
): Order {
// Use metadata for business logic without polluting the order object
$discount = 0;
if ($tier === 'PREMIUM' && $points > 1000) {
$discount = 0.15; // 15% premium discount
} elseif ($tier === 'GOLD' && $points > 500) {
$discount = 0.10; // 10% gold discount
}
// Apply risk-based adjustments
if ($riskScore > 80) {
$discount = max(0, $discount - 0.05); // Reduce discount for high-risk customers
}
return $order->applyDiscount($discount);
}
#[InternalHandler(inputChannelName: "finalize.order")]
public function finalizeOrder(
Order $order,
#[Header('processedAt')] DateTime $processedAt,
#[Header('executionId')] string $executionId,
PaymentService $paymentService
): Order {
$paymentService->makePayment($order);
return $order->markAsCompleted();
}
}
```
**When to use metadata enrichment:**
- Additional data is needed for processing logic but shouldn't be part of the business object
- You want to keep the original payload clean and focused
- Multiple steps need different contextual information
- Audit trails, processing metadata, or temporary calculations
### Dynamic Routing: Runtime Workflow Construction
Real business processes aren't static. Customer types evolve, regulations change, and new requirements emerge constantly. Orchestrator handles this complexity naturally:
```php
#[Orchestrator(inputChannelName: "process.order")]
public function processOrder(Order $order): array
{
// Base workflow steps
$workflow = ["validate.order", "process.payment"];
// Dynamic routing based on business rules
if ($order->getCustomer()->isPremium()) {
$workflow[] = "apply.premium.discount";
$workflow[] = "priority.inventory.check";
if ($order->getTotal() > 1000) {
$workflow[] = "executive.approval";
}
}
// International orders need additional steps
if ($order->isInternational()) {
$workflow[] = "customs.documentation";
$workflow[] = "international.shipping.calculation";
}
// Common final steps
$workflow[] = "reserve.inventory";
$workflow[] = "send.confirmation";
// Workflow can be customized dynamically per each Customer separately
return $workflow;
}
```
> The same orchestrator elegantly handles premium customers, international customers - each with their specific requirements clearly expressed and easily modifiable.
## Asynchronous Workflow Step
Some workflow steps are naturally resource-intensive - image processing, external API calls, email campaigns, data analysis. Orchestrator makes asynchronous processing trivial:
```php
class MediaProcessingOrchestrator
{
#[Orchestrator(inputChannelName: "process.media.upload")]
public function processMediaUpload(): array
{
return [
"validate.file.format", // Fast - runs synchronously
"scan.for.malware", // Medium - runs synchronously
"resize.image", // Slow - runs asynchronously
"generate.thumbnails", // Slow - runs asynchronously
"extract.metadata", // Medium - runs asynchronously
"upload.to.cdn", // Slow - runs asynchronously
"update.database", // Fast - runs synchronously
"notify.user.completion" // Fast - runs synchronously
];
}
// Heavy processing runs asynchronously without blocking
#[Asynchronous('media_processing')]
#[InternalHandler(inputChannelName: "resize.image")]
public function resizeImage(MediaUpload $upload, ImageProcessor $processor): MediaUpload
{
$resizedPath = $processor->resize($upload->getPath(), [
'large' => [1920, 1080],
'medium' => [1280, 720],
'small' => [640, 360]
]);
return $upload->withResizedPath($resizedPath);
}
#[Asynchronous('media_processing')]
#[InternalHandler(inputChannelName: "generate.thumbnails")]
public function generateThumbnails(MediaUpload $upload, ThumbnailGenerator $generator): MediaUpload
{
$thumbnails = $generator->generate($upload->getPath(), [
'preview' => [300, 200],
'icon' => [64, 64]
]);
return $upload->withThumbnails($thumbnails);
}
}
```
> **The power is in the simplicity**: Mix synchronous and asynchronous steps based purely on business needs and performance requirements, not technical limitations or architectural constraints.
## Error Handling and Recoverability
If our Message fails we can use Error Channel to handle the failure. This way we can preserve the Message even if we can't handle it at given moment.
We can for example push Error Message to Dead Letter to store the Message for later review, or add some customized retry mechanism to retry the Message again.
Here's how error handling and recovery works in practice:

**Key benefits of this error handling approach**:
- **No Lost Work**: Failed messages are preserved with complete context
- **Exact Resume Point**: Workflows resume from the exact step that failed, not from the beginning
- **Full Context Preservation**: Original payload, routing state, and error details are maintained
- **Administrative Control**: Failed messages can be reviewed, modified, and replayed manually
- **Automatic Retry Options**: Configure automatic retry with exponential backoff
## Executing Orchestrators: Multiple Entry Points for Maximum Flexibility
Ecotone provides several ways to trigger orchestrated workflows, each designed for different use cases and integration patterns. Let's explore the most common approaches.
### Business Interface: Clean API for Predefined Workflows
The most straightforward way to execute orchestrators is through dedicated business interfaces. This approach provides a clean, type-safe API that encapsulates workflow execution:
```php
interface OrderProcessingService
{
#[BusinessMethod(inputChannelName: "process.order")]
public function processOrder(Order $order): ProcessingResult;
}
// The orchestrator that handles the workflow
class OrderOrchestrator
{
#[Orchestrator(inputChannelName: "process.order")]
public function processOrder(Order $order): array
{
$workflow = [
"validate.order",
"process.payment",
"reserve.inventory"
];
if ($order->getCustomer()->isPremium()) {
$workflow[] = "apply.premium.benefits";
$workflow[] = "expedite.shipping";
} else {
$workflow[] = "schedule.standard.shipping";
}
$workflow[] = "send.confirmation";
$workflow[] = "audit.transaction";
return $workflow;
}
}
// Usage in your application
class OrderController
{
public function __construct(
private OrderProcessingService $orderProcessor
) {}
public function processOrder(Request $request): JsonResponse
{
$order = Order::fromRequest($request);
// Clean, simple workflow execution
$result = $this->orderProcessor->processOrder($order);
return new JsonResponse([
'order_id' => $result->getOrderId(),
'status' => $result->getStatus(),
'estimated_delivery' => $result->getEstimatedDelivery()
]);
}
}
```
**Benefits of Business Interface approach**:
- **Clean API**: Business-focused method names that express intent clearly
- **Documentation**: Self-documenting through interface contracts
- **Encapsulation**: Workflow complexity hidden behind simple method calls
### Event-Driven Orchestration: Reactive Workflow Triggers
For event-driven architectures, orchestrators can be triggered automatically when specific events occur. This approach is perfect for workflows that should start in response to domain events:
```php
class UserVerificationEventHandler
{
// Event is propagated to the orchestrator
#[EventHandler(outputChannelName: "verify.user.account")]
public function verifyUserAccount(UserRegistered $event): array
{
return $event;
}
}
class UserVerificationOrchestrator
{
#[Orchestrator(inputChannelName: "verify.user.account")]
public function onUserRegistered(UserRegistered $event): array
{
$user = $event->getUser();
// Build verification workflow based on user type
$workflow = ["send.welcome.email"];
if ($user->requiresEmailVerification()) {
$workflow[] = "send.email.verification";
$workflow[] = "wait.for.email.confirmation";
}
if ($user->requiresPhoneVerification()) {
$workflow[] = "send.sms.verification";
$workflow[] = "wait.for.sms.confirmation";
}
if ($user->isEnterprise()) {
$workflow[] = "schedule.onboarding.call";
$workflow[] = "assign.account.manager";
$workflow[] = "setup.enterprise.features";
}
$workflow[] = "activate.user.account";
$workflow[] = "send.activation.confirmation";
$workflow[] = "track.registration.metrics";
return $workflow;
}
}
```
**Benefits of Event-Driven approach**:
- **Reactive Architecture**: Workflows start automatically when events occur
- **Scalability**: Events can trigger multiple workflows independently
- **Business Alignment**: Workflows triggered by actual business events
The same approach can be achieved with Command Handlers and even Query Handlers.
### Orchestrator Gateways: Ultimate Flexibility for Dynamic Execution
For maximum business agility, use Orchestrator Gateways to construct and execute workflows at runtime. This approach is perfect when you need to build workflows dynamically based on incoming requests or external criteria:
```php
interface DocumentProcessingGateway
{
#[OrchestratorGateway]
public function processDocument(array $steps, Document $document): ProcessingResult;
}
// HTTP Controller that builds workflows based on request parameters
class DocumentController
{
public function __construct(
private DocumentProcessingGateway $documentGateway
) {}
// Example API usage:
// POST /documents/process
// {
// "document": {...},
// "requires_approval": true,
// "priority": "urgent"
// }
//
public function processDocument(Request $request): JsonResponse
{
$document = Document::fromRequest($request);
// Build workflow dynamically based on request parameters and document properties
$steps = ["validate.document", "extract.content"];
// Add approval steps based on document value and type
if ($request->has('requires_approval') || $document->getValue() > 5000) {
$steps[] = "legal.review";
// Executive approval for high-value documents
if ($document->getValue() > 100000) {
$steps[] = "executive.approval";
$steps[] = "board.notification";
} elseif ($document->getValue() > 10000) {
$steps[] = "manager.approval";
}
}
// Priority processing for urgent requests
if ($request->get('priority') === 'urgent') {
$steps[] = "priority.processing";
$steps[] = "expedite.review";
}
// Final processing steps
$steps[] = "finalize.document";
// Execute the dynamically built workflow
$this->documentGateway->processDocument($steps, $document);
return new JsonResponse([]);
}
-----------------------------
// Example API of allowing clients to define the workflow:
//
// POST /documents/custom-workflow
// {
// "document": {...},
// "workflow_steps": [
// "validate.document",
// "legal.review",
// "executive.approval",
// "apply.security.measures",
// "finalize.document"
// ]
// }
public function processCustomWorkflow(Request $request): JsonResponse
{
$document = Document::fromRequest($request);
// Allow clients to specify custom workflow steps via API
$customSteps = $request->get('workflow_steps', []);
// Validate and sanitize custom steps
$allowedSteps = [
'validate.document', 'extract.content', 'legal.review',
'manager.approval', 'executive.approval', 'apply.security.measures',
'audit.access', 'finalize.document', 'notify.stakeholders'
];
// Execute custom workflow
$this->documentGateway->processDocument($steps, $document);
return new JsonResponse([]);
}
}
```
**Orchestrator Gateways are automatically registered in the Dependency Container** and can be auto-wired into any service. Whatever steps you provide to the Gateway will be executed in the given order, enabling you to build any workflow based on incoming requests or business criteria.
**Real-world benefits**:
- **API-Driven Workflows**: Clients can influence workflow execution through request parameters
- **A/B Testing**: Different workflow variations based on user segments or feature flags
- **Customer-Specific Processing**: Tailored workflows for different customer tiers or contracts
## Collecting and Returning Data
For synchronous workflows, Orchestrator can collect data from multiple steps and return a comprehensive result. Ecotone automatically handles message passing between steps and returns the final result from the last workflow step:
```php
interface ReportGenerationService
{
#[BusinessMethod(inputChannelName: "generate.customer.report")]
public function generateCustomerReport(CustomerId $customerId): CustomerReport;
}
class ReportOrchestrator
{
#[Orchestrator(inputChannelName: "generate.customer.report")]
public function generateCustomerReport(CustomerId $customerId): array
{
return [
"fetch.customer.data",
"calculate.customer.metrics",
"generate.purchase.history",
"analyze.customer.behavior",
"compile.final.report"
];
}
}
// Each step enriches the data and passes it to the next step
class ReportGenerationSteps
{
#[InternalHandler(inputChannelName: "fetch.customer.data")]
public function fetchCustomerData(CustomerId $customerId, CustomerRepository $repository): ReportData
{
$customer = $repository->find($customerId);
return new ReportData(
customer: $customer,
generatedAt: new DateTime(),
reportType: 'customer_analysis'
);
}
(...)
#[InternalHandler(inputChannelName: "compile.final.report")]
public function compileFinalReport(ReportData $data): CustomerReport
{
// This is the final step - its return value becomes the workflow result
return new CustomerReport(
customerId: $data->customer->getId(),
customerName: $data->customer->getName(),
generatedAt: $data->generatedAt,
metrics: $data->metrics,
purchaseHistory: $data->purchaseHistory,
behaviorInsights: $data->behaviorInsights,
summary: $this->generateSummary($data)
);
}
}
// Usage in controller
class ReportController
{
public function __construct(
private ReportGenerationService $reportService
) {}
public function generateReport(string $customerId): JsonResponse
{
// The workflow executes all steps and returns the final CustomerReport
$report = $this->reportService->generateCustomerReport(new CustomerId($customerId));
return new JsonResponse([
'customer_id' => $report->getCustomerId(),
'customer_name' => $report->getCustomerName(),
'generated_at' => $report->getGeneratedAt()->format('Y-m-d H:i:s'),
'lifetime_value' => $report->getMetrics()['lifetime_value'],
'churn_risk' => $report->getMetrics()['churn_risk'],
'total_orders' => count($report->getPurchaseHistory()),
'preferred_categories' => $report->getBehaviorInsights()['preferred_categories'],
'summary' => $report->getSummary()
]);
}
}
```
**Key benefits of data collection workflows**:
- **Automatic Data Flow**: Ecotone handles passing enriched data between workflow steps
- **Incremental Building**: Data is progressively enriched as it flows through the workflow
- **Final Result**: The last step's return value becomes the workflow's final result
**Real-world use cases**:
- **Report Generation**: Collect data from multiple sources and compile comprehensive reports
- **Data Enrichment**: Progressively enhance data with information from various services
- **Calculation Pipelines**: Perform complex calculations that require multiple steps
- **Validation Workflows**: Validate data through multiple validation layers
- **Aggregation Processes**: Combine data from different domains into unified results
## *Using Splitters for Batch Parallel Processing*
Splitters excel at breaking down collections into individual items that can be processed concurrently. This way we can easily create batches of Messages to process as part of our workflow.
```php
class BatchOrderOrchestrator
{
#[Orchestrator(inputChannelName: "process.order.batch")]
public function processBatch(OrderBatch $batch): array
{
return [
"validate.batch",
"split.orders", // Splitter step - breaks batch into individual orders
"process.individual.order"
];
}
}
class OrderBatchSplitter
{
#[Splitter(inputChannelName: "split.orders")]
public function splitOrders(OrderBatch $batch): array
{
// Splitter returns array where each item becomes separate Message to process
// Each order will be processed in parallel
return $batch->getOrders();
}
#[Asynchronous('order_processing')]
#[InternalHandler(inputChannelName: "process.individual.order")]
public function processIndividualOrder(Order $order): void
{
$pricedOrder = $this->pricingService->calculatePricing($validatedOrder);
$processedOrder = $this->paymentService->processPayment($pricedOrder);
}
}
```
This is powerful yet easy to use concept, where we can by simple returning array tell Ecotone to parallel the work that's need to be done.

**Key benefits of splitter-based parallel processing:**
- **True Concurrency**: Multiple items processed simultaneously across async channels
- **Resource Optimization**: Heavy processing distributed across multiple async channels
- **Scalable Architecture**: Add more processor instances without changing workflow logic
- **Fault Isolation**: Failure in one parallel branch doesn't affect others
- **Dynamic Processing**: Processing steps determined at runtime based on item properties
## Isolated Testing
Testing Orchestrator-based workflows is really simple, as Ecotone provides support in form of `EcotoneLite`.
It allows us to test our full workflow logic in isolation, where we can stub out any external dependencies if necessary.
```php
public function test_premium_customer_receives_full_benefits(): void
{
$ecotoneLite = EcotoneLite::bootstrapForTesting([
OrderOrchestrator::class,
OrderProcessingSteps::class
]);
$premiumCustomer = new Customer(type: CustomerType::PREMIUM);
$order = new Order($premiumCustomer, [
new Item('laptop', Money::USD(1500)),
new Item('mouse', Money::USD(50))
]);
$ecotoneLite->sendDirectToChannel("process.order", $order);
// Verify business outcomes
$this->assertTrue($order->hasDiscount());
$this->assertTrue($order->hasFreeShipping());
$this->assertTrue($order->hasPrioritySupport());
$this->assertEquals(ShippingType::EXPEDITED, $order->getShippingType());
}
public function test_workflow_handles_payment_failure_gracefully(): void
{
$ecotoneLite = EcotoneLite::bootstrapForTesting([
OrderOrchestrator::class,
OrderProcessingSteps::class
], [
PaymentService::class => new FailingPaymentService()
]);
$order = new Order(new Customer(), [new Item('book', Money::USD(25))]);
$this->expectException(PaymentException::class);
$ecotoneLite->sendDirectToChannel("process.order", $order);
// Verify cleanup occurred
$this->assertFalse($order->isPaid());
$this->assertFalse($order->hasInventoryReserved());
}
```
Ecotone also provides ability to test out asynchronous steps with In Memory Channels.
Therefore even the most sophisticated workflows can be tested fully and in isolation.
## Summary - The Core Concepts
When using Ecotone's Orchestrator, workflow definitions become living documentation:
```php
// This IS your business process - no hidden logic, no scattered implementations
return [
"validate.order",
"process.payment",
"apply.premium.benefits", // Clear business intent
"expedite.shipping", // Explicit business rules
"send.confirmation"
];
```
The stateless routing pattern eliminates the complexity that has plagued workflow engines.
As there is no state involved, we can deploy workflow changes with zero downtime and need for migrations. Making it possible to deploy workflow changes as part of regular application deployments, which do not require any additional procedures.
- **Zero Migration Headaches**: Change workflows instantly without database migrations
- **Effortless Horizontal Scaling**: Any server can process any workflow step
- **No State Management**: No workflow instances, no cleanup, no orphaned processes
Due to ability to define workflows dynamically, we can build really flexible and adaptive systems, which can even be configured per each customer separately:
```php
// Different customers get different workflows automatically
if ($order->getCustomer()->isPremium()) {
$workflow[] = "apply.premium.benefits";
$workflow[] = "expedite.shipping";
}
if ($order->isInternational()) {
$workflow[] = "customs.documentation";
}
```
Together with that we are able to choose the right execution approach for each use case. As Orchestrator provides:
- **Business Interfaces**: Type-safe APIs for direct workflow execution
- **Event-Driven**: Reactive workflows triggered by domain events
- **Orchestrator Gateways**: Runtime workflow construction from HTTP requests
- **Data Collection**: Synchronous workflows that return enriched results
You don't need to rewrite your entire application overnight to use Ecotone's Orchestrators. You can start with one workflow and expand systematically.
Deploying Ecotone changes doesn't require any additional procedures, as it seamlessly integrates with Symfony, Laravel and other frameworks using Ecotone Lite support.
Therefore testing it out even in production comes with only few steps to be done, which are most about the Workflow you define, rather than the framework itself.
### Write Only Business Logic: Eliminate Boilerplate
URL: https://blog.ecotone.tech/write-only-business-logic-eliminate-boilerplate/
Last updated: 2025-08-20T20:39:58.000Z
When did we accept as normal that 60-70% of code we write is orchestration and boilerplate? Leaving just a fraction of our codebase dedicated to actually addressing real business challenges. Multiple Controllers that do transformations and delegation, Application Services that are only there to execute method on object and then save it. Endless boilerplate that obscures the real business logic buried somewhere in the middle.
> **What if you could skip all that technical noise and write only the code that matters to your business?**
## The Hidden Cost of Traditional Architecture
Let me show you what a typical "simple" user registration looks like in most PHP applications:
```php
get('email')),
$request->get('name')
);
$this->userApplicationService->registerUser($command);
return new JsonResponse(['status' => 'success']);
}
}
// Application Service layer
class UserApplicationService
{
public function __construct(
private UserRepository $userRepository,
private EventBus $eventBus
) {}
public function registerUser(RegisterUserCommand $command): void
{
$user = User::register($command);
$this->userRepository->save($user);
$this->eventBus->publish(new UserRegisteredEvent($user->getId()));
}
}
// Domain layer
class User
{
public function __construct(
private UserId $userId,
private Email $email,
private string $name
) {
$this->recordThat(new UserRegistered($this->userId));
}
public static function register(RegisterUser $command): self
{
return new self(UserId::generate(), $command->email, $command->name);
}
}
```
Count the lines: **34 lines of technical orchestration** for what should be a simple business operation. And this is just the beginning - add error handling, transactions, and you're looking at 50+ lines before you even touch the actual user registration method.
> Every line of technical code is a line that doesn't solve your customer's problem.
## The DDD Promise vs. Reality
Domain-Driven Design promises to put business logic at the center, but traditional implementations often make things worse. You end up with:
- **Application Services** that just delegate to domain objects
- **Controllers** that know too much about domain concepts
- **Command/Query handlers** scattered across multiple layers
- **Routing logic** duplicated in multiple places
- **Endless transformations** between layers
The business logic gets lost in a maze of technical abstractions. Developers spend more time navigating layers than solving problems. This creates narrative that Hexagonal, Layered Architecture, CQRS and DDD is bunch of buzz words which brings complexity rather than simplicity.
But if it would be so bad at the end, big minds of programming wouldn't be promoting this as a way to build cohesive maintainable software. Therefore there must be a way to approach that from different perspective, and that perspective emerges from Declarative Configuration.
## Declarative Configuration: A Different Approach
What if instead of writing all that orchestration code, you could simply declare your intentions and write only the business part of the code?
Here's the same user registration using Ecotone's declarative approach:
```php
recordThat(new UserRegistered($this->userId));
}
#[CommandHandler("user.register")]
public static function register(RegisterUser $command): self
{
return new self(UserId::generate(), $command->email, $command->name);
}
}
```
User is our Core Business Object (Entity/Aggregate/Model whatever we call it). Ecotone will call this factory method, get instance of new User Aggregate and then store it.
> *Aggregates can be stored with inbuilt support Doctrine ORM entities, Laravel Eloquent model or any other object with custom repository.*
**That's it.** No application service. No manual routing. Just pure business logic with a simple declaration that this method handles the "user.register" command.
> Ecotone handles all the technical concerns - routing, persistence, events - while you focus on business rules.
## Universal Controllers: Two Controllers for Your Entire Application
Here's where it gets really powerful. With routing keys, you can handle your entire application with just two controllers:
```php
headers->get('X-Routing-Key');
$commandBus->sendWithRouting(
routingKey: $routingKey,
command: $request->getContent(),
commandMediaType: "application/json"
);
return new JsonResponse(['status' => 'success']);
}
}
class QueryController
{
public function execute(Request $request, QueryBus $queryBus): Response
{
$routingKey = $request->headers->get('X-Routing-Key');
$result = $queryBus->sendWithRouting(
routingKey: $routingKey,
query: $request->getContent(),
queryMediaType: "application/json"
);
return new JsonResponse($result);
}
}
```
**Two controllers. That's your entire web layer.** The frontend sends a routing key like "user.register" or "order.place", and Ecotone automatically:
- Deserializes the JSON into the correct Command/Query object
- Routes to the appropriate handler method and aggregate
- Handles persistence, transactions, and events
- Returns the response with assigned identifier
This solution makes it extremely easy to roll out new features, as all Developers need to do is to provide an method on the Aggregate and mark it with Command Handler.
> This solution works not only for REST API, but also in context of GraphQL. It take care completely of incoming command and queries making effortless to expose and connect things together.
## Real-World Example: E-commerce Order Processing
Let's see how this works with a more complex business scenario - processing an order:
```php
items)) {
throw new EmptyOrderException();
}
return new self($command->orderId, $command->customerId, $command->items);
}
#[CommandHandler("order.confirm")]
public function confirm(ConfirmOrder $command): void
{
if ($this->status !== OrderStatus::PENDING) {
throw new InvalidOrderStateException();
}
$this->status = OrderStatus::CONFIRMED;
}
#[QueryHandler("order.getStatus")]
public function getStatus(): OrderStatus
{
return $this->status;
}
}
```
Your frontend can now:
- Place an order: `POST /command` with header `X-Routing-Key: order.place`
- Confirm an order: `POST /command` with header `X-Routing-Key: order.confirm`
- Check status: `GET /query` with header `X-Routing-Key: order.getStatus`
All routing, deserialization, and persistence happens automatically. You wrote only business logic.
## The Architecture That Emerges
This declarative approach naturally creates a clean, maintainable architecture:
**Domain Layer**: Pure business logic in Aggregates with Command/Query handlers
**Infrastructure Layer**: Handled entirely by Ecotone's configuration
**Application Layer**: Eliminated - commands go directly to domain objects
**Presentation Layer**: Two universal controllers that route based on intent
> When you remove technical boilerplate, what remains is pure business value.
## Benefits You'll Experience Immediately
- **Faster Development**: No more writing application services, complex controllers, or routing logic. Focus on business rules.
- **Simpler Testing**: Test business logic directly without mocking infrastructure concerns.
- **Better Maintainability**: Changes to business rules happen in one place - the domain object.
- **Clearer Intent**: Routing keys make the system's capabilities explicit and discoverable.
- **Reduced Complexity**: Fewer layers, fewer abstractions, fewer places for bugs to hide.
- **Easier AI Development**: If you use AI for development, you will get better results with generated code, as context provided to AI Model will be much smaller, therefore more focused.
## The Simple Architecture Promise
**Write only business logic.** Let declarative configuration handle the technical concerns. Use Command Handlers directly on Aggregates to eliminate application services. Route everything through two universal controllers using routing keys.
This isn't just cleaner code - it's a fundamentally different way of thinking about application architecture. Instead of building technical scaffolding around business logic, you declare business intentions and let the Ecotone provide the scaffolding and abstract away repetitive code.
The result of this? Applications that are easier to understand, faster to develop, and simpler to maintain. Applications, where every line of code serves a business purpose.
> **Your customers don't care about your application services. They care about the problems you solve. Focus on what matters.**
### Message Channels: Zero-Configuration Async Processing
URL: https://blog.ecotone.tech/message-channels-zero-configuration-async-processing/
Last updated: 2025-08-10T20:34:04.000Z
Almost any business requires asynchronous processing. Whether you're sending emails, processing payments, or handling file uploads, blocking your users while these operations complete creates terrible user experience. Yet most PHP developers avoid async processing because the infrastructure complexity feels overwhelming.
What if I told you that making any PHP method asynchronous could be as simple as adding a single attribute? And switching between message brokers - from RabbitMQ to Kafka to database queues - required zero code changes?
## The Problem: Async Processing Shouldn't Be This Hard
PHP developers face a unique challenge with asynchronous processing. Traditional solutions require:
- Complex message broker setup and configuration
- Manual queue management and routing logic
- Separate consumer processes with custom polling mechanisms
- Error handling and retry logic scattered throughout the codebase
- Different implementations for different message brokers
I've seen teams spend days, or even weeks setting up async processing, only to discover they've created a maintenance nightmare. And Developers to avoid this at all cost, try to reuse what is already there, even if it's not the best fit.
Not to mention that decision like switching from RabbitMQ to Kafka sounds like impossible mission.
### The Traditional Async Processing Nightmare
Most PHP developers face this scenario daily: an e-commerce order triggers multiple operations - payment processing, inventory updates, email notifications, and shipping calculations. Processing these synchronously creates a terrible user experience:
> **The result? Frustrated customers, abandoned carts, and scalability nightmares.**
## Enter Message Channels: Communication Made Simple
Message Channels in Ecotone solve this by providing **a communication abstraction that just works**. Think of them as intelligent postal services for your application - you state the intent, and postal service take care of the rest.
### What Makes Ecotone Message Channels Special?
**1\. Zero Infrastructure Complexity**
Unlike traditional message queues that require separate services, complex configurations, and worker management, Ecotone Message Channels work with your existing database, Redis, or any supported backend.
**2\. Automatic Consumer Registration**
The moment you register a **Message Channel via ServiceContext**, Ecotone automatically creates a consumer that can process messages from that channel. No additional setup required.
**3\. Intelligent Message Routing**
The `#[Asynchronous]` attribute creates automatic message routing with zero configuration. You simply declare which channel should handle your message.
## The Good Magic: ServiceContext + Asynchronous Attribute
Here's how you transform that synchronous nightmare into an elegant, asynchronous flow:
> **That's it. No worker configuration, no queue management, no complex routing rules.**
## Automatic Consumer Registration: The Hidden Superpower
Here's what most developers don't realize: **the moment you add a Message Channel via Service Context, Ecotone automatically registers a Message Consumer** that can process messages from that channel.
Run it with one command:
```bash
bin/console ecotone:run notifications
```
## The Asynchronous Attribute: Routing Without Rules
The `#[Asynchronous]` attribute creates **intelligent message routing with zero configuration**. You simply declare which channel should handle your message:
**Ecotone automatically:**
- Routes messages to the correct channels based on the `#[Asynchronous]` attribute
- Handles message serialization and deserialization
- Manages consumer processes and lifecycle
- Automatically set ups queues with durable configuration
- Ensures message delivery guarantees
## Switching Between Sync and Async: Zero Effort
Want to test something synchronously first, then make it async? **Just add the attribute:**
**The business logic stays exactly the same.** Only the execution model changes.
> This is the power of declarative configuration - you focus on what you want to happen, not how to make it happen.
## Switching Between Brokers Becomes Trivial
We want to change Message Broker, then we simply switch the Message Channel implementation:
**No other changes needed, from application perspective nothing changes.**
## Testing: Async Made Simple
Let's follow on our e-commerce scenario with following approach:
Testing async flows becomes trivial with Ecotone's built-in testing support:
**No mocking, no complex setup.** The test runs the actual async flow in memory.
## Why This Matters for Your Team
**Reduced Development Time**: No more writing boilerplate job classes and queue configuration.
**Better Code Organization**: Business logic stays in domain services, not infrastructure classes.
**Easier Testing**: Async flows test the same as synchronous code, no complex setup needed.
**Simplified Deployment**: No separate worker configuration or running setup.
**Team Productivity**: New developers can add async processing within minutes, not days.
> When architecture handles the technical concerns automatically, developers can focus entirely on solving business problems.
## Getting Started
1. **Add a Message Channel** via Service Context
2. **Mark handlers with** `#[Asynchronous]`
3. **Run the consumer** with `ecotone:run`
That's literally it. No configuration files, no infrastructure setup, no complex deployment procedures.
**Message Channels in Ecotone prove that async processing doesn't have to be complicated.** When you remove the configuration overhead and focus on declarative intent, building scalable systems becomes as simple as adding an attribute.
The next time you need async processing, ask yourself: do you want to spend time configuring infrastructure, or solving business problems?
---
*Ready to experience zero-configuration async processing? Check out the* [*Ecotone documentation*](https://docs.ecotone.tech/?ref=blog.ecotone.tech) *and see how Message Channels can transform your application architecture.*
### Advanced Messaging in PHP: Kafka, Distributed Bus and Dynamic Channels
URL: https://blog.ecotone.tech/ecotone-enterprise-kafka-distributed-bus-dynamic-channels-and-more-2/
Last updated: 2025-04-14T18:34:54.000Z
From now besides Free features, Ecotone will also provide Enterprise ones. Enterprise features are more advanced functionalities which aims to help building larger scale systems, optimize system costs, and to speed up daily development even more.
Ecotone Enterprise is available via subscription. After subscription is started (which can be done at the [main page](http://localhost/pricing?ref=blog.ecotone.tech)), we will receive licence key, which will grant us with access to new Enterprise features.
There few key Enterprise features, which we will now go through, to see how do they looks like and what we can expect from them.
### Kafka Integration
One of the key Enterprise features is integration with Kafka.
Ecotone provides two main ways of integrating using Kafka:
- Custom Message Publishers and Consumers
- Kafka Message Channels
#### Custom Message Publishers and Consumers
Custom Message Publisher and Consumers are meant for making it possible to integrate Ecotone Applications into existing Kafka infrastructure with ease.
Publisher and Consumers are higher level abstractions, so we don’t need to deal with low level complexity of the Broker.
#### Let’s take a look, how we would define Message Consumer:
To start subscribing to given topic, we will use KafkaConsumer attribute, which will register new Message Consumer for us:

Message Consumer connecting to orders topic
Above code will register Message Consumer named “shipping-order”, which will consume from topic “orders”. By default it will use **endpointId** as our **Group Id**, however that can be customized.
There is no need for any more configuration, we are basically ready to run this Message Consumer (Worker):
```bash
# Symfony
bin/console ecotone:run shipping-order -vvv
# Laravel
artisan ecotone:run shipping-order -vvv
# Ecotone Lite
$messagingSystem->run("shipping-order");
```
Under the hood Ecotone use fast and stable integration with “rdkafka”, and adds ability to customize all rdkafka options for Publishers and Consumer if we wish too. However in most of the scenarios, no extra configuration will be needed, as Ecotone provides sensible defaults.
> By default Kafka is not configured for resiliency, things like ensured Message order, delivery guarantee are disabled. Ecotone changes that default configuration, therefore all safety configurations are enabled by default.
Let’s take a look, how we would define Message Publisher:
Message Publisher are configured using Ecotone’s **Service Context** which returns configuration objects.

Kafka Publisher registered under given name in Dependency Container
By providing **referenceName** we provide name under which Message Publisher will be registered in our Dependency Container.
This configuration is enough to already be able to inject our Publisher in our Application level code and start sending Messages.

Injecting MessagePublisher registered by Ecotone and publishing Event to “orders” topic
After Publisher is executed, it will convert given Object into serializable format (depending on configuration), and then send it to topic with name “orders”. This way with minimal amount of code, we can build Publishers for different topics.
> There are different ways we can send our Messages using Message Publishers. We could send simple string based data and provide Content Type, or like in above example specific Object and let Ecotone do the serialization. Alongside with data, we could also pass Metadata.
Let’s now take a look on Kafka Message Channels.
#### Kafka Message Channels
Message Channels are one of the main Ecotone’s abstraction for communication. It provides seamless way to communicate asynchronously using Messages, and integrates nicely with higher level features of Ecotone.
> If you want to find out about Ecotone’s architecture and how all Messaging parts play well together, read documentation page at “docs.ecotone.tech”.
As our example we will take simple scenario of sending notification after User was registered. On high level it would look like this:

Event Message goes to Message Channel and then is consumed by Notification Sender
Let’s start by defining our Kafka Message Channel using Service Context:

Kafka Message Channel named “async”
We could then have some Command Handler which is publishing an User Was Registered Event using Event Bus.

Publishing User Was Registered Event
and then we would have Event Handler subscribing to this Event, which would be triggered asynchronously after this Message is consumed from our Kafka Topic:

Message will first land in Kafka Message Channel named “async”, and then will trigger Event Handler
As we can see this is really simple. We can reuse our Kafka Message Channel for different Asynchronous Message Handlers, and Ecotone will take care of routing to the correct Message Handler. This makes the development using Kafka really smooth and quick for Developers, moving technical the focus on the application level side of code.
#### Aggregates with Kafka Channels
Suppose we are build ticketing service, and we do have Ticket Aggregate (model/entity), which provides an action “close”. This action is asynchronous, and In Ecotone world could be modeled like this:

Asynchronous Command Handler action
Now what will when “async” is Kafka Message Channel, is that Ecotone will use aggregate id instance as partition key for Kafka Topic. This way all Commands that will be send to given Ticket instance, will be handled in order as they will all end up in same partition. This way out of the box we get ordering in our systems.
> Ecotone will provide context to each Event Message recorded in Aggregate, about it’s origins — Aggregate Id from which Event originated. This Aggregate Id will be used as partition key for Asynchronous Event Handlers, ensuring that even if system is under high load, there will be no conflicts in processing. Therefore automatic partitioning works for both Async Command Handlers and Event Handlers.
You can read more about Kafka integration in the [documentation page](https://docs.ecotone.tech/modules/kafka-support?ref=blog.ecotone.tech).
### Dynamic Message Channels
The next big feature of Ecotone Enterprise are Dynamic Message Channels.
Dynamic Message Channels are meant to provide flexible way of changing how messages are routed, how they are consumed and to allow for customization for even more sophisticated business requirements.
#### Distribution per Client
There may be situations when we would like to introduce Message Channel per Client. This is often an case in Multi-Tenant environments, where some Client would pay extra for additional processing power.
In Ecotone we can keep our code agnostic of Multiple Channels, and yet provide this ability to end users in a simple way.
Taking as an example Order Process:

Placing order Command Handler. Orders placed for given Tenant (Client) should have extra processing power
This code is fully agnostic to the details of Multi-Tenant environment. It does use Message Channel “orders” to process the Command. We can however make the “orders” an Dynamic Channel, which will actually distribute to multiple Channels. To do this we will introduce distribution based on the Metadata from our Command.

Routing Messages to different channels based on tenant header
Now to actually route a Message we will provide metadata while sending Command:

This Command will be routed to ****tenant\_a\_channel**
Of course we can have “standard” Clients which will running under shared Message Channel (Queue), therefore they won’t have their own processing pipeline:

If Tenant does not match “tenant\_a” or “tenant\_b”, it will go to shared\_channel
Then we would run Message Consumption (Workers) for each of the channels:
```bash
# Symfony
bin/console ecotone:run tenant_a_channel -vvv
bin/console ecotone:run tenant_b_channel -vvv
bin/console ecotone:run shared_channel -vvv
# Laravel
artisan ecotone:run tenant_a_channel -vvv
artisan ecotone:run tenant_b_channel -vvv
artisan ecotone:run shared_channel -vvv
# Ecotone Lite
$messagingSystem->run("tenant_a_channel");
$messagingSystem->run("tenant_b_channel");
$messagingSystem->run("shared_channel");
```
Of course we could also scale up Message Consumption process for each of the Channel separately.
We don’t even need to run shared\_channel directly, we could run our Dynamic Message Channel instead. Which would pick up Messages from all related sub-channels in round robin manner:
```bash
# Symfony
bin/console ecotone:run orders -vvv
# Laravel
artisan ecotone:run orders -vvv
# Ecotone Lite
$messagingSystem->run("orders");
```
> Dynamic Message Channels can also be used to simplify deployment strategy. We may simply combine multiple channels being used in Application under single Dynamic Message Channel and run it single process that will consume from all of them. This may be especially useful if the volume of Messages in our System is low.
### Throttling Strategy
Let’s take as an example of Multi-Tenant environment where each of our Clients has set limit of 5 orders to be processed within 24 hours. This limit is known to the Client and he may buy extra processing unit to increase his daily capacity.
So let’s start by defining our Dynamic Message Channel with throttling strategy:

Dynamic Message Channel with throttling strategy
In here we are using **“requestChannelName”** this is router to a Internal Handler that will make the decision about the consumption. Internal Handler is fully under our control and should return true/false for given channel name:

This will be called by Dynamic Message Channel to decide on consumption
Our Internal Handler can call database for example to verify how many orders have been placed for given Tenant (Client). If it reached the limit we would simply return false and skip the consumption from that Channel.
This way we take over the process of consumption at run time, which allows us to business based decisions based on current situation.
> Often used solution to skip processing/throttle is to reschedule Messages with a delay and recheck after some time. This solution however will waste resources and block processing of other Messages, as we consume something that is not meant to be handled only to reschedule. Therefore Ecotone’s throttling strategy provides alternative, which skips the consumption completely, so we can avoid wasting resources on polling or rescheduling Messages, as we simply don’t consume them at all.
Dynamic Message Channels does also provides ability to define any customized Sending or Receiving Strategy. This way we can fully take over the process and customize it to our needs.
To find out more, read [related documentation page](https://docs.ecotone.tech/modelling/asynchronous-handling/dynamic-message-channels?ref=blog.ecotone.tech).
### Distributed Bus with Service Map
On more big feature which we will mention within this article is Distributed Bus with Service Map. Distributed Bus is meant to solve complexities that cross application integration brings, by making integration easy to follow, change and understand no matter of Developers experience level.
**Service Map** is a map of integrated Services (Applications), and points to specific Message Channels to which Messages for given Service should be sent:

Service Map of Applications that are integrated together
In this approach **Message Channels (Pipes) are simple transport layer**, and the **routing is done on the Application (Endpoint)** level using **Service Map to make the decision**.

Routing is done via Service Map to given Message Channel
When given Message is sent it will be routed to related Channels. This way Message will land in Channels owned by given Service, and can be consumed from there.
> Ecotone provides multiple implementations of Message Channels e.g. RabbitMQ, Kafka, Redis, SQS, Dbal, or even Symfony Messenger Transport or Laravel Queues. This means that all of those can be used for cross-service integration with ease.
In the code configuration for Service Map could look like this:

Example Service Map configuration, pointing given Service Names to Message Channels
> It’s good practice to share Service Map between Applications. This way it becomes one source of truth on how integration works. Making it easy for everyone to understand the topology of the System.
### Command Distribution
Let’s suppose **User Service** wants to create Ticket by sending Command to **Ticket Service.**
In Ticket Service we will explicitly state that we allow given Command Handler to be executed in Distributed way. This makes it clear for everyone that we can’t simply delete this Command Handler, as other Services may rely on this integration:

Distributed Command Handler in Ticket Service (Application)
On the side of User Service we would send this Command to Ticket Service:

Sending Distributed Command to Ticket Service (from User Service)
**targetServiceName** is the name of the Service which we target, and will be used to find out Channel Name to which we need to send using Service Map, **routingKey** is the name of Command Handler which should be executed.
> By providing **target Service Name** we explicitly state where this Command should go. This way we secure the integration, as in case targetted Command Handler would not exist, we would still deliver the Command, which would fail on other side, and land in Dead Letter, therefore it gives ability to fix the integration without losing Message.
### **Event Distribution**
Event distribution is a bit different from Command distribution. In case of Command we do have single Service that will receive the Message, in case of Events however there may be multiple of them.
Let’s expand our previous example to include Order Service, and our scenario is that whenever new User is registered in User Service, we will publish this event to both Ticket and Order Services.

On the consumption part we will be marking our Event Handlers with Distributed:

Subscribing to Event Distributed under “user.was\_registered” name
On the publishing side we will use send Message as Event:

Publishing Event with “user.was\_registered” name
By default Event will be published to all Services in the Service Map, with exception of originating Service that publish this Event, this one will be skipped (to avoid publishing to itself). Therefore the default behaviour broadcast the Event to all Services defined in Service Map.
#### Filtered Event Publishing
The default behaviour speeds up development, as with minimal configuration we can integrate multiple Services. However for large scale volume of Events, we may want to avoid publishing Events to non-interested Services. For this we can use **filtered publishing**.

Two Services subscribes to same Event Message
In our Service Map the configuration for filtered publishing would could look like this:

Subscribing using explicit event name, or using wildcard to subscribe to given set of events
Using above Service Map, Event will be published to given Service only if it matches subscription key. Therefore we can avoid publishing Events to non-interested parties.
> When Service Map is defined as separate shared library. It becomes explicit what Events is given Service interested in. This also makes the process of subscribing to new Event visible for everyone, therefore we avoid hidden coupling that could lead to broken integration.
There are of course more features around Distributed Bus, which allows us for example to create multiple Service Maps or to introduce multiple Message Channels for targeted Service (e.g. Event or Command Channels).
To find out more, read [related documentation page](https://docs.ecotone.tech/modelling/microservices-php/distributed-bus?ref=blog.ecotone.tech).
### Summary
Ecotone Enterprise does provides more advanced set of features, which greatly enhance development process, by providing tools which help to deliver business features quicker, and also to solve product related challenges like optimization of resources, visibility of how things are integrated, and long-term maintainability by keeping things simple.
> For first new Users, Ecotone Enterprise comes with **40% discount code** for first subscription payment. Go to [https://ecotone.tech](https://ecotone.tech/?ref=blog.ecotone.tech), proceed with chosen subscription, provide promo code “**resilientmessaging**”, and discount will be applied.
> Offer will be available up to 10th of April with limited number of uses.
Features mentioned in this article are covered on high level, and are not all features provided by Ecotone Enterprise. There to find out to find out more, visit [documentation page](https://docs.ecotone.tech/enterprise?ref=blog.ecotone.tech).
### Robust and Developer friendly Application Architecture in PHP
URL: https://blog.ecotone.tech/building-resilient-and-scalable-systems-by-default/
Last updated: 2025-03-21T17:09:40.000Z
In this article we will dive into how to build resilient and scalable architecture with full focus on development experience and delivery speed. We will dive into making such architecture a default state for our System, so scalability and resiliency is not something we need to struggle for, it’s just side effect of our daily development.
Yet before we will dive into “how”, we first need to explore what scalability and resiliency actually means.
### Scalability and Resiliency traits
**Scalability** means that architecture will not break when the load increases. It also means that even on high peaks, we are able to distribute load and adjust.
On other hand **Resiliency**, means that System is prepared for failures. It will try to self-heal by default, and would require intervention from Developer only, if unrecoverable failure happens. It also means no data is lost in case of fatal errors, to make recoverability actually possible.
This both characteristics are also joined in **processing isolation**.
This means instead of requiring to handle multiple things at once (batch like), we allow for processing of each separately and concurrently. This way we can scale the processing, and in case of failure allow to retry — only the thing that actually failed.
> Scalability and resiliency are actually characteristics of Message based communication. So by exploring Messaging we can actually get to know how to build scalable and resilient Systems.
However introducing Message based communication due to it’s complexity can often lead to frustration, and if not implemented correctly can even lead to demotivation.
### Demotivating Architecture
So if Message based Communication solves resiliency and scalability, then after this architecture is built, in theory we should be good.
Yet this more often than not, is a false impression. Messaging and resiliency patterns brings a lot additional complexity, and if we won’t introduce higher level abstractions, developers will end up in investing time into setting up configuration, writing boilerplate code to fulfil required steps, and wiring things together in their daily development. This as a result slows down development of business features, as time is invested in technical aspects of the messaging.
This often leads to questions, whatever we do have time for focusing on resiliency or scalability, as we could deliver given feature much quicker by avoiding this architecture completely. Enforcing such architecture may lead to even worse results, by creating a feeling of being forced to use something which is not helpful. This eventually may lead to demotivation and lack of enjoyment in the project.
> To solve complexity and additional development effort that Message based communication brings, we need to push abstractions higher. To the level where it becomes easier to write code which is resilient and scalable, than code that does not follow those principles.
The architecture must create environment where Developer can focus on their daily task and business flows, not on setting up configuration, writing repetitive steps, and wiring. And that kind of architecture, which not only solves scalability and resiliency problems, but yet creates smooth development experience I do name — **Business Oriented Architecture**.
### Business Oriented Architecture
Business Oriented Architecture makes it easy for Developers to fully focus on business features / tasks they are working on, yet benefit from all scalability and resiliency patterns working under the hood.
To fully understand what does that mean, we need to explore three pillars that this architecture introduce.
Business Oriented Architecture introduces three pillars to make the feature delivery as smooth as possible. Each pillar abstracts given set of problems so we can focus more on things like business logic and flows.
Let’s explore what does each pillar mean, and how it was implemented in Ecotone Framework:

Each pillar abstracts away given type of problems, therefore what is left to write is Business Oriented code
### Resilient Messaging
So at the core of Business Oriented Architecture is **Messaging**, based on [Enterprise Integration Patterns](https://www.enterpriseintegrationpatterns.com/?ref=blog.ecotone.tech).
> This abstraction level, ensures that every component / module or application is easily connected together, yet fully decoupled.
>
> At this level everything is a Message, which flows over Message Channels. This means we can easily switch any part of the code to run asynchronously to ensure scalability.
> This level of abstraction also covers **Resiliency** patterns like:
- Automatic Retries and Dead Letter
- Idempotency
- Outbox pattern
When Ecotone Framework wasn’t open sourced, Resilient Messaging abstraction was the only one available (other pillars have not existed yet).
This however required from Developers to configure different parts of the Framework, **which contributed to several drawbacks:**
- Time was invested in setting up Messaging configuration, which more often than not was pretty much similar between features
- As things were not auto-configured, it exposed possibility for setting up configuring incorrectly, which lead to debugging and reverse engineering
- It also coupled Framework with Application level code. When configuration in Framework have changed, it required changes in related Applications
So above situation was far from ideal and required different way of solving things, and for this **Declarative Configuration** was introduced.
### Declarative Configuration
Aim to make daily development quicker, more robust and to decouple Application level code from Framework level code, created the need for introducing second pillar — **Declarative Configuration**.
> The goal was to make Developers focus on the business features they deliver, yet to keep all scalability and resiliency as the foundation.
>
> At the end Developer was meant to simply install the Framework and get all the goods without any additional configuration. Basically even Developers without the knowledge of Messaging or Resiliency patterns were meant to use Ecotone without any problems, yet with all it’s benefits. For this Declarative Configuration using Attributes was introduced.
- Instead of providing configuration on how to wire given class and connect it to Messaging, we simply mark given method with **CommandHandler** attribute. This is enough for Framework to know what is our intention, and do the configuration for us:

Simply mark given method as Command Handler, to make it accesible via Command Bus
- When we will add **Asynchronous** to the Command/Event Handler, this specific Handler will be executed asynchronously. This is also related to processing isolation mentioned earlier, it’s not the Message that is handled Asynchronously, it’s Message Handler that is. This way even if multiple Event Handler subscribers to the same Message, each of them is processed independently.

To execute given Message Handler asynchronous, is matter of adding Attribute
- To delay given execution, it’s enough to add Delayed attribute. The same way we can add for example priority or time to live.

Adding additional features does not require any effort or external configuration
- Declarative configuration also contributes to full decoupling from the Framework. Our Commands or Events classes that we’ve created does not extend or implement any Framework specific classes.

All Classes are pure POPO. They do not extend or implement any Framework Classes.
- The same principle of decoupling applies to Message Headers, they are not part of our Application level classes. They are part of Ecotone’s Message which is abstracted away, yet always available for us.
What is worth to mention, is that Headers are automatically propagated, so we don’t need to pass them around in our Command or Event classes.

Sending Command with Metadata, and accessing Metadata in the Handler
- The decoupling process can also done in our Controllers. If we want, we can simply use routing and let Ecotone do the transformation from given Media Type to Command Class on fly

We can simply send Messages by routing key from Controllers, no need to do transformation there
- Based on routing, we can also leverage our Messaging abstraction that allows for input-output based architecture. Which creates environment in which workflows can be build

Connecting Message Handlers using intput-output channels
There are of course much more Attributes and features available, but the above is enough to show how daily development became smooth and decoupled from extending or implementing any Framework specific classes. And when given Message Handler is not needed, we simply delete this method together with attributes, and given functionality is cleared.
Thanks to decoupling from the Framework, any internal changes to the framework do not affect Application level code anymore. This basically allowed Ecotone to keep same major version for over three years now, without a single breaking change while delivering a lot of new features and even huge refactors. From the side of Developers using the Framework they do not need about framework changes anymore, as they simply upgrade the package and everything continues to work.
Yet there is one more things that can help us with daily development, which speeds up development even more — **Building Blocks**.
### Building Blocks
We could of course use Ecotone based only on two first pillars, yet by adding third one - we basically create environment in which we focus mainly on the business logic — therefore we start to deliver features really quickly.
One of the first patterns which emerged to streamline development even more are — **Aggregates**. To understand the need for them, let’s look how often Command Handlers does look like:

Three steps action, that is most common implementation of Command Handler
This code is repetitive by nature, and is called orchestration level code. Writing repetitive code is not best way of using our time. It’s not only our time that we actually invest into this, it’s whole team’s time, as now as it was written someone need to review it, and as it’s merged it becomes internal part of the project, which need to be maintained and changed together with the feature.
So one of the Building Blocks that Ecotone introduce, are **Aggregates**.
Aggregates allows us to keep the business logic within the Entity / Model, and Ecotone will ensure to do all repetitive steps — like loading, executing method and storing. This way all the orchestration code is gone.

Executing Command using Aggregate Building Block
Ecotone also provides advanced support for Event Sourcing with different persistence strategies. This support can be used directly by storing events in Event Store. However it can also be used with Building Blocks like **Event Sourcing Aggregates**.

Return Event from Event Sourcing Aggregate, and Ecotone will store it in the Event Stream
If we use Event Sourced Aggregates, we basically avoid writing orchestration code, code responsible for persistency or code responsible for publishing those Events. This creates a space for Developers to fully focus on the business problem at hand.
This joins nicely with next build block — **Projections.** Projections can be triggered synchronous or asynchronously, and will project given view based on the related Event Stream:

Projection building an view from Order’s Event Stream
As you can see the speed of delivery basically sky-rockets while using Building Blocks. Instead of writing a lot of orchestration code ourselves, we simply state what we want to achieve with Declarative Configuration, and write only business specific logic.
The speed of delivery is not only directly related to the code we write, but to what happens after — so when we use Building Blocks there is much less code to review, it’s easier then to spot potential bugs, and less chance to configure orchestration incorrectly.
### Summary
Business Oriented Architecture creates environment in which Developers can fully focus on the task at hand, writing business related code, yet keep the System scalable and resilient by default.
There is no need to force anybody into doing that, because Message based communication becomes part of design, that does not require additional time to invest.
Ecotone Framework is built in PHP, so if that’s language of your use, you can explore more [details here](https://docs.ecotone.tech/?ref=blog.ecotone.tech). And if you have not used PHP recently, I encourage you to explore it, as with Ecotone it became really easy to build even the most complex systems with ease.
### Practial Domain Driven Design
URL: https://blog.ecotone.tech/practial-domain-driven-design/
Last updated: 2024-10-08T15:22:26.000Z
Theory can lead to experience by practice. However theory without practice will not give us real understanding of how things are done.
Therefore we need to try things out, we need to get our hands dirty, if we want to understand fully and become confident in what we do.
The same is with Domain Driven Design (DDD), we may read multiple blogs, watch videos, or even go to workshops, yet those, without our own practice will not give us real understanding.
**And if we want to learn things like:**
- What is business and technical part of the code
- How to model our Domain
- How to build business flows
we have to get first hand experiences in real Projects. By making mistakes, applying solutions, and facing challenges, we can actually see how things play together, and start to understand DDD in applicable form.
> We get confidence by practice, not by theory. And by practice we actually get to know what is DDD about.
## Layers of rules
One of the challenges which may block us from applying the knowledge in practice, are layers of rules that have been created around DDD.
We may face statements like:
- You must not use Active Record
- You must not create dependency between architecture layers
- You must keep your Domain Objects fully pure
If we will believe such statements and our whole architecture is based on Active Record for example, we’ve just blocked ourselves from doing DDD in practice. Now “To follow DDD” we will need to convenience everyone in the Project to change the way objects are mapped to database, and then lead everyone to big scale refactor.
Doesn’t it sounds silly?
In one of my first DDD projects, we’ve decided that we will follow the rule of — “Each architecture layer being fully decoupled”.
Following this rule made us spend enormous amount of time on doing transformation between layers. That time was not invested into understanding the business better, that time was invested in following “the rule”.
At the end everyone who was involved in the projected agreed, that this way of doing things was complicating our lives with little benefit. It simply did not worked in our context.
And the Context is the most important thing here. It’s really up to the context we work in, if given rule or design pattern make sense. We will feel which rules are helpful as they make development simpler, the harmful ones will create time consuming practices to follow.
And when development is simpler we regain the time, which now can be invested in what matters — understanding the business logic more.
> The ideal design does not exists, as it depends on the context in which it’s applied. Therefore there is only design which can simplify development, and one that will make it harder.
## Business Oriented Architecture
What I wanted to achieve is to take different patterns, rules and design styles, which proved to be helpful, and expose them in form of Architecture. This meant that instead of reimplement those patterns between the projects, I would simply “pull” such Architecture and start focusing on the business side of things from day one.
Of course that requires patterns that solves problems like resiliency, scalability, recoverability at the architecture level. Besides that we need to abstract things like orchestration and configuration code away.
So what I’ve found to be effective in order to achieve that, was combination of Tactical DDD patterns with Resilient Messaging, which I describe as Business Oriented Architecture.
The Business Oriented Architecture is built on top of three pillars:

Each pillar abstracts away given type of problems, therefore what is left to write is Business Oriented code
1. **Resilient Messaging**
Most of applications needs an way to recover when failures happens. For example when System which we integrate with is temporary unavailable (e.g. Sendgrid, Stripe, Twilio), or there was a bug in the code, or even if part our own infrastructure goes down.
The aim is to make the System try to self-heal in those situations so we don’t even need to intervene. And if self-healing is not possible like with bug in the code, then storing the intention of what was meant to happen, so we can resume the flow when deploy a fix.
This is where Messaging with Resilent Patterns like Outbox, Idempotency, Delayed Retries and DLQ, have proven to solve those problems at the root level.
2. **Declarative Configuration**
When Messaging is taking care of resiliency and also scalability part, there is still a problem of spending too much time on configuration either of Messaging or Application related things. The more configuration we have, the more it will become burden to maintain, which creates space for making mistakes and time consuming upgrades. Solution for that are sensible defaults and Declarative Configuration with Attributes. Attributes helps us state “what should happen” and abstracting away “how it should happen”. This in combination with Messaging, connects our components under the hood without a single line of configuration needed. Declarative Configuration is a power house for development which is intuitive and easy to change.
3. **Building Blocks**
Between Messaging and higher level components, there is still a need for delegation/orchestration logic.
Good example of this are commonly used Command Handlers. In most of DDD based Applications, they all basically look the same, fetch Aggregate, call action, save it. This kind of code bring no business value, therefore can be abstracted away using our two previous pillars — Declarative Configuration and Messaging. We can mark Aggregate methods directly as Command Handlers, and let the lower level abstractions do the orchestration logic.
Therefore what is left to write is pure business logic in Aggregate.
Business Oriented Architecture is combination of well defined patterns from Messaging and DDD world. When problems like scalability, resiliency and recoverability are solved on the Architecture level, it frees a lot of our time to focus on other things. When we will add Building Blocks to this, like Aggregates, Sagas, Projections, which are connected directly to the Messaging, there isn’t really much left to write than the business logic itself.
> When we will apply Business Architecture, most of our time consuming problems will be solved on the architecture level. This means we will not be in need to solve them again.
> Therefore the code that is left for us to write, is pure business logic itself.
>
> To explore Business Oriented Architecture more, you can visit PHP Framework — “[Ecotone](https://docs.ecotone.tech/?ref=blog.ecotone.tech)” which is built on top of those concepts.
### Summary
While theoretical knowledge of DDD is valuable, it is the practical application that truly brings it to life.
Different patterns and designs are here to help us. Not all of them will make sense in our context, yet the ones which will, will make the business logic more explicit and development more smooth.
Business Oriented Architecture shows us, that some of those patterns can be combined together to simplify our development even more. And if we will agree to work from higher level abstractions that this Architecture provides, we can regain huge amount of time, which then can be invested in business side of the code.
### Building Workflows in PHP with Ecotone
URL: https://blog.ecotone.tech/building-workflows-in-php-with-ecotone/
Last updated: 2024-05-28T15:40:15.000Z
Almost any business requires Workflows. The type of Workflows we will need to build will depend on the Business Domain we work in. This may be fully automated flows like uploading images, resizing and storing them, or flows which require manual actions at some step like verification, signing or acceptance for example.
Workflows can easily get complicated and existing tooling more often than not create hard coupling between the Application level code and the related Framework. Therefore our code lose the clear business intention, and becomes mix of technical and business concerns. This as a result creates confusion in the code and makes Workflows much harder to understand and maintain, that they actually are.
> Ecotone Framework takes approach of pushing the focus on the business side of the things. It allows us to create even most complex Workflows without the need to extend or implement a single Framework related class. This way business intention behind the Workflow stay crystal clear.
>
> Yet before we will dive into how Ecotone can help us in building Workflows, let’s first understand what high level kind of Workflows we will be dealing with.
### Stateless vs Stateful Workflows
We do have two main types of Workflows — **stateless** and **stateful**.
#### Stateless Workflows
- **Stateless workflows operate without retaining any state from previous interactions, it acts based only on the given input.**
This makes them ideal for things like Data validation and manipulation, Image processing or ETL (Extract, Transform, Load) scenarios.
#### Stateful Workflows
- **Stateful workflows can remember previous inputs, decisions, or steps in a process, allowing for complex, multi-step operations that depend on earlier outcomes and time based actions.**
This makes them ideal for things like Order fulfillment, Customer Service Ticketing or Document based Workflows.
Of course we can combine those two types together, in order to build **hybrid solution**. An good example of this could be Credit Card Approval Process - where first we would fetch and enrich Customer additional details (Stateless) and after that we would kick in confirmation and verification process (Stateful).
We will now discuss an example of Stateless Workflow. Yet if you are unfamiliar with concepts likes Command and Events, it will be good to first read some [basic information on this matter.](https://docs.ecotone.tech/modelling/command-handling/external-command-handlers?ref=blog.ecotone.tech)
### Synchronous Stateless Workflows
I want us to start with most simple workflow type which contains of several predefined steps done synchronously. This will give us taste of how components can be easily connected together and will build foundation before we will dive into more advanced scenarios.
We will focus on **Image Processing Workflow** which will containing of three steps:
1. Validating Image (Checking if file extension is correct)
2. Resizing Image
3. Uploading Image (To some external storage)

Image Processing Workflow
For connecting each step together we will be using Message Handlers.
Each Message Handler will be representing specific step in our Workflow which connected together will create “Image Processing Workflow”.
> Ecotone provides way to create Workflows using input — output ports (Message Channels) in order to determine the next steps. Each input - output port can be easily switched to work synchronously or asynchronously.
>
> Beginning of the Workflow — Command Handler
To kick off the Workflow we will first send **“ProcessImage”** Command from our HTTP Controller:
This as a result will trigger our Workflow starting from **“validateImage” Command Handler** and then will pass the Message forward.
1. We define **Command Handler** attribute which we will be able to trigger using **Command Bus.** This will be our entrypoint to the Image Processing Workflow.
2. Command Handler allows us to define **outputChannelName** which is a Channel to which result will be sent. We will discuss more deeply in a minute.
3. The **result** of this method execution will be passed to the **“outputChannelName”**
#### Part of the Workflow —Meet Internal Handlers
As our Command Handler defines output channel **“image.resize”,** we need to define Message Handler which will receive the Message from this Channel. For this we will use **InternalHandler**:
1. **Input Channel Name** state from which Channel this Handler will receive Messages from
2. **Output Channel Name** states where the result of this method execution should go to
3. **The result** of this method execution passed to output channel name
We’ve used in here **Internal Handler, not an Command Handler.**
Internal Handler is a Message Handler which is not exposed via Command Bus. This means it’s used only internally within our Application. As this is step within the Workflow we don’t want to expose it to be triggered directly and Internal Handlers help us achieve that.
> Internal Handlers are meant to make our code explicit by stating that they are internal part of the Workflow.
> If needed however, we could connect Command Handler with Command Handler. It all depend on our context.
>
> Messaging way to connect things together
Each Message Handler, whatever it’s Command Handler, Event Handler or Internal Handler is connected through Message Channels. In case of Internal Handler we’ve stated that it’s input Channel is “**image.resize”**.

By stating input and output channels we define our Message flow. So **“resizeImage” Message Handler** will be executed whenever Message will arrive on **“image.resize”**.
> Ecotone connects components using underlying Messaging architecture based on [Enterprise Integration Patterns](https://enterpriseintegrationpatterns.com/?ref=blog.ecotone.tech). This provides great abstraction for connecting different parts of the system with ease.
> This way Messages can flow between connected Message Channels, and thanks for declarative configuration application level code stays decoupled from the Framework and Messaging concerns.
>
> All things connected together
Let’s now add the last part of our Workflow “uploadImage” and see how it all connects together:
**ImageProcessingWorkflow** can be triggered just as it’s already, as there is no need for any additional configuration. Message will flow between different Handlers just as defined using declarative configuration with Attributes. This is really powerful way of connecting components using decoupled Messaging communication.
> These three methods marked with Attributes define our Workflow, without extending or implementing any Framework specific classes. All this happens thanks to Ecotone’s Declarative Configuration combined with underlying Messaging architecture.
>
> To see the code for described scenario, we can refer to [Ecotone QuickStart repository](https://github.com/ecotoneframework/quickstart-examples/tree/main/Workflows/SynchronousStateless?ref=blog.ecotone.tech). Examples on how to test this code will also be found in this repository.
### Asynchronous Stateless Workflows
In a lot of business scenarios, we will be having situations where part of the Workflow will need to be handled Asynchronously. The need for that may come from handling given part of Workflow being too time consuming, need for queuing due too big resource consumption, or making some integration more reliable and resilient.
This is where often Workflows gets really complex and hard to follow. The issue is that most of the tooling treats asynchronicity as additional tooling, rather than part of our Workflow model. As a result Application have to pay the price of accidental complexity to maintain.
> Ecotone makes asynchronicity first class-citizen thanks to Message Channels. We can easily introduce Message Channels to make code execution synchronous to asynchronous. As this is done via declarative configuration, we still write the code like it would be synchronous. Therefore the application level code stays clean and easy to follow, no matter of the execution model.
>
> So let’s now make our time consuming tasks like **“image.resize”** and **“image.upload”** done asynchronously.
> To do this we will introduce Asynchronous Message Channel (Queue), before calling Resize Image Message Handler:

Introducing Asynchronous Message Channel before resizing image
To make our flow asynchronous after image is validated, we will add Asynchronous attribute to the resize image step:
It’s important to understand that asynchronous and synchronous are just correlations between steps, and it’s up to us how we want to split the workflow:

Message goes to Asynchronous Message Channel (Queue) before Resize Image is executed
If we want we can make the upload Asynchronous too, we do it simply by adding the Attribute for **upload image Message Handler**:
Therefore our flow will looks like this now:

Message goes to Asynchronous Message Channel (Queue) before Resize Image is executed
> In Ecotone it’s not the Message that is marked as Asynchronous, as Message is just an Data Record. Instead it’s the Message Handler that states that it will handle given Message in asynchronous manner.
>
> Defining Asynchronous Message Channel
So we’ve stated using the Attribute, that given Message Handler should be executed Asynchronously. However we have not defined Asynchronous Message Channel that should be used.
We did provide the reference name of our Asynchronous Message Channel inside the attribute, which in our case is **“async”**.
Now let’s define specific implementation of Message Channel for this reference:
In above example, we’ve chosen to use Dbal Message Channel, which is Database backed Message Channel.
If we would switch the implementation here, our Message would be stored using different implementation. For example we could provide RabbitMQ, Redis, Amazon SQS etc. To find our more, refer to the [documentation](https://docs.ecotone.tech/modelling/asynchronous-handling?ref=blog.ecotone.tech).
To see the code for described scenario, we can refer to [Ecotone QuickStart repository](https://github.com/ecotoneframework/quickstart-examples/tree/main/Workflows/AsynchronousStateless?ref=blog.ecotone.tech). Examples on how to test this code will also be found in this repository.
### Testing Workflows
It’s crucial to have good support for testing Workflows. As it’s really easy to end up with tests taking ages, or ones that are hard to understand and maintain. Therefore the aim is to have reliable test suite, yet the test suite that is actually fast to run and easy to maintain.
Ecotone comes with support for Testing which allows us to:
- Isolate the Workflow or part of it which we want to run under test
- Execute the Workflow in tests like it would be done in Production
- Keep the tests quick and easy to follow
> Ecotone Lite allows us test our functionalities in a way that our production level code works. Therefore the confidence those tests provides, is really high.
> Besides that it allows for Bootstraping the test for given set of Classes, which allows us to isolate the Workflow from the other part of the system. This way depending on our need, we can include or exclude given functionalities from our Test Suite.
>
> To test our Image Processing Workflow we will use **EcotoneLite**:
Without going into too much details what is important here is that within this simple test:
- We’ve created isolated scenario, where we can test Image Processing Workflow without triggering any other parts of the System
- We test asynchronicity with In Memory Channels which are quick. And In Memory Channel in Ecotone behaves like any other Asynchronous Channels, therefore they serialize and deserialize the Messages
- Even so we include asynchronous communication in the test, we still run it in a single process. This makes it easily write, debug and provide replacement In Memory / Stub implementations.
To find out more about Ecotone’s testing capabilities, we can refer to related [documentation](https://docs.ecotone.tech/modelling/testing-support?ref=blog.ecotone.tech). To see the test code in action, you can refer to [Ecotone QuickStart repository](https://github.com/ecotoneframework/quickstart-examples/tree/main/Workflows?ref=blog.ecotone.tech) and take a look on tests catalog in each example.
### Stateful Workflows
As we have seen not all Workflows need to maintain State. In case of step by step Workflows we mostly can handle them using stateless input / output functionality. However there may a cases, where we would like to maintain the state, the reasoning behind that may come from:
- Our Workflow branches into multiple separate flows, which need to be combined back to make the decision
- Our Workflow involves manual steps, like approving / declining before Workflow can resume or make the decision
- Our Workflow is long running process, which can take hours or days and we would like to have high visibility of the current state
For **Stateful workflows** we will be using **Sagas**.
### Saga —the Stateful Workflow
Saga is basically a Stateful Workflow, which keeps the state of previous executions in order to make further decisions.
Saga communicates via Messages, it can subscribe to given set of Messages and publish new ones as a result.
We will build **Order Processing Workflow.**
\- The process will start after Order was placed and will trigger an automatic payment.
\- If payment was successful then the order process will marked as ready to be shipped.
\- If payment fail however it will retried after one hour.
\- If the retry has failed, the Order will will canceled.
Our Saga will be started when the Order Was Placed, this will kick in our Process:
Our **“startWhen”** method will be triggered whenever Order Was Placed event will be published. As a result, it will return new instance of Saga, which will be persisted in our Storage.
> We can provide Custom Storage for Saga using [Repositories](https://docs.ecotone.tech/modelling/command-handling/repository?ref=blog.ecotone.tech). We can also use in-built repositories that integrates with Doctrine ORM, Eloquent Model or Ecotone’s Document Store.
>
> Our Saga publishes the Event **“OrderProcessWasStarted”** and we can subscribe to it to trigger an action. So let’s do it now and trigger an Payment action, after our Saga is started.
We could inject here **CommandBus** to trigger the Payment. However in the example above we have leveraged **output Channel** to avoid using infrastructure level code in our Business Objects.
As taking an Payment involves calling external Service, it’s good to isolate the execution by making it **Asynchronous**. This way any potential failures will not affect storing our Saga in the database.
> Making Message Handler Asynchronous helps in isolating failures and enabling safe retries. To find out more, refer to previous [article on the subject](https://blog.ecotone.tech/building-reactive-message-driven-systems-in-php/).
>
> Our Payment Service responsible for taking Payment could looks like:
Let’s add Event Handler for the Happy Flow in our Saga, that will mark the Order as ready to be shipped, when payment was successful.
As the Event contains of order Id, Ecotone will know which Saga should be loaded for this Event.
> Ecotone provides a lot of options to map given Event/Command to specific Saga/Aggregate instance. More information can be found in [related documentation](https://docs.ecotone.tech/modelling/command-handling/identifier-mapping?ref=blog.ecotone.tech).
>
> We can expose this state to the Customer using Query Handler marked directly on the Saga.
This is the benefit of State based Workflows, as they hold information about current state of the Workflow, which can be exposed outside.
Let’s now handle our failure scenario, where Payment has failed and we should retry it after one hour.
We’ve marked our our Event Handler with Delayed attribute, to delay the execution by one hour. This way after payment has failed we will another retry after one hour.
And if maximum volume of retries is exceed, we will consider Order as cancelled.
> Saga is a Stateful Workflow, as it’s running on the same basics as Stateless Workflows using Input and Output Channels under the hood. The difference is that it does persist the state, therefore the decisions it makes can be based on previous executions.
>
> To see the code for described scenario, we can refer to [Ecotone QuickStart repository](https://github.com/ecotoneframework/quickstart-examples/tree/main/Workflows/Saga?ref=blog.ecotone.tech). Examples on how to test this code will also be found in this repository.
### Summary
Ecotone supports building Workflow using underlying Messaging architecture by providing Input / Output Pipes strategy, which on the high level works like seamless chaining of Message Handlers.
Besides that provides declarative configuration, which allows us to keeps our business code clean from extending or implementing framework related classes.
There are more features that Ecotone provides out of the box, which are out of scope of this article. Therefore if to explore more scenarios like below, please read related documentation page:
- [Handling Workflow failures](https://docs.ecotone.tech/messaging/workflows/handling-failures?ref=blog.ecotone.tech)
- [Correlating Messages with Saga Instance](https://docs.ecotone.tech/modelling/command-handling/identifier-mapping?ref=blog.ecotone.tech)
- [More Saga’s capabilities](https://docs.ecotone.tech/messaging/workflows/stateful-workflows-saga?ref=blog.ecotone.tech)
This all together create robust solution for building Workflows in PHP that stay clear about it’s business intent. Building Workflows does not have to be complicated with good underlying model.
### Integrating PHP Applications with Ecotone and RabbitMQ
URL: https://blog.ecotone.tech/integrating-php-applications-with-ecotone-and-rabbitmq/
Last updated: 2025-03-07T08:52:01.000Z
Integration between PHP Applications (Services) can be really challenging, as we enter area where a lot of things make break and fail. It does not make it easier that often different Applications are owned by different Teams. And to create such integration we need to agree on way we communicate, so both side can understand each other.
The two most common ways of integrating are: “HTTP” or “Message Broker”. There are [potential problems to consider when doing HTTP integration](https://medium.com/nerd-for-tech/starting-with-microservices-in-php-6e3c411f3d27?ref=blog.ecotone.tech) but discussing them is out of the scope of this Article. In this Article we will be focusing on the integration using Message Broker and more precisely [RabbitMQ](https://www.rabbitmq.com/?ref=blog.ecotone.tech).
Integration using Message Broker may require a lot of knowledge about Messaging and Routing Patterns and can easily get complicated. Due to that **it often happens that integration between Services becomes non-trivial task**, which includes a lot of discussions, failed tries and changes, that often span over several days, or in worse scenarios weeks.
> The problem with Service to Service integration using Message Brokers is, they can quickly become burden to maintain. As they easily get complicated and potential bugs may impact multiple Applications and Teams, therefore people become afraid of changing them anyhow.
>
> **The solution to this lies in working from higher level abstraction.** Abstraction which is high enough, so we don’t need to deal with low level Routing Patterns directly in the Message Broker. The aim is to lower the entry barrier and make the integration easily understood and done. So the integration can be done within hours or even minutes. And this is the aim of the article, **to provide you with knowledge and tooling to do this in PHP using Ecotone with RabbitMQ.**
Yet to understand where Ecotone’s solution comes from, we need first to understand one fundamental difference — **the difference between logical and physical part of the System.**
### Logical and **Physical** part of the System
While we integrate Services together, we either put focus on **the** **Logical part** or **the Physical part** of the system**:**
- **The Logical part is the Business side of things.** In here we discuss things using Business concepts like: “When Payment Was Processed in *Payment Service* then *Shipping Service* will deliver the Order”**.**
- **The Physical part is about technical details.** In here we discuss things using Message Broker specific concepts like: “We need to create *Topic based Exchange* named ‘*software.public.payment.order’* and then publish Message with *routing key* ‘*payment.ordered’* so the ‘*order\_shipping’ Queue* can bind to this”*.*
**The lower level abstraction we work in, the more focus we will put in the Physical part instead of the Logical one.** This means we will invest more time into writing, maintaining and understanding code and configuration, than in understanding business side of the things.
This as a result can make us easily lose track of why we do given things, as our focus will go into details, not the higher level picture.
> Ecotone provides higher level abstractions so we don’t need to deal with low level Message Broker concepts. It aims to push the focus on the Logical side of the code, which takes us from “how” to the to the “why” side of things. This a result help us spot business misconceptions and deliver business features much quicker.
>
> Ecotone’s Distributed Bus
Each Service in Ecotone connects to Distribution Mechanism under given name: *“shipping\_service*”** or *“payment\_service”*.
This where the logical part comes in, as we actually **define naming for the business boundaries (Applications).**
We will be using this name to communicate between Services, using Ecotone’s **Distributed Bus**. Distributed Bus provides higher level abstraction, which allow us to focus on logical part of the system, instead of low level Message Broker concepts.
With Distributed Bus we will be working with two **different types of Messages: Commands and Events**. The difference between them is important, and we will see why soon.
> With Ecotone’s Distributed Bus, we won’t be in need to declare Exchanges, Queues and bindings. We will be working on business level and Ecotone will take care of those low level concepts for us.
>
> Let’s kick off now with sending Command Messages via Distributed Bus.
#### Enable Ecotone’s Distribution Mechanism
To start sending Messages (Command and Events) via Distributed Bus, we first need to enable it. We will enable it for RabbitMQ using Ecotone’s *ServiceContext* configuration:
> Above configuration for AMQP describes integration related to RabbitMQ, Ecotone Enterprise provides more configurable way, which works with different Message Brokers. Read more in Ecotone’s official documentation under “Distributed Bus with Service Mapping”.
This as a result **will register DistributedBus in our Dependency Container**, which we can start using right away.
To receive Messages from Distributed Bus, we want to enable Distributed Consumer:
This as a result will register new Message Consumer (Worker process), that we can run using *“ecotone:run”* Console Command. Name of the Message Consumer will be equal to our Service Name defined earlier:
**Symfony:**
> bin/console ecotone:run payment\_service
**Laravel:**
> php artisan ecotone:run payment\_service
> By enabling given Service as Message Publisher, Message Consumer or both, we state how given Service will interact with the rest of the System. This make it clear for everyone what is the role of given Service.
>
> Sending an Command
Suppose we are working in *“order\_service”* that process new Orders. After Order is received we want to take a Payment. To take payment we will be separate Service *“payment\_service”*.
When we want to trigger action on given Service, we will using Commands.
> Commands carry intention of triggering given business action in specific Service.
>
> If you’re unfamilar with concepts of Commands, you may get more details in [this article](https://medium.com/nerd-for-tech/going-into-php-cqrs-85cf8e21fa57?ref=blog.ecotone.tech).

Sending Take Payment Command from Order Service to Payment Service
Let’s stop for a moment and give a thought to the above diagram.
On the diagram we’ve two logical points which helps us answer following questions:
1. **Where do we want to send Command to? —** We send the Command to Payment Service
2. **What action do we want to trigger there?** — We want to trigger taking an Payment
This is crucial information, as it states how and with what boundaries do we interact.
> When using higher level diagrams we talk in Business terms like Boundaries (Context/Service) and Business Actions (Commands). Yet it’s important that we don’t need to carry diagrams with us to understand the code, the code itself should tell the story.
>
> Let’s actually make it it happen now using Ecotone’s Distributed Bus:
The code answers the same questions as above diagram, therefore we don’t need it to understand higher level perspective. **We can easily understand that we are sending an Command to Payment Service in order to Take the Payment.**
After Distributed Bus is triggered, Command Message will be sent to *“payment\_service”*.
> Diagrams like to get outdated, yet the code always represents how the System works at this very moment. So having code that clearly states how we interact with other Services is just pure gold.
>
> Receiving an Command
We can now receive the Command in *Payment Service*, let’s register Distributed Command Handler then:
We are using *CommandHandler* and *Distributed* attributes here, which does following things:
- By marking given method with *CommandHandler* attribute, we enable it to be triggered by local *CommandBus*
- By adding *Distributed* attribute we state that this Command Handler should be available for *DistributedBus* too.
From now on this Command Handler will be available for distributed communication using *“payment.take”* routing key.
This is all we need to do to communicate between Services using Ecotone.
> When we mark given Message Handler as Distributed, we connect it to Distribution Mechanism. Yet what is also important is that we make the code explicit, that given Handler can be executed by other Services. Therefore it becomes clear for everyone in the Team that this is an Distributed Command.
>
> How does Commands works another the hood
We won’t be writing integration with RabbitMQ directly, as we are working from higher level code. However it’s still worth to see how does the physical part work under the hood, so it’s clear for us what’s happening.
When we send an Command, we are actually sending Message with target Service Name as routing key:

Commands are routed by Service Name
> Command always targets single Command Handler, which on higher level means single Service. Therefore Ecotone always routes Commands based on the Service Name, which ensures only single Service will receive it.
>
> When Service Connects to Ecotone’s Distributed Mechanism as Consumer, it will automatically create an Queue which will be bound by the Service Name:

Payment Service receives Command Message based on Service Name routing key
This means that whenever Command will be sent to Payment Service, it will be delivered to this Service’s Queue.
Then when Message is consumed from Payment Service Queue, it will trigger our *Distributed Command Handler*.
### Publishing Event Messages
So far we’ve discussed Commands, yet there is second type of Message, which is Event Message. Events instead of being sent to specific Service are published, and whoever is interested may subscribe to it. Therefore **Event Message can be delivered to multiple Services**.
If you’re unfamilar with concepts of Events, you may get more details in [this article](https://medium.com/nerd-for-tech/event-handling-php-334dbf9916e4?ref=blog.ecotone.tech).
Suppose as a result of Successful payment, we want to deliver the Order to the Customer. Payments are handled by *“payment\_service”* and delivery is done by *“shipping\_service”*
Under the hood when we publish Event Message, we are sending an Message to the Ecotone’s Distributed Exchange with provided routing key:

Under the hood, we publish Event with given routing key
### Subscribing to Event Messages
Subscribing to Distributed Event is pretty straightforward. We provide *EventHandler* with routing key name and *Distributed* attribute.
Under the hood, Ecotone binds our Service’s Queue with given routing key:

Shipping Service Queue is bound by Event routing key
That would be all to communicate using Command and Events, using Ecotone is pretty straight forward and this is how it should be, if we want to focus on the logical part of the sytem. How to install Ecotone Distributed Module, you can read at [documentation page](https://docs.ecotone.tech/modelling/microservices-php/distributed-bus?ref=blog.ecotone.tech).
Now, we can take a look on few different scenarios which are often discussed when we start to do distributed communication.
### Keeping the Events Private
Often Systems do not make distributed Communication explicit. In those situations external Services simply bind to our Events, sometimes without any control from our side, if given Event is meant to be exposed or not.
As a result we can easily lose track what and how is being consumed by External Services and **this brings explicit Service Boundaries down**:
1. **Accidencial breaking other System** — If other Service can bind to our internal Events directly, this means it becomes Consumer of our Events. **If we change our Event structure, we may now accidentally break external Service.**
2. **Lack of modernisation** — Our Events became public Events, which means we are no longer in full ownership of those. As a result we now need to discuss and consult what we can actually change. Which often result in people not willing to make changes to the Events, as it’s basically takes too much time.
3. **Logical part is lost —** Discussing boundaries, Service to Service communication using Business language is often lost or hard to follow.
*We’ve dived into low level programming where business concepts do not take place.*
With Distributed Bus on other hand, things are made explicit and the Service boundaries are being respected. We explicitly state what we want to publish outside and what we want to keep private. This make it clear for everyone in the Team what lives on the edges of the boundary and what is kept within.
> **With Ecotone distinction between Public and Private Events is clear**. We will be explicitly stating what is leaving our Service boundary using DistributedBus.
>
> Distributing all the Events
There are many systems that publish all Events outside by default. This is not recommended as in inherit problems described above, yet it may be needed if our System is already working like that.
When migrating from legacy System to Ecotone we may want to preserve this behaviour to avoid bigger changes. In those situations, we most likely use some kind of Event Bus. In those situations we can replace our current Event Bus with Ecotone’s Event Bus, that publish Events internally:
And then simply **subscribe to “object” which means subscribe to all Events to distribute them:**
Instead of **object**, we could pass here an **Interface** that given set of Events are implementing:
or **union type** of Event Classes:
> Distributing all the Events is far from ideal as Events may fly over Message Broker without any meaning, as nobody really subscribe to them. Besides that any changes to Event structure may result in failure in other Service. Therefore it’s better to keep distinction on private and public Events.
>
> Private vs Public Events
In general it’s good to follow distinction between Distributed Events (Public) and ones meant to he handled on the single Service level (Private).
This way will know which Events are safe to change as they are used internally only and which need special attention before changing.
> With Ecotone Public Events are explicit, as those are the one that goes via Distributed Bus.
>
> During Event Distribution we can do one more step and provide custom structure for our Public Event. This way our internal Event structure will be fully decoupled from external Services:
### Decoupled Message Classes
In some Frameworks we are bound to use the same Class on the publishing and consuming side. This means in order to deserialize Event or Command, we need to have same Class with the same name and namespace in each participating Service.
This is far from ideal as it creates hard coupling between Services, which can be easily broken if class name is changed.
> Ecotone promotes decoupled communcation between Services. It delivers Messages based on routing keys, not Classes.
>
> In Ecotone, Message is delivered based on the routing, not the Class. The class to which we should deserialize is determined just before Message Handler execution, based method’s parameters.
> Therefore even if the Classes are named differently in each Service, we will be able to deserialize it. This go further, as we don’t even need to use Classes as we can deserialize to Arrays instead:
The same way Publishing side is decoupled, and we can use whatever type we want, for example, for example array:
If you want find out more about Decoupling your Services, you can read one of my [previous article](https://blog.ecotone.tech/loosely-coupled-microservices-in-php/) on the matter.
> Ecotone decouples Services from each other by delivering Messages based on routing keys instead of Classes. This way we avoid hard dependency as Services can deserialize given Events to the form that actually make sense in given Context.
>
> Subscribing to more Events at once
If given Service is meant to **subscribe to larger portion of Events**, we can use star (\*) for that:
This way we subscribe to all events having prefix *“billing.”.*
It will include: **“billing.order\_charged”,** **“billing.refund.made”**.
### Failure mode
In case of problems with processing given Message, Ecotone provides Error Handling. The Error Handling works exactly the same, as [Service level asynchronous processing](https://docs.ecotone.tech/modelling/asynchronous-handling?ref=blog.ecotone.tech).
In case of Exception, depending on the configuration it will either block processing or use delayed retries:

Retrying Failed Message with Delay
After delay retries are exceeded we can either drop the Message or store it in Dead Letter Database:

Command is pushed to Error Channel and stored in Database
If you want to read more about Retries and Dead Letter, you can check [documentation page](https://docs.ecotone.tech/modelling/recovering-tracing-and-monitoring/resiliency/error-channel-and-dead-letter?ref=blog.ecotone.tech).
#### Providing Custom Error Mechanism
If we want we can fully take over the process of Error Handling by defining our custom Error Channel:
and then we can hook in using Service Activator:
### Missing Command Handler
It may happen that Command routing key have actually been changed, or given Command Handler was simply dropped. We want to ensure that in those situation Message won’t be simply dropped or ignored, as this is potential bug which need to be fixed and Data preserved.

As Commands are routed by Service Name, Message will be delivered to target Service even if routing have been changed on target Service.
In those situations Ecotone will kick off failure mode, which store given Command in Dead Letter.
### Distributing Events Safely with Outbox Pattern
When we send Messages to RabbitMQ and storing changes in the database within single action we may end up in inconsistent state. This is because we are doing changes on two storages at the same time, where one of them mail fail:

Successfully storing Order in database, yet failing to send Message to RabbitMQ
In the code it would like this:
To solve this we can use Ecotone’s inbuilt feature to send Messages over Database:

Storing Event Message together with Order in Database and then publishing it separately
To do this we will first publish the Event internally using Ecotone’s Event Bus.
As each Command Handler is wrapped in Database Transaction by default, Order and Message will be committed together:
And then we subscribe to internal Event and distribute it away:
In order for this Event Handler to store the Message in Database, we need to define *“orders”* as Database Message Channel:
If you want to read more about Resilient Communication, you may one of the [previous articles](https://blog.ecotone.tech/building-reactive-message-driven-systems-in-php/).
> Subscribing to Private Events and then republishing them as Public is not only about safe Publishing, as it also creates space for decoupling. In this place we can remap private Event into Public Event with different structure.
>
> Sending Metadata
There may a cases where together with Command or Event we would like to send Metadata. Those may be details like Executor Id, Timestamp or event HTTP Domain from which the request for action came.
Those details mostly do not matter from Message Handling perspective, yet may be crucial for auditing, debugging or side effect which are triggered later in the flow. Putting them directly in Command or Event may blur their purpose and be cumbersome to be passed around.
Ecotone solves that by making Metadata first class citizen, which is passed together with the Command and Event:
Then we can access it directly in Distributed Event Handlers:
Metadata and propagation are crucial in Message-Driven Systems and Ecotone supports much more than it’s shown here. If you want to explore the topic in depth, I recommend you to read [Multi-Tenant in Laravel](https://medium.com/dev-genius/laravel-multi-tenant-systems-with-ecotone-e3e5a4751a55?ref=blog.ecotone.tech) or [Multi-Tenant in Symfony](https://medium.com/dev-genius/symfony-multi-tenant-applications-with-ecotone-8cc15d2715e2?ref=blog.ecotone.tech) where this topic was described in much more details.
### Separate Queues and Processing
So far we have been discussing handling Distributed Messages in context of single Message Queue. However in large scale systems we may actually want to process some of the Messages separately or with higher priority than the others.
Suppose we want to scale separately Message Consumers related to Taken Payments and Failed Payments. We could then separate those into different Message Channels (Queues):

Redirecting Message from Distributed Queue to separate Queue
In the code on the Service Level it will looks like this:
And then we define *“taken\_payments”* and *“failed\_payments”* Message Channels using Service Context configuration:
This would allows us to scale Message Consumers for taken payment independently from failed payments and treat Distributed Queue just as proxy.
> Message Channels can have multiple implementations, therefore we could use RabbitMQ for Message Distributed, yet use Amazon SQS or Redis internally. It’s up to us what works best in given context.
>
> Summary
The lower level code we work in, the higher trade off we will have to put on the logical part of the system. As focusing on the technical details moves as away from focusing on the business part.
Ecotone on other hand gives us tools to work from higher level abstraction, so we can deliver quicker, with less configuration and higher business focus. Business focused do not need to be forced, as if we spend much less time on the integration, we will naturally shift our focus on the business parts. This way we create environment where people produce high quality software that is aligned with business needs.
The example implementation of Distributed communication in [this repository](https://github.com/ecotoneframework/quickstart-examples/tree/main/MicroservicesAdvanced?ref=blog.ecotone.tech) and example of full Application written in Symfony and Laravel integrated via Distributed Bus can be found [here](https://github.com/ecotoneframework/php-ddd-cqrs-event-sourcing-symfony-laravel-ecotone?ref=blog.ecotone.tech).
### Symfony Multi-Tenant Applications with Ecotone
URL: https://blog.ecotone.tech/symfony-multi-tenant-applications-with-ecotone/
Last updated: 2024-03-02T11:19:19.000Z
How multi-tenancy is implemented depends on the business domain we work in. We may require shared database or a separate database for full isolation. We may have few Tenants or hundreds of them, we may need to throttle or speed up performance for given Tenant. All of this creates unique environment, in which Multi-Tenancy is not only a technical consideration, but also a Business one.
In my previous article I was describing how to build [Multi-Tenant systems in Laravel with Ecotone](https://medium.com/dev-genius/laravel-multi-tenant-systems-with-ecotone-e3e5a4751a55?ref=blog.ecotone.tech) with the least possible effort. And in this article we will do the same, yet for the Symfony Framework.
Scenarios in this Article will have Demos linked at the end of each section. This way we will not only discuss the example, but we will also be able to refer to executable demo.
> *This will be practical guide, after which you will know why and how you can apply Multi-Tenancy for different scenarios in your project. If you want to explore theory behind Multi-Tenancy, I highly encourage reading* [*Michał Kurzeja Article*](https://accesto.com/blog/queueing-in-multi-tenant-saas-systems/?ref=blog.ecotone.tech) *first.*
### Sending Messages with Database per Tenant
Suppose we are in E-Commerce Domain and we’ve two Tenants where each has it’s own separate Database (DB per Tenant strategy).
First thing which need to happen in E-Commerce system is of course registration of new Customer, and this what we will focus on now.
The process of registering new Customer will go as follows:

We will be sending Register Customer Command Message to our Command Handler
We will send an *Register Customer Command* using *Command Bus,* to the *Command Handler* which will **store new Customer in the database**. The tricky part is that, **we want to store the Customer in database related to given Tenant**.
Let’s kick off by installing [Ecotone for Symfony](https://docs.ecotone.tech/modules/symfony?ref=blog.ecotone.tech):
> ***composer require*** *ecotone/symfony-starter*
This will provide us with Ecotone’s Symfony integration and Database supporting tooling.
### Mapping Connection to Tenants
We will be using Doctrine ORM for our example. As each Tenant will have it’s own database connection, we will need to define Doctrine configuration for each Tenant first (**doctrine.yaml**).
When connections are defined, we can now setup how will they map to Tenant names. We do it using Ecotone’s configuration method marked with **ServiceContext** attribute.
This is basically it. Ecotone will now know how given Tenant name maps to given Connection. So whenever we will send any kind of Message (Command/Query/Event) it will know which connection should be used.
### Multi-Tenant Command Handler
We will be using Ecotone’s CQRS for our Multi-Tenant System. This will provide us with great amount of inbuilt features, that we can use out of the box in Multi-Tenant Systems.
Let’s define our **Register Customer Command Handler**:
As you can see Command Handler is nothing special. It’s just an **method which perform business logic** marked with PHP Attribute. Our Command Handler takes an Command Class and stores the Customer using Doctrine ORM. This code would work in single Tenant environment just fine.
The tricky part however is that we need to use **ObjectManager/EntityManager** for specific Tenant, as each has it’s own Database Connection.
By adding **#\[MultiTenantObjectManager\] Attribute** we are telling Ecotone to inject ObjectManager for currently activated Tenant. This way we can store our Customer in correct Tenant’s Database, and we keep our code agnostic to Multi-Tenancy.
> Ecotone make use of Attributes to provide Declarative Configuration, which keep our business code agnostic of Multi Tenant environment.
> This way we can develop like there would be a single Tenant, yet deliver System that will work with Multi-Tenancy by default.
>
> Let’s define *RegisterCustomer* Command Class:
Command Class is simple POPO (Plain Old PHP Object), it does not extend or implement any framework specific classes. Command contains all the data needed for Customer registration.
> Ecotone will manage flushing and clearing our Object/Entity Managers by default after Command Handler is executed. This way our code is simplified as all we need to do it to persist given Entity and we are good to go.
>
> Multi-Tenant Message Bus
After introducing Command Handler in our code base, we can now send Command to it for given Tenant.
We will be executing given Command in context of specific Tenant:
In here we are sending **Command over Command Bus and passing Tenant name** using metadata (Message Headers). This way Ecotone will understand that we performing given Command Handler in context of given Tenant’s database. Typically we would resolve Tenant name here, based on the HTTP Domain or User Session.
> *We’ve defined Command Handler for Multi-Tenancy, but we can do the same for Query Handlers (Responsible for fetching data) and Events. We will take a deeper look on Event Handlers in later part of the article.*
>
> This is basically all we need to store Customer in Multi-Tenant environment. Basically our code would work either for single or multiple Tenants, as it’s fully agnostic to Multi-Tenancy. Let’s now check more scenarios, which we may need in our Multi-Tenant Systems.
The demo implementation can be found under [this link](https://github.com/ecotoneframework/quickstart-examples/tree/main/MultiTenant/Symfony/MessageBus?ref=blog.ecotone.tech).
### Shared and Multi Database Tenants
We may have business model where by default we put every Tenant in the same Database, yet if Customer will buy premium he will receive separate Database instance.
To handle such cases, Ecotone provides the default connection. This way, if there is no mapping for given Tenant name, default will be used:
### Accessing Current Tenant in Message Handler
For specific scenarios we may need to be aware of Tenant’s context in which execution is done. For example given Tenant may have luxury Shop where delivery should happen right away after order is made, when for other Tenants time does not matter.
In case of Ecotone, whatever we send via Message Headers (Metadata) is accessible for us on the Message Handler level. This way depending on the need we can ignore or access given metadata. And as we send Tenant name via Message Headers, we can access it in case of need:
Header attribute states what Message Header we want to access. In our case we want to access tenant header, which we sent earlier via Command Bus.
> *We can access any Message Header in our Message Handlers. This means, whatever Metadata we will pass with Command/Query/Event (e.g. User Id, User Role, HTTP Domain from which request is made etc), we can then access it when needed.*
### Hooking into Tenant Switch
If we already have Multi-Tenant application running, most likely we are using some custom libraries or integration. In such cases, it may be required to trigger some code when given Tenant is activated or deactivated.
**Ecotone opens possibility to hook into the process of Tenant switch**, where it can provide Connection that is going to be activated and the Tenant name.
To hook in all we have to do it to mark given method with **OnTenantActivation** or **OnTenantDeactivation**, given methods will be triggered following actions will happen. This way by simply marking given method with Attribute, we can actually hook into the flow and perform needed logic.
The demo implementation can be found under this [link](https://github.com/ecotoneframework/quickstart-examples/tree/main/MultiTenant/General/HookIntoTenantSwitch?ref=blog.ecotone.tech).
> *Ecotone follows declarative configuration. This means that we mostly going to state what we want to achieve by marking methods with Attributes. This way we can focus on business part of the system, instead of configuration and setups.*
>
> Events and Tenant Propagation
When Customer is registered we may want to trigger side effects, like sending an Email with Welcome Message. For those situation we can define Events and Event Handlers.
When Customer is registered, we publish CustomerWasRegistered Event Message using Event Bus. Then all methods marked with Event Handler that subscribe to it (First parameter indicates Event we subscribe too) will be executed as a result.
As you can Ecotone, we could access Tenant Message Header in our Event Handler, this happens thanks to Ecotone’s metadata propagation capabilities.
The demo implementation can be found under [this link](https://github.com/ecotoneframework/quickstart-examples/tree/main/MultiTenant/Symfony/Events?ref=blog.ecotone.tech).
### Context and Metadata Propagation
Ecotone by default propagate all Message Headers automatically. This as a result preserve context Tenant. In our case sending Notification will happen in context of the same Tenant, as Customer Registration was done:

Metadata is automatically propagated from Command to published Event
This way we can of course access Tenant name in our Event Handlers too:
> *Whatever metadata we send at the beginning of the flow (e.g. Register Customer Command), we will be able to access in any synchronous or asynchronous sub-flows (e.g. Customer was Registered Event Handlers).*
> *This means we can easily pass things that are not directly related to Customer Registration Command and access them, in context which make sense. For example we could pass HTTP Domain, IP Address in Metadata, and access it in Event Handler that stores those for auditing.*
>
> Asynchronous Events
We can run our Event Handler synchronously which is default way, but we can execute Event Handlers Asynchronously. Ecotone provides [set of integrations](https://docs.ecotone.tech/modelling/asynchronous-handling?ref=blog.ecotone.tech#running-asynchronously) for Asynchronous handling, like **RabbitMQ, Redis, Database Channels** and we can also use **Symfony Messenger Transport.**
We want to use Database Channel, this means that we expect Messages for given Tenant, to be stored in given Tenant’s Database. For this we will use **Ecotone’s Database Message Channel, as it provides support for Multi-Tenancy**.

Sending Event Message over Message Channel (Database Queue)
Let’s **mark our Event Handler as Asynchronous**.
This Event Handler will be now understood to be handled asynchronously (in the background) and Event Message will be sent to *“notifications”* Message Channel. So let’s define this Channel now as Database Queue:
This is all we need to do to configure given Event Handler as asynchronous. Now whenever our Event Handler will be executed, Event Message will first go to Database Queue for given Tenant and then will be consumed asynchronously.
> *All we need to do, is to place Asynchronous Attribute on top of the Event Handler, and Ecotone will now that this Handler should be executed asynchronously. This will work exactly the same for Command Handlers.*
>
> Running Asynchronous Message Consumer
When we publish Message to Asynchronous Message Channel (in our case Database Queue), we need then to consume it.
To run Message Consumer we will be using inbuilt Console Command *“ecotone:run”*:
> *bin/console ecotone:run notifications*
This will run separate Message Consuming process which will be fetching and executing our Messages coming to “notifications” Channel.
As we are in Multi-Tenant environment and our *“notifications”* is Database Queue, this actually means that for each Tenant there may be a separate Database having it’s own Queue. And this need to be considered during consumption.
Depending on Business Domain we work in, we may have hundreds of Tenants, so running hundreds of Message Consumers may be far from ideal. For those situations, Ecotone by default use Round-Robin strategy to **consume using single process**. This means that we will be fetching from each Tenant in order:

Ecotone using Round Robin Strategy to consume Messages from multiple Tenants
Ecotone using Round Robin Strategy to consume Messages from multiple Tenants
This way of consuming works out of the box, we don’t need to do any customer configuration to make it happen. If we would like to speed up message consumption we could run multiple of those processes.
We could actually take over the whole process and throttle given Tenant, when he produces too many Messages, or speed up consumption for specific Premium Tenants. However this will be explored in separate article.
> Round-Robin consumption strategy is great as it allows having single process which can manage multiple Tenants. However Ecotone allows us for much more here, as it allows for defining our own consumption strategies to throttle or speed up consumption for given Tenants. This allows for full customization accordingly to our Business needs.
>
> The demo implementation can be found under [this link](https://github.com/ecotoneframework/quickstart-examples/tree/main/MultiTenant/Symfony/AsynchronousEvents?ref=blog.ecotone.tech).
### Database Transactions and Outbox Pattern
We may want to enable Database Transactions to make the system more resilient to failures. Of course in our case we want Transaction to start for given Tenant’s Database.

Database transaction will be started automatically when Command Bus is executed
Database transaction will be started automatically when Command Bus is executed
Ecotone will start Database transaction for correct Tenant database automatically, when we execute Command. This comes out of the box with [Dbal Module](https://docs.ecotone.tech/modules/dbal-support?ref=blog.ecotone.tech), which installed with Symfony Starter. Therefore no extra configuration is needed. You can read more about configuring Transactions in the [documentation](https://docs.ecotone.tech/modules/dbal-support?ref=blog.ecotone.tech#transactions).
When we publish Events Asynchronously to Database Queue this will be also covered with Transaction. This way in case of exception, we can be sure that everything will be rolled back together.

This works as [Outbox pattern](https://blog.ecotone.tech/implementing-outbox-pattern-in-php-symfony-laravel-ecotone/) that we get out of the box in Multi-Tenant system. Together with that Ecotone provides so called [combined Message Channels](https://docs.ecotone.tech/modelling/recovering-tracing-and-monitoring/resiliency/outbox-pattern?ref=blog.ecotone.tech#combined-message-channels-with-reference), where Messages could be moved automatically from the Database to the Message Broker (e.g. RabbitMQ, Redis, SQS). This way actual handling of the Messages would be done for Message Broker Consumers (and we would scale those), not Database ones.
### Dbal Business Methods
Dbal Module provides [Business Interface ](https://docs.ecotone.tech/modelling/command-handling/business-interface/working-with-database?ref=blog.ecotone.tech)— an easy way to write database queries hidden behind abstraction.
We define interface of what we want to achieve and Ecotone take care of how. This means that all we need to do is to write Interface and implementation will be delivered and registered it in our Dependency Container.
Business Interfaces when called from our Message Handlers (Command/Query/Event Handlers) will automatically inherit Tenat’s connection.
If you want to find out more about using Dbal based Business Interfaces, read this [article](https://blog.ecotone.tech/working-with-databases-using-ddd-mindset/).
### Sending Commands straight to the Model
Ecotone provides support for sending Command straight to our Doctrine ORM Entity. This way there is no need to write any delegation level code.
This of course works with Multi-Tenancy too:
As we can see on the example above we’ve created static factory method, this way we tell Ecotone, that this factory method “register” will create new Customer. After this method is executed, Ecotone will call use EntityManager for given Tenant to store it in the correct Database.
This means we don’t need to write such code anymore:
From the Controller side, nothing changes we still send it just as before:
What is important it also work for Action based Methods, which in some scenarios allows us to drop Command Classes completely:
And then we can execute Command Bus like below:
It’s enough to pass **aggregate.id** inmetadata to state which Customer instance we want to execute method at. If you want to explore more on the topic, you can read about using Doctrine ORM as Aggregates in this [article](https://blog.ecotone.tech/build-symfony-application-with-ease-using-ecotone/).
The demo implementation can be found under [this link](https://github.com/ecotoneframework/quickstart-examples/tree/main/MultiTenant/Symfony/Aggregate?ref=blog.ecotone.tech).
### Event Sourcing
When we need to build different Views or audit changes in our system, we may want to use Event Sourcing for that.
Ecotone comes with full Event Sourcing support, which allows us [roll out production ready Event Sourced Application](https://blog.ecotone.tech/implementing-event-sourcing-php-application-in-15-minutes/) in no time for Multi-Tenant systems.
The flow works the same as Doctrine ORM Aggregates, which we explored earlier. The difference is that Event Sourced Aggregates return Event classes instead of changing internal state.
#### Auto-Setup
Of course we need a place where Events will be stored for given Tenant, and for this we use Event Store in Tenant’s Database.
Ecotone will take care of serializing and deserializing Events, setting up Event Store in given Tenant database (inbuilt support for PostgreSQL, MySQL, MariaDB), and will also support us with setting up Read Model Projections.
#### Read Model Projections
Projections are used to build different views from Events. Each Projection can be a separate table or set of tables in database, which are dynamically created:
Whenever Event will be published, related Projection will be triggered. Ecotone based on Metadata will understand which Tenant it’s related to and initialize Projection first (if this did not happen before).
After initialization our Projection’s Event Handler will be triggered:
By default this will all happen synchronously, this make it super easy to start working with Event Sourcing. In case of need **we can switch our Projections to run Asynchronously** however**.**
You may [read documentation](https://docs.ecotone.tech/modelling/event-sourcing?ref=blog.ecotone.tech), if you want to explore more on the topic of Event Sourcing.
The demo implementation can be found under [this link](https://github.com/ecotoneframework/quickstart-examples/tree/main/MultiTenant/Symfony/EventSourcing?ref=blog.ecotone.tech).
### Summary
In this article we’ve enabled way to build Symfony Applications which are Multi-Tenant friendly, using code that is not coupled to Multi-Tenant configuration. This way of creating applications make it easy to build and maintain applications, as the code we write can work in single and multi-tenant environments without any changes.
Ecotone will take care of context propagation. This way it does not matter if the code is synchronous or asynchronous, as context of Tenant in which action is done will be preserved for us.
If we enter asynchronous processing and background tasks however, we may face a need for more advanced Queuing based solutions. This may happen because we would like to throttle given Tenant because it produces too many Messages, speed “premium” Tenant and handle failures and retrying in easy to work way. Ecotone provides that, however this topic deserves a separate article.
### Laravel Multi-Tenant Systems with Ecotone
URL: https://blog.ecotone.tech/laravel-multi-tenant-systems-with-ecotone/
Last updated: 2024-03-02T11:19:22.000Z
### Laravel Multi-Tenant Applications with Ecotone
How multi-tenancy is implemented depends on the business domain we work in. We may require shared database or a separate database for full isolation. We may have few Tenants or hundreds of them, we may need to throttle or speed up performance for given Tenant. All of this creates unique environment, in which Multi-Tenancy is not only a technical consideration, but also a Business one.
In this article we will focus on real life solutions, which we can apply in any PHP Application using **Ecotone** with **Laravel.** We will see how it’s flexible enough to be **adjusted to our Business needs** and how our **code stays clean of Multi-Tenant concerns**.
Solutions in this article **will also work with any other Framework**, as Ecotone can be used in almost any project. Yet we will focus on how to possible with the least possible effort in Laravel environment.
Scenarios in this Article will have Demos linked at the end of each section. This way we will not only discuss the example, but we will also be able to refer to executable demo.
> This will be practical guide, after which you will know why and how you can apply Multi-Tenancy for different scenarios in your project. If you want to explore theory behind Multi-Tenancy, I highly encourage reading [Michał Kurzeja Article](https://accesto.com/blog/queueing-in-multi-tenant-saas-systems/?ref=blog.ecotone.tech) first.
>
> Sending Messages with Database per Tenant
Suppose we are in E-Commerce Domain and we’ve two Tenants where each has it’s own separate Database (DB per Tenant strategy).
First thing which need to happen in E-Commerce system is of course registration of new Customer, and this what we will focus on now.
The process of registering new Customer will go as follows:

We will be sending Register Customer Command Message to our Command Handler
We will send an *Register Customer Command* using *Command Bus,* to the *Command Handler* which will **store new Customer in the database**. The tricky part is that, **we want to store the Customer in database related to given Tenant**.
Let’s kick off by installing [Ecotone for Laravel](https://docs.ecotone.tech/modules/laravel-ddd-cqrs-event-sourcing?ref=blog.ecotone.tech):
> **composer require** ecotone/laravel-starter
This will provide us with Ecotone’s Laravel integration and Database supporting tooling.
### Multi-Tenant Message Bus
Let’s define our Register Customer Command Handler:
As you can see Command Handler is nothing special. It’s just an **method which perform business logic** marked with PHP Attribute. Our Command Handler takes an Command Class and stores the Customer using Eloquent Model. This code does not really care about multi-tenancy, it would work in single Tenant environment just fine.
> Ecotone keep our code agnostic of Multi-Tenant configuration. This way we can write code like there would be single Tenant, yet it works in Multi-Tenant environment by default.
>
> Let’s define *RegisterCustomer* Command Class:
Command Class is simple POPO (Plain Old PHP Object), it does not extend or implement any framework specific classes. Command contains all the data needed for Customer registration.
#### Mapping Connection to Tenants
Now let’s define connections for two tenants — “**tenant\_a**” and “**tenant\_b**” in *“* ***config/database.php*** *”* just as we do it on the daily basics:
When connections are defined, we can state how they map to Tenant names. We do it using Ecotone’s configuration method marked with **ServiceContext** attribute.
This is basically it. Ecotone will now know how given Tenant name maps to given Connection. So whenever we send any kind of Message (Command/Query/Event) it will look at the mapping and enable given Database as default.
#### Executing Message Bus
We’ve defined how Tenants maps to Connections, so now we can execute our Command Handler using Command Bus:
We send **Command over Command Bus and passing Tenant name** using metadata (Message Headers). This way our Command Handler will be executed in context of given Tenant’s database.
The demo implementation can be found under [this link](https://github.com/ecotoneframework/quickstart-examples/tree/main/MultiTenant/Laravel/MessageBus?ref=blog.ecotone.tech).
> We’ve defined Command Handler for Multi-Tenancy, but we can do the same for Query Handlers (Responsible for fetching data) and Events. We will take a deeper look on Event Handlers in later part of the article.
>
> Shared and Multi Database Tenants
We may have business model where by default we put every Tenant in the same Database, yet if Customer will buy premium he will receive separate Database instance.
To handle such cases, Ecotone provides the default connection. This way, if there is no mapping for given Tenant name, default will be used:
### Accessing Current Tenant in Message Handler
For specific scenarios we may need to be aware of Tenant’s context in which execution is done. For example given Tenant may have luxury Shop where delivery should happen right away after order is made, where for other Tenant time does not matter.
In case of Ecotone, whatever we send via Message Headers (Metadata) is accessible for us on the Message Handler level. This way depending on the need we can ignore or access given metadata. And as we send Tenant name via Message Headers, we can access it in case of need:
Header attribute states what Message Header we want to access. In our case we want to access tenant header, which we sent earlier via Command Bus.
> We can access any Message Header in our Message Handlers. This means, whatever Metadata we will pass with Command/Query/Event (e.g. User Id, User Role, HTTP Domain from which request is made etc), we can then access it when needed.
>
> Hooking into Tenant Switch
If we already have Multi-Tenant application running, most likely we are using some custom libraries or integration. In such cases, it may be required to trigger some code when given Tenant is activated or deactivated.
**Ecotone opens possibility to hook into the process of Tenant switch**, where it can provide Connection that is going to be activated and the Tenant name.
To hook in all we have to do it to mark given method with **OnTenantActivation** or **OnTenantDeactivation**, given methods will be triggered following actions will happen. This way by simply marking given method with Attribute, we can actually hook into the flow and perform needed logic.
The demo implementation can be found under this [link](https://github.com/ecotoneframework/quickstart-examples/tree/main/MultiTenant/General/HookIntoTenantSwitch?ref=blog.ecotone.tech).
> Ecotone follows declarative configuration. This means that we mostly going to state what we want to achieve by marking methods with Attributes. This way we can focus on business part of the system, instead of configuration and setups.
>
> Events and Tenant Propagation
When Customer is registered we may want to trigger side effects, like sending an Email with Welcome Message. For those situation we can define Events and Event Handlers.
When Customer is registered, we publish CustomerWasRegistered Event Message using Event Bus. Then all methods marked with Event Handler that subscribe to it (First parameter indicates Event we subscribe too) will be executed as a result.
### Context and Metadata Propagation
Ecotone by default propagate all Message Headers automatically. This as a result preserve context Tenant. In our case sending Notification will happen in context of the same Tenant, as Customer Registration was done:

Metadata is automatically propagated from Command to published Event
This way we can of course access Tenant name in our Event Handlers too:
The demo implementation can be found under this [link](https://github.com/ecotoneframework/quickstart-examples/tree/main/MultiTenant/Laravel/Events?ref=blog.ecotone.tech).
> Whatever metadata we send at the beginning of the flow (e.g. Register Customer Command), we will be able to access in any synchronous or asynchronous sub-flows (e.g. Customer was Registered Event Handlers).
> This means we can easily pass things that are not directly related to Customer Registration Command and access them, in context which make sense. For example we could pass HTTP Domain, IP Address in Metadata, and access it in Event Handler that stores those for auditing.
>
> Asynchronous Events
We can run our Event Handler synchronously which is default way, but we can execute Event Handlers Asynchronously. Ecotone provides [set of integrations](https://docs.ecotone.tech/modelling/asynchronous-handling?ref=blog.ecotone.tech#running-asynchronously) for Asynchronous handling, like **RabbitMQ, Redis, Database Channels** and we can also use **Laravel Queues,** which we will now do**.**

Sending Event Message over Message Channel (Laravel Queue)
Let’s start by **marking our Event Handler as Asynchronous**.
This Event Handler will be now understood to be handled asynchronously (in the background) and Event Message will be sent to *“notifications”* Message Channel. So let’s define this Channel now as Laravel Database Queue:
This is all we need to do to configure given Event Handler as asynchronous. Now whenever our Event Handler will be executed, Event Message will first go to Laravel Database Queue and then we can consume it asynchronously.
> All we need to do, is to place Asynchronous Attribute on top of the Event Handler, and Ecotone will now that this Handler should be executed asynchronously. This will work exactly the same for Command Handlers.
>
> Running Asynchronous Message Consumer
When we publish Message to Asynchronous Message Channel (in our case Laravel Database Queue) we then need to consume it and execute the Message Handler.
To run Message Consumer we will be using inbuilt Console Command *“ecotone:run”*:
> php artisan ecotone:run notifications
This will run separate Message Consuming process which will be fetching and executing our Messages coming to “notifications” Channel.
As we are in Multi-Tenant environment and our *“notifications”* is Database Queue, this actually means that for each Tenant there may be a separate Database having it’s own Queue. And this need to be considered during consumption.
Depending on Business Domain we work in, we may have hundreds of Tenants, so running hundreds of Message Consumers may be far from ideal. For those situations, Ecotone by default use Round-Robin strategy to **consume using single process**. This means that we will be fetching from each Tenant in order:

Ecotone using Round Robin Strategy to consume Messages from multiple Tenants
This way of consuming works out of the box, we don’t need to do any customer configuration to make it happen. If we would like to speed up message consumption we could run multiple of those processes.
We could actually take over the whole process and throttle given Tenant, when he produces too many Messages, or speed up consumption for specific Premium Tenants. However this will be explored in separate article.
The demo implementation can be found under this [link](https://github.com/ecotoneframework/quickstart-examples/tree/main/MultiTenant/Laravel/AsynchronousEvents?ref=blog.ecotone.tech).
> Round-Robin consumption strategy is great, as it allows having single process which can manage multiple Tenants. However Ecotone allows us for much more here, as we can define our own consumption strategies, throttle or speed up consumption for given Tenants. This allows for full customization accordingly to our Business needs.
>
> Database transactions
We may want to enable Database Transactions to make the system more resilient to failures. Of course in our case we want Transaction to start for given Tenant’s Database.

Database transaction will be started automatically when Command Bus is executed
Ecotone will start Database transaction for correct Tenant database automatically, when we execute Command. This comes out of the box with [Dbal Module](https://docs.ecotone.tech/modules/dbal-support?ref=blog.ecotone.tech), which installed with Laravel Starter. Therefore no extra configuration is needed.
When we publish Events Asynchronously to Database Queue this will be also covered with Transaction. This way in case of exception, we can be sure that everything will be rolled back together.

You can read more about configuring Transactions in the [documentation](https://docs.ecotone.tech/modules/dbal-support?ref=blog.ecotone.tech#transactions).
### Dbal Business Methods
Dbal Module provides [Business Interface ](https://docs.ecotone.tech/modelling/command-handling/business-interface/working-with-database?ref=blog.ecotone.tech)— an easy way to write database queries hidden behind abstraction.
We define interface of what we want to achieve and Ecotone take care of how. This means that all we need to do is to write Interface and implementation will be delivered and registered it in our Dependency Container.
Business Interfaces when called from our Message Handlers (Command/Query/Event Handlers) will automatically inherit Tenat’s connection.
If you want to find out more about using Dbal based Business Interfaces, read this [article](https://blog.ecotone.tech/working-with-databases-using-ddd-mindset/).
### Sending Commands straight to the Model
Ecotone provides support for sending Command straight to our Eloquent Models. This way there is no need to write any delegation level code.
This of course works with Multi-Tenancy too:
As we can see on the example above we’ve created static factory method, this way we tell Ecotone, that this factory method “register” will create new Customer. After this method is executed, Ecotone will call “**\->save”** in order to store our Model in database.
This means we don’t need to write such code anymore:
From the Controller side, nothing changes we still send it just as before:
What is important it also work for Action based Methods, which in some scenarios allows us to drop Command Classes completely:
And then we can execute Command Bus like below:
It’s enough to pass **aggregate.id** inmetadata to state which Model we want to execute. If you want to explore more on the topic, you can read about using Models as Aggregates in this [article](https://blog.ecotone.tech/build-laravel-application-using-ddd-and-cqrs/).
The demo implementation can be found under this [link](https://github.com/ecotoneframework/quickstart-examples/tree/main/MultiTenant/Laravel/Aggregate?ref=blog.ecotone.tech).
### Event Sourcing
When we need to build different Views or audit changes in our system, we may want to use Event Sourcing for that.
Ecotone comes with full Event Sourcing support, which allows us [roll out production ready Event Sourced Application](https://blog.ecotone.tech/implementing-event-sourcing-php-application-in-15-minutes/) in no time for Multi-Tenant systems.
The flow works the same as Eloquent Model Aggregates, which we explored earlier. The difference is that Event Sourced Aggregates return Event classes instead of changing internal state.
#### Auto-Setup
Of course we need a place where Events will be stored for given Tenant, and for this we use Event Store in Tenant’s Database.
Ecotone will take care of serializing and deserializing Events, setting up Event Store in given Tenant database (inbuilt support for PostgreSQL, MySQL, MariaDB), and will also support us with setting up Read Model Projections.
#### Read Model Projections
Projections are used to build different views from Events. Each Projection can be a separate table or set of tables in database, which are dynamically created:
Whenever Event will be published, related Projection will be triggered. Ecotone based on Metadata will understand which Tenant it’s related to and initialize Projection first (if this did not happen before).
After initialization our Projection’s Event Handler will be triggered:
By default this will all happen synchronously, this make it super easy to start working with Event Sourcing. In case of need **we can switch our Projections to run Asynchronously** however**.**
You may [read documentation](https://docs.ecotone.tech/modelling/event-sourcing?ref=blog.ecotone.tech), if you want to explore more on the topic of Event Sourcing.
The demo implementation can be found under this [link](https://github.com/ecotoneframework/quickstart-examples/tree/main/MultiTenant/Laravel/EventSourcing?ref=blog.ecotone.tech).
### Summary
In this article we’ve enabled way to build Laravel Application which are Multi-Tenant friendly, using code that is not coupled to Multi-Tenant configuration. This way of creating applications make it easy to build and maintain applications, as the code we write can work in single and multi-tenant environments without any changes.
Ecotone will take care of context propagation. This way it does not matter if the code is synchronous or asynchronous, as context of Tenant in which action is done will be preserved for us.
If we enter asynchronous processing and background tasks however, we may face a need for more advanced Queuing based solutions. This may happen because we would like to throttle given Tenant because it produces too many Messages, speed “premium” Tenant and handle failures and retrying in easy to work way. Ecotone provides that, however as the topic is depth we will explore it in a separate article.
### Working with Databases using DDD Mindset
URL: https://blog.ecotone.tech/working-with-databases-using-ddd-mindset/
Last updated: 2024-03-02T11:19:23.000Z
While working with data we will find ourselves in need to map Classes to Database tables and vice versa. We map it, because we want to use higher level objects, not a simple scalar types like Database does.
Mapping (transformation), fetching and storing is not related to our business logic, that’s why we mostly hide it behind an Interface, likely DAO or Repository Pattern.
> We move implementation of our Database related Interfaces into infrastructure or persistence layer, to explicitly separate it from the business logic. By that, we want to show that this is not what our business is about. Yet, even so we have hidden it in non-domain related layer, we are still in need to write and maintain this code. This means we still need to invest time and focus into things that we are trying to get rid off.
>
> To have full focus on the business, we need to deal with low level code with as less effort as it’s possible. This comes from the mindset where we treat whole application as business oriented, not only the specific layer/module. And to make whole application oriented around the business, we’ve to use higher level abstractions that takes away need for implementing and maintaining low level code.
### PHP way with Business Interfaces
Ecotone provides Business Interface, which aims for reducing low level and boilerplate code to minimum, so the focus can naturally shift to the more important parts of the system.
In my [previous article](https://blog.ecotone.tech/message-based-business-oriented-interfaces/), I was describing how Business Interfaces can be used in Message based Systems. Consider Business Interfaces as tool to help us define intention using an Interfaces, and Ecotone will take care of how and provide the implementation.
For working with databases, Ecotone provides special type of those Business Interfaces which take away the need to write transformation logic, parameter binding and SQL execution. This way we are hiding low level code behind abstraction, focusing on high level business functionality.
### Modifying Database Data
To define Method that will insert/update/delete, we will be using *DbalWrite* Attribute:
We’ve have created an *PersonService* interface, which contains of *register* method. By marking it with *DbalWrite* attribute, we are telling Ecotone to execute given SQL whenever this method is invoked. The implementation of this Interface will be delivered by Ecotone and registered in your Dependency Container.
As we can see, we’ve bound two parameters *name* and *surname,* and we can find parameters with same name in method declaration.
Method’s parameters will be automatically bound to SQL ones.
> Interfaces that we define are part of our business level code, they don’t come from the framework. To tell Ecotone what to do we use meta programming - based on Attributes. This way we get full ownership of the code, and full flexibility in defining it the way it’s needed in given context.
#### Return number of modified Records
In case of Update or Deletes we may want to know how many records were modified. For this we may add Integer return type for declared method.
As you can see we’ve used *DateTimeImmutable* for our parameter. Ecotone will use inbuilt conversion, to convert Date Time into to string before SQL will be executed.
### Parameter Conversion
Our Domain Model may use higher level classes than scalar types understood by the Database. And in most situations we will want our Interfaces to follow Business types instead of Database ones. Therefore we can use Conversion mechanism.
#### Inbuilt Class Conversion
We already saw default Date Time Conversion in play, yet Ecotone can provide conversion for any Class as long as it provide “*\_\_toString”* method.
And now we can use it as part of our Interfaces without worrying about Conversion:
PersonId will be automatically converted to string, as it contains of *\_\_toString* method.
#### Customized Parameter Conversion
We can write our own Converter to customize how we can want to Convert given Classes. Suppose we have class *DayOfWeek* which on PHP level is represented as a *enum* *string*, yet in database we want to store is as an *integer*.
Then we can set up Converter class for it:
Converter is a class that is registered in our Dependency Container. Ecotone will find all converters thanks to the attribute marker, and call it, when the conversion is needed. In our case it will be called when conversion from DayOfWeek to integer is needed.
After defining Converter, we can now use higher level class it in our Interface, being assured that in the Database it will be stored as integer.
Converter will be reused between all your Interfaces, therefore we write it once and we cover all cases.
#### Using Expression Language
For cases where we would like to customize our Parameter for given scenario we may use [Expression Language](https://symfony.com/doc/current/components/expression%5Flanguage.html?ref=blog.ecotone.tech). This way we can customize behaviour for specific action.
Suppose we have Person Name class and we would like to convert it to lower case before saving.
Then for storing PersonName as lower case, we can call this method before saving using Expression Language:
By providing *DbalParameter A*ttribute we can define expression to be evaluated before given parameter is stored.
**payload** is special variable within the expression that refers to given paramter, in this scenario *PersonName*.
#### Non Argument, Database Parameters
We may have cases, where there is no need to pass parameter, as it can be evaluated dynamically. For this we can use *DbalParameter* as part of method’s attributes.
In this situation we’ve predefined “now” parameter using Dbal Parameter on the method level. We are using expression language to evaluate parameter value.
**reference** is a special variable within expression that points to your Dependency Container. This way we can fetch given Service and call method directly on it. In this situation we are fetching *Clock Service* and calling *now()* method.
For Method Level Dbal Parameters we can access all the arguments passed to the method by their names. In our case it would be “personId” or “name”.
#### JSON based Database Parameters
The database columns will not always contain of simple scalar types, it may actually contains of JSON. However in our Domain level code JSONs are mostly represented as more sophisticated classes or an array of Objects, therefore it requires conversion.
For our example, let’s suppose we want to store array of Person Roles in database. At the Domain level code, Person Role is represented as as PersonRole class.
And then our Interface level, we would define array of Roles:
By defining DbalParameter with *convertToMediaType* we are stating that we would like to convert given parameter to specific Media Type, in our case it will be JSON.
We can register our own [Media Type Converter](https://docs.ecotone.tech/messaging/conversion/conversion?ref=blog.ecotone.tech), but in case we are using out of the box [JMS Module](https://docs.ecotone.tech/modules/jms-converter?ref=blog.ecotone.tech), all we need to do, is to define an Converter.
This will be enough to make the conversion from Collection of PersonRoles directly to JSON.
### Querying Database Data
So far we’ve focused on storing data and parameter conversion, however we may use Ecotone’s abstraction for querying data too.
#### Querying multiple records
To fetch records we will be using *DbalQuery* attribute.
The result of the above will be array of array contains *person\_id* and *name*.
We can pass Pagination as an object and use for multiple parameters to make the Interface more readable:
And then we can use this Class as part of our interface:
To make use of expression language inside SQL, we define it as follows:
> ***:(expression)***
So in our case, if we want to access pagination.limit, it will be
> ***:(pagination.limit)***
### Converting Result Set
When working Domain level code, we will want to work with Classes instead of associative array returned by default by Dbal.
Lucky Ecotone is cable of to convert the result based on return type defined in Interface.
In the above method we state using fetchMode that we want to fetch single row from the result and then this single row will be converted to *PersonDTO* class.
To tell Ecotone how to do conversion we need to register Converter.
#### Returning nulls
When fetching single row, we may find no result at all. For this cases we can use union return type:
#### Returning single value
For aggregation functions like *SUM(), COUNT(), MIN(),* we may want to return them directly instead of specific row. For this Ecotone provides fetch mode to return first column of first row:
#### Converting multiple records
When fetching multiple rows, we may want to use classes instead of array too. However we need to define what should we return and PHP does not support generics. To solve this missing functionality, Ecotone provides ability to read Docblocks in order to understand what do we want to convert to.
### Fetching Large Result Sets
The default mode for fetch associative result, which means all the result will be loaded into memory. However we may use fetch mode to iterate over results, this way only single row will be loaded into memory at time:
### Doctrine ORM Support
In case we are using Ecotone’s [Aggregate support](https://docs.ecotone.tech/modelling/command-handling/state-stored-aggregate?ref=blog.ecotone.tech) with [Doctrine ORM](https://blog.ecotone.tech/build-symfony-application-with-ease-using-ecotone/), we may use special type of Business Interface — *Repository*.
Suppose Person is our Doctrine ORM Entity, then we can define the Repository Interface like this:
Ecotone will find related Doctrine ORM Entity Manager and persist the class. The same will work for fetching, based on return type Ecotone will find related Entity and fetch it.
### Eloquent Model Support
In case we are using Ecotone’s [Aggregate support](https://docs.ecotone.tech/modelling/command-handling/state-stored-aggregate?ref=blog.ecotone.tech) with [Eloquent Model](https://blog.ecotone.tech/build-laravel-application-using-ddd-and-cqrs/), we may use special type of Business Interface — *Repository*.
Suppose Person is our Eloquent Model, then we can define the Repository Interface like this:
Ecotone will use inbuilt methods like *save* to store the class. And for fetching it will use find method. This way we can hide persistence actions behind an interface.
### Summary
Full Domain focus is a practice of building applications that aim to solve business problems, not technical ones. The aim is oriented on making the whole application business oriented, not a specific layer or module.
> By writing only business related code, we create a space for everyone in the team to focus on what matters. Thanks to that, gradually everyone in the team will start to increase his business domain knowledge. The rule is simple, if there is no technical code to read and write, the only thing that we can focus on - **is business**.
>
> Ecotone’s main tenet is to provide us with higher level abstractions, so we can enable shift to the business parts of system. Database abstractions discussed in this article are just one of the building blocks that Ecotone provides. Therefore I highly encourage you to take deeper look in the [Ecotone’s documentation](https://docs.ecotone.tech/?ref=blog.ecotone.tech) to find out more and experience that in real life project. And if you want to read more about Dbal based Business Methods, you can go to [related section](https://docs.ecotone.tech/modelling/command-handling/business-interface/working-with-database?ref=blog.ecotone.tech).
### Message Based — Business Oriented Interfaces
URL: https://blog.ecotone.tech/message-based-business-oriented-interfaces/
Last updated: 2024-03-02T11:19:24.000Z
### Message based-Business Oriented Interfaces
[Laravel Fascades](https://laravel.com/docs/10.x/facades?ref=blog.ecotone.tech) provides great way to quickly access given functionality. This as a result make the development experience smooth, as we simplify stating what we want to achieve and we get it. However this comes with the down side, as Fascades are based on static methods and bounds us directly to specific implementation. This as a result make it cumbersome to switch the implementation and to actually test it.
On the other side we have development based on abstractions. Instead of binding and hard coding given solution, we use Interfaces in order to decouple from the implementation. This way we get the ability to provide stubs and mocks, making the code easy to test.
The down side of this approach however, is that development experience is not so smooth anymore. Now we need to start thinking about delegations, adapters and wiring things together.
So the trick is to keep smooth and fast development experience, yet to produce code that is maintainable and testable at the same time.
The guarantee of the above is Messaging, as it allows for ease of binding things, yet comes with decoupled nature, so it’s easy to add, replace and modify components. Therefore let’s check how we can make this happen with [Ecotone](https://github.com/ecotoneFramework/ecotone?ref=blog.ecotone.tech), using Business Interfaces which are based on Messaging.
### Activating Messaging
Suppose we have Caching Service. This Service does not follow any particular interface, it’s just stand alone Class we’ve introduced.
*Caching Service* does require *CachedItem*, which contains of key, value.
This Service can be placed anywhere in the code e.g. Service layer, Infrastructure Layer, some Tooling Namespace, whatever fits our application.
Now we want to activate this Service to be accessible via Messaging. And to do it we will use PHP Attribute - *ServiceActivator*.
We’ve added Attributes without changing single line of application level code. However that it’s enough to enable Ecotone’s Messaging and to open us for a lot of possibilities, including usage of Business Interface.
> With Ecotone, Messaging can be used within existing code base with ease. Ecotone will do all the bindings, and necessary configuration, so we can focus on the business aspects of the application. Thanks to that it does not really matter if we work in legacy or green field project, to start using Messaging it’s enough to mark given method with Attribute.
>
> Business Interface
Business Interface is no more than simple Interface defined in the code, marked with *BusinessMethod* Attribute. It works as a Gateway to execute given Messaging Endpoint (Service Activator).
We don’t need to implement this Interface anywhere in the code, Ecotone will deliver implementation for this, which will be automatically registered in Depedency Container. This means we can already inject and start using this Interface, even so we have not defined implementation.
When we will execute this method, under the hood Ecotone will construct and send this Message. This will execute activated Service, in our case Caching Service.
As a result we get simplicity of Fascade, as the only thing we need to create is an interface and given piece of functionality will be executed. And still we have the power of switching the implementation for testing purposes.
> Business Method is efficient way to expose any Messaging functionality in form of simple Interface.
> The best part is, if you’ve legacy code, you can expose it functionality without changing single line of code, by combing Service Activator with Business Method.
>
> Example implementation is available in [quick-start examples repository](https://github.com/ecotoneframework/quickstart-examples/tree/main/BusinessInterface/ServiceActivator?ref=blog.ecotone.tech).
### Command Business Methods
If we are using [Ecotone’s Command Handlers](https://docs.ecotone.tech/modelling/command-handling/external-command-handlers?ref=blog.ecotone.tech), we may expose them via Business Interface too. This allows us to avoid using Command Bus in the code base, and to bypass Middlewares related to the Bus.
As an example, let’s take *Create Ticket Command Handler*.
Normally we would use Command Bus to execute this, yet we can define our own Business Interface that will execute this Command Handler directly.
This works exactly the same as Service Activator, yet the difference is in visibility. Service Activator is private and can be executed only by Business Interface, where Command Handler can be executed by Business Interface and the Command Bus.
> By using Business Methods we can create Domain specific Interfaces and bind them directly to Message Handlers of our choice. Thanks to that, a lot of boilerplate code that we would normally write and maintain is no longer needed.
>
> Query Business Methods
Business Interface can also be used for Queries with additional support for conversions. Let’s follow up on Ticket example and introduce *TicketQueryHandler*:
And then we can define it on our Business Interface:
Business Method will return whatever Query Handler returns. So in our example it will be most likely an associative array.
However from the side of Business Interface, we may want to work with higher level code than array. For this we can change the return type in the Business Method, and Ecotone will do conversion before it’s returned:
To tell Ecotone how to do the conversion, we can use [inbuilt mechanism using Converters or use our own registered Converter](https://docs.ecotone.tech/messaging/conversion/conversion?ref=blog.ecotone.tech). To use inbuilt mechanism, all we would have to do is to create an conversion method:
> Business Interfaces can also be used for querying and together with Conversion support, we can create nice decoupled Interfaces. By using Ecotone’s conversion, we get ability to build Anti Corruption Layers between Modules with ease.
>
> Passing Message Headers
With Command/Query Bus we can pass additional Metadata and with Business Interface it’s the same. Metadata can be passed in form of Message Headers. This is a way to provide additional information along side with Command or Query class instance.
After defining given Message Header we can access it within Message Handler:
Message Headers are great way to pass additional metadata in order to avoid putting passing unrelated data to the Command or Query itself.
> Conversion also work on the Message Handler level, so if we would type hint executorId to be class like Uuid or ExecutorId, Ecotone will convert it from string to given type.
>
> Routing and Different Strategies
Let’s imagine we’ve introduced FileSystem Cache along side to InMemory one. At this moment InMemory Cache is executed directly from Business Method, so if we want to switch dynamically we need a router in between.
Ecotone provides an Router implementation, which is responsible for for routing given Message to specific Message Endpoint (Service Activator).
Router is an simple Service within our Application, just like Service Activators. There is no custom framework logic involved into the process, so the routing logic can be tested easily.
In our scenario, we want to decide where given item should be cached. By returning the routing key, we are stating where given message should be routed.
When we’ve Router defined, we can define Service Activators for different Cache Types:
Routing keys under which each Service Activator is registered are corresponding to the routing keys returned by the Router.
Now we can enrich our Business Interface to provide the *cache.type* Header:
> In general there are no limits on how we want to define our Routing logic. We could base it on the CachedItem, we could fetch the information from outside, do it based on item size etc. As Router is simple a Service within our Application, we have full control over the process.
>
> Example implementation is available in [quick-start examples repository](https://github.com/ecotoneframework/quickstart-examples/tree/main/BusinessInterface/Routing?ref=blog.ecotone.tech).
### Asynchronous Processing and Batching
There may be a cases where we would like handle batch of operations.
In those situations we may want to push processing to the background, to avoid waiting for each operation to complete in order to finish the script.
With Ecotone’s Messaging asynchronous processing becomes trivial, as all we need to do it, is to state that using Attribute.
We’ve defined this Service Activator to work asynchronously. Before this method will be executed, Message will go through Message Channel named “async”. So what is left is to define what kind of Message Channel it’s.
ServiceContext is attribute indiciating that given method returns Ecotone’s configuration. In this example we are using Database based Message Channel. [There are multiple implementations ](https://docs.ecotone.tech/modelling/asynchronous-handling?ref=blog.ecotone.tech)we can choose from.
We don’t need to change Business Interface and invocations, they stay exactly the same like in synchronous version. So all we did, was to add attribute to define that given Service Activator should work asynchronously.
> Performing given actions asynchronously is really powerful. Instead of doing everything all together in one go (which is time consuming and prune to errors), we handle given method asynchronously. This way each invocation is handled in full isolation and Message Consumption can be scaled.
>
> Example implementation is available in [quick-start examples repository](https://github.com/ecotoneframework/quickstart-examples/tree/main/BusinessInterface/Asynchronous?ref=blog.ecotone.tech).
### Aggregate Business Methods
Aggregate methods can also be exposed via Business Methods. This is possible when using [Ecotone’s Aggregate support](https://docs.ecotone.tech/modelling/command-handling/state-stored-aggregate?ref=blog.ecotone.tech).
To execute given business method on specific Aggregate instance, we need to state what Identifier should be used for fetching the Ticket Aggregate.
This way Ecotone will load Ticket Aggregate having defined *$ticketId,* then execute *close method* and save the Aggregate. Loading and saving will happen with registered [Repositories](https://docs.ecotone.tech/modelling/command-handling/repository?ref=blog.ecotone.tech).
> In this example we are executing Command Handler without any Command Class. This is possible thanks to Ecotone’s Message Routing. In cases where Commands are redundant we can simply not use them at all.
>
> Example implementation is available in [quick-start examples repository](https://github.com/ecotoneframework/quickstart-examples/tree/main/WorkingWithAggregateDirectly?ref=blog.ecotone.tech).
### Summary
Business Oriented Interface works as API for given set of methods.
It’s really easy to bind any functionality to Business Interface, no matter if you work in legacy code or a green field project.
On top of that we get huge amount of features including, Result Conversion, Asynchronous Processing and Invoking Aggregates.
This makes the Business Interfaces a powerful solution for quick and smooth development which keeps the code maintainable and testable at the same time.
### DDD and Messaging with Laravel and Ecotone
URL: https://blog.ecotone.tech/ddd-and-messaging-with-laravel-and-ecotone/
Last updated: 2024-03-02T11:19:28.000Z
Domain Driven Design is about focusing on the business logic first, everything around that are just steps to achieve it. Yet those steps are important, as they help to create environment in which full business focus is possible. **We can’t really give full attention to the business problems if our system:**
- Fails randomly when some integration is down.
- We get inconsistency in data because something was not sent or received correctly.
- We spend hours maintaining non-business related code like configurations, integrations, orchestrations.
**Our architecture has to become mature, for business focus to be possible.**
If we want to introduce DDD then our role is, not to force people around to use it, but to **create environment in which it can emerge naturally**.
> We need foundation that solves the very basics of our problems like: resiliency, scalability and maintainability, and solving those is a promise of Messaging architecture. When this is achieved, Domain Driven Design comes forward as natural practice.
>
> Messaging —The Return of OOP
I will start with quote that I always mention during workshops. The quote comes from Alan Key, Godfather of computer science, who coined the term **Object Oriented Programming:**
> “**Object** oriented programming gets people to focus on the lesser idea. The big idea is **Messaging**.”
> \~ **Alan Kay**
>
> Accordingly to Alan Key **Messaging was the root of what OOP was meant to be**, yet at some point we’ve deviated from that. We deviated into focus on *Objects* and *references*, instead of *Communication* and *Messages*. As a result we are now trying to achieve attributes of Messaging like resiliency, scalability and loosely coupling using development style that has moved away from it.
> Messaging is return to what OOP was meant to be, which along the way we forgot. It creates an environment where better patterns and methodologies like DDD can come forward naturally.
>
> Good reference on how to build Messaging system can be found in [Enterprise Integration Patterns](https://www.enterpriseintegrationpatterns.com/?ref=blog.ecotone.tech) (EIP). **Ecotone Framework implements EIP patterns in PHP** andmakes Messaging the main citizen in our Applications. It introduces it at the foundation level, which becomes a platform for **communication** **between any PHP Objects**.
### Messaging with Ecotone
Ecotone brings Messaging based on [Enterprise Integration Patterns](https://www.enterpriseintegrationpatterns.com/?ref=blog.ecotone.tech) (EIP) to PHP. EIP patterns introduce building blocks which allows to connect components seamlessly.
There are four main components on top everything is built:

**Message —** *I*t’s a data record, which contains of **Payload** and **Headers** (*Metadata*) and is uniquely identifiable. *Payload* is data needed in order to handle given Message (like list of products we would like to order) and *Headers* are additional framework or application level metadata (like Message Id, Executor of the Message, Timestamp).
**Message Handler/Endpoint —** Is a place where we handle given Message and perform business related logic. This is a place where for example logic for placing an order will take place.
**Message Channel —** Message Handlers are connected to Message Channels in order to receive Messages. Channels may be synchronous or asynchronous and this indicates how Message will be handled.
**Message Bus —** Is used as a “Gateway” to begin Messaging flow. It converts application level data into **Message** and sends it corresponding **Message Channel.** This is how flow begins**.**
If you want to explore more on the topic, you may refer to one of my previous [blog posts](https://blog.ecotone.tech/building-message-driven-framework-foundation/). However above information is enough for us to jump into practice of Messaging with [Laravel](https://laravel.com/?ref=blog.ecotone.tech) and [Ecotone](https://docs.ecotone.tech/?ref=blog.ecotone.tech).
### Placing an Order Scenario
Let’s explore scenario of User placing an Order for given set of products.
As a result of order being placed, we will send an Email and call external Shipping Service via HTTP to deliver the products.
This means there will be three actions:
- Storing an Order in database
- Sending an Email with confirmation
- Calling external Service via HTTP to deliver products
Let’s solve this without using any Messaging first. This way we will be able to see step by step, how we can refactor Non-Messaging to Messaging based code and what benefits it gives.
In the Controller we take the current user id and retrieve list of product ids from the Request, then we pass it to *OrderService* that does all the logic.
Let’s have a look on *OrderService* now:
This looks pretty straightforward. We store the order, send the email and call external Shipping Service. However this code does not support us in case of failures. Let’s dive into what may happen here, starting from sending an email:
Sending an email may fail due to network issues. If this happen, then the flow will stop and we will never deliver the order.
> We should consider anything that goes over network as unreliable, as at some point of time in future it will fail. By being aware of that, we can start designing more robust applications which can recover from those situations.
>
> So to solve that we could add handy Laravel function to apply retries:
This does not really solve the problem, it just makes it less likely to happen. If the Mail Server / Sendgrid / Mailgun will be down for longer period of time, we will not recover from this.
If email is not crucial we could use try-catch strategy to silent the error:
This of course is not bullet proof solution, it’s rather a solution of last resort, however for our scenario let’s consider it fine, as we have bigger fish to fry, delivering an order.
If delivering an order failed, we throw an exception, yet this means the order will never be delivered, which is crucial for the business.
To make it more resilient, we could start refactor the same way we did with email retries:
Again this does not really solve the problem, as in case of longer downtime of Shipping Service we will end up with Exception anyways. This time we can’t really ignore the failure, as Customer will not receive his goods.
This is a place where we most likely start to add some boolean flags in database to indicate if delivery was successful:
Now we need to write and maintain extra process, that look in database, if delivering order have failed, so we can trigger retries.
With this we are having more and more code related to recoverability now, the business logic starts to disappear in all the infrastructure related code.
Considering this is only single feature, it’s easy to imagine how much of this kind of code we will need for the whole system. **We can’t focus fully on the business problems, when we need to solve resiliency this way.**
From current perspective we won’t find good solution, as we either end up complicating the code more and more, or ignoring the fact that our system may fail. This is because we are solving side effects, not the root of the problem. And the **architecture that solves this problem is Messaging Architecture**.
> By introducing Messaging we solve resiliency problem at the root level. This means by following Messaging principles, our architecture gets self-healing capabilities, therefore we don’t need to write recoverability code on our own. As a result we have much less code to maintain, our code becomes more readable and we have more time which we can invest into solving business problems.
>
> **Messaging way — Event Flow**
We know that previous approach will make us pay huge price, therefore we want to solve resiliency problem differently. Let’s take a look on how we can modify our code to achieve resiliency using Messaging.
Let’s start by installing **Ecotone** for **Laravel**:
> **composer require ecotone/laravel**
Firstly, we will introduce Event Message. **Event is high level concept for Message which carry information that something in our system has happened**. This means Events are used to summarize result of given action. In our example it will be information that the Order was placed:
When we’ve an Event Message, we can now subscribe to it using Event Handlers. Typically we will be using Event Handlers to trigger side effects of given Event. In our scenario we have two sides effect of order being placed:
- Sending an confirmation Email
- Delivering order to the Customer
To subscribe to given Event we will be marking given method with Event Handler attribute. Let’s now register two Event Handlers in our *OrderService*
As you can see we basically moved the logic to separate methods and marked method with Attributes. That’s enough to activate given method as Event Handler. **The first parameter in Event Handlers tells *Ecotone* what Event Class given method is subscribing too**, in our case it’s *OrderWasPlaced*. If you want you can move this method together with Attribute to different class and it will still work.
> Ecotone follows declarative configuration with PHP Attributes. This means we won’t be extending or implementing framework related classes in our application level code. Instead we will using metadata in form of Attributes to state what we want to achieve.
>
> To trigger *Event Handlers*, we need to publish *OrderWasPlaced* event and we do it using *Event Bus*. Event Bus like any other Buses (Command/Query Bus) are available automatically after installing Ecotone package.
As you can see our code have not changed much. We just moved the logic to two separate methods, marked it with *EventHandler* and triggered Event Bus. We can run this code now.
The current code will work, but it does not make system resilient yet. It will execute Event Handlers synchronously. This means it will still have the same problems as the previous example.
To achieve resiliency we will make Event Handler Asynchronous. This way we will be able to use powerful Messaging concepts like Failure Isolation, Automatic Retries and Dead Letter.
By adding *Asynchronous* attribute we are stating that this Event Handler should work asynchronously. We gave information to Ecotone that whenever Event is meant to be delivered to this Event Handler, it should first go through given *Queue* with name “*asynchronous\_queue*”.
To register Message Queue and we can use [Laravel Queues](https://laravel.com/docs/10.x/queues?ref=blog.ecotone.tech).
*ServiceContext* is special Attribute in Ecotone, that stays this method returns configuration. In above method we are returning configuration for the Queue using Laravel Queues (More integrations are available). We are stating that we want to use *“database” connection* and Queue with name *“asynchronous\_queue”.*
To execute Message Consumer that will fetch Asynchronous Messages and execute Handlers, we will be using bellow command:
> php artisan ecotone:run asynchronous\_queue -vvv
If you want to explore more about asynchronous handling you can go to [documentation page](https://docs.ecotone.tech/modelling/asynchronous-handling?ref=blog.ecotone.tech).
> In Ecotone, queue implementation is decoupled from Event Handlers. Therefore we can change the implementation of the Queue without changing application level code.
>
> It’s important to understand what happens under the hood when we send Event Message. In most of the implementations of Event Bus, there is lack of failure isolation. When we send an Event Message, single Message goes to the Queue and triggers all related Event Handlers.

Typical Event Bus — Single Messages goes to the Queue and trigger all Event Handlers
This put on Developers the need to analyse each of the scenario if retry is safe to be done. As if we retry failed Message, we will end up re-triggering all Event Handlers. This produce unexpected side effects, where Event Handler that was previously successful will be triggered more than once. This is why Events are often considered unsafe to retry, which is true from perspective of this implementation.
This is not the case in Ecotone however, as Ecotone deliver separate copy of Message to each of Event Handlers.

Ecotone’s Event Bus — Each asynchronous Event Handler receives it’s own copy of the Event Message
This way we ensure the isolation of processing, if given Event Handler will fail, we will retry only the Handler that failed in full isolation.
Before we will discuss how those retries works, let’s have a final look on the *Order Service*:
As you can see each method has concrete responsibility. Placing an order stores the order and inform that the order was placed. The side effects like confirmation email and delivering the order are hooking into the flow by subscribing to the Event. The same way we can add more side effects without altering placing the order.
> We wrote code that follows Single Responsibility Principle, yet that was no the aim. The aim was to provide isolation for failures thanks to Messaging, and SRP is just side effect. After awhile of working with Messaging you will find out that a lot of good practices becomes part of your daily development practice without thinking about them, because Messaging is what OOP meant to be.
>
> Failure and retries
At the beginning of the article we were doing retries by handling them manually:
This was pushing us into handling failures in the application level code. With Messaging we’ve opened possibility to do this kind of things automatically without writing any additional code. For this we’ve two options:
#### Instant Retries
Instant retries works the same as our above code. So they wrap given Event Handler and in case given Exception happen, retries will instantly kick in:

Instant Retries
The only thing we need to do to configure them is to provide Ecotone with configuration for which Exceptions it should happen and how often:
#### Delayed Retries
Delayed retries are more powerful concept, as they give us possibility to retry given Message with delay. It helps to solve scenarios where external Services are down for longer period of time, as in that case Instant Retries won’t help us.

Delayed retries resend the Message to the Queue with delay
We may set up, how many times we should retry, what should be the time between retries and if each try should multiply the time:
The “*errorChannel*” is the place where Error Message will be pushed. We define the name in here because we may want to set up different configuration per Message Consumer.
To use above configuration as default one, configure “**defaultErrorChannel”** to “**errorChannel** *”* in your [Laravel’s configuration for Ecotone](https://docs.ecotone.tech/modules/laravel-ddd-cqrs-event-sourcing?ref=blog.ecotone.tech#defaulterrorchannel).
### Dead Letter
There will be cases that no retries will help us auto-recover, this may be because External Service is down for really long time, or we’ve introduced a bug in application or integration with external Service is incorrect. In those situations retries will not solve the problem, so we need different solution.
Ecotone provides Dead Letter to store Error Messages in database. To make use of it we need to install [dbal integration](https://docs.ecotone.tech/modules/dbal-support?ref=blog.ecotone.tech):
> composer require ecotone/dbal
After installing we get ability to store Error Messages in the database:

After delayed retries have been exceed, we store Error Message in Dead Letter
We store this Message for a reason, as we don’t want to write code to recover email or retrigger integration. Having this Message in the database, allows us to three step to recover:
1\. Investigate why it failed (Error details are stored with Message).
2\. Do the fix and release it on production.
3\. Replay the Message back to the Queue.

Replaying Message from Dead Letter
To view, delete/replay the Message from Dead Letter we may use inbuilt Command Line Interface:

Dead Letter Command line Interface
To configure dead letter, we need to modify last parameter of our retry configuration:
> Actually we may connect multiples Ecotone based Applications and review Error Messages from one place using [Ecotone Pulse](https://docs.ecotone.tech/modelling/resiliency/ecotone-pulse-service-dashboard?ref=blog.ecotone.tech).
>
> Safe Message Sending
We’ve isolated failures and enabled retries, whenever failure happens it will be automatically recovered and if unrecoverable error happens we will store it in Dead Letter. Yet there is one more part which we can make more resilient — Sending Messages.

Sending Message to the Queue which will deliver order has failed
We are having three actions here, we store Order in database and we send two Messages to the Message Queue. There may be a situation where, sending to the Queue will fail. In that case we could end up in inconsistent state, where order is stored, confirmation is sent, yet order is never delivered.
In our case we are sending Messages to the Database Queue using Laravel Queues, so we can wrap everything in transaction and commit it together.
With this we will ensure we always end up in consistent state, as everything is committed together. Yet we’ve introduced *DB:transaction* which is infrastructure level code in our placing order process, and this will happen for each situation when we will want to use transactions.
We can refactor this code and get rid of transactions from the application level code using Command Messages.
### Command Message
To avoid working with database transactions directly, we will introduce Commands. Command are automatically wrapped in transactions, when [ecotone/dbal](https://docs.ecotone.tech/modules/dbal-support?ref=blog.ecotone.tech) module is enabled.
**Command Messages describe a specific action to be taken** (like `RegisterUser`, `ChangePassword`, or `RegisterProduct`). They carry an intention of what we would like to happen.
> If you’re unsure, if Message is an Event or Command, you may ask a question: if this Message stating that something happened (Event) or asking for something to happen (Command)?
>
> To create an Order via Command Message, let’s first create an Command Message, this will wrap parameters we are passing to ***OrderService::place:*** *“userId”* and *“productIds”.*
Having Command defined, we can now define Command Handler for it.
We have only packed the parameters from the method into an *PlaceOrder* class and marked the method with *CommandHandler* attribute. That’s enough to activate this method as Command Handler.
Let’s now now send Command from the HTTP Controller. To send an Command Message we will be using concrete type of Message Bus — **Command Bus.**
Right now transactions will be automatically started for us whenever we place an Order. Any future Command will be wrapped with transactions too, this gives us default resiliency, so we don’t need to think about it anymore.
We’ve discussed Instant Retries in case of Asynchronous Messages, but we may enable it for synchronous actions too, like placing an Order:
This will secure us from from the situation when database connection is lost, dead lock occurred or any other exception happen which we would like to retry. So by adding above configuration, we secure that in case of database connection error **instead of losing an Order, we will do instant retry to recover.**
> Instant Retries and automatic Database Transactions are handled with Interceptors. Interceptors allows us to hook into the flow and do additional logic. This way we can handle cross-cutting concerns with ease. If you want to explore more [visit documentation page](https://docs.ecotone.tech/modelling/extending-messaging/interceptors?ref=blog.ecotone.tech).
>
> Your Jobs are your Commands
We use [Laravel Jobs](https://laravel.com/docs/10.x/queues?ref=blog.ecotone.tech#generating-job-classes) to process asynchronous time consuming tasks, yet in Messaging world **Jobs are still Messages with specific intention**.
The intention may be to *upload a file, resize image, send an email*. In case of Messaging we stop thinking about Asynchronous Messages as Jobs, as they are simply Command Messages with another use case for them.
### Resiliency Summary
From now on, we don’t need to write recoverability code as we have solved resiliency on foundation level. Resiliency became part of our architecture, which is now the default way of how we develop things. All future features will be able to self-heal by default now.
**The time we’ve regained for everyone in the team is huge:**
- **Developers can write, maintain and test business related code**, as recoverability is already solved
- **Developers can spend less time debugging and looking for issues**, as each feature can now easily be made resilient
- **Team on the meeting and in PRs can discuss, review and focus on higher level business code** instead of recoverability code
We made a ground work to **focus on the business part of the system now, so let’s discuss Domain Driven Design.**
### Domain Driven Design
We already did few steps into business oriented software. If we take a look on our code, we will see it does focus on what Business would like us to do:
This code is easy to follow and understand and even so we are using Message Queues for asynchronous processing, we don’t mix it with application level code.
What’s also important, we’ve started to use business terms in the code base by introducing Command - “*PlaceOrder*” and Event — ”*OrderWasPlaced*”.
Both Commands and Events are using business language and will be understandable by Business when we will speaking about those.
The next step is encapsulate logic with Aggregate and get rid of orchestration level code.
### **Messaging with Aggregates**
If we allow to create our Models directly we open possibility for creating incorrect Models. Nothing really block us to pass products, yet not calculate the total price:
This code will store Order in the database, yet the total price will be incorrect and OrderWasPlaced Event will never be published. As you can see, we’ve not protected our system from incorrect usage.
Using *PlaceOrder Command* we can be sure, that wherever in code we will be sending this Command, Order will be stored in database in correct state and Event will be published. That’s why it’s important to not bypass Messaging and **use it as our API, to protect correctness of our data and that expected behaviour is executed.**
The important building block in DDD is Aggregate. **Aggregate are Models rich in behaviour, so in our case that will be Eloquent Models that expose business related actions.** Aggregates hold business logic and protect correctness of the data. This means we can move the logic we’ve placed in “*OrderService::place”* directly into *Order Aggregate*.
As you can see we’ve exposed creation of Order Model via Command Handler directly in Aggregate. For that we are using **static method which returns new instance of Order**. It becomes explicit in the code that this Command Handler is responsible for creating new Orders.
Let’s consider possibility of new feature to cancel the Order. Standard implementation could looks like this:
The above code is written to do three steps:
1\. Fetch Aggregate
2\. Change state of the Order
3\. Save Aggregate
The first and third point are actually an orchestration level code, and we don’t need to write it. And this can be done automatically by Ecotone:
We exposed cancel method directly on Aggregate. If there would be any business rules to verify, we could do it on the Aggregate level to protect this action from incorrect usage.
To execute this action we will be using *Command Bus* with method *sendWithRouting*.
We are passing special metadata parameter, which provides *“aggregate.id”,* this way Ecotone knows which Aggregate instance it should fetch from database and execute.
### Domain Driven Design Summary
By introducing higher level concepts like Commands and Events we start to use Domain Language and create Business flows. Aggregates combined with Command Handlers help us to protect our business rules and make business logic explicit.
We can publish Events directly from Aggregates and hook side effects using Event Handlers. This way we can build business flows with ease.
> All Building Blocks (Commands, Events, Aggregates) are glued together seamlessly using Ecotone’s Messaging. This helps us fully focus on the business part of the System.
>
> Main Summary
This article had a lot of information, as the concepts explained in here are depth and can’t described in few sentences. During workshops it take me around 3–4 hours to explain theory and do exercices on this subject, therefore **give yourself time to understand materials in this article**. Some of them may require re-reading to “sink in” or doing actual coding in order to feel it in the first hand.
You could use Ecotone without the resiliency part, by bringing the features that you’re mostly interested in. For example some developers use Ecotone’s Event Sourcing Module without the Resilient Messaging part. Remember however, that it’s the environment that creates the results. If we want our systems to focus on the Business, not technical parts, we need to create environment where it can happen. And to do it, **we need resiliency as part of our architecture, not as part of the business feature we need to build.**
When integrating with Messaging for the first time, do not rewrite your whole system at once, **give yourself a time to experience it on small part of the code base**. What we did in this article is a re-write of one functionality, and this is how you can start in your own system. Having single feature on production will give everyone in the team time to experience it. And when you feel confident about the solution, you can decide on rewriting next features. This is the safest way to do the transition.
The more you will be using Messaging with DDD, the more you will see how well those pieces works together to help us build reliable, scalable and business oriented applications.
Thank you for reading :)
### Finally, Tracing in PHP — Say Hello to OpenTelemetry
URL: https://blog.ecotone.tech/tracing-using-opentelemetry/
Last updated: 2024-03-02T16:19:16.000Z
Profiling leads the way in PHP to verify performance of our applications. Yet when we want to track flows and communication within our system we need something more. We need a way to trace requests between Services, we need a way to trace Messages flows, and where the communication has failed or stopped.
And finally, we have official tooling in PHP to do. Let’s hello to [OpenTelemetry](https://opentelemetry.io/docs/what-is-opentelemetry/?ref=blog.ecotone.tech).
### OpenTelemetry
OpenTelemetry is connection of two big standards and tracing frameworks [OpenTracing](https://opentracing.io/?ref=blog.ecotone.tech) and [OpenCensus](https://opencensus.io/?ref=blog.ecotone.tech) projects. The leadership of those two projects have [came together](https://www.cncf.io/blog/2019/05/21/a-brief-history-of-opentelemetry-so-far/?ref=blog.ecotone.tech) to create OpenTelemetry, which combines the best parts of both.
> OpenTracing and OpenCensus will not longer be maintained, they are considered archived now. So, if you want to integrate tracing within your system, consider OpenTelemetry instead.
>
> OpenTelemetry allows us to trace the flows within the system, how much time do they take, what’s happening during the flow, and help us visualize those flows using 3rd part tooling.
> We can summary it as a high level overview of what the system does, which can be used for observing, tracing and monitoring of our system.
> Thanks to OpenTelemetry we are not bound to given Tracing provider. We may choose one of different tracing providers (e.g. DataDog, Zipkin, Jaeger) which integrates with OpenTelemetry specification. Therefore we can switch and choose whatever feel best in context of our system.
>
> In PHP we often had unofficial integrations with 3rd party or implementation of standards that were not stable, yet with OpenTelemetry it’s different. [The integration is official implementation of the standard in PHP](https://opentelemetry.io/docs/instrumentation/php/?ref=blog.ecotone.tech) and was verified by OpenTelemetry team.
> At the end September 2023, PHP implementation of OpenTelemetry was released under stable 1.0.0 version.
>
> Auto-Instrumentation
OpenTelemetry provides few amazing features, and of them is [Auto-Instrumentation](https://opentelemetry.io/docs/instrumentation/php/automatic/?ref=blog.ecotone.tech). Auto-Instrumentation provides hook mechanism, which will trace whatever we would like to verify, without changing single line of code. This way we can add tracing to basically all applications, no matter if they are legacy or new projects.
There are different packages using Auto-Instrumentation already available, which provides hook mechanism for things like database calls, http calls, symfony/laravel requests etc.
Auto-Instrumentation is installed via PHP extension. After extension is installed, [we may choose different auto-instrumentation package](https://packagist.org/?query=opentelemetry%20auto&ref=blog.ecotone.tech), install it, and voilà tracing enabled.
Of course we may add our own hooks using simple interface from **OpenTelemetry\\Instrumentation\\hook** *,* by simply providing a class and method, which we would like to trace:
If you want to build your own auto-instrumentation package, you will find [step by step instruction here](https://opentelemetry.io/blog/2023/php-auto-instrumentation/?ref=blog.ecotone.tech).
### Production Optimization
Doing tracing on the production is huge thing, as this the environment where we mostly face problems which locally do not exists. More amount of data, real life integrations, application issues that we need to debug, it all happens on the production.
The problem is that traces needs to be sent outside and this cost time. If we send to some external Service over network, we will pay in time for that and with lack of multi-threading in PHP, it means the whole PHP process will pay that price.
> OpenTelemetry introduces [Collector concept](https://opentelemetry.io/docs/concepts/components/?ref=blog.ecotone.tech#collector), which sits together with your Application as form of a side-car, so you can send traces to optimized Agent within your network.
>
> Collector works as a proxy, which collects the logs and sends it to the 3rd party of your choice, for example DataDog.
> This happens over GRPC with Protobuf for performance, and as we host the Agent (Collector) within our own network, it becomes really efficient solution for sending traces quickly within production environment.
### Tracing Message-Driven Architecture
System with complex business flows and Messaging Architecture, can benefit greatly from Tracing. As OpenTelemetry provides overview of what is happening within our system and together with 3rd party integration like Jaeger/DataDog we can visualize how our flows looks like.
And this is why I’ve integrated [Ecotone Framework](https://docs.ecotone.tech/modules/opentelemetry?ref=blog.ecotone.tech) with OpenTelemetry, to make use of this benefits.
We will now explore how this integration looks using real life examples and how can we benefit from it. Yet before we will do it, let’s quickly understand the main concepts behind OpenTelemetry.
### OpenTelemetry Concepts
There is one main concept in OpenTelemetry, which is called **Span**.
[**Span**](https://opentelemetry.io/docs/concepts/signals/traces/?ref=blog.ecotone.tech#spans) **—** Span is concept which represent given unit of work, which can be measured in time. That can be a database call, http call or simply your HTTP Request. Spans can references each other, for example HTTP Request Span may contain of database calls as a child span.
[**Span Context**](https://opentelemetry.io/docs/concepts/signals/traces/?ref=blog.ecotone.tech#span-context)**\-** Represents context of given span, like it’s own unique identifier — Span Id, parent id which references to parent Span etc.
**Trace** — Connects spans under same measuring unit. All Span Contexts hold reference to Trace using identifier.
That’s basically enough knowledge to jump into real life examples.
### Tracing Flows
Ecotone will trace your flows for Command/Query/Event Handlers and Buses. This is nice way to see, how our flows are connected and what are the side effects of triggering given action.
Each Message Handler will receive a separate span, this way we can isolate and research particular part of the flow separately.
Each Bus and Message Handler receives it’s own Span
Within each Span, Ecotone provide so called [OpenTelemetry Events](https://opentelemetry.io/docs/concepts/signals/traces/?ref=blog.ecotone.tech#span-events). Events are no more than basic logs, which provide details of what’s happening within given Span. For Command Bus it could be information about Middlewares it started like Database Transaction.
Within Command Bus Span, database transaction is started and logged as an OpenTelemetry event
### Tracing Asynchronous Flows
In case of asynchronous flows, there is a need to pass the [Span Context](https://opentelemetry.io/docs/concepts/signals/traces/?ref=blog.ecotone.tech#span-context) between processes. This way OpenTelemetry knows what was the parent Span that caused that.
Ecotone will propagate Tracing Context automatically, when asynchronous Messages are sent. This is done via Message Headers and is done on the Framework level, so Application level code does not need to be aware of this.
Asynchronous Event Handlers are correlated within Trace
### Adding Auto-Instrumentation Package
We were mentioning about Auto-Instrumentation Packages, so let’s see how it works in practice. Suppose we want to start tracing Database queries as we would like to know what kind of SQLs are happening and how much time they take.
When [Auto-Instrumentation is configured](https://docs.ecotone.tech/modules/opentelemetry?ref=blog.ecotone.tech#auto-configuration), installation of auto-packages becomes trivial, as all we need to do is to require composer package:
> composer require open-telemetry/opentelemetry-auto-pdo
Voilà, we now trace Database Queries. Whatever SQLs happen on the application level, inside framework or any libraries we use, we will track them now. Nothing will hide from us :)
Tracing all Database Queries happening within Application
As you can see in previous photo, our flow starts when we call Command Bus. This is not fully accurate, as it actually starts with HTTP Request. However using Auto-Instrumentation for Laravel or Symfony, we can fix that, and start traces earlier:
> composer require open-telemetry/opentelemetry-auto-laravel
Our top level Span become HTTP Request
Right now we get much more details on what is the overall time of the request, as the tracing starts, when the request handling starts.
### Tracing Issues
We may have situation where Customer will not receive an email or his payment will not be recorded due to bug in the system. To find out Traces that may help us debug the problem, we will use native Ecotone functionality which propagates metadata within the flow.
So in here we are sending an Command via Command Bus and provide *executorId* within *Metadata*. This will be automatically propagated to all the *Events* that happens as a result of this *Command*, and related asynchronous flows.
Ecotone propagates Metadata to *OpenTelemetry* in form of [Attributes](https://opentelemetry.io/docs/concepts/signals/traces/?ref=blog.ecotone.tech#attributes), therefore we can make use of it for searching related traces. We know that *executorId* will be *id of Customer* that faced the issue, so we may use it for lookup.
Looking up for traces related to given Customer using propagated metadata
We’ve identified failed trace using executorId and now we can take a look, what happened as Exception and failed Message is available within the Trace.
Exception and all metadata that we’ve provided is available within the trace
As we can see our *Asynchronous Event Handler* have failed, while sending Notification. We can clearly see, that previous part of the flow was successful, only the part where notification was sent has failed.
> Within the trace we’ve all the needed information like exception message, stacktrace, metadata, so it’s easy to understand what and how it failed.
>
> Tracing using Message Identifiers
In Ecotone all Messages contains of Message Id, Correlation Id and Parent Id within Metadata. Those are automatically assigned and propagated by the Framework, so from application level code we don’t need to deal with those Messaging Concepts.
This of course open possibilities, as we can make use of those Identifiers to lookup related traces:
Tracing using Correlation Id
Lookup using Message Id, Correlation Id are especially useful when we are interested in concrete flow, as it will give us more accurate results which are correlated with specific Message. This will help us find out what have happened during the flow and if any part of the flow has failed.
> Ecotone’s Event Sourcing Module stores all the metadata in the Event Stream. This becomes very handy if something should happened but did not. As we can use of *Correlation Id* or Message Id, to check what happened during the flow.
>
> Cross Service Communication
If we have more than one Service (Application), we would like to have possibility to lookup traces from single place instead of jumping between different instances of Zipkin or Jaeger. Lucky OpenTelemetry does understand concept of different Services, therefore we may push traces with information about Service it belongs to.
We may filter traces for specific Service separately
We can filter specific trace for specific Service, yet the real power is achieved when we can combine them.
Ecotone provides Distributed Bus for communication between Services., which handles Pub-Sub (Event Communication) or Direct (Command Communication). Whenever we are using Distributed Bus to send Message to different Service, Ecotone will take care of Span Context propagation. This way traces will be correlated together:
Communication between Services is correlated automatically.
As you can see traces have been combined together. We can clearly see how flow have started within Customer Service and then have moved to BackOffice Service, after calling Distributed Bus.
This way we get high level overview of everything what is happening with our system, no matter if this is Single Service or Microservice architecture.
> To play around with real life OpenTelemetry integration together with Ecotone and either Symfony or Laravel, visit [this repository.](https://github.com/ecotoneframework/php-ddd-cqrs-event-sourcing-symfony-laravel-ecotone?ref=blog.ecotone.tech)
>
> Summary
In PHP we often had unofficial integrations with 3rd parties, or implementation of standards that were not official or always in beta phase, yet with OpenTelemetry it’s different. [The integration is official implementation of the standard in PHP](https://opentelemetry.io/docs/instrumentation/php/?ref=blog.ecotone.tech) and verified by OpenTelemetry team. And starting from the end of September 2023 confirmed to be stable with 1.0.0 version release.
OpenTelemetry is a powerful toolkit that can help save hours of debugging and provide clear overview on how the system responds and behaves. It also becomes much easier to onboard new developers, as they may run Tracing locally. This helps in understanding the flows quicker, and makes people used to debugging problems the same way it happens on production.
So it’s worth to say thank you to [Brett McBride](https://github.com/brettmc?ref=blog.ecotone.tech), [Przemek Delewski](https://github.com/pdelewski/?ref=blog.ecotone.tech),
[Bob Strecansky](https://github.com/bobstrecansky/?ref=blog.ecotone.tech) and everyone else involved in making this happen.
The value OpenTelemetry brings to development is huge, and by joining it with proper Messaging Architecture, it becomes a gamer changer for PHP.
### Building your own Message-Driven Framework — Foundation
URL: https://blog.ecotone.tech/building-message-driven-framework-foundation/
Last updated: 2024-03-02T16:20:00.000Z
### Building Message-Driven Framework — Foundation
Most of the materials will say not to build your own Messaging Framework, yet somehow we’ve a lot of them, better or worse, internal or open sourced. Great amount of them starts as a tiny integration with RabbitMQ, Kafka or SQS, and after awhile starts to grow.
It starts to grow because it has to, if we want to have reliable architecture then Message Broker by it’s own is not enough. We need a framework within the language that will support Message based communication.
In this article we will dive into how to build such Framework, as I will be revealing the concepts that have been introduced behind [Ecotone Framework](https://docs.ecotone.tech/?ref=blog.ecotone.tech) coming from [Enterprise Integration Patterns book](https://www.enterpriseintegrationpatterns.com/?ref=blog.ecotone.tech).
### Communicating with Message Broker directly
We may decide to go with direct integration with Message Broker, as consuming and sending messages is not big deal, right?
It mostly works fine till the moment it lands on the production. Now different scale, long running processes and scenarios that we have not thought before, start to happen.
After some time on production we will reveal that there is more things, that we need to cover besides consuming and sending Messages, like:
1. **Handling infrastructure failures** — Message Consumer will be now running for hours or days, so we will need to introduce reconnecting strategies, when connection will be broken. Besides we may need to handle cases when connection to Broker goes into zombie mode and just hangs.
2. **Receiving duplicated Messages** — We will have to deal with double consumption of the Message, either when handling Message simply failed or was failed be acknowledged.
3. **Handling transient and unrecoverable errors** — We will need to handle application level issues with grace (networks issues, concurrency, simply bugs in the code) to recover from them to avoid manual fixing or interventions (Instant and delayed retries, DLQ).
There is of course more, like maintaining integration code, bugs that can be only solved by battle testing for longer period of time and great deal of knowledge which we will need to acquire.
So if we went path of direct integration with Message Broker then we will have to fix production errors and add missing features. This is mostly the point where we unconsciously start building our own Messaging Framework. However building Messaging Framework should start as conscious decision, not as a side effect of bug fixing and production errors, as only then we can invest time in proper abstraction.
### Proper Messaging Abstraction
So considering we made a conscious decision about building Messaging Framework, this means we can invest time into building and learning new things. What is most important is that good Messaging Framework begins in the language. While building Ecotone I have not touched integration with Message Broker for the first year, as I was fully focusing on the foundation.
The foundation lies in the Messaging patterns. Luckily patterns have been already described and battle tested via implementation in various languages and frameworks like Spring Integration in Java, Ecotone Framework in PHP and NServiceBus in C#.
Messaging patterns I will be mentioning here are part of [Enterprise Integration Patterns](https://www.enterpriseintegrationpatterns.com/?ref=blog.ecotone.tech) book.
### Enterprise Integration Patterns

Domain language of Messaging
EIP book provides as with Domain Model for Message based Systems, which introduces patterns for decoupled communication. The foundation patterns on which everything is built are [*Messages*](https://www.enterpriseintegrationpatterns.com/patterns/messaging/Message.html?ref=blog.ecotone.tech) and [*Message Channels*](https://www.enterpriseintegrationpatterns.com/patterns/messaging/MessageChannel.html?ref=blog.ecotone.tech).
> Message is **data record**, which contains of payload and headers. Payload can be anything, it can XML, JSON or PHP class, headers are key-value metadata.
>
> Often abstractions put equal sign between Message Payload and Message, which means it lack of possibility to pass Message Headers.
> This as a result makes it hard to pass anything extra. It complicates the messaging framework and application level code, as now we need to carry meta-data information like message id, timestamp, executor id within the message’s payload and possibly introduce framework level interfaces into application level code.
> Message Channel is abstraction for communicating between [Message Endpoints](https://www.enterpriseintegrationpatterns.com/patterns/messaging/MessageEndpoint.html?ref=blog.ecotone.tech) (Message Handlers) using Messages. In Message based architecture there is no direct reference between components as communication goes via Channels.
>

Shipping Service consumes Event Message from “asynchronous\_messages” Queue
Message Channels can be synchronous and asynchronous depending on the implementation, yet the underlying abstraction for them stay the same. We send Message to a channel and other party consumes it on the other end.
This is the core and foundation model for Message based communication. Wrong abstractions on this fundamental level, creates a lot of extra complexity, so it’s important to avoid this. So before we will go further into EIP abstraction, let’s discuss one most common abstraction that have deviated from it - Message Bus.
### Message Bus Abstraction
In EIP we will find Message Bus pattern, yet it’s not the same as common implementation of Message Bus, which is not based on Message Channel communication.
So the common Message Bus implementation works like below:

Instead of sending Messages via Channels, we are sending Messages via Message Bus
#### Connecting Message Endpoints
Message Bus is actually a trigger for the Message flow and in concept of EIP it’s called [Messaging Gateway](https://www.enterpriseintegrationpatterns.com/patterns/messaging/MessagingGateway.html?ref=blog.ecotone.tech). It takes the input, prepares the Message and sends it to the Message Channel. Yet in Message Bus abstraction we don’t have channels, so we trigger Message Endpoints right away.

Each component requires injecting and sending custom Message via Message Bus to push the flow
Each Message Endpoint is configured via Message Bus to route the Message properly. As the routing exists on the Message Bus level, it’s required to use the Message Bus to push the Message forward. This put burden on application level code as now we need to use Message Bus in each of the Message Endpoints in order to push the flow forward.
> In case of Message Flows combined from multiple Message Endpoints, we will need to retrigger Message Bus in each of them to push the flow forward.
>
> Asynchronous Handling
Message Bus has its roots in synchronous communication, where each Message Endpoint is executed directly. There is no core abstraction that asynchronous processing is part of.

Message Bus requires to execute Message Bus twice in asynchronous scenario
To make asynchronous possible, whenever Message is sent via Message Bus, it checks if given Message is defined as asynchronous, and if so pushes the Message to given transport (Message Broker).
When Message is consumed from the transport it executes Message Bus again with information “I am in asynchronous mode, let’s handle the Message”. The other known solution is introducing Asynchronous Message Bus, which always sends to asynchronous transport and when Message is consumed, executes Synchronous Message Bus.
> Message Bus treats asynchronous processing as something external, an feature that have to be built on top of the abstraction, not as part of it.
>
> Message Endpoint Isolation
After Message is consumed from given transport, it executes all the related Message Endpoints. This leaves no space for isolation. If one of the Handlers fails, then when Message is retried it will retry succesfully Endpoints too.

Message Endpoints are not isolated and are executed as part of same Message handling
> To achieve failure isolation with Message Bus, it’s often required to create multiple transports and introduce complexity in infrastructure layer.
>
> Message Channel Abstraction
Enterprise Integration Pattern’s abstraction is based on communication using Message Channels:

Message Endpoints are connected via Message Channels
#### Connecting Message Endpoints
This abstraction connects Message Endpoints using Message Channels without introducing mediator in between like it’s with Message Bus.
To target specific Message Endpoint, we are targeting Message Channel to which Endpoint is connected.

Message Endpoints are connected via Message Channels
To kick off the flow we are using Messaging Gateway, just like with Message Bus, yet it can be triggered once for given flow, as the Message will flow using connected Channels.
> We can actually pass the same Message through the flow, because the Message itself is not an routing, the channel is. This creates flexibility of connecting, intercepting and modifying the flows without affecting application level code much.
>
> Asynchronous Handling
This abstraction fits naturally with asynchronous communication.
Message Channels can be asynchronous and synchronous, therefore in order to make communication asynchronous, it’s matter of changing the implementation of the channel.

Message Consumer is created for given Message Endpoint, when asynchronous channel is used
This means that Messaging Gateway send the Message to asynchronous channel from which the Message is consumed and given Message Endpoint executed.
Yet this requires having Asynchronous Message Channel per Message Endpoint, which may not be ideal when the volume of Message Endpoints is large. However as adding and modifying flows in Message Channel abstraction is easy, this can be solved by using [routing slip](https://www.enterpriseintegrationpatterns.com/patterns/messaging/RoutingTable.html?ref=blog.ecotone.tech):

Use routing slip header to target specific Message Endpoint
With routing slip we can make use of single Asynchronous Message Channel which we will be sending Messages to, yet within the Message we provide routing slip header. It contains of the channel name to which it should be routed after being consumed from the Asynchronous Channel.
> With Message Channel abstraction we pass the Message directly to Message Endpoint after consuming it from Message Broker.
>
> Message Endpoint Isolation
With Message Channel abstraction we can achieve isolation on the architecture level.

Each of Message Endpoints is connected to it’s own Message Channel, therefore isolation is guaranteed
In case of asynchronous processing, as we send Message to each of the channels, the flows becomes naturally isolated. This means that in case of failure only given Message Endpoint that failed will be retried.
With routing slip solution where there is only one Asynchronous Message Channel in play, the solution works pretty much the same. We would be sending two copies of the Message, each with it’s own routing header that would target specific Message Endpoint:

This ensures full isolation, as each Message Endpoint receives it’s own copy of the Message
> The isolation of Message Endpoints becomes natural part of the development when using Message Channel abstraction. Therefore retries of failed Messages becomes safe, as it does not produce unexpected side effects.
>
> Summary
The cost of wrong abstraction is huge, it’s either becoming problem for the framework or for the end users. Some wrong abstractions are so common, that we may start to think it has to work this way, and accept the limitations and workarounds as a normal part of development. Yet good abstractions does not need workarounds, they create environment where things just work and “click” together.
There will be two more follow up articles, on which I will be touching subjects like:
1\. **Messaging architecture in practice** — In this article we will focus on how those patterns works in practice, using real life code examples.
2\. **Messaging architecture optimizations** — We will see where Messaging Framework can be optimized to make it work smooth and fast.
If you want to explore more about Messaging Architecture, check my previous article on [YOLO Message-Driven ](https://medium.com/dev-genius/yolo-message-driven-architecture-e97a26392709?ref=blog.ecotone.tech)architecture.
### YOLO Message-Driven Architecture
URL: https://blog.ecotone.tech/yolo-message-driven-architecture/
Last updated: 2024-03-02T11:19:44.000Z
At the root of Messaging is communication using Messages, where each of the Message is fully identifiable and handled in complete isolation. The promise of investing into this is, resiliency, self-healing capabilities and scalability.
Yet at some point Messaging has deviated from those basic rules into something I call YOLO Message-Driven Architecture.
### The rules of YOLO Messaging
The YOLO became a standard way of doing Messaging and is pretty straight forward to follow. To implement YOLO Messaging, we just need to counter the very basics of Messaging and follow below rules:
1. **We use Messages only to offload tasks** — Instead of communicating between components, modules and services using Messages, we downgrade it usability only to offload some task/job like sending an email. As a follow up we put an equal sign between Messaging and Job Queue. At the end if it’s all about offloading a task, then it has to be the same, right?
2. **Messages are not handled in isolation —** We publish an Message and execute multiple Subscribers within same Message consumption process. If one of them fails, flows stops, or if we do have retries, we retrigger successful handlers too. At the end who would care that same action get triggered twice or more, if it happens then YOLO, right?
3. **If it fails, then it fails, it’s an edge case anyway** — We skip supporting patterns like Dead Letter, Retries, Outbox pattern. This as a result make us lose messages or require to manually recover from errors and look through stack of logs to find the cause. If we are lucky and we lost message during the weekend, then we can ignore, as who would care to go through weekend’s log, right?
Of course the above is written as parody, yet this parody is unfortunately more often that not, real. That’s why in my articles, workshops or discussions I put a prefix “resilient” Message-Driven architecture, as I want to differentiate from what is commonly known as Messaging.
The YOLO pillars are standing the ground well and it’s hard demolish them. To do it we need to shake their foundations by returning to the very basics of programming, return to what Object Oriented Programming is about.
### Message Oriented Programming

In *“Object Oriented Programming”* term the first class citizen is *“Object”*, which clearly states what we should focus on: objects, their structures and data. The naming is clear, so we know what to do, we can finish the article :)
Yet before we do that, it’s worth to consider if *“OOP”* is actually the thing we think it is. Everyone who ever programmed can share a story of the code base, where the naming was misleading and the behaviour was doing something totally different than the name stated. And unfortunately OOP is no different, and it was described by Alan Kay nicely:
> “**Object** oriented programming, gets people to focus on the lesser idea.
> The big idea is **Messaging**.” — Alan Kay
*Alan Kay* is one of the godfathers of computer science, who coined the term *“Object Oriented Programming”*, yet what he meant by that was different from what we mostly consider OOP now. OOP was meant to promote communication via Messages, where objects are consumers and publishers of Messages. Alan Kay stated that using Object in the term was unfortunate, as it shifted the focus in wrong direction.
Knowing that OOP is about Messaging, we can rediscuss our YOLO rules, to throw new light on them.
### Resilient Message-Driven Architecture
Let’s redefine what Messaging architecture should provide to us, in context of Objects and Messages:
- Each Message is a data record, which is fully identifiable
- Object expose an API by consuming particular Messages, and may publish new Messages
- Object handle given Message in full isolation and has enough internal information to perform it’s action
When we have those three basic rules, we can reiterate the false assumptions of YOLO Messaging:
> “**We use Messages only to offload tasks”**
One of the advantages is possibility to offload tasks using Messaging, yet this is one of the features, not the only feature it enables. Considering this as the main aim is pushing Messaging on the edges of the architecture. When we want to consider *Messaging* as part of *OOP*, then it has to become central way of developing things, not something on the edges.
With Messaging we communicate using Messages between Modules, Services and even Classes, so it’s much more than putting an job in Beanstalkd.
> “**Messages are not handled in isolation”**
One of the keys to enable Resilient Messaging is to be able to let each Message be handled in full isolation. This means that for same Message when we have multiple Handlers, which happens in case of Event Handlers and Event Messages, there should be a way to enable isolation.
We do that in publish-subscribe way, by delivering a copy of the Message to each of the Handlers separately.
This way we guarantee safe retries and that no side effects will be done when retries happens.
> “**If it fails, then it fails, it’s an edge case anyway”**
Failing is an edge case till someone lose the money, then it becomes an business problem. If our architecture does not support resiliency we can’t put trust in it. It becomes hard to recognize when bug in our code base made the data disappear or when it was “Rabbit, being Rabbit”. Actually it’s never RabbitMQ fault that we lose the data, it’s our architecture that does not support resiliency.
There are a lot patterns that support resiliency like Delayed and Instant Retries, Dead Letter Storage, Outbox pattern. Together with message handling isolation, they create a real combo architecture that support resiliency out of the box.
### Summary
Some Message Brokers support patterns and solutions that were described along the way. Yet what is important, to push *Messaging* to the level of *OOP*, it has to become part of the development tools we use on the daily basics. For this we need to have inbuilt support in our programming languages for working with Messages.
Messaging Frameworks that provide such inbuilt support are C#’s [*NServiceBus*](https://particular.net/nservicebus?ref=blog.ecotone.tech) from Udi Dahan, Java’s [*Spring Integration*](https://spring.io/projects/spring-integration?ref=blog.ecotone.tech) which is foundation for Netflix’s Spring Cloud and [*Ecotone*](https://docs.ecotone.tech/?ref=blog.ecotone.tech) for PHP which I am founder of.
Having Messaging as part of our daily development, does not mean we will need to deal with Messaging concepts. We may actually work from higher level code, where we won’t be dealing with low level Messaging API. This way we can join clean business code with powerful Messaging concepts that guarantee resiliency and recoverability, which at the end will help us to get to the roots of what OOP was about.
### My Database is not a Message Broker!
URL: https://blog.ecotone.tech/my-database-is-not-a-message-broker/
Last updated: 2024-03-02T11:19:44.000Z
Whenever we send Messages to Message Broker and store changes in our database, one of those actions may fail. If this happen we will end up in inconsistent state of the system.
To solve this we may use [Outbox Pattern](https://blog.ecotone.tech/implementing-outbox-pattern-in-php-symfony-laravel-ecotone/) which stores the Messages in the database, which then can be re-published to the Message Broker.
Yet **not everyone want to use database as Message Broker**, this may be true because:
- Our database does not support transactions
- We want to avoid constantly polling our database
- We send really high amount of Messages and we want to avoid scaling database Message Consumers
Besides the above, the Outbox pattern may be considered unnecessary complexity, or simply developers may prefer to avoid using Database as Message Broker.
I am not going to dive into, if using Database as Message Broker is valid approach, as it depend on your own context. What I will do however is to show you the other ways to increase the consistency, using the patterns I’ve applied to Ecotone Framework.
### Sending Retries
This one is easiest to achieve. Whenever we fail to send Message to a Message Broker we will retry the call.
> It’s important to provide a delay between each attempt, this way we give Message Broker a chance to become available, so sending Message can be self-healed.
>
> Ecotone provides by default *2 retry* attempts, first after *10ms* and second after *400ms, this is configurable.*
### Ghost Buster
Let’s consider scenario with Customer registration:
Suppose that whole register method is under database transaction.
And after storing Customer and publishing “Customer Registered” Event Message (to a Message Broker) we fail on storing Address. This as a result will rollback database transaction, however we already sent the Event Message to a Broker.
> Messages that have been sent where related data has been rolled back are Ghost Messages. When Message will be consumed there will be nothing to reference too, which will make your Message Handlers fail.
>
> To solve this we should delay sending asynchronous Messages after Message Handler (*RegistrationService)* have finished processing.
> In case of Ecotone sending asynchronous Messages happens just before the transaction is committed or simply after Command Handler have finished execution. This way in case Message Handler fails for any reason, Messages won’t be sent to the Message Broker.
### Error Channel
Let’s consider fatal scenario, our Message Broker becomes unavailable completely. This means that retries won’t really help us to recover. To recover from this situation, we need to send the Message to other place, where we can store it and replay later.
With Ecotone we may set up so called *Error Channel,* where we define how we will handle given Error Message, for example we may use inbuilt Dead Letter with Database.
If we choose Database Dead Letter, then if Message will fail during sending, we will store it in database under our current transaction.
This means we will be able to safely commit the transaction and preserve Error Messages which we can later replay using [CLI](https://docs.ecotone.tech/modelling/resiliency/error-channel-and-dead-letter?ref=blog.ecotone.tech#dead-letter-console-commands) or [Ecotone Pulse Dashboard](https://docs.ecotone.tech/modelling/resiliency/ecotone-pulse-service-dashboard?ref=blog.ecotone.tech).
> Storing Messages that failed on sending in Database Dead Letter help us recover from failure and allows for safe commit of the data without losing any information. After Error Message is stored in the database, we can safely review and replay it.
>
> Yet to make it more reliable we need to consider one more thing…
### Message Serialization Failure
Suppose we send three Messages and fourth has broken serialization. We can’t really rollback now as we will end up with Ghost Messages, yet we can’t store Failed Message in Database Dead Letter, because we can’t serialize it. To solve this we need to make step back.
> To make sending reliable on architecture level, we will need to split serialization from sending and serialize all Messages before we will start sending them. This way we ensure that from application perspective all Messages are fine and what is left to be done is to send Messages to the Message Broker.
>
> In case of Ecotone whenever we send multiple Messages, they are first serialized and then collected for later sending, this way we ensure that Messages are serializable. If error happens, then no Messages will be sent.
If sending to Message Broker fails it has to be due to integration with a Message Broker, so most likely automatic retries will solve the problem. If not then Message is already serialized, so we can send it to Error Channel and store in Database Dead Letter.
### Critical Messages
If we are super unlucky, there is still single scenario where we may fail even so we applied above patterns. This may happen when all messages were sent to the Broker and database transaction commit will fail.
To solve this we would need to introduce Outbox pattern and commit Messages and the data together. Yet we tried to avoid using Database as a Broker, in those scenarios we would need to accept this risk. However it’s worth to consider different approach where we will join those two solutions together.
So in our system we may have critical flows and non-critical flows. Sending an email will non-critical, yet storing an payment will critical.
In case of Ecotone we can steer and apply Outbox pattern to critical flows and the other pattern we described above to non critical flows.
By doing so, we ensure that business critical components will be always consistent, yet we avoid the pitfalls of Outbox pattern in places where a bit more risk is just fine.
### Summary
There are multiple patterns which we can apply to increase the assurance of our Data and Messages being consistent. It’s important to build those pattern it into underlying architecture, so the resiliency becomes the default way of working.
Ecotone provides those patterns out of the box, you may read more about them in following chapter about “[sending resiliency](https://docs.ecotone.tech/modelling/resiliency/resilient-sending?ref=blog.ecotone.tech)”.
If you would like to introduce Ecotone with [Laravel](https://docs.ecotone.tech/modules/laravel-ddd-cqrs-event-sourcing?ref=blog.ecotone.tech) or [Symfony](https://docs.ecotone.tech/modules/symfony-ddd-cqrs-event-sourcing?ref=blog.ecotone.tech), then Ecotone provides packages for that. If you use your own framework or any other (Magneto, Zend, Laminas etc) then you may use [Ecotone Lite](https://docs.ecotone.tech/modules/ecotone-lite?ref=blog.ecotone.tech), which is standalone solution that can be used in any environment.
Whatever you choose to do, stay resilient and stay safe! :)
### Building Blocks: Exploring Aggregates, Sagas, Event Sourcing with Ecotone
URL: https://blog.ecotone.tech/building-blocks-exploring-aggregates-sagas-event-sourcing/
Last updated: 2024-03-02T16:30:23.000Z
In the world of software development, we often find ourselves juggling various technical concerns, infrastructure considerations, and complex integrations. However, what if there was a way to focus primarily on the business logic and let a framework handle the heavy lifting of interconnecting the different components?
In this article, we’ll dive into the concept of building blocks in Ecotone and how they enable developers to build resilient, domain-focused applications while abstracting away the complexities of integration and infrastructure.
### Building Blocks: Specialized Cells

At the heart of Ecotone lies the concept of building blocks, analogous to the specialized cells in our bodies. Each building block represents a specific functionality, such as Command or Event Handlers, Aggregates, Sagas and more. These blocks provide solid groundwork built on resilient messaging, allowing developers to focus on the business logic and flow of their applications.
Just as cells in our bodies perform specific functions, Ecotone’s building blocks do the same in their respective areas. For example, Command Handlers handle incoming commands, Event Handlers react to events, and Sagas orchestrate complex workflows. These specialized cells collaborate and communicate seamlessly, forming the organs of your application. Just as organs work together harmoniously, Ecotone’s building blocks join forces to create robust and interconnected, yet decoupled, applications.
> In our cellular analogy, cells send messages to other cells, yet they are not burdened with the responsibility of message transport. Similarly, in Ecotone, you, as a developer, make use of building blocks to provide business logic and let the framework handle the intricate details of message routing and delivery. Your building block and messages are POPOs `(*Plain Old PHP Objects*)`, they do not extend or implement framework specific classes.
> Those powerful concepts `discharge` you from the complexities of infrastructure, and enable you to work at the business level with a sense of ease and abstraction.
>
> E-Commerce Platform
Let’s dive into an e-commerce platform and start using Building Blocks to build the application.
We’ll start with the registration of a new Customer.
### Customer Aggregate
In our application we will start by setting up the *Customer Aggregate.*
> Aggregates are behaviour rich Entities, that encapsulate data and expose a public API to interact with it.
This could be achieved with a Service/Application layer, where we could expose a series of actions:
The above solution require us to write orchestration code.
A *CustomerService* class uses a repository to fetch and store Customer, and an additional delegation layer that is not business related code.
And even if this is possible in *Ecotone*, there is a better way to deal with this, that allows us to drop all of the boilerplate code.
With Ecotone, the Aggregates can directly be used as the Command Handler. Ecotone will use the *Repository* in order fetch and save the Aggregate just like in *CustomerService* above. As a result we get rid of the boilerplate in the Service/Application layer. Less code to write, less code to maintain.
> Ecotone provides Repository integration with [Doctrine ORM](https://blog.ecotone.tech/build-symfony-application-with-ease-using-ecotone/) and [Eloquent Models](https://blog.ecotone.tech/build-laravel-application-using-ddd-and-cqrs/) to enable them as Aggregates. Yet if we want to write our own Repositoriy implementation, this is albo possible, obviously.
Important in Message-Driven architecture is testing. Without proper testing support, connecting components and ensuring that everything works as expected become painful.
Therfore Ecotone provides full testing support where we can isolate the components we need to test.
With [Ecotone Lite](https://docs.ecotone.tech/testing-messaging-architecture/testing-aggregates-and-sagas-with-message-flows?ref=blog.ecotone.tech) we can bootstrap an Ecotone application with a given set of classes. It supports testing, enables us to send Commands and assert the state afterwards.
As the Command Handlers have been implemented within the Aggregate, the requirement is functional. No more need to create multiple layers and transformations. We focus directly on the domain and we can easily test it.
Regardless from where the code is called, even from a Controller, its usage will remain the same and with the simple test above, we have proven it will work as expected.
### Product — Event Sourced Aggregate
In order to create new products for our e-commerce shop, we need to fulfill a couple of requirements.
> \- Product has a price that can change;
> \- By default, thhhe Product is hidden and not available in the shop;
> \- Product must be approved first, before it is possible to sell it;
> \- We should keep history of all the product’s changes;
> \- We should be able to provide a list of all the products that were not verified yet, so the business can check them out;
> \- In future we may provide different filtering and text searches;
As we want to keep the history of all changes, event sourcing will do the job, as it keeps track of all the changes.
In case of Event Sourcing instead of changing internal state, we are returning list of events. Those events are stored in Event Store.
> Ecotone provides Event Store out of the box for PostgreSQL, MySQL or MariaDB.
> Yet if we want we can write our own Event Sourcing Repository.
Normally, we would have to rebuild the state inside the Aggregate from past events using *“EventSourcingHandler”* methods.
But in our scenario, we don’t even need to do that, as there are no business invariants (“*ifs”* in Command Handler that protect the aggregate) that need specific state to be rebuilt.
We can test it as we did above with Ecotone Lite:
> Product must be approved first, before it will be available in the shop.
To handle this requirement, let’s start with command *ApproveProduct command:*
By parsing *“productId”*, Ecotone is able to figure out which Aggregate should be fetched for the execution.
And then the Command Handler in the *Product Aggregate*:
We may run the test with the *In Memory Event Store*, this will also ensure that events can be serialized correctly.
We’re providing initial state using *“withEventsFor”* method, so we can trigger the command and verify the resulting event afterwards.
As we run this test using In Memory Event Store, we also need to provide [Converters](https://docs.ecotone.tech/messaging/conversion/conversion?ref=blog.ecotone.tech) for objects, if we need to provide custom serialization and deserialization mechanisms e.g. *“UuidConverter”*.
All events will be serialized to In Memory Event Store. This way, the execution mimics as much as possible what would happen in production.
---
If we will take a look at the *“ApproveProduct”* command, we will see that it only contains the *“productId”.* Not exactly what one would a call a *rich domain model*.
This also means that we have created *“ApproveProduct”* command just to match the Framework’s needs, which is not ideal.
Once more, *Ecotone* takes care of this and avoids this pitfall. Let’s redesign our *Approve Command Handler*:
We’ve defined a routing key for the Command Handler named *“product.approve”*. We can trigger this Command using this key now.
By passing metadata *“aggregate.id”* to the *CommandBus* we are telling Ecotone, which Product instance it should fetch and we can get rid of Commands that are carrying identifiers only.
> Routing for Message Handlers can be used to trigger Command Handler without Command class, yet it can also be used to execute command in given format e.g. json/xml directly from Controller. We can pass incoming Request’s data, tell Ecotone what Media Type it contains and Ecotone will deliver the Message, convert it accordingly and execute your Message Handler.
>
> Unapproved Product List — Projection
> We should provide list of not approved products so the business can see which products it should still verify.
> In future we may provide different filtering and text searches.
Now we are able to create and approve products, we can list the products that have not been approved yet:
We provide a Projection that is derived from Product’s Event Stream.
Each method marked with *“EventHandler”* defines what event it would like to subscribe to.
We are using *DocumentStore* to store the projection’s Read Model, as it provides In Memory implementation for tests. This is Ecotone’s abstraction to store array/objects in key-value storage. We could use however whatever persistance mechanism we’d like.
> The Document Store provides implementation for In Memory used directly in tests and for real databases likes PostgreSQL, MySQL or MariaDB.
> As you can see, the Document Store is the Event Handlers’s constructor’s second argument
> By marking parameter with *“#\[Reference\]”* we are telling Ecotone that this is a Service and should be injected from Dependency Container.
Then we can test the projection using Ecotone Lite:
> With Event Sourcing we can build as many Read Models (Views), as we need. In case of Ecotone we can combine Event Streams from different aggregates, if we need more aggregated view.
> With this we build for the future: When new requirements emerge, we will be able to build new views without changing our domain model.
>
> Scaling with Cells and Building Blocks:

As cells combine to form organs, the same principle applies to building blocks in Ecotone. These blocks join together to build the various components and functionalities of your application. And just as our bodies can scale and grow, Ecotone enables the scaling of your applications by facilitating communication between different building blocks and even across multiple applications. The framework handles the intricacies of message transport, so you can focus solely on the logic and flow of your business processes.
> `It’s crucial in messaging based systems to have full testing support, otherwise system based on messaging easily get messy and will give the impression of being hard to understand and maintain.`
>
> That’s why Ecotone provide full testing support.
We already discussed a little of Ecotone’s testing support, however there is much more to it. With Ecotone we get full testing support. We can isolate groups of classes to use in the test, run Message Consumers (workers) synchronously or asynchronously, trigger Consumers with in Memory channels or real Message Broker channels etc.
Due to Ecotone’s messaging nature based on [Enterprise Integration Patterns](https://www.enterpriseintegrationpatterns.com/?ref=blog.ecotone.tech), it becomes really easy to test any scenario you could think of.
Let’s reconsider our example with the Unapproved Product List Projection.
In the above test scenario we’ve included the *Projection* and the *Aggregate* in the test. Then, the triggered Command will results in an Event, and finally the projection can be materialized.
By default, in test mode, all projections are running synchronous, yet we can switch to asynchronous, if we want to.
Combining classes under test is a powerful concept: It allows us to only include the classes that are relevant to a given scenario and test full flows in isolation.
> With Ecotone testing support, it becomes really easy to write unit, integration and acceptance tests. This will ensure that all your business flows are working as expected.
>
> Placing an Order
We want to include one more functionality to our application - placing an order.
There is one caveat in the order process: Customer could see that products are available in stock, however when the order is placed, the stock could already have changed. If products are in stock when the order is placed, then everything is fine. If, however, products are out of stock, we want to retry reserving them one hour later. If the second attempt still fails, we should cancel the order.
We will be calling external service over HTTP to reserve the products in stock. This our interface for doing so:
We will just mention the *Order Aggregate*, implementation will be as straight forward as the *Customer Aggregate*.
We can publish events from *State-Stored Aggregates.* The difference between this and *Event Sourcing Aggregate* is that for latter, events are kept in the Event Stream.
“OrderWasPlaced” will now begin our *OrderSaga*.
**“whenFirstAttempt”** method will be called after Saga is started and is triggered asynchronously. This way we ensure, that even if it were to fail, it would not affect the Saga's storage. On failure, we can use messaging to retry
**“whenSecondAttempt”** method will be called after Saga is started and is triggered asynchronously. This way we ensure, that even if it were to fail, it would not affect the Saga's storage. On failure, we can use messaging to retry.
\*\*“whenSecondAttempt”\*\* method will be called one hour after the Saga was started. We can then verify our business requirements and check if we can reserve the products this time.
This way, we have actually easily connected two different flows.
So whenever Order is placed, this Saga will be started.
As a result of starting Saga, we will run one Event Handler right away, asynchronously, and the second one, an hour later.
Delaying Message Handlers is a powerful concept. Thanks to the “*Delayed”* attribute we can make business delays explicit in the code.
> Making Event/Command Handlers Asynchronous is matter of adding an \`Asynchronous\` attribute. Each Asynchronous Message Handler receives a copy of the Message. And each Handler works in full isolation (which enables safe retries) and allows us to define custom ways of handling.
> For example, one Event Handler can be synchronous, the other asynchronous or we may delay some Handlers or add different levels of priority.
>
> Of course Ecotone provides an easy way to test asynchronous Handlers, so we can verify, if our Saga runs as expected.
Using *“releaseAwaitingMessagesAndRunConsumer”* we make it easy to test out really complex scenarios, where time is involved. This way we can trigger events awaiting given delay and verify the state.
> There are no constraints in writing tests in Ecotone. It is possible to test and connect basically every possible scenarios. No matter if the code is asynchronous, make use of delays or multiple Message Handlers. The level of difficulty does not matter, because Messaging is Ecotone’s second nature.
> And having such support is crucial for building maintainable software that we can put trust.
>
> Production run
We’ve been building models and testing them. Development is straightforward, because all we do is building business related code.
There is no “glue” code, no framework related code etc.
What we’ve been creating so far, is already production ready and can be deployed to production.
We did not need to define any custom repositories because Ecotone provides built in ones for: *Event Streams*, *Sagas* or *State-Stored Aggregates*. Nevertheless, if we need to, we can switch to our own custom ones.
The code from this article can be found in [Github Repository.](https://github.com/ecotoneframework/quickstart-examples/tree/main/BuildingBlocks?ref=blog.ecotone.tech)
You will find all the tests under *“tests”* catalog and you may run the code in production environment using *“run\_example.php”*.
### Building Blocks Conclusion:
Ecotone’s building blocks provide a powerful and intuitive way to develop resilient, decoupled and domain-focused applications. Just like interconnected cells in nature, these building blocks seamlessly communicate with each other, allowing developers to focus on the business logic while leaving the infrastructure complexities to the framework.
By abstracting away the transport of messages and providing purpose-built cells, Ecotone enables developers to unlock a joyful and efficient development experience.
So, embrace the interconnectivity of Ecotone’s building blocks, and embark on a journey of resilient and enjoyable application development.
### Revolutionary BOA Framework: Ecotone
URL: https://blog.ecotone.tech/revolutionary-boa-framework-ecotone/
Last updated: 2024-03-02T16:31:05.000Z
In the ever-evolving world of software development, there’s always something new on the horizon, something that shifts our perceptions and catalyzes transformation in how we approach building applications.
I’m excited to introduce you to a revolutionary business oriented framework, that will change the way you perceive PHP application development: [Ecotone](https://docs.ecotone.tech/?ref=blog.ecotone.tech).
Ecotone is a fresh breath of air in the PHP landscape, founded on principles of Business-Oriented Architecture (BOA). This framework is positioned to redefine the way developers engineer applications, paving the way towards faster and more robust development and a more enjoyable coding experience. Best of all? It’s production ready.

### Ecotone and Business-Oriented Architecture (BOA)
Ecotone embraces the concept of Business-Oriented Architecture.
BOA’s fundamental principle is about making business logic the primary citizen in your application. It shifts the focus from technical details to the actual business processes.
BOA is achieved by using three core pillars: Resilient Messaging, Declarative Configuration and Building Blocks.
**Resilient Messaging**: At the heart of Ecotone lies a resilient messaging system that enables loose coupling, fault tolerance, and self-healing capabilities. Ecotone leverages message-driven architecture to ensure seamless communication between components, reducing dependencies and promoting scalability. Messages are the backbone of the system, providing a reliable means of communication that can be easily replayed and debugged. With such foundation Ecotone enables higher level API so developers can focus on the business logic without worrying about the complexities of message handling.
**Declarative Configuration**: One of the standout features of Ecotone is its declarative configuration approach. Developers can define the desired outcomes and behaviors of their applications using intuitive attributes, allowing Ecotone to handle the underlying implementation details. This shift from imperative to declarative programming simplifies development, reduces boilerplate code, and promotes code readability. Ecotone’s declarative configuration empowers developers to express their intent clearly, resulting in more maintainable and expressive codebases.
**Building Blocks:** Ecotone provides powerful building blocks that facilitate the implementation of business logic. Those building blocks are based on well known patterns like Aggregates, Sagas, Projections etc.
Building blocks provide an API for the applications and make it easy to build and connect complex business workflows.
As Ecotone follow spirit of Domain Driven Design, your business code based on building blocks will stay clean of external dependencies, as you will never be forced to use or extend framework specific classes.
> Ecotone harnessing the same mature and well known principles from leading open-source platforms across languages. As the only PHP framework introduces Enterprise Integration Patterns as foundation for the resilient messaging architecture. EIP is implemented by giants like C#’s NServiceBus and Java’s Spring Cloud Stream. By introducing event sourcing and building blocks support provides, high level API similar to Java’s Axon Framework. Thanks to that Ecotone lets you experience the thrill of advanced architectural patterns without switching programming language.
>
> BOA vs. CRUD Applications: The Game-Changer
At this point, you might be wondering, “But CRUD-based applications have been working fine, so why change?”
True, CRUD (Create, Read, Update, Delete) operations form the backbone of many applications. However, these operations often become an oversimplification of what a business really needs, leading to complexities when trying to implement more intricate business rules. If domain is driven by business use cases, we need something more to handle it.
As a developer, you’ve probably experienced the pain of refactoring a large amount of code just to accommodate a minor business change. Or, you might have been puzzled, trying to map complex business rules onto a technical domain model. This is the fault of shifting our focus on technical aspects, instead staying aimed on the business.
> BOA shifts your application’s structure towards real business use-cases. Each business operation translates to a particular action in the application, making your code more intuitive and reflective of the business domain. It’s not just about data anymore, it’s about meaningful business operations and processes.
>

### Creating a Shift in PHP Application Development
It’s crucial to address PHP’s perceived decline. Many developers believe that PHP lacks the versatility and modernity offered by other languages. However, Ecotone shatters this misconception by providing an innovative framework that showcases PHP’s potential to deliver robust, scalable, and business-focused applications. With Ecotone, PHP can once again become an attractive option, appealing to developers who seek a fresh perspective and efficient development practices.
> Ecotone is not just another PHP framework. It’s a paradigm shift in PHP application development, making the creation of business-centered applications enjoyable and efficient. Its principles of BOA, support for DDD, and a message-driven architecture make it a powerhouse for modern application development.
>
> Moreover Ecotone isn’t just for building monolithic applications. It offers first-class support for microservices architecture. Where you can enjoy the benefits of BOA while architecting your application as a set of small, independently deployable services.
### Summary
Ecotone is a manifest for the future of PHP application development. It’s a reflection of the evolution of PHP from a simple scripting language to a robust platform for building complex, scalable, and resilient applications.
The time has come to approach software development from a business-centric perspective. With Ecotone, the future of PHP looks brighter than ever.
Are you ready for the shift? Embrace Ecotone and start building applications the way they should be — business-oriented, resilient, and simply enjoyable. Dive into the future of PHP application development, where business logic rules the roost, and witness a new dawn in your development journey. Welcome to the era of business oriented applications.
### Building Reactive — Message Driven Systems in PHP
URL: https://blog.ecotone.tech/building-reactive-message-driven-systems-in-php/
Last updated: 2025-12-01T14:10:37.000Z
### Building Reactive - Message Driven Systems in PHP
I believe applications in 2023 and beyond should be able to self-heal, isolate failures so they don’t cascade on other components, and provide us with help to get back on track when unrecoverable error happens.
They should help the developer on the design level when adding new features without breaking old ones, and be easily tested and maintainable in the long term.
Besides that, they should scale, not only through the infrastructure it runs on, but also through the application’s architecture and design.
[The Reactive Manifesto](https://www.reactivemanifesto.org/?ref=blog.ecotone.tech) provides guidelines to achieve this.
> The goal of this article is to show not only why, but how, we can build applications in PHP that are resilient, scalable and amenable to change.
> This article applies to business oriented applications, where business logic, processes and workflows can be found.
> It’s a summary of my experience gathered by years of working in business oriented software, and while building the [Ecotone](https://github.com/ecotoneframework/ecotone?ref=blog.ecotone.tech) messaging framework.
---
### Reactive Systems
Reactive systems solve everyday problems before they manifest themselves. They focus on making explicit what may go wrong, and preparing the system to deal with these issues. They are flexible, loosely-coupled and scalable.
Systems that are Responsive, Resilient, Elastic and Message Driven, are called Reactive Systems.
[The Reactive Manifesto](https://www.reactivemanifesto.org/?ref=blog.ecotone.tech) describes each of these four principles.
> Word “reactive” may be understood as Reactive Programming, this is not the same as Reactive Systems. Reactive Systems enforce design principles when building and integrating applications, reactive programming, on the other hand, is a programming paradigm. If you want to know more, you may read [article by Jonas Bonér](https://www.oreilly.com/radar/reactive-programming-vs-reactive-systems/?ref=blog.ecotone.tech), the Reactive Manifesto’s author.
Let’s dive into each of the principles.
- **Responsive** is being able to respond in a timely manner and provide the users with a good experience, which in result encourage them to keep on using the application. This can be achieved on numerous ways, to name a few: dedicated read models, caching, scaling etc.
- **Elastic** is being able to scale the system to meet its needs.
When the load rises, and responsiveness drops, we scale more web servers or consumers. On the other hand, when the load drops, we want to scale down to free the resources and decrease generated costs.
- **Resilient** is being prepared for failures. When we rely on anything external to our application — and this can even be another application over a local network — it may fail. Being resilient means understanding that failures will happen, anticipate this and implement solutions into the application’s design that will help us recover.
- **Message Driven** means that components, modules, services communicate via messages, not direct calls. Messages are pieces of data that can be transferred over the network. They are identifiable and carry an intention. When a Message is sent, other components may consume it at some point in the future. Yet, there is no direct dependency between components and they don’t rely on each other’s availability. By avoiding direct dependency between components, they become naturally isolated and remain unaffected by failures of one and the other.
In this article we will focus mainly on two principles: Message-Driven and Resilient. However as the four principles are deeply interconnect, focusing on those two we will, in the end, be touching on all of them.
For example, Message-Driven systems make it possible to scale the consumers and throttle the messages. This way, the systems can be scaled and remain responsive.
In Resilient Systems, failures are isolated, recovery can be automated and responsiveness can be preserved.
---
### Building Reactive Systems in PHP
We went through a bit of theory, which was needed to define the article’s goal. We now know that Reactive System principles help in building scalable, extensible and resilient software.
Now as we understand the theory, time to get our hands dirty and refactor a PHP implementation that does not make use of a Message-Driven architecture.
Suppose we run an e-commerce business. Customers come to our website to buy home accessories and furniture. We are so popular that we sell our products in multiple countries.
Our core business grows around providing fast product matching, placing orders and providing great promotions and discounts which encourage customers to visit our website.
In order to deliver products to customers we integrate with an external Shipping Service
We will focus the order flow:
- Storing Order in database
- Sending confirmation e-mail to the customer with the order’s summary
- Starting delivery process by calling a Shipping Service over HTTP API
### Phase 1 — Understand the problem
Let’s consider following implementation for the above scenario:
There is a lot going on to place an order.
We deal with data (storing order) and with side effects (sending email and calling the Shipping Service).
If one of the components fails (for instance: sending the email) it may affect the other parts (shipping or storing order).
Besides there is absolutely no way to recover from an error. If something fails, it will probably propagate to the end user, without clear details about what really happened.
If we try to resolve this within the current design, we will start leaking infrastructure code into our business code.
And with every new feature we will try to implement, the problem will come back as a boomerang, as we will not have dealt with its root cause.
There is a different architectural approach where this kind of problems are solved on the design level: Message-Driven systems.
### Phase 2 — Making it Message Driven, making it Resilient
One of the characteristics of a Reactive System is being Message-Driven.
It means that instead of direct calls between components, module or services, information transits using Messages.
Message-Driven architecture needs abstraction built on top of the language. The [**NServiceBus**](https://particular.net/nservicebus?ref=blog.ecotone.tech) Framework provides implementation of messaging architecture in C#, the [**Spring Integration**](https://docs.spring.io/spring-integration/reference/html/overview.html?ref=blog.ecotone.tech) foundation project for Spring Cloud introduce messaging in Java, [**Ecotone**](https://github.com/ecotoneframework/ecotone?ref=blog.ecotone.tech) Framework implements Message-Driven architecture in PHP
> The term “Ecotone”, in ecology means transition area between ecosystems, such as forest and grassland.
> The [Ecotone Framework](https://github.com/ecotoneframework/ecotone?ref=blog.ecotone.tech) functions as transition area between your components, modules and services. It glues things together, yet respects the boundaries of each area.
Ecotone’s Message contains a Payload and a Headers:
Payload can be anything, it can be a json/xml string, object instance, an array etc.
Headers are message’s metadata, contain framework specific information and custom information that is not part of the payload (e.g. timestamp, executor of the message, executor’s roles).
> You will not have to interact directly with Ecotone’s Messages, this will be hidden from your daily development. In fact Ecotone does not force you to extend or implement any framework specific classes or interfaces.
> Ecotone helps in keeping the business code clean and focused on the business problems, not the infrastructure.
Let’s move forward and define our Command Message and Event Message which will help us to decouple side effects.
We will change our OrderService so it can receive Commands and publish Events.
> Sometimes people discard the solution when they see Events and Commands, because all they want is to send an Asynchronous Message. Commands or Events are Messages.
> They are actually higher level concepts that make the intention of the Message explicit. In Ecotone they are POPO (Plain Old PHP Objects).
> Ecotone takes care of the serialization and the deserialization, of the payload and headers, when they are emitted.
Readability of this class has greatly improved. It becomes naturally oriented towards a single responsibility: Placing an order. Yet what is most important is that we have separated data storage from the side effects. We will see below how side effects are called now.
> Ecotone uses a declarative way to configure messaging. This means that you will be writing business code and tag it with attributes to connect it to the messaging system.
> By using the **#\[CommandHandler\]** attribute we indicate that this method is responsible to handle the PlaceOrder Command. Ecotone infers this from the type of the first typed property.
And this is how we call this Command Handler from the Controller now using a Command Bus:
> If you’re using Symfony or Laravel, Ecotone will automatically register Command and Event Bus interfaces in your Dependency Container.
Let’s define the Event Handlers that subscribe to the OrderWasPlaced event and trigger the side effects:
We have defined Event Handlers that subscribe to the OrderWasPlaced event.
Ecotone makes use of concept called Message Channels.
Message Channels are like pipes in which messages transit. In the example above, the channel is called “asynchronous\_channel”.

How message flows to Command Handler and to Event Handlers
When we use Command or Event Bus, we use a Messaging Gateway.
It takes our data and converts it into Ecotone’s Message. This is how we connect to messaging through simple interface.
When the Command is sent via the Command Bus, it goes through a channel to the Command Handler. The channel can be asynchronous or synchronous.
From there, in our case, we publish Event Message using the Event Bus. The Event will be deliver to each of the subscribing Event Handlers.
As we have defined Event Handlers to be asynchronous, with the
**#\[Asynchronous(“asynchronous\_channel”)\]** attribute, events will be handled asynchronously.
> Depending on your needs, multiple implementations of the Message Channel exist: RabbitMQ, SQS, Redis etc.
> Yet, whatever the picked solution is, the business code remains unchanged.
You can read more about about Commands handling [in Ecotone’s documentation](https://docs.ecotone.tech/modelling/command-handling?ref=blog.ecotone.tech).
If you want to read more about Events handling read this [section Ecotone’s of documentation](https://docs.ecotone.tech/modelling/event-handling?ref=blog.ecotone.tech).
### Protecting data and side effects from failures
By making our Event Handlers asynchronous, we have separated side effects from data persistence.
Right now, our Event Handlers will be executed asynchronously, after receiving the Message from a Message Broker. Failure of the summary email will not affect the placing of the order, as the order is already placed and stored in the database.
> In resilient applications we have to consider that the side effects will fail sooner or later. By decoupling side effects from data persistence, we prepare our system for this.
Event Handlers need to be isolated as well. If we were to handle them together, failure in one would affect the other. This would result in the same problems as coupling data persistence and side effects.
When we publish an Event, Ecotone delivers a copy of the message to each of the Event Handlers separately. This means, that each Asynchronous Handler handles his own Message in isolation.

Delivering Event Messages to Event Handlers
> You can imagine this solution as a Publish-Subscribe implementation, where each Event Handler is treated as separate subscription.
> This provides isolation of each Message Handler and safe retries become possible.
Read more about asynchronous event handlers in [Ecotone’s blog post](https://blog.ecotone.tech/asynchronous-php/).
Read more about publish-subscribe Event Handlers in [Ecotone’s documentation](https://docs.ecotone.tech/modelling/asynchronous-handling/publish-subscribe-event-handlers?ref=blog.ecotone.tech).
### Securing your Messages from being lost
We have not yet fully secured placing of the order.
After storing the Order, we are publishing events to an external Message Broker. This means that there is more than one storage engine involved (Database and Message Broker).
What does this mean for us? Well, the delivery of the Event to the Message Broker could fail and, depending on the implementation, this might cause a rollback of the order or its persistence without triggering the side effects. As a result, the customer won’t receive his Order.
The Outbox Pattern is a solution for such use cases and Ecotone implements this using Message Channels.
By default, Ecotone wraps the Command Handlers and all subsequent actions in a transaction. This means that if we use [Database based Message Channel](https://docs.ecotone.tech/modules/dbal-support?ref=blog.ecotone.tech#message-channel), the Messages will be committed along with the Order.

How outbox pattern can be applied with Message Channels
> Ecotone wraps the Command Handler and all subsequent actions in a transaction. So all the synchronous Event Handlers are part of the same transaction and changes remain atomic.
> It’s especially useful when the application design requires the modification of multiple Entities or when synchronous event projections are required.
> Non-atomic actions such as side effects can run asynchronously.
With a ServiceContext, one can add extra configuration to Ecotone.
Above configuration switches Message Channel of name “asynchronous\_channel” to make Database Channel.
As this is database channel now, messages will be committed together with data change.
Read more about using Outbox Pattern and scaling the solution in [this Ecotone’s blog post](https://blog.ecotone.tech/implementing-outbox-pattern-in-php-symfony-laravel-ecotone/).
### Handling Message Deduplications
In most of the Message Broker setups, Message can be emitted more than once. This happens, because our asynchronous Message Handler may successfully handle the message but fail to confirm this to the Message Broker.

dFailure during acknowledge of message to the Message Broker
In case of failure, the Message will be emitted again by the Broker, but we have to prevent handling the Message a second time.
All Ecotone Messages contain a unique MessageId and can therefor be identified and tracked. Based on this, Ecotone provides deduplication mechanism by implementing [idempotent consumer](https://microservices.io/patterns/communication-style/idempotent-consumer.html?ref=blog.ecotone.tech).
When message is handled successfully, Ecotone stores the MessageId. This way duplicated messages can be tracked and, when required, discarded.
Deduplication can be customized for the Message Handlers. This may be useful when handling external events (e.g. webhooks) with custom identifiers that we would like to track in order to recognize duplicates
In above example we’ve sent a Command with Metadata. All metadata (e.g. executorId) is accessible in the Message Handlers, via the Header attribute.
If you want to know more about how Handlers are executed read this part of [Ecotone’s documentation](https://docs.ecotone.tech/messaging/conversion/method-invocation?ref=blog.ecotone.tech).
> If we were to generate the orderId on the frontend side, we could actually deduplicate orders this way. This ensures that a given order will only be submitted once, even if we get two or more same requests.
### Recovering From Synchronous Errors
One of the characteristics of a Reactive System is being Resilient.
Resilience means we’ve prepared our system for failure and that it can gracefully recover without any intervention.

Automatic retries when calling synchronous Command Handler
Placing orders uses synchronous calls through a Command Bus. Imagine losing the database connection. The customer will not be able to finalize his order and if there is no automatic retry mechanism in place, the order will be lost.
As we now have isolated the side effects from the Place Order Command Handler, it becomes possible to retry it.
Ecotone lets us setup a retry strategy for retrying synchronous Command Handlers.
With the configuration in the example above, Commands will be retried automatically when the set exceptions are thrown. Only after three failed retries will these exceptions will be thrown outside of Command Bus.
> We isolated Command Handler from the side effects and it only stores the Order now. The number of possible errors has been reduced.
> The most common problems are database connection issues or optimistic locking exceptions when concurrent access occur. Recovering from these issues becomes trivial.
### Recovering from Asynchronous Errors
In case of our Asynchronous Event Handlers, we may retry them too.
However in this case we have a bit more options, how we want to do it.
#### Instant Retries
The same mechanism as for synchronous Command Handlers can be used for asynchronously handlers. In this case, it works for both Command and Events (remember our Event Handlers are isolated, so we can safely retry them).
#### Delayed Retries
Sometimes, instant retries will not solve our problem. The Shipping Service could be unavailable for a couple of minutes for instance. In that case we may retry the message with delay.

Delayed Message is resend to original message channel with delay
With Ecotone you can set up delayed retries. If Shipping Service is down, we give it some time to recover and try again.
This mechanism deals with two problems: we unblock the customer as the message is delayed, and we give the system a chance to self-heal.
In this configuration we’ve set up a retry strategy with three attempts. Initial delay is 1 second (1000ms) and will be multiplied by 10 with each attempt. It works out of the box when your Message Channel supports delays (SQS, RabbitMQ, Dbal, Redis).
When the Message cannot be handled and the number of delayed retries is exceeded, the error is unrecoverable and the Message will be moved to the Error Channel.
> Everything that goes [over network is not reliable](https://en.wikipedia.org/wiki/Fallacies%5Fof%5Fdistributed%5Fcomputing?ref=blog.ecotone.tech) and resilient systems are built with this in mind.
> Resilient systems, when things go wrong, recover and continue working.
> With good foundations, the system self-heals and you don’t need to worry about external service being down for a couple of minutes. Eventually, everything will be fine.
### Handling Unrecoverable Errors
After multiple delayed retries, if the problem is not resolved, more retries will probably not change anything.
The error is unrecoverable and needs to be dealt with differently.

Message exhausted delayed retries and is pushed to the Error Channel
Ecotone solves this by implementing [Error Channel](https://www.enterpriseintegrationpatterns.com/InvalidMessageChannel.html?ref=blog.ecotone.tech).
After retries are exhausted the Message is moved to Error Channel.
The Error Channel will work as publish-subscribe (if not defined otherwise). This means as many as needed Event Handlers can be connected in order to provide custom logic, like sending Slack notification or Email, when Message fails.
Ecotone comes out of the box with solutions that connects to Error Channel in order to store Error Messages in a database and a provide set of functionalities to review, replay or delete them.

Error Message is stored in database. Fix was released and message can be replied
The Message is moved to Error Channel, as we enabled [Dbal Dead Letter](https://docs.ecotone.tech/modules/dbal-support?ref=blog.ecotone.tech#dead-letter) (Ecotone’s out of the box solutions), it’s stored in the database.
Then we review what happened, it could be a new bug introduced in our notification template. We then fix the issue, release the change and replay the Message.
The message will return to the original message channel it came from, so it can be re-consumed and handled by Notification Subscriber.
Read more about handling Error Messages in the section of the [Ecotone’s documentation](https://docs.ecotone.tech/modelling/error-handling?ref=blog.ecotone.tech#error-channel).
### Handling multiple Applications
The default solution that [Dbal Dead Letter](http://Protecting%20data%20and%20side%20effects%20from%C2%A0failures) provides is to manage Error Message via CLI.
```bash
Symfony: bin/console ecotone:deadletter:replay {messageId}
Laravel: artisan ecotone:deadletter:replay {messageId}
Ecotone Lite: $messagingSystem->runConsoleCommand("ecotone:deadletter:replay", ["messageId" => $messageId]);
```
This is not ideal as we need to access production servers to replay the message and, when we have more than one service, we may need to jump between the servers.
Ecotone, provides Ecotone Pulse which is an application that aggregates Error Messages from your different services and provides a UI for reviewing, replaying and deleting them.

Ecotone Pulse Dashboard
Read more about Ecotone Pulse in the [Ecotone’s documentation](https://docs.ecotone.tech/modules/ecotone-pulse?ref=blog.ecotone.tech).
### Summary
As we’ve seen in the examples above, some small changes were enough to decouple the components from each other by introducing Message-Driven architecture. The system has become much more stable and reliable. This is the power of messaging architecture: it enables us to go beyond limited programming of synchronous calls and build systems that are robust.
It took me over five years to build Ecotone into it’s current shape, and I believe that, right now, it opens new ways to integrate and build applications in PHP and use well known and robust reactive principles.
You really don’t need to start new project from scratch, go through a major rewrite or change your main framework to start building applications following message driven architecture.
[Ecotone](https://github.com/ecotoneframework/ecotone?ref=blog.ecotone.tech) can be used with [Laravel](https://docs.ecotone.tech/install-php-service-bus?ref=blog.ecotone.tech#install-for-laravel) and [Symfony](https://docs.ecotone.tech/install-php-service-bus?ref=blog.ecotone.tech#install-for-symfony) and integration is trivial.
In case you don’t use these frameworks, then you can use [Ecotone Lite](https://docs.ecotone.tech/install-php-service-bus?ref=blog.ecotone.tech#install-ecotone-lite-no-framework).
This article summarizes how to implement Message-Driven architecture but there is much more information in the Ecotone documentation.
Start small, refactor one functionality at a time, play with it and test it out. Once you feel more confident with this design pattern take on another module. Iterate and with each increment, you’re application will become more message-driven and reliable.
---
Demo project of the integration is available in [this repository](https://github.com/ecotoneframework/quickstart-examples/tree/main/RefactorToReactiveSystem?ref=blog.ecotone.tech).
### Making your Application stable with Outbox Pattern
URL: https://blog.ecotone.tech/implementing-outbox-pattern-in-php-symfony-laravel-ecotone/
Last updated: 2024-03-02T16:22:28.000Z
Whenever we send `asynchronous messages` and `modify state` in database within same action, we put ourselves at risk. The risk come from the possibility that state will be persisted and message will fail or vice versa.
When we send asynchronous messages to external broker like `RabbitMQ` or `SQS` this may fail, when we store something in the database this may fail. Operations over network are not 100% reliable, and in order to keep our applications stable, we need to build software that considers that.
So prevent backfire when we need to send asynchronous messages and modify the state, we may implement Outbox pattern, which ensures that no message or state will be lost.
Examples in the article will be using [Ecotone](https://docs.ecotone.tech/?ref=blog.ecotone.tech), PHP Framework.
### Implementing Outbox Pattern
Let’s consider below example:
In the example we store Order in database, however we may fail to send our `OrderWasPlaced` Event Message.
General idea of Outbox Pattern is to be sure that no messages or state is lost along the way, if this is achieved then we’ve a success.
So how do we achieve this? Instead of having two different storages in same action, we need to have one.
In our example above we could achieve that, by replacing `EventBus` implementation with something that will instead of sending to `Message Broker`, will store in the `database`. Then we would wrap whole `Command Handler` in `transaction`. This ensures that no state or messages are lost, as messages would be persisted together with state.
The final step is to fetch messages from database and send them to Message Broker, after that we can discard message. Then `message consumer` will pick it up and handle.
> Most of the Message Brokers are at-least once delivery. This means that you are guaranteed to receive the message at least once, however you may actually receive it two or more times. This may happen because consumer will fail to acknowledge the message to the Broker, yet message was handled successful.
> That’s why it’s worth to implement Message Deduplication. So even, if we receive the message for second time, we will know that it was successful and then we can skip it.
> Ecotone provides message deduplication by default.
### Consuming Message from Database
The solution that we are aiming at, is to not lose messages or state, and there are more ways to achieve that.
The previous example is most common implementation of Outbox Pattern, however we can achieve the same differently.
In above example we made Event Handler asynchronous. If the transport channel will be database transport, then we will send related Messages to the same database in which we store the state. So instead of fetching and sending them to broker, we can consume and handle them directly without any Message Broker involved.
> Using Message Channels and consuming messages directly from Database does not require custom implementation for Outbox pattern. As database channel is just another implementation, that we can use of.
> What we need to be sure of, is that sending the message and storing the state are wrapped in same database transaction.
### Scaling with Outbox pattern
It’s possible to scale your database channel consumers, like any other consumers. If you want to keep the order and still scale, you may use different asynchronous channels to split the workload and then running single consumer per channel.
However you may decide to not scale your database consumers, as they put more workload on your database, especially when there is no auto-scaling possible. In that case we can make use of the database channel just for the `Outbox pattern` to pass through message to different channel that will be responsible for handling it:
In `Ecotone` you may pass Messages from one channel to another.
In above example, we defined Event Handler which will receive Message first on `Database Channel`, and after fetching it from there it will passed to `RabbitMQ Channel`.
This way database consumers are only responsible for passing Message to next channels, and actual work is done `RabbitMQ Consumers`.
> In Ecotone you may pass message through multiple channels. This allow for example to move messages to consumers that are easily scalable and use other channels for keeping consistency (outbox pattern).
### Summary
Whatever solution you choose to use, the most important is to store messages and the state within same transaction. You may actually use outbox pattern for critical parts of your system and in places where losing message is acceptable or publishing messages is the only operation, you can publish messages directly to RabbitMQ channels.
Ecotone aims for building PHP applications that are stable and solid, that’s why `Outbox pattern` and `Message deduplication` is available out of the box.
### Testing Asynchronous Message Driven Architecture
URL: https://blog.ecotone.tech/testing-messaging-architecture-in-php/
Last updated: 2024-03-02T16:22:57.000Z
Tests are vital parts of our systems. Easy to understand and modify tests will help us in keeping the project in good shape for long period of time.
First we may start with synchronous code, however sooner or later we will need to start processing part of our flows asynchronously, and this is when Message Driven Architecture becomes handy.
When using `Message Driven Architecture` we mostly aim for loose coupling of our components, quick recover from issues and possibility to handle high load.
However due to decoupled and asynchronous way of handling things, testing becomes much bigger challenge.
Testing this kind of architecture can easily become nightmare from the perspective of the speed and maintenance of such tests.
In this article we will aim on making those tests quick, easy to understand and write using examples from [Ecotone Framework](https://blog.ecotone.tech/).
### Asynchronous execution
When we are dealing with synchronous code, writing tests is pretty straightforward.
We set up `state`, we call some `Class` or `API`, and we `assert` our expectations.
In case of asynchronous code we have `publisher of a message` (e.g. command/event) and `message consumer` which runs in separate processes. This make testing more tricky if we want to test full scenario, as it requires two processes to communicate.
Our test scenario, will be placing an order and sending asynchronous confirmation notification to the customer.
> *The `asynchronous` attribute is related to channel (queue/transport).*
> *Consumer with same name as channel (`notifications`) can be run to start consuming messages and executing our Event Handler.*
### Running Publisher and Consumer in separate processes
We may run the test case which will publish given message (publisher side), and run the consumer in the background. Then we will be looping and awaiting for our expectation to be fulfilled.
This solution has few drawbacks however:
- It increase time for test to run, as now we bootstrap new process
- It becomes hard to debug, as it runs in the background and we don not have full control over the execution
- We can not use `in memory` / `dummy` implementations, as changes in one process, will not be visible in the second one
Having a lot of tests like this will slow your test suite dramatically.
When test suite fails it may be really hard to debug what is the cause, as consumer process is a background process.
Besides due to lack of shared memory stack, we will be required to build some tooling to support this (Like continues checking if state in database have changed for X seconds before we will consider test a failure).
> The biggest advantage of running publisher and consumer in separate processes is it’s the closest way to how things are running on the production.
> However this comes with huge cost, as those kind of tests are slow and hard to debug and often starting to deviate from production due to required support tooling.
When we will run consumer process it will block our test suite, as consumer after handling given message will be waiting for next ones.
However `Consumers` can be implemented with possibility to intercept execution.
Interception happens mostly for starting transactions, logging and error handling, but can also be used for testing purposes.
Using this technique we may implement `limit of handled messages` and `execution time limit`.
`Handled message limit` will ensure that we finish test as fast as the message is handled, `execution time limit` on other hand protects in case of failure that the test will finish.
> When running consumer in test be sure to intercept it.
> This will decrease test suite time and ensure no zombie processes running in the background.
### Running asynchronous code as synchronous
In most of the cases the `consuming process` is actually the same application, which means we can actually run it from `publishing process` too.
Running consumer within same process as our test scenario, will decrease our test suite time and will make debugging much easier.
It will also allow us for using in memory implementations, as changes will happen within same process. This is huge advantage, as we can mock things out for particular scenario with ease.
> *Running publisher and consumer within same process (test scenario), is still much like production run, as executed code is the same.*
### Running Consumer with In Memory Channel
In most of the cases when we run test with real Message Broker behind the scenes, we can’t run our tests in parallel.
Besides that when we interact with Message Broker our test scenario takes much longer than it would be with in memory implementations.
`Message Queue` which is consumed by the Consumer is just a `Message Channel`.
If our Consumer implementation is abstracted from specific broker implementation, then we will be able to replace it with `In Memory Message Channel`.
This is exactly the case for Ecotone, you may switch Message Channel implementation as it suits you.
> Using In Memory implementations for Message Channels, speeds up tests to and allows to run them in parallel.
### Switch from Polling to Event-Driven
`Pollable channels (Queues)`creates [Pollable consumers](https://blog.ecotone.tech/messaging/messaging-concepts/consumer#polling-consumer), which means the code will be executed asynchronously.
The second option is so called [Event-Driven consumer](https://blog.ecotone.tech/messaging/messaging-concepts/consumer#event-driven-consumer), which means code is triggered synchronously (imagine synchronous Event/Command Handler).
Ecotone Framework supports Message Channels and different Consumer implementations, therefore we are able to switch our code from running asynchronous to synchronous and vice versa.
> With good messaging framework asynchronicity is abstracted away and we can write code that is unaware of the consumption process.
> This allow us to write simpler tests and switch Message Broker implementations without affecting our production code.
### Limit scope of your tests
In messaging architecture it often happens that given message is consumed by multiple handlers. However in given test scenario, we may be only interested in small portion of the flow and we want to skip the rest.
With Ecotone testing support we provide list of classes that should be resolved for given test scenario. This way we can easily test small portion of our code base in given test scenario.
```ruby
$ecotoneTestSupport = EcotoneLite::bootstrapForTesting(
// pass list of classes that should be included in this test
[OrderService::class, OrderNotifier::class,
$dependencyContainer
);
```
### Summary
Testing message driven architecture may be challenging, due to decoupled nature and asynchronicity. However it comes with so many pros, especially when the system grows, that is becomes a need at some point of time.
We may lower the bar with good supporting tools that messaging frameworks provide.
So at the end we can have all the messaging benefits and still be able to write simple yet effective tests.
### Loosely coupled Microservices in PHP
URL: https://blog.ecotone.tech/loosely-coupled-microservices-in-php/
Last updated: 2024-03-02T11:19:53.000Z
In this article we will get deep into the subject of integrating *Microservices* in PHP and keeping them loosely coupled.
We will focus on integration via `messaging`, as integration of microservices over [HTTP has a lot of drawbacks](https://blog.devgenius.io/how-to-integrate-microservices-a506fe2d1a48?ref=blog.ecotone.tech) and requires separate article to tackle.
Besides of the details and theory how to achieve that, we will learn how to actually make it happen in PHP with [Ecotone Framework](https://github.com/ecotoneframework/ecotone?ref=blog.ecotone.tech) (works with `Symfony` and `Laravel`).
### Sharing message classes
So one of mostly used solution in PHP is to share classes in separate package or just copy them in each of the service.
This gives a hint of what we are dealing with and helps with deserialization.
However the more classes we share the more changes we need to do.
Then it’s go down the spiral, where it’s not about releasing a single service when we do a change, it’s about releasing several services, because we need to keep them in sync.
### Route messages, not classes
Routing message by class works by keeping name of the class in header’s of the message. This header is later used in order to know, which class we should deserialize to.
When we expect other service to understand our class, it creates situation, where the other service need to have a class with exactly same name.
We can easily imagine situation, where we forget to change the name in one of the services or release another service with delay, which would create `failure due to mismatch in class names`.
> Actually if we handle message within single service it still may create issues.
> If message is in the queue and we will `change class name or namespace`, there will be no way to deserialize it.
So how should be messages routed?
In most of the cases we already use this solution, however we have not promoted it to the application level, the solution is `routing keys`.
> Routing keys can be seen as application level names for the events and commands.
> They create contract and shared naming between services so we can understand the intention behind the message.
When message is routed by routing key, we can map given routing key to class name.
In result refactoring class name in one service will not require changes in another one.
> With Ecotone you actually do not need to build any kind of `routing-key -> class-name` map.
> Message is routed to given handler based `routing key` and then `payload` of the message is deserialized `based on first method parameter`.
### Being explicit about your public API
Whenever given event or command is exposed to other services, it becomes part of your public API.
If you publish every single event to outside world, it becomes a problem when you want to change it, as it’s not easily clear will it affect external services.
> Contracts between services are part of application level and they should be explicit, not hidden in Message Broker implementation.
Ecotone provides *DistributedBus* for services publishing messages.
In this way we can be `explicit on the application level` if event is meant to be consumed by other services and we need to be `aware, if we want to change it`.
On the side of consumer, we make it explicit that message we are subscribing to, is coming from external service.
In case we don’t add `Distributed` to `Event Handler` this event will be treated as local (private) one.
The same works for `Distributed Command Handler`, none of the services will be able to execute our `Command Handler`, if it's not explicitly `distributed`.
This make it clear for new joiners and in the long term of the project, which Handlers are executed by `external services` and which are `local ones`.
> For pushing this forward, you may add Consumer Driven Contract with [Pact](https://docs.pact.io/?ref=blog.ecotone.tech).
> This will allow you to know what fields from your message are used by other services, so you can easily modify ones that are not.
### Public and Private events
Even, if we will explicitly publish distributed events and limit their amount, we still may be blocked by other services to make internal changes.
If we will modify `payload` or we will want to drop or replace the event, then we may end up in affecting other parties.
That is why it's worth to distinguish between `public` and `private` events.
By using `DistributedBus` we already made a step forward by being explicit about what events we are sending outside, however there is one more benefit to this.
> Before publishing event we can now transform it into a different one. This event will become our public API and the other one will stay private within publishing service.
This gives us back a lot of power. As long as we can deliver this `public event`, we can modify our internal service the way we want without affecting other parties.
> We can enrich public events with extra details, so the `need for consumption of other events or calling our HTTP Api will decrease`.
### Know what you send
`Command` and `Events` are `Messages`, however there is semantic difference to each of them.
*Command* `targets specific handler`, which means there is only a single endpoint that handles this message.
*Event* on other hand, does not target anything. It's being published and parties that are interested may `subscribe`. This means that there may be 20 subscribers, but also there may be none.
So how to deal with this in distributed environment.
When we `send` command, we should target specific Service and given Handler in this Service. This identify targeted service and make sure that no other service will handle this command.
> Services names, just like routing keys are part of the application level. We need to know, who and why we are communicating with.
The first parameter it targeted service name, where command will go and second is the routing key for the handler.
> In case there will be `no given handler` in targeted service or it `Handler` won't be `distributed`, message will fail and may land in `DLQ` depending on the configuration.
In case of events, each service explicitly states what event it want to subscribe too.
> Subscribing and receiving only events that given services is interested need, help in keeping your message flow performant.
### Message payload can be anything
Current frameworks in PHP have built mental modal of `PHP Message implementation` being equal to `Class` or `payload` being equal to `Class`.
That was never a case with messaging principles, payload of the message can be anything a `json/xml`, `array`, `class` or even an `int` or `simple text string`.
> Neither message, neither payload of the message must be a Class.
> Message have payload which can be deserialized to `Class`, but at the same time we should be able to deserializable it to `array` or even keep it as `json`, if we wishes to handle it this way.
What if you just need the intention? For example it may be enough to know that invoice was generated, to send an sms to the customer. You don’t need to know the details at all. Looking at the message this way create much more loosely coupled interface.
Let’s take as an example publishing events that `Order Was Placed`.
We may not really want to create classes, as the only thing we need it to retrieve `userId` to send an email.
Other scenario can be that we want to just store message payload for later auditing purposes directly in `json`.
> In Ecotone, whatever content-type (xml, json, avro, protobuf etc) message has, as long as you’ve registered Converter for it, you will be able to deserialize it to class if you want to.
In general we may even use empty method declaration, if there is a need.
> This gives power back to developers. We create classes when we feel the need, not because we need to.
### Metadata stuff
What, if we want to provide details like who was the executor of given action, or a time where when it happened, or maybe some infrastructure information like from which domain given order was placed?
This could be potentially added to the `payload` during step for enriching `public event`. However this may blur the image of the event, and in general may not related with it at all.
Suppose we have multiple sites where customers make order and we want to enrich event’s metadata with domain where order was placed.
> Ecotone provides easy way to work with metadata, it will take care of passing it via Message Broker and allow you to make use of it on other end.
### Summary
With time and with maturity of the project we want more solid and long term solutions for integrations. Those solutions were used in other languages considered more mature and now `Ecotone` brings those into PHP, so we all can benefit and build on solid foundations.
Loosely coupling is art. It reveals things that are hidden, by making them explicit.
The things that before could look hard, becomes smooth and just feels good to do.
And this is the aim, good experience for us and shared understanding, so we can change services with smile on our faces.
If you want ask question or have a discussion about `Ecotone` or `Messaging` in general, join [Ecotone’s community channel](https://discord.gg/CctGMcrYnV?ref=blog.ecotone.tech). Let's build community around Messaging in PHP together and push our language even further :)
### Handling asynchronous errors in PHP with Laravel Queues, Symfony Messenger and Ecotone
URL: https://blog.ecotone.tech/working-with-asynchronous-failures-in-php/
Last updated: 2024-03-02T16:23:34.000Z
You may be using [asynchronous processing](http://essing-in-php-symfony-messenger-laravel-queues-and-ecotone-8ca17102c5b2/?ref=blog.ecotone.tech) with one of the messaging platforms like RabbitMQ, SQS, Beanstalkd, etc already.
Or you may be using one of the frameworks ([Ecotone](https://docs.ecotone.tech/?ref=blog.ecotone.tech), [Symfony Messenger](https://symfony.com/doc/current/messenger.html?ref=blog.ecotone.tech) or [Laravel Queues](https://laravel.com/docs/9.x/queues?ref=blog.ecotone.tech)) to hide messaging platform details.
No matter what you use, sooner or later you will face errors when processing a message.
So how do you deal with failures, when your code runs asynchronously?
Handling errors with grace may actually change the way you code and make your application more maintainable and more robust.
### Auto recover wherever it’s possible
All the frameworks comes with functionality to redeliver the message in case of failure.
This is your first line of defense to avoid being called at night or having support shifts.
There are errors that can be auto recovered like connection failures, 3rd party service being unavailable or optimistic locking exceptions.
> Our main aim should be to self-heal wherever it’s possible. Message will fail from time to time this is unavoidable, what is avoidable is manual intervention.
You want to redeliver those message with increasing delay, to have higher chance of self-heal.
### Handling everything within HTTP Request
There may be temptation to handle everything like placing an order, sending an email, taking an payment within HTTP Request.
This may lead to a solution based on try catches and saving the errors so someone can pick it up and fix later.
This makes us write custom code to handle failures and may lead to non recoverable state or manual intervention in order to recover.
> System can auto recover without the need to write any additional code. Messaging Frameworks will take care of it, thanks to that your code can focus on the business problems not technical ones.
This is one of the reasons why messaging platforms exists, to help you build more solid and stable code.
Let your HTTP request do single action like placing an order and `as a effect` send an event message that will state, that the order was placed.
From there you can subscribe to this event and do the rest in asynchronous manner.
### Multiple Handlers for single message
If your event message is handled by multiple handlers, then in case of redelivering such messages due to failure, you may sent email twice or make a second payment.
Some external providers allow for using `imdepodency keys`, which allow to handle duplicate calls, but that is not always the case.
The best way is to actually have single action per message, how to achieve that when there is a need for two or more actions to happen?
Let’s take as an example situation of placing an order, which in result we want to send an email and take payment from credit card.
### Symfony Messenger
The main implementation would look like this:
If there will be a failure, we may may end up with double payment or email.
In order to solve this we need to create custom handlers.
This fixes the main issue, however introduce extra messages that normally would not exists and increase complexities of the code.
We could try to solve this by sending `SendPlaceOrderEmail` and `MakePayment` messages instead of `OrderWasPlaced` directly after order was placed.
This however will put responsibility on crafting those messages during placing the order and will invert responsibility. Placing an order is a complete action in itself, the above actions are just result of it.
### Ecotone
In case of Ecotone we mark given Handler as asynchronous, not the Message.
Then a copy of a message is delivered to each of the handlers.
This means that each asynchronous handler works in atomic way and process the message separately.
In case of failure, only single handler will fail and will be safe to retry.
### Laravel Queues
In case of Laravel Queues, there is no concept of handling Event Messages, everything is a Job that should fulfill given action.
This solves the main problem by design, however it inverts the responsibility and make placing an order action aware of things that normally would subscribe to it a result.
### **Temporary Interrupted Flow**

Developers that are new to messaging architectures tend to build surrounding handling code, instead of allowing messages to fail.
This may be a field in database like `wasEmailSent` which is populated by try catch, whenever email sending fails.
> We can write code agnostic of the infrastructure errors and keep track of the them without adding extra storage for each of the errors.
Messages are first class citizens, not just a job to perform. They actually tell us a story, how the flow looks like in our system.
Messages may fail for variety of reasons, however if they fail, we will auto recover, and if not, then we investigate, fix and replay.
> Treat messages like part of the flow that can be temporary interrupted, after fixing the issue the flow will resume.
### Unrecoverable Errors
There are cases when error will not be recoverable or will take to much time in order to be recovered automatically.
This kind of errors are mostly related to issues with the application code, incorrect calls / compatibility broken with 3rd party API, or service that we use being down for longer period of time.
The application level error can be really beneficial
> Unrecoverable errors are places where learning happens, as it may reveals scenarios that we have not thought of before.
For example, as a result of closing an account, we want to terminate electronic wallet, however the wallet has positive balance, which end up in exception.
What should we do in that case, payout the money to customer’s bank account or close it anyway?
Those are the errors that may rise questions to our Product Owners / Domain Experts, in order to learn more about how the business works.
### Dead Letter Queues
Dead Letter Queue is a place where unrecoverable error messages lands and we need to make manual intervention in order to solve the problem.
After fixing the error, we can replay the error message to handle it correctly and resume the flow.
> Dead Letter Queues are your last line of defense in case the errors that can not be recovered automatically.
Let’s check how our frameworks are handling those.
### Symfony
Symfony provides way to store unrecoverable errors, in a way so you can review, replay or delete them.
You may review the error messages from the console or directly from the database.
> *When your failure database storage is down, Symfony will* [*drop your error message*](https://github.com/symfony/symfony/issues/36870?ref=blog.ecotone.tech) *and you will not be able to recover it.*
### Ecotone
Ecotone provides way to store unrecoverable errors, in a way so you can review, replay or delete them.
You can review the errors directly from the console and the database.
In order to control error messages for all your services from single place, [Ecotone Pulse](https://docs.ecotone.tech/modules/ecotone-pulse?ref=blog.ecotone.tech) was created. It allows your to review, replay and delete error messages using single application.

Ecotone Pulse
> *When your failure database storage is down, Ecotone will keep your message in the queue, till the moment your database will be back online.*
### Laravel
Laravel provides way to store unrecoverable errors, in a way so you can review, replay or delete them.
You can review the errors directly from the console and the database.
```
php artisan queue:work redis --tries=3 --backoff=3
```
> When your failure database storage is down, Laravel will keep your message in the queue, till the moment your database will be back online.
### Summary
Existing frameworks provide variant of battle tested solutions, that will help you in building more solid and stable applications.
Some errors will happen no matter of how well we test or design our code, that is why we need support tooling that will help us recover from those.
In the end, it’s about customers having good experience, which means system working in stable way, even when add tons of new features :)
### Message Processing in PHP — Symfony Messenger, Laravel Queues and Ecotone
URL: https://blog.ecotone.tech/message-processing-in-php-symfony-laravel-ecotone/
Last updated: 2024-03-02T16:23:58.000Z
### Message Processing in PHP — Symfony Messenger, Laravel Queues and Ecotone
Message processing becoming more and more popular in PHP.
Putting all the logic inside simple Request — Response model becomes not enough for our current system needs.
Our applications do more and more. It becomes standard to send an email after registration, call external Services or perform some intensive tasks.
Messaging platforms (RabbitMQ, Kafka, SQS, etc) **helps in solving those problems** by increasing the amount of load system can take, introducing background processing and handling failure retries.
**Symfony Messenger**, **Laravel Queues** and **Ecotone Framework** provides higher level abstraction for message processing that hides integration with given messaging platforms and introducing additional features.
### Differences between Task Queues and Message Brokers
There are different types of platforms that may be used to solve asynchronous processing in PHP, some of them are Task Queues and other are Message Brokers.
***Task Queues*** like [Beanstalkd](https://beanstalkd.github.io/?ref=blog.ecotone.tech) provides abstraction over Task (Message).
Task or Job is describing what needs to be done and asynchronous Worker process handles it.
Task Queues provides full lifecycle support, so we can track status of given Task (ready to process, being processed, completed).
They provide `Point to Point Channels`, which means we send Task (Message) and it will be delivered to exactly one Worker (Consumer).
> Task Queues are helpful with offloading the system workload
On other hand ***Message Brokers*** like [RabbitMQ](https://www.rabbitmq.com/?ref=blog.ecotone.tech) provides more flexible way of working with messages.
It allows for `Message Routing` based on different criteria or delivering copy of a message to multiple Consumers (Workers).
For Message Brokers, Message is just an information that is passed from one place to another. The application makes actual meaning out of it.
Thanks to routing capabilities, Message Brokers can deliver the Message in `Point To Point` fashion or by `Publish And Subscribe`.
In Publish and Subscribe, Message is published and any party that is interested can subscribe to it. Thanks to that Publisher can be fully decoupled from the subscriber (consumer).
> Message Brokers can offload your workload, but also are great for building message flows and cross service communication, as by it nature they handle message distribution and decoupled communication.
---
Symfony Messenger, Laravel Queues and Ecotone **provide own abstraction to work with sending and handling messages**.
This means, that they **treat platforms as transport layers** providing enough integration to cover their own functionality.
This helps in providing similar experience over different platforms and lowers the entrypoint by hiding the complexity.
> *It’s worth to know what functionalities your framework provides.*
> *As long as it will be covering your use case, you will not need to deal with Message Broker or Task Queue integration directly.*
### What is Messaging?
Description bellow comes from great book [Enterprise Integration Patterns](https://www.enterpriseintegrationpatterns.com/patterns/messaging/?ref=blog.ecotone.tech), which describes usage and implementation of messaging patterns.

Messaging or Messaging Architecture is a way to implement **communication using Messages**.
Just like a letter, Message contains of **Payload** and **Headers**.
The payload contains of data that we want to transfer.
Headers on other hand are used to route the message and enrich it with extra information, like identifier of the message, who was the executor or when it occurred.

Messages are sent and received from **Channels** using **Endpoints**.
Channels can be Point-to-point where only one consumer can receive message sent to the channel, or Publish-subscribe which broadcast the message to all subscribing endpoints.
Endpoints are places where we process, transform or filter out the Messages, this is the place which we mostly call **Message Handlers**.
In general, an application should not be aware that it is using Messaging.
Most of the application’s code should be written without messaging in mind.
This frees the application from integration concerns and to let it solves business problems.
So how can Message Handler (Endpoint) stay unaware of Messaging and still receive and send Messages?
It’s wrapped by **Consumer**, which depending on the need can be **Event-Driven** (executed synchronously) or **Polling** (asynchronous, polling the messages).
To send messages to the channel, we are using **Messaging Gateway**. This is abstraction, that hides complexity of constructing Messages and connecting to external platforms.
### High Level Framework Abstraction
Let’s take a look on the abstraction that each of the Framework provides. I will be following Messaging terms, however I will map those terms to implementation details of each of the frameworks.
### Symfony Messenger
[**Messenger**](https://symfony.com/doc/current/messenger.html?ref=blog.ecotone.tech) introduces messaging solution in Symfony Framework.
It provides a message bus with the ability to send messages and then handle them immediately in your application or send them through transports (e.g. queues) to be handled later.
> Symfony Messenger has more similarities with Message Broker than with Task Queue.
### What is Message?
Message (called **Envelope**) is a class, which contains of Payload (called **Message**) and Headers (called **Stamps**).
> In Symfony Messenger **Payload** must be **PHP Class**.
As long as you don’t want to extend basic functionality, you will not need to work with Symfony implementation of Message directly.
### How Messages are send to the Message Handler?
The Message Gateway is called **Bus**.
```
$bus->dispatch(new PlaceOrder('milk'));
```
`Dispatch method` takes class and based on class name looks for Message Handler that can handle that.
> Symfony Messenger does not provide Point to Point channels by default, as you may subscribe for single Message from multiple Message Handlers.
> However Messenger allows for defining own Buses that can be set up to achieve that.
### How messages are routed by routing keys?
There is no possibility to route Message using routing keys.
This comes from the design, as Message expects an actual class as payload, and based on the given class we know where it’s supposed to be routed.
### How the behaviour can be enriched?
Symfony Messenger comes with implementation of Middlewares.
Middlewares are connected to given bus and intercept message flow providing a possibility to add extra behaviour or changing the Message.
### How Messages are handled synchronously?
Whenever we send Message using Message Gateway (Bus), it’s handled synchronously by default.
### How Messages are handled asynchronously?
When we are sending Message using Message Gateway, Symfony adds special middleware `SendMessageMiddleware`.
This Middleware stop the flow and sends the Message to external Platform (Database, RabbitMQ, etc).
Then there is a Consumer that consumes the Message and run Message Gateway once more, however this time with `ReceivedStamp` which tell the Middleware to let the flow continue.
### How to pass Message Headers?
To construct Message with Headers we need to provide class for each header, that implement StampInterface.
> *You may access headers in Middleware, however there is no possibility to access headers inside Message Handler at this moment.*
### How to integrate different Applications?
There is not out of the box solution for this.
However you may share the configuration between two applications, where one application will publish the Message and the second will be running Consumer.
> Payload in Messenger is a Class, so it requires this class to be available on both ends in order to deserialize it correctly.
---
### Ecotone Framework
[Ecotone](https://github.com/ecotoneFramework/ecotone?ref=blog.ecotone.tech) from the ground is built around messaging concepts.
It provides implementation of Enterprise Integration Patterns and provides easy to work API that hides messaging details from application code.
Ecotone can be used with Symfony, Laravel or no extra framework at all.
> Ecotone has more similarities with Message Broker than with Task Queue.
### What is Message?
Message is a class, which contains of Payload and Headers.
> In Ecotone **Payload** can be anything PHP class or array, XML, JSON, simple string.
Ecotone follows principle that **you should not be forced to use framework specific classes**. Probably, you will never need to work with Ecotone’s implementation of Message directly.
### How Messages are send to the Message Handler?
Ecotone provides Message Gateway implementation. By default delivers 3 implementations: **CommandBus**, **EventBus** and **QueryBus**.
```
$commandBus->send(new PlaceOrder('milk'));
```
`Send method` takes class and based on class name looks for Message Handler that can handle that.
> CommandBus and QueryBus are backed by Point to Point channels, which means that they aim single Message Handler.
> EventBus on other hand provides publish subscribe solution, where multiple handlers can subscribe to one given Message.
### How messages are routed by routing keys?
You may send your Message using routing.
Your Command Handler will be connected to given Bus using routing key provided in Attribute.
> Ecotone will take Payload of the Message and based on type hint of Message Handler deserialize it to given class.
> You can also invoke Command Handler without any parameters just by using routing.
### How the behaviour can be enriched?
Ecotone provides concept of **Interceptors**.
It allows to enrich the behaviour for given Message Handler or group of them, at chosen moment of time.
You may intercept Message Flow before/after Handler execution or before Message is sent to asynchronous channel.
> You may also define your own Attributes to annotate your Message Handlers then you may target them for intercepting.
### How Messages are handled synchronously?
Whenever we send Message using Message Gateway (Bus), it’s handled synchronously by default.
### How Messages are handled asynchronously?
Ecotone allows replacing default synchronous channel that Message Handler is connected to with asynchronous one.
> Message Handler decides on it’s own, if it want to handle given Message in synchronous or asynchronous manner.
Instead of marking whole message to be handled asynchronously, Ecotone allows for marking specific Message Handler to run asynchronously.
This makes difference when there is more than one Message Handler subscribing to given Message, as it allows to decide which parts of the system should run asynchronously and which not.
> Each Message Handler receives it’s own copy of Message. This is game changer when we are running them asynchronously, as each Handler is handling his own message in isolation, so one failing Handler will not affect another one.
### How to pass Message Headers?
Ecotone provides possibility to inject Message Headers into your Message Handler and your Interceptors.
### How to integrate different Applications?
Ecotone provides possibility to integrate different applications together using RabbitMQ integration.
You may send Commands to achieve Point to Point integration by targeting given Application.
Besides that you may publish Events to achieve Publish and Subscribe, where multiple applications can subscribe to given Message.
> As Ecotone works with Symfony and Laravel and No Framework at all, you can use it to integrate any PHP Application.
---
### Laravel Queues
[Laravel Queues](https://laravel.com/docs/9.x/queues?ref=blog.ecotone.tech) allows you to easily create queued jobs that may be processed in the background to offload from your web requests intensive tasks.
> Laravel Queues has more similarities with Task Queue than with Message Broker.
### What is Message?
Laravel Queues introduces Job as a Message.
Message is a PHP Class, that is also a Message Handler.
Concept of headers does not exists.
### How Messages are send to the Message Handler?
Message is a Message Handler, so it executes itself in order do the work.
```
PlaceOrder::dispatch($order);
```
### How messages are routed by routing keys?
The design expects having access to given class in order to execute it, so there is no concept of routing by keys.
### How the behaviour can be enriched?
Laravel Queues provides possibility to register your Middlewares inside your Message.
Middleware must conform to given interface.
### How Messages are handled synchronously?
To dispatch in synchronous manner make use of `dispatchSync` method.
```
PlaceOrder::dispatchSync($order);
```
### How Messages are handled asynchronously?
Messages are handled asynchronously by default
> You may omit onQueue method, if you want to use default queue.
### How to pass Message Headers?
There is no concept of Message Headers.
### How to integrate different Applications?
Laravel Queues is a Task Queue like implementation, it was not designed for cross application communication.
### Summary
**Symfony Messenger** and **Ecotone** are built towards general message handling, that can be used to decouple the system, build message flows and offload the work.
**Laravel Queues** are mostly about offloading the work.
The most important is that each of the frameworks promotes working with messages and asynchronous processing. This pushes our PHP community forward :)
Learn more about Symfony Messenger [here](https://symfony.com/doc/current/messenger.html?ref=blog.ecotone.tech).
Learn more about Ecotone Framework [here](https://github.com/ecotoneframework/ecotone?ref=blog.ecotone.tech).
Learn more about Laravel Queues [here](https://laravel.com/docs/9.x/queues?ref=blog.ecotone.tech).
### Build Laravel Application using DDD and CQRS with Ecotone
URL: https://blog.ecotone.tech/build-laravel-application-using-ddd-and-cqrs/
Last updated: 2024-03-02T16:24:31.000Z
DDD becomes more and more popular in PHP World and there are a lot of discussions on [how to approach it](https://twitter.com/matthiasnoback/status/1516379161325187072?ref=blog.ecotone.tech).
In Laravel community it’s [getting momentum too](https://twitter.com/PovilasKorop/status/1517034905682812929?ref=blog.ecotone.tech).
Have you been wondering how can it be implemented in Laravel?
In this article I will explain basics of DDD building blocks and how can we use them in Laravel Application.
It’s not required, however I encourage you to take a look on previous blog about CQRS [“Going into CQRS with PHP”](https://blog.ecotone.tech/cqrs-in-php/) before starting.
### Eloquent ORM and DDD
In DDD we are using *Domain Models*, which are different from *Eloquent Models.*
Domain Models are clean from infrastructure and Framework related implementation, in order to have full control over modifications and extensions.
> Domain Models are meant to solve business related problems not technical ones.
> Thanks to that it’s easier to maintain and extend them.
If we decided to use Eloquent and mix it with Domain Model, then we’ve introduced database dependency.
However we did it for a reason, as we want to reap benefits that Eloquent integration brings.
> Fighting your own framework may bring higher complexity into the code base and make increase maintainability cost.
For building Domain Models without Eloquent there will be a separate blog post, in this one we will focus on, what we can achieve, if we decided to go hand in hand with Eloquent ORM.

### Aggregates
In DDD we build `Aggregates which are classes rich in behaviour`.
As an example let's take `Article`, which may be be `published`, however first need to be `approved` by the author.
This could be Eloquent Model, that we would store in database using `->save()` method.
It's important to expose actions (methods) on the Aggregate and make use it as the only way to modify the data.
Calling insert and updates SQLs directly on the database, may introduce incorrect data or bypass our constraints.
> If the only way to modify given aggregate is through his public methods and methods are protecting it’s own state inside, then we come the place where our models are always valid.
### Value Objects
The part of the model are Value Objects.
VO’s are classes that are immutable. They are wrappers for given types that needs validation.
*If we have Value Object like Email in system, then we can pass it around and be sure, it’s always valid one. This decrease amount of guard logic within the system.*
### Enable Ecotone with Laravel
To enable Ecotone with Laravel install:
```
composer require ecotone/laravel
```
For automatic serialization and deserialization:
```
composer require ecotone/jms-converter
```
### Eloquent Creating new Aggregate
We will implement `Issue` aggregate. Issues can be reported by our customers in case of system errors.
Let's start by defining `ReportIssue Command`.
In order to execute the `ReportIssue`, we need to call `Command Bus`.
What comes from `$request->all()` return data from `HTML Form` which is:
```
["email" => "johnybravo@gmail.com","content" => "My PC is not working"]
```
The `Email` inside the `ReportIssue` is Value Object Class, so we need to know how to convert from `string` to `Email` class. In order to do it we will register `Converter`.
> Ecotone JMS Converter package will handle all deserialization from Arrays / JSON / XML to PHP classes and other way around.
Let’s implement our Eloquent `Issue Aggregate`:
1. We mark our Model with `#[Aggregate]` so Ecotone can find it
2. We enable factory method under `"issue.report"` routing key.
3. As we want to publish event which contains `Id` we need to save `Issue` inside the factory method, so the identifier will be assigned
4. We publish `IssueWasReported` using `recordThat` method, which comes from `WithAggregateEvents` trait.
5. We need to expose public method with identifier for Ecotone `#[AggregateIdentifierMethod("id")]`
Now we can execute our `Controller we have defined previously to send Command and create new Issue`.
### Changing The Aggregate Issue
Now we can add possibility to close the Issue.
> There is no Command Class defined for Command Handler and that’s because we do not need any data in here. When needed Ecotone allows for seamless routing to given Handlers by routing name only.
Now we want to execute this Command Handler
The `metadata` part are extra information, that are not part of the Command itself.
Ecotone use it to pass around framework related information.
By passing `aggregate.id` we tell Ecotone which `Issue Aggregate it should execute`.
> You may use metadata to pass your own extra details that you would like to pass alongside with Command for example `User Id`.
### Event Handling
When `Issue` aggregate was reported we are publishing event:
We can register subscriber, that will send Email with confirmation to the customer after Issue was reported.
To `subscribe to specific Event we type hint given class as first parameter` (just like with Command Handler) and mark method with `#[EventHandler]`.
### Summary
`Ecotone Framework` is handling glue code and providing building blocks, so we can build applications quickly and in solid way.
It integrates with Laravel and Eloquent in way those Frameworks were designed.
And in case of need allow you to extend your application with new functionalities like [Event Sourcing](https://blog.ecotone.tech/implementing-event-sourcing-php-application-in-15-minutes/) and [Asynchronous communication](https://blog.ecotone.tech/asynchronous-php/).
If you want to run Demo Application with `Laravel and Ecotone` you can find it under [this repository](https://github.com/ecotoneframework/php-ddd-cqrs-event-sourcing-symfony-laravel-ecotone?ref=blog.ecotone.tech).
### Scheduling Execution in PHP
URL: https://blog.ecotone.tech/scheduling-execution-in-php/
Last updated: 2024-03-02T11:19:57.000Z
We often need to schedule the execution of given business functionality in our applications.
The timing depends on what we want to achieve. It may be monthly executed invoices or notifications sent after the user was registered on the website.
And in this article, we will deep into different ways of scheduling execution in PHP.
This article assumes basic knowledge about [Commands](https://blog.ecotone.tech/cqrs-in-php/) and [Events](https://blog.ecotone.tech/event-handling-in-php/).
### Scheduled Batch Job
The most common approach is scheduled batch jobs.
This is a process that rises at a specific hour, in most of the cases executes big database Query, fetches a large portion of data and execute related actions.
> In PHP world Scheduled Batch Jobs are mostly implemented by Cron Jobs, that executes process at given time.
Batches are pretty straightforward in implementation, access to database, iterate and execute.
What we could achieve by that?
- We could fetch all users that have registered within the last 15 minutes, to send them a welcome notification.
- We could fetch all the orders to recalculate company earning statistics.
- For a particular user we may have an agreement to invoice him at a given date, so we would look for overdue dates to generate it
### Scheduled Jobs Implementation
Having a system cron job often creates problems with tracking if something went wrong and requires running non-PHP process.
If this is problematic for you, Ecotone brings Scheduled Jobs into PHP.
### Scheduled Method
`EndpointId` in `#[Scheduled]` defines the name, that will be used to execute the process. `#[Poller]` defines how this method should be executed.
This method will be scheduled for execution every 10 seconds.
The process can be now run:
```
# Symfony
bin/console ecotone:run notificationSender -vvv
```
```
# Laravel
artisan ecotone:run notificationSender -vvv
```
```
# Lite
$messagingSystem->run("notificationSender");
```
### Scheduled Handler
You may also schedule execution of given `Command Handler`.
The first parameter of `#[Scheduled]` indicated routing to `Command Handler`.
In this case, we have set up Cron to execute every minute and call our Command Handler.
### Problems with Scheduled Batch Jobs
There may be moments in time when Scheduled Batch Jobs will become problematic.
- Batch Jobs often generate a huge load on database, which affects end-users of the system.
- What if the batch job will fail at midnight?
If we can catch it and notify, then users of the system are in luck, however, developers may have another sleepless night.
This becomes even more problematic if our script breaks in the middle of processing. As we need to recover from that and run the job only for part of the data, that was not yet processed.
- And what if we want to perform actions during the day?
We either need to increase the system resources or agree that it may affect end users during that time.
So there must be a better approach, right?
### Messaging
`Messaging architecture` provides us with a solid and stable platform to handle such problems.
It helps us in building applications that can scale and perform well on high loads.
So what is `Message`?
A message is a letter that can inform about a recent event that happened in the system or command an action that the system should perform.
With Messaging we are dealing with one message (a record) at a time and to keep the system stable, we can queue messages up and deal with them when we are ready.
This solves the problem of being overloaded and handling many records at a time. As we can just queue messages up and work on them one by one.
> Messaging provides more stability to the system as, if we fail we fail at specific Message, we can retry this message or put it for review and continue with processing other ones.
### Static Message Schedules
Suppose that we want to send a notification to newly registered user 5 minutes after registration.
After registration, we are publishing event `UserWasRegistered`.
Now we can handle this Event [asynchronously](https://docs.ecotone.tech/modelling/asynchronous-handling?ref=blog.ecotone.tech) and delay the execution.
`#[Delayed]` describes in milliseconds how long we want to delay the execution.
> Ecotone delivers copy of a message to each Event Handler. Thanks to that you may delay one Handler yet execute other one instantly
### Dynamic Message Schedules
In case we would like to dynamically decide, when a given process should be executed, we can define it when sending a message.
Suppose the user made an order and if he does a quick product shipping, we want to delay it for 3 days or otherwise 7 days.
And our `Command Handler`
> *We are using asynchronous to have storage for the message we send.*
> *We may for example back it by RabbitMQ or DBAL (Database).*
### Periodic Message Schedules
We may also want to do recurring actions, like invoicing. To perform given execution after given periods of time.
Let’s implement invoicing for a user.
After the user was registered, we will register the first attempt to generate the invoice.
When the invoice was generated, we will register another attempt with delay.
We are joining a new user to the flow after he registers.
In case the user would be blocked, then `generateInvoice` we could just do a return without publishing the event and the flow for a given user would simply end.
This will create a message flow, where we will keep generating the invoices for a given user at a time, till the moment when we will decide to stop it.
> If you put `#[Asynchronous]` attribute on top of the class, it will apply to all the `Handlers`.
### Summary
Ecotone brings a true Messaging Platform to PHP. It provides easy-to-follow tools to glue things together, in a solid and stable way.
Messaging is a powerful concept and once developers get used to that, it can save a lot of sleepless nights, especially in business-critical components.
You may read more about Ecotone [here](https://github.com/ecotoneframework/ecotone?ref=blog.ecotone.tech).
If you want to see the implementation of the following article using Ecotone Lite go [here](https://github.com/ecotoneframework/quickstart-examples/tree/master/Schedule/src?ref=blog.ecotone.tech).
### Implementing Event Sourcing PHP Application in 15 minutes
URL: https://blog.ecotone.tech/implementing-event-sourcing-php-application-in-15-minutes/
Last updated: 2024-03-02T11:19:58.000Z
In this post we will jump straight to the code and we will implement Event Sourcing Application in 15 minutes.
The only thing worth to read before starting is general idea of Event Sourcing from [previous post](https://medium.com/nerd-for-tech/starting-with-event-sourcing-in-php-161a83597d69?ref=blog.ecotone.tech).
There is no time to be wasted, so let’s start.
### 1st minute — Setting up project
1. Create empty catalog “App” and run “*composer init”* inside*.* Name the application “*ecotone/app”* and make use of defaults.
After processing we should have composer.json:
```
{
"name": "ecotone/app",
"autoload": {
"psr-4": {
"Ecotone\\App\\": "src/"
}
},
"require": {}
}
```
2\. Now let’s require Ecotone Lite package for Event Sourcing
```
composer require ecotone/lite-event-sourcing-starter
```
### 3rd minute — Implementation
We will create electronic Wallet, that will keep log of all transactions.
We will do In Memory implementation to not waste any time on database configuration.
> Ecotone is powered up by well tested and solid [Prooph Event Store](https://github.com/prooph/event-store?ref=blog.ecotone.tech) for storing Events.
> Besides In Memory implementation, we can switch to PostgreSQL/MySQL/MariaDB.
We will have three possible actions on Wallet:
1. Registering new Wallet
2. Adding money to Wallet
3. Subtracting money from Wallet
> Remember that we are in Event Sourcing world, so after performing action, we return Events.
> *If we want to rebuild the state from previous events in order to validate if given action can be performed, we can implement method like* onWalletWasRegistered*.*
Let’s see how our events looks like:
### 9th minute — Building Projection
So now we want to be able to answer question, what is the current amount of money on given wallet. To do it we will make use of projection, which subscribe to events and do the calculations.
Our projection recalculate the current wallet balance, whenever event happens.
It also expose possibility to query it by “*getWalletBalance”*.
### 13th minute — Running the example
We will now register the Wallet and then add 100 and subtract 40.
Our Projection should tell us after those events will happen, that the current amount is 60.
Create in the root of the project file called “*run\_example.php”*
Now, when we run it, the result will be 60.
### 15th minute — Summary
We have built Event Sourced Wallet.
Ecotone aims for straight forward configuration. We have only defined the classes that are needed for this functionality, the amount of configuration is minimal.
Thanks to that we can quickly implement new functionalities and keep our code clean.
If you want to follow on Ecotone Framework [go here](https://github.com/ecotoneframework/ecotone?ref=blog.ecotone.tech).
If you want to see above implementation go to [this repository](https://github.com/dgafka/php-event-sourcing-application-in-15-minutes?ref=blog.ecotone.tech).
### Starting with Microservices in PHP
URL: https://blog.ecotone.tech/how-to-integrate-microservices-in-php/
Last updated: 2024-03-02T16:25:20.000Z
This is follow up on “[How To Integrate Microservices](https://dariuszgafka.medium.com/how-to-integrate-microservices-a506fe2d1a48?ref=blog.ecotone.tech)” post.
Feel encouraged to read the previous article first.
In this article, we will take theory and apply it in practice using PHP.
We will use [Ecotone Framework](https://github.com/ecotoneFramework/ecotone?ref=blog.ecotone.tech) and [RabbitMQ](https://www.rabbitmq.com/?ref=blog.ecotone.tech), to integrate two Services together.
---
### Implementing Messaging in PHP
Before we start, we need to enable [RabbitMQ Module](https://docs.ecotone.tech/modules/amqp-support-rabbitmq?ref=blog.ecotone.tech#configuration) for used [framework](https://docs.ecotone.tech/install-php-service-bus?ref=blog.ecotone.tech) (Symfony/Laravel/Lite).
We will build two Services.
Service which will be consuming messages we will call “order\_service” and Service that will publish them, *“my\_service”*.
The naming is important and we need to [set up Service Name in configuration](https://docs.ecotone.tech/messaging/service-application-configuration?ref=blog.ecotone.tech#ecotone-core-configuration).
In the “*Order Service*” we will enable Consumer to consumes messages coming from other Microservices.
In “*My Service*” we will enable Distributed Bus, that will allow us to send events and commands to other Microservices.
### Sending Command to Order Service
Let’s start by defining [Command Handler](https://blog.ecotone.tech/cqrs-in-php/) in *Order Service*.
The Command Handler is available under *“placeOrder”* routing key.
We may now send the command from *My Service* using Distributed Bus to place the order:
1. Service Name that Command should be sent to
2. Routing to Command Handler inside *Order Service*
3. Data to be sent (payload of Command)
4. And optional content type of the data
After executing this code, Command Message will be delivered to *Order Service*.
*Order Service* may consume it now by running:
```
(bin/console|artisan) ecotone:run order_service -vvv
```
### Publishing Event
Suppose that we want to cancel all orders of the user in case his account was banned.
*My Service* will publish event about user being banned and *Order Service* will subscribe to this event.
The Event Handler will now subscribe to Event published with routing key “*user.was\_banned*”.
1. Name of the Event (routing key)
2. Data to be sent (payload of Event)
3. Optional content type of the payload
After executing this code, Event Message will be delivered to *Order Service*.
*Order Service* may consume it now by running:
```
(bin/console|artisan) ecotone:run order_service -vvv
```
### Going into more details…

### Ways of Routing
```
#[Distributed]
#[CommandHandler("placeOrder")]
public function placeOrder(PlaceOrderCommand $command): void
```
We are using *“placeOrder” routing name* to route the Command to specific Handler.
```
$this->distributedBus->sendCommand("order_service","placeOrder",...)
```
You could meet with solutions where routing is based on the Class Name or require sharing actual class implementations between Services.
Sharing PHP Classes between Services makes them become public API.
We can’t anymore simply change the class name, as it will break other Services.
The class becomes hard to change, as modifications now involve other parties.
The second option would be to agree on non PHP, Public API.
We could take JSON Schema instead of PHP Class and do the routing based on custom name like *“placeOrder”, just as we did in above example*.
> Ecotone is flexible and adjust to your needs.
> If coupling Services by sharing classes is fine in your context, then you may do it.
> If you want to decouple Services you may use custom names.
### Using Classes with Custom Routing
Even so, that we have used Custom Routing we are still expecting PlaceOrderCommand class.
```
#[Distributed]
#[CommandHandler("placeOrder")]
public function placeOrder(PlaceOrderCommand $command): void
```
Based on the routing Ecotone knows which Handlers it should execute and based on the method declaration which class it should deserialize to.
All you need to do it to register [Media Type Converter](https://docs.ecotone.tech/messaging/conversion/conversion?ref=blog.ecotone.tech) so Ecotone knows how to deserialize given Content Type to PHP Class.
> You could also type hint for string to get JSON or type hint for array, if you would like to work with simple types.
> You could also have no arguments at all and execute the Handler based on routing name only.
### Sending/Publishing Classes
If you have your [Media Type Converter](https://docs.ecotone.tech/messaging/conversion/conversion?ref=blog.ecotone.tech) registered on the Publisher side, then you may send Command and Event classes.
Ecotone will take care of serialization before sending it to RabbitMQ.
### Passing Metadata
There will be cases, when you will want to enrich the Message with some Metadata.
You can for example publish Event and add Person Id of currently logged user.
If we will put it in the payload it can easily blur the event, especially that there may be more meta data to store.
Message is like letter and letter contains Headers (Metadata).
Ecotone comes with solution that allows us to add and send Metadata with Commands and Events in straight forward way.
Suppose we have Audit Service, that stores the information about who banned the user.
or, if you want to be more specific, you can pass specific Header directly
### Delivery Guarantees
There may be situations, when you will want to send more than one Message at time.
If for any reason before sending or during sending second Command our code will fail,
then we may end up in situation, where only first Command went out.
This would would create inconsistency between Services.
If you’re using local [Command](https://docs.ecotone.tech/modelling/command-handling/external-command-handlers?ref=blog.ecotone.tech)/[Event](https://docs.ecotone.tech/modelling/event-handling/handling-events?ref=blog.ecotone.tech) Handlers, Ecotone on default wraps those handlers in RabbitMQ Transactions.
This guarantees, that you all messages will be sent together at the end of the successful flow.
### Handling Great Amount Of Messages
If we will sent a lot of messages, then we will want to target Message only to the Services that can handle specific Message to avoid unnecessary load on the system.
> Ecotone sends events only to the Services that are subscribing to it.
> Commands are sends only to specific targeted Services.
### Handling Error Messages
There may be situations, when Event or Command Handler will fail.
In that case RabbitMQ will try to redeliver the message, till the moment it will be successful. During that time other messages will be blocked.
Ecotone comes [with solution](https://docs.ecotone.tech/modelling/asynchronous-handling?ref=blog.ecotone.tech#handling-error-messages), that allows you to set up retries with delays.
So in case message will fail, we can retry it after X minutes, during that time other messages will be unblocked.
After defined amount of retries, you may store Error Message in [Dead Letter](https://docs.ecotone.tech/modules/dbal-support?ref=blog.ecotone.tech#dead-letter) (database) for further investigation.
### Summary
Ecotone provides rich support for building Microservices.
As it’s built around Messaging Concepts from the ground, all the tools are just natural extensions.
Messaging provides stable ground that help jump over a lot of complications that distributed architecture brings into existence.
The aim of Ecotone is to provide developers with solid tools that are powerful, yet easy to use.
If you want to see demo implementation of Microservices Integration in Ecotone Lite, you [can check it here](https://github.com/ecotoneframework/quickstart-examples/tree/master/Microservices?ref=blog.ecotone.tech).
To follow up on Ecotone Framework [go here](https://github.com/ecotoneFramework/ecotone?ref=blog.ecotone.tech).
### How To Integrate Microservices
URL: https://blog.ecotone.tech/how-to-integrate-microservices/
Last updated: 2024-03-02T11:20:01.000Z
In order to know *how*, we first need to ask question, *why* do we integrate Services.
We integrate Services as we want to access external data:
*“Fetch current wallet balance”*
Or because we want to Command other Service to do action:
*“Transfer money to electronic wallet”*
Other Services may also take action on their own, when specific Event happens:
*“When Person Account Was Banned, block his electronic wallet”*
Command and Events produces Actions in the system, which result in data change or side effects (like sending email/sms).
Queries on other side are only to fetch the data, they do not change the state of the Service anyhow.
It’s important to distinguish Queries from Actions (Command and Events), and not mix them together. We will see way does it matter just in a minute.
---
### Integrate Services over HTTP
The first possibility to integrate is using HTTP. We are making HTTP Request to specific endpoint and we get the Response.
HTTP power lies in getting the feedback (Response) right away.
However HTTP Integration has few drawbacks:
- We need to depend on Service being up and running. In case service is down, we are unable to call it
- Service may be overloaded or simply working slowly, which may creates latency issues on our side
- It creates coupling between Services
Even considering above problems, possibility to get the response right away makes it good fit for Query Integration.
> On other hand, HTTP integration for Actions may create inconsistencies in the system.
Suppose that after registering user we call another Service to send email.
What will happen, when the Service is down?
We will not be able to call, and due to that we create series of things that need to be solved:
\- If we want to keep registration, we will need to silent the error.
\- *I*f we want to send the email anyway, we will need to store failed data so we can retry it
\- *W*e will need retry mechanism with delays, as the Service may be up and running in 10 seconds or 20 minutes.
Suppose another scenario where we call another Service in order to subtract money from the wallet and the request times out.
What does this mean for us?
Well we can’t really know, because Service could performed the Action, but also could not.
If the system does not provide some kind of deduplication mechanism, if we will resend the request, we may subtract the money twice.
And, if we don’t we may end in situation, where money was not subtracted at all.
Well not really a good situation to be in, right? :)
> HTTP is good fit for Queries, however for handling Actions there is more robust solution, Messaging.
---
### Integrate Services over Messaging

The Messaging is like Postman, and we are like clients sending letters (Messages).
The letter contains headers and content (In Messaging we call content — Payload).
We are providing letters to Postman, and Postman delivers them to the recipient’s box.
When the recipient is ready, he takes the letter out of the box, reads the headers and content and performs the Action.
To push it to the programming level, the Postman can be [RabbitMQ](https://www.rabbitmq.com/?ref=blog.ecotone.tech), we connect to it to provide Message to deliver. RabbitMQ knows how to deliver it to the given box (Queue).
When it ends up in Recipient’s queue, he may *consume* it in the best moment for him.
Let’s check how does Messaging solves HTTP drawbacks:
- HTTP Problem #1: We need to depend on Service being up and running. In case service is down, we are unable to call it
We give the letter to Postman and recipient take it out of the box, whenever he is ready.
This allows us to send letter stating “send sms to X” to Notification Service (Recipient) even if this Service is down.
When the Service will get up, he will pick the letters perform the actions.
> With Messaging we become independent of the state of Services around
- HTTP Problem #2: Service may be overloaded or simply working slowly, which creates latency issues for our side
When we call the Service over HTTP we are in request-response model.
This model creates latency, as we are waiting for the response to be received.
> In Messaging, we are in fire-and-forget model. This means we only connect to the Postman (Message Broker) to send a message and the flow continues, no matter of the current Recipient’s state.
> This set us free from the response times of other services.
- HTTP Problem #3: Coupling with other Services
If the client is registered in our system, we may want to do several actions in other services.
Like creating a wallet in Wallet Service, sending an Email using Notification Service.
If we integrate over HTTP, we will need to call those Services in order to inform them about new registration. This of course brings all HTTP drawbacks, multiplied by the number of Services we call.
In the case of Messaging, we only integrate with Postman.
We would publish Event Message using Postman and any Service that is interested may subscribe to it.
Recipients may join and disconnect from subscriptions, whenever they wish. The Postman will take care of delivering the message to all subscribing Services.
> Messaging creates decoupled solution, where each Service may be in control of what they want to know (subscribe to).
---
### Actions as Commands or Events
In Messaging everything we send is a Message, however, we may distinguish two types of Messages depending on how we want to use them.
> Commands are way to send Message to concrete Service in order to perform action.
For example, when we send Command to Notification Service stating “Send Email To Johny Bravo”, we expect it to be delivered only to this Service, as other Services may not provide such action.
> Events are way to publish Message, so Services that are interested can subscribe to it.
For example, we may publish Event stating “Order Was Placed”.
We do not say it to any concrete Service, we are just stating the fact of what just happened.
And any Service that it willing to take action based on that fact, may subscribe to it.
---
### Summary
In Messaging we don’t depend on availability of the other Service, so it’s hard to expect the response. This creates nice decoupling, however makes Messaging hard to use for Queries.
> Messaging is great for Actions, as it’s reliable and stable. It help us keep the consistency between Services.
In next article we will see how to apply this theory in practice using PHP and [Ecotone Framework](https://github.com/ecotoneFramework/ecotone?ref=blog.ecotone.tech).
[Click here to go to next article.](https://dariuszgafka.medium.com/starting-with-microservices-in-php-6e3c411f3d27?ref=blog.ecotone.tech)
### Build Your Symfony Applications with ease using Ecotone
URL: https://blog.ecotone.tech/build-symfony-application-with-ease-using-ecotone/
Last updated: 2024-03-02T16:26:12.000Z
### Build Your Symfony and Doctrine ORM Applications with ease using Ecotone
In this article we will be pushing refactor of our Symfony Application to the boundaries.
We will focus on dropping boilerplate completely so we can write only the code that matters, allowing us for easy modifications, maintenance and future extensions.
We will start with example functionality, which we will be refactoring step by step by extending our Symfony application with Ecotone.
Prepare a good coffee or tea and enjoy the ride :)
### Starting point
Our application will be having two functionalities:- Registering new user- Activating the user after the registration was done
Our *UsersApiController* receiving Request and calls *UserService* to register new user.
Our UserService, begins transaction and stores entity using Entity Manager.
And this is how our *User* looks like.
Before we start, let’s install Ecotone for Symfony:
> *composer require* [*ecotone/*](https://packagist.org/packages/ecotone/?ref=blog.ecotone.tech)*symfony-bundle*
### Drop redundant transaction management
What hurts eyes is the transaction management. We are doing it for each of the action (*registerUser*, *activateUser*) and the future actions will also need it. Let’s remove the boilerplate and place it one place.
To make it we will build a pipeline, where before running any action, we will be handling the transaction.

Let’s first start by registering our actions as [Command Handlers](https://blog.ecotone.tech/cqrs-in-php/). This will allow us to intercept their execution by wrapping it in transaction.
> *If you are familiar with Symfony Messenger, you know the concept of Message Handler.*
> *A Command Handler is higher level concept and describes Message Handler which is responsible for actions that change the data or provide side effects (e.g. sending email).*
To execute the command handlers, we need to replace our *UserService* with *CommandBus* in the *Controller*.
$this->commandBus->sendWithRouting("registerUser", $name);
This execute Command Handler registered under name *“registerUser”.* The second argument is payload, which will be passed as *first argument* to our Handler.
> *In this example, payload is actually a single parameter. We could easily provide array or object. Ecotone allows you to choose freely, depending on your preferences and needs.*
Let’s wrap our command handlers in transaction now:
#\[Around(pointcut: CommandHandler::class)\]
public function transactional(MethodInvocation $methodInvocation)
Around is [interceptor](https://docs.ecotone.tech/modelling/interceptors?ref=blog.ecotone.tech) that allows us to add logic before and after execution of the Handler is performed. This is great for things like Transactions.
*Pointcut* tells what do we want to intercept. In this scenario, we have intercepted all Command Handlers.
For proceeding with the Command Handler invocation we use *$methodInvocation->proceed();*
### Pushing to the limits
Let’s compare activate method with new deactivate method.
If you look closely you will see boilerplate code:/\*\* @var User $user \*/
$user = $this->entityManager->find(User::class, $id);// Run some action on the user$this->entityManager->persist($user);
In order to fetch the user and persist the changes, we need to create separate class and method and all what we want to do is to execute method on the user.
Wouldn’t it be easier, if we could call the Entity’s method directly?
Lucky Ecotone solves this, as we are allowed to mark Entities as Command Handlers.
To get support for Doctrine ORM, we will install [Ecotone Dbal](https://docs.ecotone.tech/modules/dbal-support?ref=blog.ecotone.tech):# install ecotone/dbal:
composer require ecotone/dbal
\# Add in services.yaml, so Ecotone can discover database connection:
Enqueue\\Dbal\\DbalConnectionFactory:
factory: \['Ecotone\\Dbal\\DbalConnection','createForManagerRegistry'\]
arguments: \[ "@doctrine","default" \]
> *If you install* [*ecotone/dbal*](https://docs.ecotone.tech/modules/dbal-support?ref=blog.ecotone.tech)*, transaction management will be handled by default.You can remove TransactionWrapper.*
And we need to enable Doctrine ORM Repositories for Ecotone:
Right now we are ready to mark our User Entity with Command Handlers:
1. In Ecotone we are calling Entity as *#\[Aggregate\]*
2. Just like with Doctrine ORM, we need to mark identifier *#\[AggregateIdentifier\]*
3. And we mark methods as Command Handlers: *#\[CommandHandler(“activateUser”)\]*
The only change we need to make in Controller is to tell activate method Entity’s identifier:
```
$this->commandBus->sendWithRouting("activateUser", $id, metadata: ["aggregate.id" => $id]);
```
### Summary
We have dropped all of boilerplate code, leaving only the business logic code in our application.
Now we can produce new functionalities with minimum amount of code and things to test.
All the glue code was moved to Ecotone and Symfony, letting us focus on what matters.
If you want to get more information about framework, visit main [Ecotone Github](https://github.com/ecotoneframework/ecotone?ref=blog.ecotone.tech).
If you want to see implementation of things described in this post, visit [Example Application](https://github.com/ecotoneframework/php-ddd-cqrs-event-sourcing-symfony-ecotone?ref=blog.ecotone.tech).
### Make Your PHP Domain Speak the Business Language
URL: https://blog.ecotone.tech/how-to-build-maintainable-php-applications/
Last updated: 2026-05-15T14:57:59.000Z
*Updated on 2026-05-17*
A new developer joins your team. They open `OrderService.php` as their first task. The class extends `AbstractMessageHandler`, implements `QueueAwareInterface`, has half a dozen `use Symfony\Component\...` statements, and the actual business logic — the part that says “you can’t ship an order that wasn’t paid for” — is on line 84 of a 200-line file. Twenty minutes in, they’ve learned a lot about your framework and almost nothing about your business. **That’s the cost of letting the framework speak louder than the domain.**
**The short version.** Maintainable PHP isn’t about avoiding refactors — AI assistants make framework upgrades and renames trivial in 2026\. It’s about code that says what the business does, in the language of the business, with as little framework noise as possible. PHP attributes get you there: the framework reads them and wires everything up, but the domain class itself stays free of framework imports. The result is code a human reads as fast as a machine.
---
## What framework noise actually costs
Framework coupling used to be expensive because upgrades broke things. With modern AI tooling, that cost has collapsed — rename a class across a 50k-line codebase in seconds. The cost that hasn’t changed is **cognitive**:
- **Onboarding tax.** Every framework concept in your domain is a concept the next reader has to learn before they can read your business logic.
- **Bugs hidden under boilerplate.** When the business rule is line 84 of a method that started with 80 lines of framework wiring, reviewers and AI both miss it.
- **Wrong things look right.** A class that extends `AbstractController` looks like every other controller — even when it’s actually doing domain work that doesn’t belong in HTTP-tier code.
- **Slow code review.** Reviewers have to mentally subtract the framework noise to see what changed semantically.
None of these are caught by tests. None are caught by AI. They’re paid every time a human reads the code — which is roughly 10x more often than the code is written.
---
## The principle — framework reads your code, your code doesn’t read the framework
The cleanest indicator that a class speaks the domain rather than the framework: **it has no `use` statement importing the framework**. PHP attributes make this possible because attributes are *read* by the framework but don’t have to be *imported* by the class declaring them — they live in their own namespace.
Compare two ways to register a message handler. First, the framework-coupled version:
```php
use Symfony\Component\Messenger\Handler\MessageHandlerInterface;
final class OrderHandler implements MessageHandlerInterface
{
public function __invoke(PlaceOrder $command): void
{
// ...
}
}
```
*The class header tells you about Messenger. It tells you nothing about orders.*
Now the attribute version:
```php
final class OrderHandler
{
#[CommandHandler]
public function place(PlaceOrder $command): void
{
// ...
}
}
```
*The class is about placing orders. The attribute is metadata the framework reads at boot — it’s a hint, not a base class.*
The second version reads as a sentence: “OrderHandler can place a PlaceOrder command.” The first reads as: “OrderHandler is a Symfony Messenger MessageHandlerInterface that invokes itself with a PlaceOrder.” Same behaviour, completely different cognitive shape.
---
## The proof — the domain becomes portable as a side effect
When the domain stops importing the framework, something useful happens for free: the same code runs anywhere. Here’s a state-stored aggregate written once:
```php
#[Aggregate]
final class Order
{
public function __construct(
#[Identifier] private string $id,
private OrderStatus $status,
) {}
#[CommandHandler]
public static function place(PlaceOrder $command): self
{
return new self($command->orderId, OrderStatus::Placed);
}
#[CommandHandler]
public function ship(ShipOrder $command): void
{
if ($this->status !== OrderStatus::Placed) {
throw new \DomainException("Cannot ship an order that wasn’t placed");
}
$this->status = OrderStatus::Shipped;
}
}
```
*Read it top to bottom. The whole file is about orders — placement, shipment, the rule about needing to be placed first.*
The receipt for “the domain reads as the business” is that the file is byte-identical whether you run it on Symfony, Laravel, or standalone:
```bash
composer require ecotone/symfony-bundle # Symfony
composer require ecotone/laravel # Laravel
composer require ecotone/lite-application # Standalone / lambda / worker
```
That’s not the goal — portability is a *consequence*. The goal is the file itself: it says what an Order is and what can be done with it, with no framework getting in the way of that statement.
---
## What still belongs in the framework
This isn’t an argument against frameworks — the framework still owns the parts that aren’t domain logic:
- **HTTP — controllers, routing, request/response.** Symfony controllers and Laravel routes live where the framework expects them.
- **Console — CLI command parsing, IO.** Same.
- **DI — service definitions, autowiring.** The framework’s container reads your domain attributes and wires everything up.
- **Persistence transports — Doctrine, Eloquent, SQL builders.** But the domain shouldn’t extend these — it should be persisted *by* them via repository patterns.
The dividing line is the one PHP file: a controller is allowed to import Symfony or Laravel; a domain aggregate is not. Inside the domain, the only language is the business’s.
---
## Common questions
### Doesn’t this require an extra layer of abstraction?
The opposite. The attribute-driven approach has *fewer* layers than implementing framework interfaces — no adapter classes, no factory wrappers, no double-typing. The framework reads attributes and dispatches directly. There’s no layer in between.
### How do I handle stuff like database transactions then?
Cross-cutting concerns like transactions, retries, and logging live in interceptors registered with the framework — not in the domain code. The handler stays clean; the interceptor wraps it.
### How does this work with AI-assisted coding?
It works *better*. AI assistants generate cleaner output when the surrounding code reads as a sentence rather than a tangle of framework conventions. A domain class that says “Order can be placed and shipped” gives the assistant unambiguous context; one that mixes `extends AbstractMessageHandler implements TraceableInterface` with the actual rule forces the model to guess what part is business intent.
---
## Wrapping up
The longest-lived production PHP codebases share one trait: their domain files read like the business they support. Not because someone enforced “clean code” with a ruler, but because every framework concept that crept into the domain was an obstacle to the next person reading the file. **Make your PHP domain speak the business language** — everything else is implementation detail.
Companion reads: [CQRS in PHP — Stop Mixing Reads and Writes](https://blog.ecotone.tech/cqrs-in-php/) for the read/write split that makes domain intent easier to express, and [Enterprise PHP in 2026: The Patterns You’re Missing](https://blog.ecotone.tech/meet-ecotone-enterprise-ready-framework-for-php/) for the bigger picture.
---
*Dariusz Gafka is a Software Architect and author of the [Ecotone Framework](https://github.com/ecotoneframework/ecotone?ref=blog.ecotone.tech). He writes about event sourcing, CQRS, and message-driven PHP architecture.*
### Starting with Event Sourcing in PHP
URL: https://blog.ecotone.tech/starting-with-event-sourcing-in-php/
Last updated: 2026-05-15T15:01:53.000Z
*Updated on 2026-05-17*
A customer claims they bought a product for €79 last March, but your `products` table currently shows €89 with one row per product. **You can’t answer their question** — the price *now* is all you have. The audit log shows when the row was updated, not what the actual price was at the moment of purchase. That gap is the one event sourcing closes by design.
**The short version.** Event sourcing stores state as a sequence of events (“PriceWasChanged from €89 to €79”), not as the latest row. To know the state at any moment, replay the events up to that moment. To answer queries fast, project events into a denormalised read model. Ecotone has native event sourcing built-in, with the same attribute-driven API as the rest of the framework.
---
## State as a stream — not a row
Here’s the standard mutable model:
```php
final class Product
{
public function __construct(
private string $id,
private int $priceCents,
) {}
public function changePrice(int $newPriceCents): void
{
$this->priceCents = $newPriceCents; // history lost
}
}
```
*Standard CRUD: the previous price is overwritten and gone.*
The event-sourced version doesn’t mutate state — it records what happened:
```php
#[EventSourcingAggregate]
final class Product
{
private string $id;
private int $priceCents;
#[CommandHandler]
public static function create(CreateProduct $command): array
{
return [new ProductWasCreated($command->id, $command->priceCents)];
}
#[CommandHandler]
public function changePrice(ChangePrice $command): array
{
return [new PriceWasChanged($this->id, $this->priceCents, $command->newPriceCents)];
}
#[EventSourcingHandler]
public function applyCreated(ProductWasCreated $event): void
{
$this->id = $event->productId;
$this->priceCents = $event->priceCents;
}
#[EventSourcingHandler]
public function applyPriceChanged(PriceWasChanged $event): void
{
$this->priceCents = $event->newPriceCents;
}
}
```
*Command handlers return events; event-sourcing handlers apply them. Ecotone persists the events to the event store and rebuilds state by replaying them.*
Two things to notice. The command handler **doesn’t change state directly** — it returns an event. The event-sourcing handler is what mutates the in-memory state, and it’s also what runs during replay when Ecotone rebuilds the aggregate from history. The same event type goes through the same code whether it’s being recorded for the first time or replayed five years later.
---
## Projections — answering questions fast
Replaying every event for every read would be slow. **Projections** denormalise events into read models optimised for the queries you actually run:
```php
#[ProjectionV2("price_history")]
#[FromAggregateStream(Product::class)]
final class PriceHistoryProjection
{
#[EventHandler]
public function whenChanged(PriceWasChanged $event, Connection $db): void
{
$db->insert("price_history", [
"product_id" => $event->productId,
"old_price" => $event->oldPriceCents,
"new_price" => $event->newPriceCents,
"changed_at" => (new \DateTimeImmutable())->format("c"),
]);
}
#[QueryHandler("product.priceAt")]
public function priceAt(string $productId, \DateTimeImmutable $at, Connection $db): int
{
return (int) $db->fetchOne(
"SELECT new_price FROM price_history
WHERE product_id = ? AND changed_at <= ?
ORDER BY changed_at DESC LIMIT 1",
[$productId, $at->format("c")]
);
}
}
```
*The projection writes one row per price change. The query reads the most recent change before the requested timestamp — answering “what was the price last March?” in one indexed lookup.*
Projections are **derived state**: drop the table and replay, and you get the same data back. That’s the contract that makes event sourcing safe to evolve — you can change the projection logic, replay, and the read model rebuilds itself.
For the deep-dive on rebuilds, blue-green projection deployments, and partitioning, see [Your Projections Will Fail — Make Them Resilient](https://blog.ecotone.tech/your-projections-will-fail-make-them-resilient/).
---
## Sending the command, reading the projection
```php
$commandBus->send(new CreateProduct($id, 8900));
$commandBus->send(new ChangePrice($id, 7900));
// later...
$priceLastMarch = $queryBus->sendWithRouting(
"product.priceAt",
[$id, new \DateTimeImmutable("2026-03-15")]
);
```
*The command bus and query bus are auto-registered — just inject them where you need them.*
---
## What you get for free
Beyond the basic aggregate + projection pair, Ecotone’s native event sourcing ships with:
- **Snapshots** — for aggregates with thousands of events, snapshot the latest state to skip replay from zero. [Snapshotting docs](https://docs.ecotone.tech/modelling/event-sourcing/event-sourcing-introduction/persistence-strategy/snapshoting?ref=blog.ecotone.tech).
- **Event versioning / upcasting** — rename fields or split events without breaking historic data.
- **Gap detection** — projections can detect missing events and recover.
- **Backfill + rebuild** — populate a new projection from historic events without downtime. [Backfill docs](https://docs.ecotone.tech/modelling/event-sourcing/setting-up-projections/backfill-and-rebuild?ref=blog.ecotone.tech).
- **Multi-tenant streams** — one event store, isolated streams per tenant.
- **EcotoneLite testing** — aggregate and projection tests in-memory, deterministic, no event store setup needed.
---
## Symfony, Laravel, or standalone — same code
```bash
# Symfony
composer require ecotone/symfony-bundle ecotone/event-sourcing
# Laravel
composer require ecotone/laravel ecotone/event-sourcing
# Standalone
composer require ecotone/lite-application ecotone/event-sourcing
```
*Native event sourcing, three install paths. Same aggregates and projections run unchanged on either stack.*
---
## Common questions
### Do I need event sourcing for everything?
No. Event sourcing earns its keep where history matters — financial ledgers, audit-heavy domains, anything where “what was true at time X” is a real question. For CRUD-shaped domains, state-stored aggregates are simpler. Ecotone supports both side by side.
### Where are events stored?
Ecotone’s event store sits on top of your existing database — PostgreSQL, MySQL, or MariaDB through Doctrine DBAL. No separate database to operate; the events live in the same connection as the rest of your data, so backups and migrations stay simple.
### How do I test event-sourced aggregates?
`EcotoneLite::bootstrapFlowTesting()` with the aggregate registered. Send commands, assert recorded events. No event store, no database. Tests run in <100ms.
---
## Wrapping up
Event sourcing isn’t a silver bullet, but for any domain where “what happened?” is a real question, it’s the only model that gives you a complete answer. The setup cost in 2026 PHP is one composer require and one attribute on your aggregate. Companion reads: [CQRS in PHP](https://blog.ecotone.tech/cqrs-in-php/) for the read/write split that event sourcing builds on, and [Event Handling in PHP](https://blog.ecotone.tech/event-handling-in-php/) for the synchronous publish-subscribe pattern.
Full surface in the [Ecotone event sourcing docs](https://docs.ecotone.tech/modelling/event-sourcing?ref=blog.ecotone.tech); runnable example at the [quickstart repo](https://github.com/ecotoneframework/quickstart-examples/tree/master/EventSourcing?ref=blog.ecotone.tech).
---
*Dariusz Gafka is a Software Architect and author of the [Ecotone Framework](https://github.com/ecotoneframework/ecotone?ref=blog.ecotone.tech). He writes about event sourcing, CQRS, and message-driven PHP architecture.*
### Async PHP Done Right — Per-Handler Channels
URL: https://blog.ecotone.tech/asynchronous-php/
Last updated: 2026-05-15T15:02:11.000Z
*Updated on 2026-05-17*
Your PHP registration endpoint takes 4 seconds. You profile it: 3.6 of those seconds are spent waiting for SendGrid to acknowledge the welcome email. The user’s account is created on line 1; everything after is them watching a spinner because SMTP is slow today. The fix isn’t a faster mail provider — it’s **moving the email out of the request thread entirely**. That’s what async PHP is for.
**The short version.** Async in PHP doesn’t have to mean a separate queue worker library, a Symfony Messenger config tree, or a custom job class hierarchy. Mark a handler with one attribute, point it at a channel (in-memory, database, RabbitMQ, SQS), and Ecotone runs it off the request thread — with per-handler retry policies, transactional outbox if you want it, and the same code on Symfony, Laravel, or standalone PHP.
---
## The pain — everything in one request
The classic synchronous registration looks fine until something downstream is slow:
```php
final class UserService
{
#[CommandHandler]
public function register(RegisterUser $command): void
{
$user = new User($command->email);
$this->users->save($user);
$this->mailer->sendWelcome($user); // 3.6s on a bad day
$this->crm->syncContact($user); // could be down entirely
$this->analytics->trackSignup($user); // 200ms, every time
}
}
```
*The user waits for every downstream call. If the CRM is down, registration fails — even though the user row was already saved.*
Three problems compound here. **Latency**: the user waits for the slowest hop. **Failure cascade**: one downstream timeout fails the whole request. **Inconsistent state**: rolling back the database undoes the registration, but if the email already went out, the user got a welcome message for an account that no longer exists.
---
## The fix — one attribute, one channel
The first three sub-flows are *independent* of the request — they need to happen, but not in front of the user. Move them onto event handlers and mark each one async:
```php
final class UserService
{
#[CommandHandler]
public function register(RegisterUser $command, EventBus $events): void
{
$user = new User($command->email);
$this->users->save($user);
$events->publish(new UserWasRegistered($user->id(), $command->email));
}
}
#[Asynchronous("notifications")]
#[EventHandler(endpointId: "welcome.mail")]
public function sendWelcome(UserWasRegistered $event, Mailer $mailer): void
{
$mailer->sendWelcome($event->email);
}
```
*The request returns as soon as the user row is committed and the event is enqueued. The mail handler runs on a separate worker.*
To enable a channel, register it once in a `ServiceContext`:
```php
final class MessagingConfiguration
{
#[ServiceContext]
public function notifications()
{
return AmqpBackedMessageChannelBuilder::create("notifications");
}
}
```
Then run the consumer:
```bash
# Symfony
bin/console ecotone:run notifications -vvv
# Laravel
php artisan ecotone:run notifications -vvv
```
*Same command, two stacks. The consumer auto-registers from the channel name.*
---
## Per-handler isolation — the bit that matters in production
If you mark *three* handlers async on the same event and the second one fails, what happens to the other two? In Symfony Messenger, all three live in the same envelope — a retry re-runs all three (and re-sends the welcome email). In Laravel queues, they’re separate jobs but share queue-level configuration.
Ecotone publishes a **separate copy** of the event to each handler’s own channel. Failures, retries, and dead-lettering are *per-handler*:
```php
#[Asynchronous("notifications")]
#[EventHandler(endpointId: "welcome.mail")]
public function sendWelcome(UserWasRegistered $event, Mailer $mailer): void { /* ... */ }
#[Asynchronous("crm")]
#[EventHandler(endpointId: "crm.sync")]
public function syncCrm(UserWasRegistered $event, CrmClient $crm): void { /* ... */ }
#[Asynchronous("analytics")]
#[EventHandler(endpointId: "analytics.track")]
public function track(UserWasRegistered $event, Analytics $a): void { /* ... */ }
```
*Three handlers, three channels, three retry policies. The CRM handler can be down for an hour without affecting the welcome mail.*
---
## Outbox + RabbitMQ — never lose a message, never poll your DB
The risk with naive async is the **dual-write problem**: the request commits the user row, then publishes to RabbitMQ. If the broker is down between commit and publish, you have a user with no welcome email and no record of the missed event.
The textbook fix is the transactional outbox. Ecotone bundles it as a combined channel — commit the event into the database in the same transaction as the user row, then forward it to RabbitMQ:
```php
#[Asynchronous(["database_channel", "rabbit_channel"])]
#[EventHandler(endpointId: "welcome.mail")]
public function sendWelcome(UserWasRegistered $event, Mailer $mailer): void
{
$mailer->sendWelcome($event->email);
}
```
*Combined channels: the event is committed atomically with the user row into `database_channel`, then forwarded to `rabbit_channel` for the consumer to pick up.*
The event is **never lost** — even if RabbitMQ is down for hours — and downstream consumers scale on the broker, not on your database. For the deeper rationale, see [Implementing the Outbox Pattern in PHP](https://blog.ecotone.tech/implementing-outbox-pattern-in-php-symfony-laravel-ecotone/).
---
## Symfony, Laravel, or standalone — same code
The handlers and channel definitions above have no framework-specific imports. Pick your install path:
```bash
# Symfony — auto-registers via the bundle
composer require ecotone/symfony-bundle
# Laravel — auto-discovered via the service provider
composer require ecotone/laravel
# Standalone / lambda / worker / CLI tools — any PSR-11 container
composer require ecotone/lite-application
# RabbitMQ transport (any of the above)
composer require ecotone/amqp
```
*Same handlers, three install paths. Migrating between stacks doesn’t rewrite the domain.*
---
## Common questions
### Is this a replacement for Symfony Messenger or Laravel Queue?
No — it works *with* them. Messenger and Laravel Queue are transports; Ecotone’s `#[Asynchronous]` sits on top, adding per-handler isolation, combined channels, outbox, and routing-by-attribute. Keep your existing transport configuration.
### How do I test async flows without spinning up RabbitMQ?
`EcotoneLite::bootstrapFlowTesting()` gives you in-memory channels and deterministic async testing — no broker, no polling, no flaky tests. The same handlers run in CI under 100ms.
### What happens when a handler keeps failing?
Configure retries per channel and a dead-letter queue for permanent failures. Failed messages stay inspectable and replayable from the CLI — see [error channel and dead letter](https://docs.ecotone.tech/modelling/recovering-tracing-and-monitoring/resiliency/error-channel-and-dead-letter?ref=blog.ecotone.tech).
---
## Wrapping up
Going async in PHP used to mean adopting a job library, writing job classes, configuring a worker, and accepting that one slow consumer could stall the whole queue. With per-handler channels and a combined outbox, that whole list collapses into one attribute and one channel definition. Companion read: [Event Handling in PHP — From Tangled Code to Clean Flows](https://blog.ecotone.tech/event-handling-in-php/) covers the synchronous version of the same pattern, and [Enterprise PHP in 2026: The Patterns You’re Missing](https://blog.ecotone.tech/meet-ecotone-enterprise-ready-framework-for-php/) bundles outbox, isolation, and workflows together.
Full surface in the [async handling docs](https://docs.ecotone.tech/modelling/asynchronous-handling?ref=blog.ecotone.tech).
---
*Dariusz Gafka is a Software Architect and author of the* [*Ecotone Framework*](https://github.com/ecotoneframework/ecotone?ref=blog.ecotone.tech)*. He writes about event sourcing, CQRS, and message-driven PHP architecture.*
### Event Handling in PHP — From Tangled Code to Clean Flows
URL: https://blog.ecotone.tech/event-handling-in-php/
Last updated: 2026-05-14T15:44:13.000Z
*Updated on 2026-05-14*
You’ve seen this PHP service before — maybe you wrote it. `UserService::register()` creates a user, sends an email, writes an audit log, calls a CRM webhook, and updates a search index. It’s 200 lines, has six dependencies, and every change to one feature risks breaking the others. The fix isn’t more layers — it’s **splitting the main flow from the sub-flows using domain events**.
**The short version.** A domain event is a message that says “this happened” — `UserWasRegistered`, `OrderWasPlaced`. The main flow publishes the event; sub-flows (email, audit, CRM) subscribe as separate handlers. Each handler is independently testable, independently deployable, and independently retriable when something fails. With Ecotone you get this from a single attribute on a method.
---
## The pain — one service, too many jobs
Here’s what the tangled version usually looks like:
```php
final class UserService
{
public function register(string $email, string $name): void
{
$user = new User($email, $name);
$this->users->save($user);
$this->mailer->sendWelcome($user);
$this->audit->log("user.registered", ["email" => $email]);
$this->crm->syncContact($user);
$this->search->index($user);
}
}
```
*Five responsibilities in one method. Adding a sixth means re-testing all five.*
What’s wrong here isn’t the code — it’s the coupling. The **main flow** is “create and save a user.” Everything else is a **sub-flow** that happens *because* the user got registered. Mixing them means you can’t change the email template without risking the audit log, can’t retry the CRM call without re-sending the email, and can’t test registration without mocking five collaborators.
---
## The fix — publish a domain event
An event is a plain PHP class describing something that already happened. No interface to implement, no base class to extend.
```php
final class UserWasRegistered
{
public function __construct(
public readonly string $userId,
public readonly string $email,
) {}
}
```
The main flow publishes the event through the `EventBus` — Ecotone auto-registers it in the container so you just inject it.
```php
final class UserService
{
public function __construct(private EventBus $events) {}
#[CommandHandler]
public function register(RegisterUser $command): void
{
$user = new User($command->email, $command->name);
$this->users->save($user);
$this->events->publish(new UserWasRegistered(
$user->id(),
$command->email,
));
}
}
```
*The main flow does one thing — creates and saves the user. Sub-flows are no longer its problem.*
Now every sub-flow becomes its own handler — a single method with a single responsibility:
```php
final class WelcomeMailHandler
{
#[EventHandler]
public function send(UserWasRegistered $event, Mailer $mailer): void
{
$mailer->sendWelcome($event->email);
}
}
final class CrmSyncHandler
{
#[EventHandler]
public function sync(UserWasRegistered $event, CrmClient $crm): void
{
$crm->syncContact($event->userId, $event->email);
}
}
final class AuditHandler
{
#[EventHandler]
public function log(UserWasRegistered $event, AuditLog $audit): void
{
$audit->record("user.registered", ["userId" => $event->userId]);
}
}
```
*Three handlers, three single-purpose classes. Each is testable in isolation with no collaborators beyond the one service it actually uses.*
*Notice the second parameter on each handler.* Ecotone’s method-level dependency injection means you don’t have to inject every collaborator into the class constructor — pass them straight to the method that needs them. The handler signature documents what it actually depends on.
---
## Per-handler isolation — the bit other event systems miss
Symfony’s EventDispatcher and Laravel’s events both run all listeners for an event in the same process. If the CRM sync throws, the email might already have been sent (if the listener ran first) or might never run (if it didn’t). There’s no clean recovery story.
Ecotone publishes a **separate copy** of the event to each handler’s own channel. The mail handler succeeded? Done. The CRM handler failed? It retries on its own channel without re-sending the welcome email. This is the same pattern message-driven JVM systems have used for over a decade — and the single most-cited reason teams move to it from Symfony’s EventDispatcher.
---
## Make it production-safe — async + outbox
Sending email in the same web request is fragile: SMTP times out and the user sees a 500 even though their account was created. Move the sub-flows off the request thread by marking them `#[Asynchronous]` and choosing a channel:
```php
#[Asynchronous(["database_channel", "rabbit_channel"])]
#[EventHandler(endpointId: "welcome_mail")]
public function send(UserWasRegistered $event, Mailer $mailer): void
{
$mailer->sendWelcome($event->email);
}
```
*Combined channels: the event is committed atomically with the user row into `database_channel`, then forwarded to `rabbit_channel` for the consumer to pick up.*
The combination of DBAL outbox + RabbitMQ means the event is **never lost** — even if the broker is down at commit time — and downstream consumers scale on the broker, not on your database. There’s no separate outbox library to wire up; the channel definitions live in a `ServiceContext` and Ecotone handles the rest.
For the full breakdown of why this matters, see [Enterprise PHP in 2026: The Patterns You’re Missing](https://blog.ecotone.tech/meet-ecotone-enterprise-ready-framework-for-php/).
---
## Symfony, Laravel, or standalone — same code
The handlers above are framework-agnostic POPOs. Pick your install path:
```bash
# Symfony — auto-registers via the bundle
composer require ecotone/symfony-bundle
# Laravel — auto-discovered via the service provider
composer require ecotone/laravel
# Standalone / lambda / worker / CLI tools — any PSR-11 container
composer require ecotone/lite-application
```
*Same handlers, three install paths. Migrating between stacks doesn’t rewrite the domain.*
---
## Common questions
### Is this a replacement for Symfony EventDispatcher or Laravel events?
Not a replacement — a different layer. EventDispatcher and Laravel events are in-process, synchronous, framework-bound. Ecotone events are domain events: per-handler isolated, async-capable, and outbox-safe. You can keep using EventDispatcher for framework lifecycle hooks and use Ecotone for business events.
### Where do these events live — what about an event store?
Plain `#[EventHandler]` publishes events to handlers in-memory or via channels — no event store needed. If you want an audit trail or event sourcing, add an event-sourced aggregate; the event classes stay the same.
### Can two handlers run in different services?
Yes — Ecotone’s distributed bus lets one service publish an event and another service subscribe via RabbitMQ, SQS, or Kafka. The handler signature is identical in both services.
---
## Wrapping up
Splitting main flows from sub-flows is one of those changes that pays for itself within a sprint — every new feature touches one handler, not the world. The pattern itself is older than PHP; the part that’s new is having a tool that bundles the publishing, the per-handler isolation, the async channels, and the outbox into a single attribute.
If you want to dig deeper, the [Ecotone event handling docs](https://docs.ecotone.tech/modelling/command-handling/external-command-handlers/event-handling?ref=blog.ecotone.tech) walk through the full surface, or jump straight into the [documentation index](https://docs.ecotone.tech/?ref=blog.ecotone.tech).
---
*Dariusz Gafka is a Software Architect and author of the* [*Ecotone Framework*](https://github.com/ecotoneframework/ecotone?ref=blog.ecotone.tech)*. He writes about event sourcing, CQRS, and message-driven PHP architecture.*
### CQRS in PHP — Stop Mixing Reads and Writes
URL: https://blog.ecotone.tech/cqrs-in-php/
Last updated: 2026-05-14T15:44:05.000Z
*Updated on 2026-05-14*
You’ve debugged this bug. Someone calls `$products->findById($id)` from a controller — innocent, right? Then a customer reports their view count jumped by 200 overnight. Turns out `findById` also increments a counter “for analytics,” and a cache warmer is calling it in a loop. The function *looks* like a read. It isn’t. **That’s the bug CQRS prevents.**
**The short version.** CQRS — Command Query Responsibility Segregation — splits your code into two buckets: **commands** change state, **queries** read state. A query that touches the database for writes is a bug. A command that pretends to be idempotent is a bug. Once the boundary is enforced, you can read freely without worrying about side effects, and you can route commands and queries through different infrastructure (caches, replicas, async channels) without rewriting code. Ecotone gives you a `CommandBus` and `QueryBus` behind PHP attributes — no glue, no factories, no conventions to memorise.
---
## The split — commands change, queries don’t
A **command** is a request to change state — `ChangeUserEmail`, `PlaceOrder`, `CancelSubscription`. It can fail; it can be rejected. It returns void or a tiny acknowledgement. Crucially, it never returns the data you’re modifying — that’s a separate concern.
A **query** reads state and returns it. **Queries must have no observable side effects.** No cache writes, no view counters, no last-accessed timestamps. If a “read” updates a row, it’s a command in a wig.
That single agreement — queries are pure reads — is the entire point. It’s why CQRS makes systems reasonable in a way CRUD doesn’t.
---
## Defining a command
A command is a plain PHP class describing the change you want:
```php
final class ChangeUserEmail
{
public function __construct(
public readonly string $userId,
public readonly string $newEmail,
) {}
}
```
The handler is a method marked with `#[CommandHandler]` — Ecotone routes commands to handlers by the first parameter’s type:
```php
final class UserService
{
#[CommandHandler]
public function changeEmail(ChangeUserEmail $command, Users $users): void
{
$user = $users->byId($command->userId);
$user->changeEmail($command->newEmail);
$users->save($user);
}
}
```
*One command, one handler. The second parameter is injected by Ecotone’s method-level DI — no constructor wiring needed for collaborators that only one method uses.*
Send the command from a controller through the auto-registered `CommandBus`:
```php
final class UserController
{
public function __construct(private CommandBus $bus) {}
public function changeEmail(string $userId, Request $request): Response
{
$this->bus->send(new ChangeUserEmail(
$userId,
$request->get("email"),
));
return new Response(204);
}
}
```
*The controller doesn’t know which class handles the command. It just sends it. Refactoring the handler — moving it, renaming it, splitting it — doesn’t touch the controller.*
---
## Defining a query
Queries follow the same shape but go through a separate `QueryBus`:
```php
final class GetUserShippingAddress
{
public function __construct(public readonly string $userId) {}
}
final class UserQueries
{
#[QueryHandler]
public function shippingAddress(
GetUserShippingAddress $query,
Connection $db,
): ShippingAddress {
return ShippingAddress::fromRow(
$db->fetchOne("SELECT * FROM addresses WHERE user_id = ?", [$query->userId])
);
}
}
```
```php
$address = $queryBus->send(new GetUserShippingAddress($userId));
```
Two buses, two intents. Once the codebase is structured this way, finding “everything that can change a user” is one grep for `#[CommandHandler]`; finding “everything that reads a user” is one grep for `#[QueryHandler]`. **That’s the productivity win nobody talks about.**
---
## The modern idiom — handlers on the aggregate
For domain models, you don’t need a separate service class for command handlers — put the handler on the aggregate itself:
```php
#[Aggregate]
final class User
{
public function __construct(
#[Identifier] private string $id,
private string $email,
) {}
#[CommandHandler]
public function changeEmail(ChangeUserEmail $command): void
{
$this->email = $command->newEmail;
}
}
```
*The aggregate IS the handler. Ecotone fetches the user by `#[Identifier]`, applies the change, and persists — no separate `UserService` needed.*
This is where CQRS stops being a pattern and starts being how the code *looks*. The behaviour and the state live in the same class; the bus orchestration lives in the framework.
---
## Symfony, Laravel, or standalone — same code
The handlers, commands, and queries above have no framework dependency. Same domain code, three install paths:
```bash
# Symfony — auto-registers via the bundle
composer require ecotone/symfony-bundle
# Laravel — auto-discovered via the service provider
composer require ecotone/laravel
# Standalone / lambda / worker / CLI tools — any PSR-11 container
composer require ecotone/lite-application
```
*The same `UserService`, `UserQueries`, and `User` aggregate run identically on either stack.*
---
## Common questions
### Do I need event sourcing to use CQRS?
No. CQRS is the read/write split; event sourcing is one way to store the write side. You can do CQRS with Doctrine, Eloquent, or any ORM. Ecotone supports both state-stored and event-sourced aggregates — pick what fits.
### What about CQRS with separate read and write databases?
CQRS doesn’t require physically separate stores — the segregation is logical first. If you do split (write to PostgreSQL, read from a denormalised projection in Redis or Elasticsearch), Ecotone’s `#[Projection]` handlers keep the read model up to date from domain events. See [projection docs](https://docs.ecotone.tech/modelling/event-sourcing/setting-up-projections?ref=blog.ecotone.tech).
### Is this a replacement for Symfony Messenger or Laravel Bus?
No. Messenger and Laravel Bus are message dispatchers; Ecotone’s `CommandBus`/`QueryBus` sit on top, adding routing-by-attribute, handler-on-aggregate, async with per-handler isolation, and projections. Keep what you have — add what’s missing.
---
## Wrapping up
CQRS sounds enterprisey but it’s really just one rule: **don’t pretend a write is a read**. Once that rule is structurally enforced, half the bugs you fix in legacy PHP services stop happening — including the one where a “harmless” read silently mutates a counter. Companion read: [Event Handling in PHP — From Tangled Code to Clean Flows](https://blog.ecotone.tech/event-handling-in-php/) covers the natural next step, publishing events from your command handlers.
The full surface lives in the [Ecotone command handling docs](https://docs.ecotone.tech/modelling/command-handling?ref=blog.ecotone.tech).
---
*Dariusz Gafka is a Software Architect and author of the* [*Ecotone Framework*](https://github.com/ecotoneframework/ecotone?ref=blog.ecotone.tech)*. He writes about event sourcing, CQRS, and message-driven PHP architecture.*
### Enterprise PHP in 2026: The Patterns You're Missing
URL: https://blog.ecotone.tech/meet-ecotone-enterprise-ready-framework-for-php/
Last updated: 2026-05-14T15:11:45.000Z
*Updated on 2026-05-14*
For years the PHP community has been told its language can’t do “enterprise.” In 2026, that’s no longer true — but the gap between a Symfony or Laravel app and one that survives real production load isn’t the framework. It’s four patterns most PHP teams still hand-roll badly: the **transactional outbox**, **per-handler failure isolation**, **composable workflows** instead of status columns, and **event-sourced read models**.
> **TL;DR**`if`
### Table of contents
- [Why “enterprise PHP” feels harder than it should](#why-enterprise-php-is-hard)
- [Pattern 1 — Transactional Outbox + RabbitMQ in Two Lines](#outbox)
- [Pattern 2 — Per-Handler Failure Isolation](#isolation)
- [Pattern 3 — Composable Workflows Instead of Service Spaghetti](#workflows)
- [Pattern 4 — Projections Instead of JOINs](#projections)
- [Same Domain Code, Symfony or Laravel — Pick Your Stack](#symfony-laravel)
- [Common questions](#faq)
---
## Why “enterprise PHP” feels harder than it should
If you read the [Symfony Messenger outbox issue](https://github.com/symfony/symfony/issues/34147?ref=blog.ecotone.tech) — open since 2019, still active in 2025 — or the [Laravel Horizon “jobs lost randomly” thread](https://github.com/laravel/horizon/issues/857?ref=blog.ecotone.tech), you’ll see the same shape of pain everywhere:
- A handler runs **before** the database transaction commits, so a row that should have been read isn’t there.
- One slow consumer **blocks every other handler** behind it on the same transport.
- A retried job re-fires *all* its sibling handlers, double-charging customers or sending duplicate emails.
- A failed background job **disappears** silently because the dead-letter wiring wasn’t done correctly.
These aren’t framework bugs. They’re missing patterns. JVM teams using Spring Integration, Axon, NServiceBus or MassTransit got these patterns for free a decade ago. PHP teams have, until recently, written them by hand — and got burned every time the implementation drifted from the textbook.
> [Ecotone](https://docs.ecotone.tech/?ref=blog.ecotone.tech)
---
## Pattern 1 — Transactional Outbox + RabbitMQ in Two Lines
The dual-write problem is brutal: you save an order, then publish “OrderPlaced” to RabbitMQ. The save commits, the publish fails, and Shipping never hears about an order the customer already paid for. The textbook fix is the **outbox pattern** — write the event into the same transaction as the business state, then have a forwarder push it to the broker.
Most PHP solutions stop at “DB-only outbox” — fine for small systems, painful at scale because every consumer hammers the database. Ecotone lets you **combine** an outbox channel with a real broker so writes stay transactional *and* downstream consumers scale on RabbitMQ:
```php
final class MessagingConfiguration
{
#[ServiceContext]
public function databaseChannel()
{
return DbalBackedMessageChannelBuilder::create("database_channel");
}
#[ServiceContext]
public function rabbitChannel()
{
return AmqpBackedMessageChannelBuilder::create("rabbit_channel");
}
}
final class ShippingHandler
{
#[Asynchronous(["database_channel", "rabbit_channel"])]
#[EventHandler(endpointId: "shipping.onOrderPlaced")]
public function handle(OrderWasPlaced $event, ShippingApi $api): void
{
$api->scheduleDelivery($event->orderId);
}
}
```
*Combined channels: the event is committed atomically with the order row into `database_channel`, then a forwarder publishes it to `rabbit_channel` where consumers scale out independently.*
That’s the entire setup — no glue table, no cron, no `messenger:doctrine:outbox` package. The outbox guarantees the event is never lost; RabbitMQ gives you the throughput, fan-out and operational tooling you actually want at the consumer side.
Compare with the [hand-rolled Symfony + Outbox + RabbitMQ walkthrough](https://medium.com/devwarlocks/symfony-outbox-pattern-rabbitmq-a-key-for-reliable-microservices-10bf267fdb0a?ref=blog.ecotone.tech) — same end state, \~150 lines of plumbing replaced by two attributes.
---
## Pattern 2 — Per-Handler Failure Isolation
Symfony Messenger dispatches **one envelope** through every handler bound to it. If three listeners react to `OrderWasPlaced` and the second one throws, you have to decide globally what to do — retry the whole envelope and re-fire handler #1, or skip and lose handler #3\. There is no good answer.
Ecotone publishes a **separate copy** of the event to each handler’s channel. Handler #1 succeeded → it’s done. Handler #2 retries on its own channel with its own backoff. Handler #3 runs as if nothing happened.
```php
#[Asynchronous("billing")]
#[EventHandler(endpointId: "billing.onOrderPlaced")]
public function bill(OrderWasPlaced $event, BillingApi $api): void { /* ... */ }
#[Asynchronous("shipping")]
#[EventHandler(endpointId: "shipping.onOrderPlaced")]
public function ship(OrderWasPlaced $event, ShippingApi $api): void { /* ... */ }
```
*Two channels, two consumers, two retry policies — one event.*
This is exactly the pain in the dev.to post [“Symfony Messenger: A Great Servant, But a Terrible Master”](https://dev.to/tito10047/symfony-messenger-a-great-servant-but-a-terrible-master-or-how-asynchrony-cost-me-half-my-beard-3k5c?ref=blog.ecotone.tech) — and it’s why per-handler isolation is the single most-cited reason teams move to Ecotone.
---
## Pattern 3 — Composable Workflows Instead of Service Spaghetti
Every “we just need a status column” feature eventually becomes a 600-line service with `if ($order->isPaid && !$order->isShipped && ...)` chains. PHP teams reach for queues, listeners, and conditional code; the workflow is **implicit**, scattered across files, and impossible to reason about.
Ecotone makes the workflow **explicit** — handlers chain via `outputChannelName`, and intermediate steps are private to the workflow:
```php
final class ProcessOrder
{
#[CommandHandler("verify.order", outputChannelName: "place.order")]
public function verify(PlaceOrder $command): PlaceOrder
{
if (!$this->isValidOrder($command)) {
throw new InvalidOrderException();
}
return $command;
}
#[InternalHandler("place.order", outputChannelName: "notify.customer")]
public function place(PlaceOrder $command): PlaceOrder
{
$this->orders->save($command);
return $command;
}
#[InternalHandler("notify.customer")]
public function notify(PlaceOrder $command, Notifier $notifier): void
{
$notifier->orderPlaced($command->orderId);
}
}
```
*Three steps, one workflow. Each step is a normal PHP method; chaining is declared in attributes, not buried in service calls.*
The real power shows up when you **combine workflows together**. Once you have `verify.order`, `process.payment`, `dispatch.shipment` as named building blocks, you compose them into higher-level flows with an `#[Orchestrator]` *(Ecotone Enterprise)*:
```php
final class CheckoutOrchestrator
{
#[Orchestrator(inputChannelName: "checkout")]
public function checkout(): array
{
return [
"verify.order",
"process.payment",
"dispatch.shipment",
"notify.customer",
];
}
}
final class RefundOrchestrator
{
#[Orchestrator(inputChannelName: "refund")]
public function refund(): array
{
return [
"verify.refund.eligibility",
"process.payment.reversal",
"notify.customer", // reuses the step from CheckoutOrchestrator
];
}
}
```
*Two orchestrators, one shared `notify.customer` step. Workflows compose like Lego — change the order, swap a step, branch on metadata, all without touching the implementations.*
This is the same routing-slip pattern that JVM teams use in Apache Camel and Spring Integration. In PHP, until recently, you got it by writing it yourself badly; now it’s an attribute.
> `outputChannelName#[InternalHandler]`
---
## Pattern 4 — Projections Instead of JOINs
When `OrdersList` is taking 800ms because you’re four joins deep, the textbook answer is **CQRS with a read model** — keep the write model normalised, project events into a denormalised table optimised for the queries you actually run.
```php
#[Projection(name: "orders_list")]
final class OrdersListProjection
{
#[EventHandler]
public function whenPlaced(OrderWasPlaced $event, Connection $db): void
{
$db->insert("orders_list", [/* ... */]);
}
#[EventHandler]
public function whenShipped(OrderShipped $event, Connection $db): void
{
$db->update("orders_list", ["status" => "shipped"], ["id" => $event->orderId]);
}
}
```
*The projection rebuilds itself from the event stream — drop the table and replay any time.*
Ecotone Enterprise adds **partitioned projections** (one partition per aggregate, parallel rebuild) and **streaming projections** (Kafka or RabbitMQ Streams as the event source). On the OSS tier you still get sync and async projections, replay, and gap detection.
---
## Same Domain Code, Symfony or Laravel — Pick Your Stack
The patterns above all live in plain PHP classes — POPOs with attributes. They have **no dependency on the host framework**. The same `OrderService`, `ShippingHandler`, `CheckoutOrchestrator` runs identically on:
```bash
# Symfony — auto-registers via the bundle
composer require ecotone/symfony-bundle
# Laravel — auto-discovered via the service provider
composer require ecotone/laravel
# Standalone / lambda / worker / CLI tools — any PSR-11 container
composer require ecotone/lite-application
```
*Three install paths, one set of domain classes.*
Eloquent, Doctrine, Symfony Messenger Transports, Laravel Queues — Ecotone plugs into what’s already there. On Symfony, your DBAL outbox uses the existing Doctrine connection and your RabbitMQ channel can wrap a Symfony Messenger transport. On Laravel, the outbox uses Eloquent’s connection and the broker channel can ride Laravel’s Queue infrastructure.
That portability is unique in PHP. It means:
- A **shared kernel** of domain code can be reused across two services running on different stacks (a Laravel admin panel and a Symfony API, both reacting to the same `OrderWasPlaced` event).
- Migrating from one stack to the other doesn’t require rewriting your domain — only re-installing the Ecotone bridge package.
- Library authors can ship Ecotone-based modules that work for both communities out of the box.
> **not**
---
## Common questions
### Is Ecotone a replacement for Symfony Messenger or Laravel Queue?
No. It runs on top of either. Messenger and Laravel Queue are transports; Ecotone is the patterns layer (outbox, isolation, workflows, projections, ES) on top of them.
### What’s the PHP equivalent of Axon Framework?
Ecotone is the closest equivalent — same Enterprise Integration Patterns lineage as Axon, Spring Integration, NServiceBus, and MassTransit, expressed through PHP attributes.
### Workflows vs Sagas — when do I use which?
Workflows (stateless chains via `outputChannelName` and `#[Orchestrator]`) are for deterministic step-by-step processes where each step decides what runs next. Sagas (stateful, identifier-tracked) are for long-running coordinations that wait on external events — e.g. “order placed, then payment received minutes later, then shipping confirmed hours later.” Use workflows for sequencing, sagas for waiting.
### How do I test async flows without spinning up RabbitMQ?
`EcotoneLite::bootstrapFlowTesting()` gives you in-memory channels and deterministic async testing — no broker, no polling, no flaky tests.
---
## Wrapping up
The patterns themselves aren’t new — they’re the same ones running banks and logistics platforms on the JVM since the early 2010s. What’s new in 2026 is that PHP finally has them in a tool that doesn’t ask you to leave Symfony or Laravel behind.
If you want to try it on your codebase, the [tutorial](https://docs.ecotone.tech/tutorial-php-ddd-cqrs-event-sourcing?ref=blog.ecotone.tech) walks through a runnable example end-to-end, or jump straight into the [Ecotone documentation](https://docs.ecotone.tech/?ref=blog.ecotone.tech).
---
*Dariusz Gafka is a Software Architect and author of the [Ecotone Framework](https://github.com/ecotoneframework/ecotone?ref=blog.ecotone.tech). He writes about event sourcing, CQRS, and message-driven PHP architecture.*